| The fundamental principle of a vector database revolves around embeddings. An embedding is a numerical representation (a vector) of text, images, audio, or other data, capturing its semantic meaning in a high-dimensional space. LLMs (Large Language Models) are often used to generate these embeddings, transforming raw data into vectors suitable for storage and retrieval in a vector database. When an LLM is used to generate embeddings, the vector database becomes inherently dependent on that specific LLM. The "semantic space" of the embeddings—how meaning is encoded and how similarity is measured—is defined by the LLM that created them. 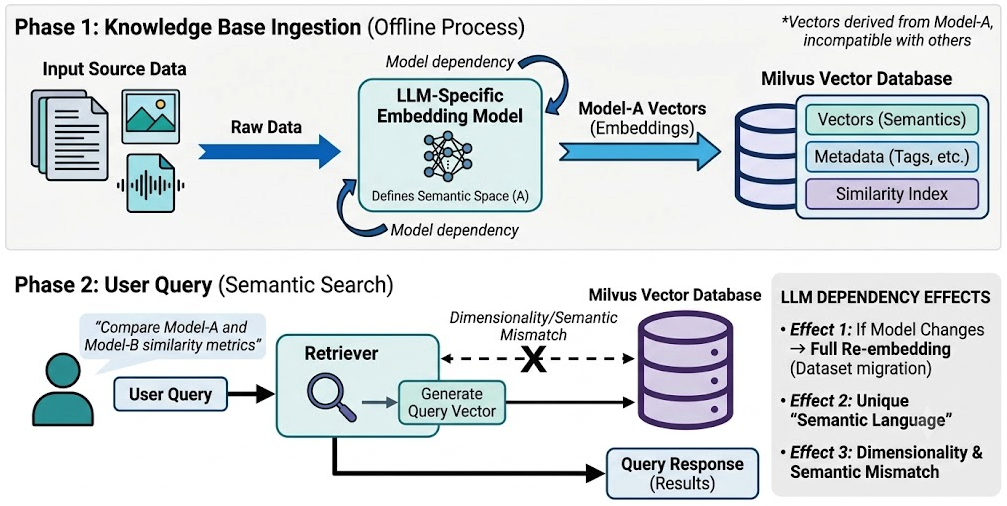
Why Re-embedding is Necessary When an LLM Changes or UpgradesUpgrading or switching the LLM used for embedding generation necessitates re-embedding the entire dataset within your vector database. 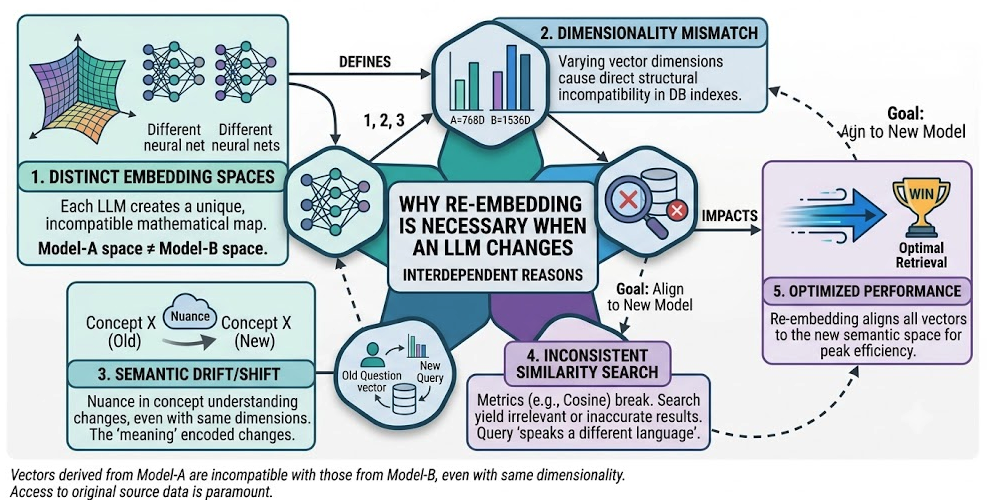
This is because: - Distinct Embedding Spaces: Different LLMs, even those designed for similar tasks, have unique architectures, training data, and learning objectives. This results in each LLM creating its own distinct "embedding space." What one LLM considers semantically close, another might represent differently.
- Dimensionality Mismatch: LLMs often output embeddings of different dimensions (e.g., one model might produce 768-dimensional vectors, while another produces 1024 or 1536-dimensional vectors). A change in dimension makes the old and new embeddings incompatible and directly unusable with each other in the same index.
- Semantic Drift/Shift: Even if two LLMs produce embeddings of the same dimension, their underlying understanding and representation of concepts will differ. An upgraded LLM (e.g., moving from
text-embedding-ada-002 to text-embedding-3-large or a custom fine-tuned model) will have a more nuanced or different semantic interpretation. The "meaning" encoded in the vector changes. - Inconsistent Similarity Search: Vector databases rely on distance metrics (e.g., cosine similarity, Euclidean distance) to find semantically similar items. These metrics only work effectively when all vectors being compared reside in the same, consistent embedding space. If you try to query with an embedding generated by the new LLM against a database of embeddings generated by the old LLM, the similarity search will yield inaccurate, irrelevant, or suboptimal results because the query vector "speaks a different language" than the indexed vectors.
- Optimized Performance: Re-embedding ensures that all vectors in your database are aligned with the new LLM's semantic space, leading to optimal performance for similarity search, retrieval, recommendation, and any other downstream tasks that rely on vector similarity.
The Actual Migration Process When Changing LLMsMigrating your vector database to use embeddings from a new or upgraded LLM is a significant undertaking that requires careful planning and execution. The process typically involves these phases: 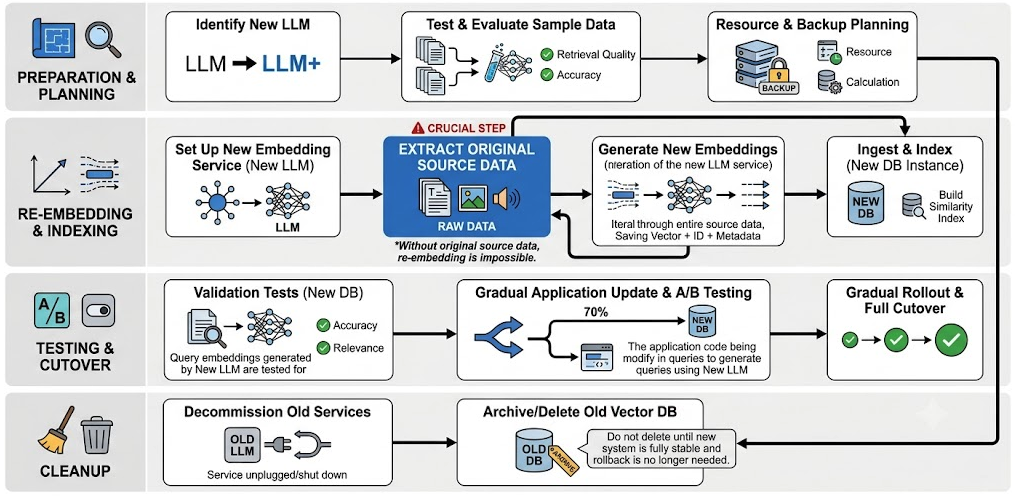
1. Preparation and Planning- Identify New LLM: Select the new embedding model (e.g., a newer version from the same provider, a different provider's model, or an open-source alternative).
- Test and Evaluate:
- Generate embeddings for a representative sample of your data using the new LLM.
- Evaluate its performance on key tasks (e.g., retrieval quality, semantic accuracy, relevance for your specific use case) compared to the current model. This helps validate the choice.
- Resource Planning: Estimate the computational resources (CPU/GPU, memory) and time required to re-embed your entire dataset. This can be substantial for large datasets.
- Backup: Critically, back up your existing vector database and ensure you have reliable access to the original source text/data that was used to generate the initial embeddings.
- Schema Check: If the new embeddings have a different dimensionality, confirm that your vector database supports this or plan for potential schema adjustments.
2. Re-embedding and Indexing- Extract Source Data: Retrieve all the original text, documents, images, or other raw data that was used to create the initial embeddings. This is the most crucial step; without the source data, re-embedding is impossible.
- Generate New Embeddings:
- Set up an embedding service or script utilizing the new LLM.
- Iterate through your entire dataset of original source data.
- For each piece of data, send it to the new LLM's embedding endpoint or function to generate its corresponding vector.
- Store these newly generated vectors, ideally alongside their original unique IDs and any relevant metadata.
- Populate New Vector Database (Recommended Approach):
- Create a new, separate vector database instance. This minimizes downtime and risk to your production system.
- Ingest all the newly generated embeddings into this new database. Ensure that each vector is associated with its correct ID and metadata.
- Build indexes on the new database. This process can be time-consuming, depending on the dataset size and database configuration.
- Alternatively (Riskier, for smaller datasets or specific VDBs): If your vector database supports atomic updates of vectors by ID, you might consider an in-place update. However, this is generally less safe and harder to roll back.
3. Testing and Cutover- Validation: Perform comprehensive integration tests on the new vector database. Query with embeddings generated by the new LLM and verify that the results are accurate, relevant, and meet performance expectations.
- A/B Testing (if applicable): If your application supports it, route a small percentage of live user traffic to the new vector database. Monitor its real-world performance, latency, and user experience.
- Application Update: Update your application's code to:
- Use the new LLM for generating query embeddings when users search or interact with your system.
- Point to the new vector database instance for all vector operations.
- Gradual Rollout: Incrementally transition all traffic to the new vector database setup.
- Monitoring: Closely monitor the new system for any performance degradations, errors, or unexpected behavior after the full cutover.
4. Cleanup- Decommission Old Services: Once the new system is stable and fully operational, decommission the old embedding service.
- Archive/Delete Old Database: Archive or delete the old vector database instance to free up resources, after confirming that the new setup is robust and no rollback is anticipated.
This migration process highlights why access to your original source data is paramount and why careful planning is essential to ensure a smooth transition with minimal disruption to your services. |