| To develop a ChatGPT-like service targeting specific insurance product categories using FAISS/Milvus as the vector database, the foundational components include a robust data ingestion pipeline for processing diverse insurance documents into manageable text chunks, an LLM-powered embedding service responsible for transforming both these document chunks and incoming natural language user queries into dense vector representations, and the FAISS/Milvus vector database itself for efficient storage and high-performance similarity search. The overall flow initiates with the continuous ingestion and embedding of insurance product data into the vector database; subsequently, when a user submits a natural language query, it is embedded using the same LLM, sent to the vector database to retrieve the most relevant insurance information vectors, and the corresponding source text is then presented, potentially synthesized for clarity. High-level architecture comprises a backend data pipeline encompassing data sources, the embedding model, and the vector database for knowledge base creation, paired with a frontend query pipeline featuring a user interface, a query embedding model, and a retrieval-and-synthesis layer interacting with the vector database to deliver targeted insurance product information. 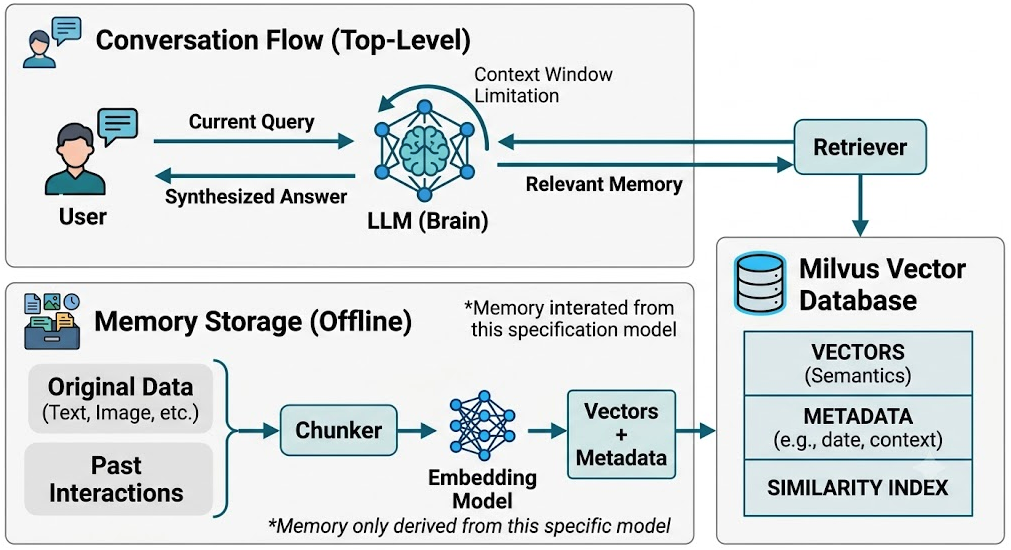
To build a service that retrieves insurance product information based on natural language queries, leveraging Vector Databases and LLMs, the following core components are essential: - Data Ingestion & Preprocessing Module:
- Document Loaders: Tools to read various data formats containing insurance product details (e.g., PDFs, web pages, database records, structured CSV/JSON files).
- Text Splitters: Algorithms to break down large documents into smaller, manageable chunks suitable for embedding. This ensures that each chunk represents a coherent piece of information while fitting within the LLM's context window.
- Metadata Extractor: Components to identify and extract crucial metadata associated with each document or chunk (e.g., product name, coverage type, insurer, region, effective date). This metadata can be stored alongside vectors for filtering or enhanced retrieval.
- Embedding Model (LLM for Embeddings):
- A pre-trained or fine-tuned Large Language Model specifically designed to generate high-quality vector embeddings from natural language text. This model must be capable of understanding the nuances of insurance terminology to accurately represent both document chunks and user queries in the vector space. Examples include
sentence-transformers, OpenAI Embeddings, Cohere Embeddings, or open-source models like BERT, RoBERTa, or specialized insurance domain models.
- Vector Database (FAISS/Milvus):
- A specialized database optimized for storing and querying high-dimensional vector embeddings efficiently.
- FAISS (Facebook AI Similarity Search): An open-source library for efficient similarity search and clustering of dense vectors. It's often used for in-memory or single-node deployments due to its speed.
- Milvus: A cloud-native vector database designed for massive-scale vector search. It offers horizontal scalability, high availability, and support for various similarity metrics. Other options include Pinecone, Weaviate, Chroma, etc.
- Query Processing Module:
- Query Encoder: Utilizes the same embedding model used for document chunks to convert a user's natural language query into a vector embedding. Consistency is crucial for effective similarity search.
- Retrieval Engine: Interacts with the Vector Database to perform similarity searches, finding the top-k most relevant document chunks based on the cosine similarity (or other distance metrics) between the query vector and document vectors.
- Generative LLM (for Retrieval Augmented Generation - RAG):
- A powerful Large Language Model (e.g., GPT-3.5, GPT-4, Llama 2, Claude) that takes the user's original query and the retrieved relevant document chunks as input. Its role is to synthesize a concise, coherent, and user-friendly answer based only on the provided context, preventing hallucinations and ensuring factual accuracy from the source insurance data.
- API & User Interface:
- Backend API: An interface (e.g., REST API) to receive user queries, orchestrate the retrieval and generation process, and return answers.
- Frontend Application: A web-based or mobile interface (e.g., built with React, Vue, Streamlit, or Gradio) where users can input queries and view the generated responses.
Data Organization for Vector Databases in Insurance AI ServicesCategorizing your insurance product information and Q&A before populating your Vector Database is a highly effective strategy. It leads to a more accurate, efficient, and scalable AI service, ultimately providing a better experience for your users and reducing operational complexities. The key is to design your categories in a way that aligns with common user queries and the inherent structure of insurance data. Why is Categorization Beneficial?Organizing your insurance data into distinct categories offers several advantages for a Vector Database powering an AI service: 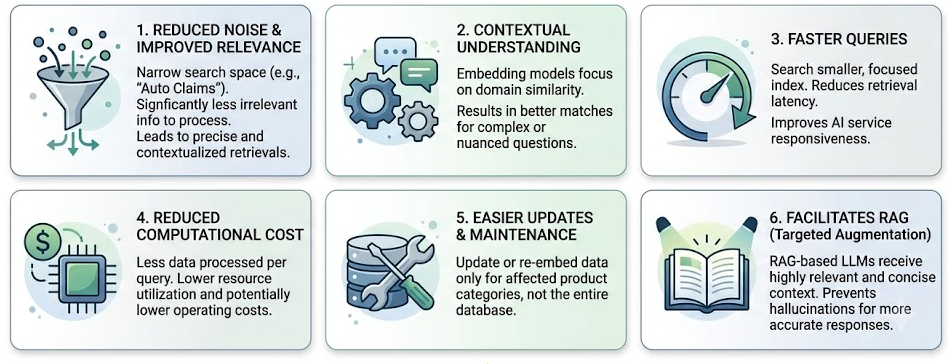
- Improved Retrieval Accuracy and Relevance:
- Reduced Noise: When a user asks a question, categorizing allows the system to first narrow down the search space to a relevant category (e.g., "Auto Insurance Claims" instead of searching through all insurance data). This significantly reduces the amount of irrelevant information the Vector Database needs to process, leading to more precise and contextualized retrievals.
- Contextual Understanding: Queries often imply a specific domain. By pre-filtering based on category, the embedding models can focus on similarity within that domain, resulting in better matches for complex or nuanced insurance questions.
- Enhanced Performance and Efficiency:
- Faster Queries: Searching within a smaller, more focused index (a category) is inherently faster than searching a monolithic, vast index. This reduces retrieval latency, improving the responsiveness of your AI service.
- Reduced Computational Cost: Less data needs to be processed per query, leading to lower computational resource utilization and potentially lower operating costs for your Vector Database and embedding models.
- Better Management and Scalability:
- Easier Updates and Maintenance: When a policy changes or new Q&A is added for a specific product, you only need to update or re-embed data within that particular category, rather than affecting the entire database.
- Scalability: Categories allow for horizontal scaling. Different categories can be managed, indexed, and stored independently, making it easier to scale your system as the volume and diversity of insurance data grow.
- Facilitates Retrieval-Augmented Generation (RAG):
- Targeted Augmentation: For RAG-based LLMs, providing a highly relevant and concise set of retrieved documents from a specific category is critical. Overloading the LLM with too much or irrelevant context can lead to hallucinations or less accurate responses. Categorization ensures the LLM receives the most pertinent information.
- Improved User Experience and Guardrails:
- Guided Interactions: In some cases, categorization can enable a more guided user experience, allowing users to select a category first, which then tailors the AI's responses more effectively.
- Boundary Enforcement: Categories can help enforce boundaries. If a user asks about "health insurance" and your system is primarily for "auto insurance," the categorization can help flag this or guide the user appropriately.
Recommended Categorization StrategiesThe optimal categorization depends on your specific use cases and the granularity of information your service needs to handle. Consider combining several approaches: 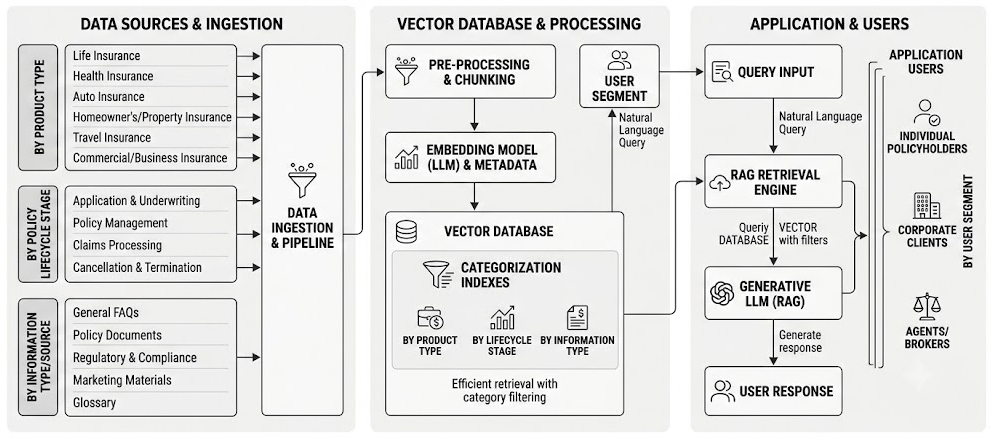
- By Product Type:
- Life Insurance (Term, Whole, Universal)
- Health Insurance (Individual, Family, Group, Dental, Vision)
- Auto Insurance (Collision, Comprehensive, Liability, Uninsured Motorist)
- Homeowner's/Property Insurance
- Travel Insurance
- Commercial/Business Insurance
- By Policy Lifecycle Stage:
- Application & Underwriting
- Policy Management (Premiums, Renewals, Endorsements)
- Claims Processing (Reporting, Documentation, Settlement)
- Cancellation & Termination
- By Information Type/Source:
- General FAQs
- Specific Policy Documents (terms and conditions)
- Regulatory and Compliance Information
- Marketing Materials/Product Brochures
- Glossary of Insurance Terms
- By User Segment:
- Individual Policyholders
- Corporate Clients
- Agents/Brokers (if your service also supports internal users)
Hybrid and Advanced Approaches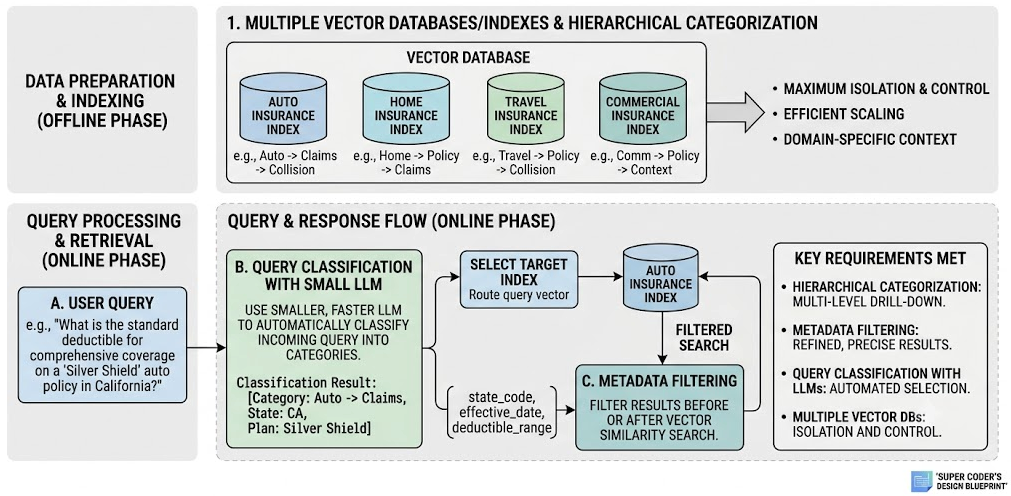
- Hierarchical Categorization: Implement a multi-level categorization (e.g., "Auto Insurance" -> "Claims" -> "Collision Claims"). This allows for both broad and granular searches.
- Metadata Filtering: Even within a category, use metadata (e.g., "effective_date," "state_code," "deductible_range") that can be filtered before or after the vector similarity search to further refine results.
- Query Classification with LLMs: Use a smaller, faster Language Model to classify the incoming user query into one or more categories before performing the vector search. This automates the category selection process.
- Multiple Vector Databases/Indexes: Instead of one large Vector Database, you might have multiple smaller ones, each dedicated to a specific product type or critical function. This provides maximum isolation and control.
Overall System FlowThe system operates in two main phases: an offline Data Indexing Flow and an online Query Processing Flow. 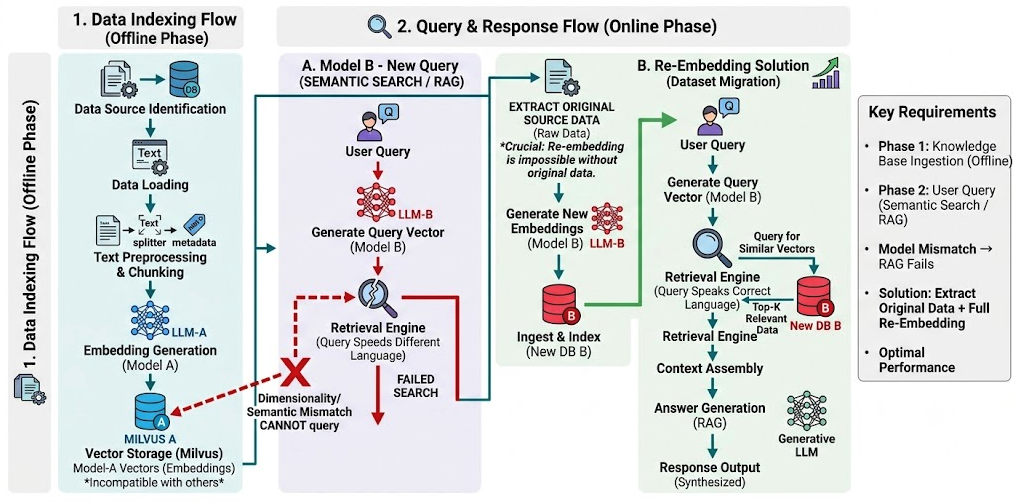
1. Data Indexing Flow (Offline)1. Data Source Identification: Identify and access various sources of insurance product information (e.g., policy documents, product brochures, terms and conditions PDFs, internal knowledge bases, public regulatory filings).
2. Data Loading: The Document Loaders component reads and extracts raw text content from these diverse sources.
3. Text Preprocessing & Chunking: The extracted text is cleaned (e.g., removing boilerplate, formatting), and then the Text Splitters divide it into smaller, semantically meaningful chunks. Relevant metadata (e.g., product ID, insurer name, policy type) is extracted and associated with each chunk.
4. Embedding Generation: Each text chunk is fed into the Embedding Model, which converts it into a high-dimensional vector embedding.
5. Vector Storage: The generated vector embeddings, along with their original text chunks and associated metadata, are stored in the Vector Database (FAISS/Milvus). An index is built to enable efficient similarity search. 2. Query Processing Flow (Online)1. User Query Input: A user submits a natural language query (e.g., "What is the deductible for health insurance plan 'Silver Shield'?") through the Frontend Application.
2. Query Encoding: The Query Encoder (the same Embedding Model used for documents) converts the user's natural language query into a vector embedding.
3. Vector Search (Retrieval): The query vector is sent to the Retrieval Engine, which queries the Vector Database. The database performs a similarity search (e.g., k-nearest neighbors) to find the top-k most relevant document chunks that closely match the query vector.
4. Context Assembly: The retrieved text chunks (and optionally their metadata) are combined to form a comprehensive context for the next step.
5. Answer Generation (RAG): The assembled context, along with the original user query, is passed to the Generative LLM. The LLM then synthesizes a natural language answer based solely on the provided context, ensuring accuracy and relevance to the retrieved insurance product information.
6. Response Output: The generated answer is sent back through the Backend API and displayed to the user on the Frontend Application. High-Level Architecture: LLM-Powered Insurance Information Service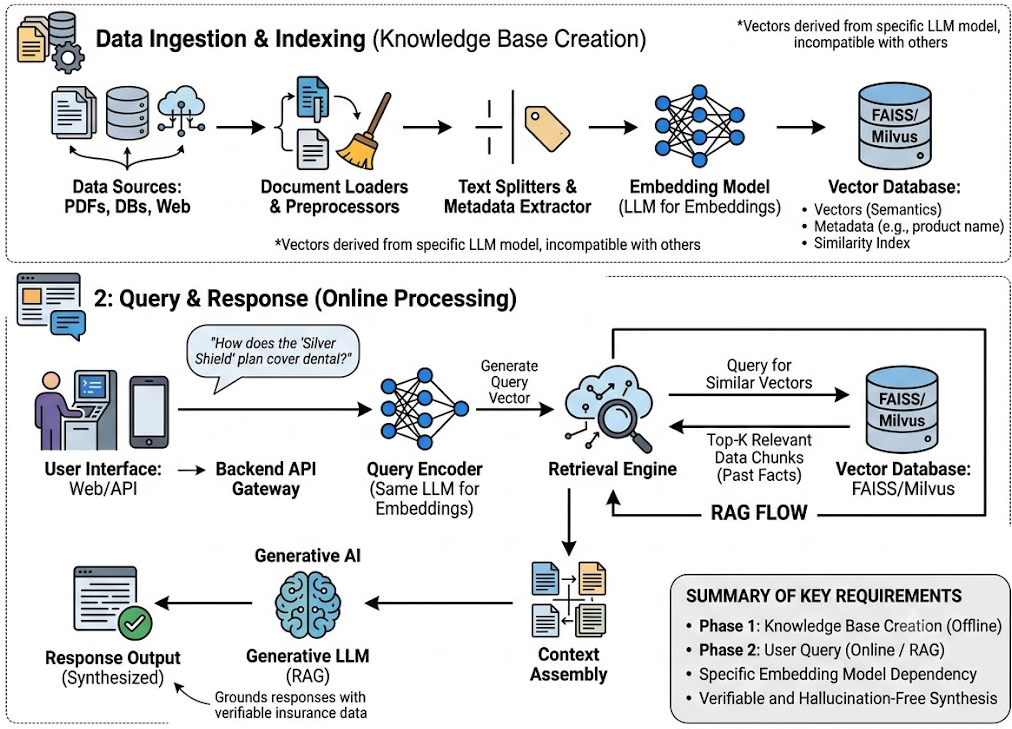
Description of Architecture Layers:
1. Data Ingestion & Indexing Layer: - Data Sources: Raw insurance product data in various formats.
- Document Loaders & Preprocessors: Modules responsible for extracting raw text, cleaning, and formatting.
- Text Splitters & Metadata Extractor: Breaks down text into chunks and extracts crucial associated metadata.
- Embedding Model: The LLM that transforms text chunks into numerical vector representations.
- Vector Database (FAISS/Milvus): Stores the generated embeddings and their corresponding original text/metadata, indexed for efficient search. This is the core "Vector Database" mentioned.
2. Query & Response Layer: - User Interface: The front-end application where users interact with the service.
- Backend API Gateway: Acts as the entry point for user queries, routing requests and managing responses.
- Query Encoder: Uses the same Embedding LLM to convert the user's natural language query into a vector.
- Retrieval Engine: Orchestrates the similarity search in the Vector Database based on the query vector.
- Context Assembly: Combines the retrieved relevant text chunks into a coherent context.
- Generative LLM: The large language model (e.g., OpenAI GPT series, Llama 2) that takes the user's query and the assembled context to generate a natural language answer. This LLM's role is specifically for generating the response based on the retrieved facts.
|