| In a relational database, a "Table" stores structured data rows and columns. In a vector database, its equivalent is a "Collection," which stores vector embeddings along with optional metadata. Vector databases often leverage multiple collections to perform complex queries, combine different types of information, and achieve more nuanced results. What is a Collection in Vector Databases?A Collection is essentially a logical container or a table-like structure within a vector database that stores vectors (specifically, embeddings) and their associated metadata. 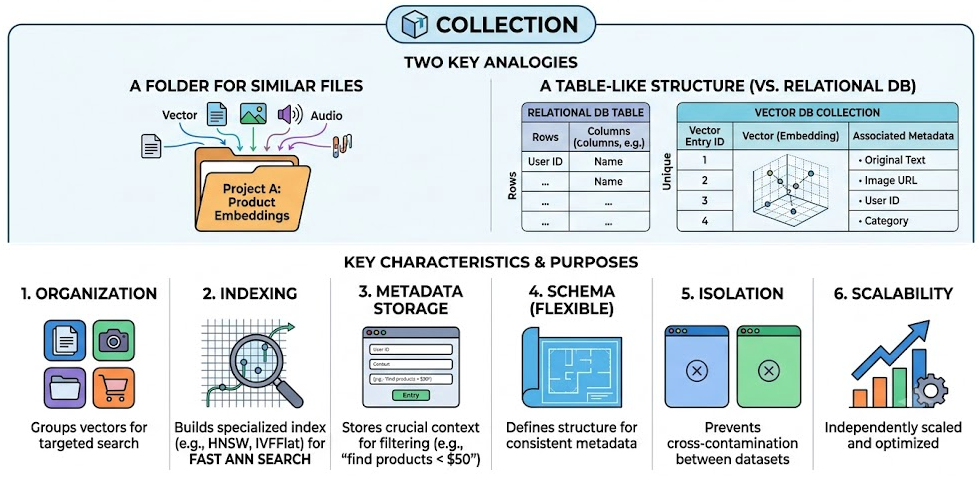
Think of it like: - A folder for similar files: All files in a folder usually relate to a specific project or topic. Similarly, a collection groups embeddings that belong together, perhaps from the same source, related application, or semantic domain.
- A table in a relational database: Just as a table stores rows (records) with columns (attributes), a collection stores vector entries, each consisting of a high-dimensional vector and its associated metadata.
Key characteristics and purposes of a Collection: - Organization: It groups vectors that are meant to be searched together. For instance, you might have one collection for text document embeddings, another for image embeddings, and yet another for product recommendation embeddings.
- Indexing: The vector database builds a specialized index (e.g., HNSW, IVFFlat, Annoy) over the vectors within a collection to enable extremely fast approximate nearest neighbor (ANN) searches. This index is specific to the collection.
- Metadata Storage: Along with each vector, a collection typically stores associated metadata (e.g., original text, image URL, user ID, timestamp, category). This metadata is crucial for understanding the search results and often used for filtering searches (e.g., "find similar documents published after 2023").
- Schema (often flexible): While some vector databases are schema-less, many allow you to define a schema for the metadata stored within a collection, ensuring data consistency.
- Isolation: Collections provide isolation between different datasets or applications. Searches performed on one collection won't affect or include data from another.
- Scalability: Each collection can be independently scaled, indexed, and optimized for its specific workload.
What is the relationship between Collection and Embeddings?The relationship is foundational: Collections are designed to store, index, and query embeddings efficiently.
Here's a breakdown of their interconnectedness: 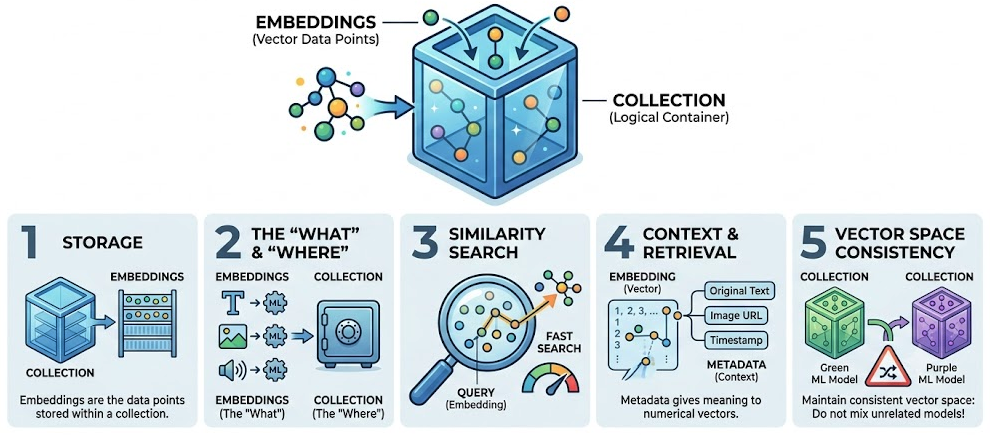
- Storage: Embeddings are the data points that get stored within a collection. Without embeddings, a collection would be empty and purposeless.
- The "What" and the "Where":
- Embeddings are the numerical representations of real-world data (text, images, audio, etc.) generated by machine learning models. They capture the semantic meaning of the data in a high-dimensional vector space.
- Collections are the containers where these embeddings live, allowing them to be managed and queried.
- Similarity Search: The primary function of a vector database is to perform similarity searches. When you issue a query (which itself is converted into an embedding), the database searches for the most similar embeddings within a specified collection. The collection's index is what makes these searches fast.
- Context and Retrieval: An embedding is just a series of numbers. When a similarity search returns a relevant embedding, it's the metadata stored alongside that embedding in the collection that gives it meaning. For example, if you search for similar texts, the collection returns the vector and the original text, document ID, author, etc.
- Vector Space Consistency: Typically, all embeddings within a single collection are generated by the same embedding model or models that produce embeddings in a compatible vector space. This ensures that the distance metric used for similarity search is meaningful across all vectors in the collection. Mixing embeddings from drastically different models in the same collection would yield poor and often irrelevant search results.
Example code for Vector Searchfrom pymilvus import connections, Collection
# 1. Connect to Milvus server
connections.connect("default", host="localhost", port="19530")
# 2. Load an existing collection (Collection Name: "book_collection")
# The collection must be loaded into memory before performing a search.
collection = Collection("book_collection")
collection.load()
# 3. Prepare the query vector
# Typically, this is a vector embedding generated from a user's text query using models like OpenAI's embedding.
query_vectors = [[0.1, 0.2, 0.3, 0.05]]
# 4. Set search parameters based on your index type
search_params = {
"metric_type": "L2", # Distance metric (L2: Euclidean, IP: Inner Product, COSINE, etc.)
"params": {"nprobe": 10}, # Number of units to query (higher means more accurate but slower)
}
# 5. Execute the search() query
results = collection.search(
data=query_vectors, # The query vector(s) to search for
anns_field="book_embedding", # Name of the vector field in your schema
param=search_params, # Search configuration
limit=3, # Top-K: number of closest results to return
expr="category == 'IT'", # (Optional) Scalar filtering expression
output_fields=["title", "author"] # Attributes to return along with the vector results
)
# 6. Process and print the search results
for hits in results:
for hit in hits:
print(f"Entity ID: {hit.id}")
print(f"Similarity Distance: {hit.distance}") # For L2 metric, lower distance means higher similarity
print(f"Title: {hit.entity.get('title')}")
print(f"Author: {hit.entity.get('author')}")
print("-" * 30)
Vector Database Reference 1 - Personalized Product RecommendationScenario: An e-commerce platform aims to provide highly personalized product recommendations to users, balancing individual preferences with broader product trends. 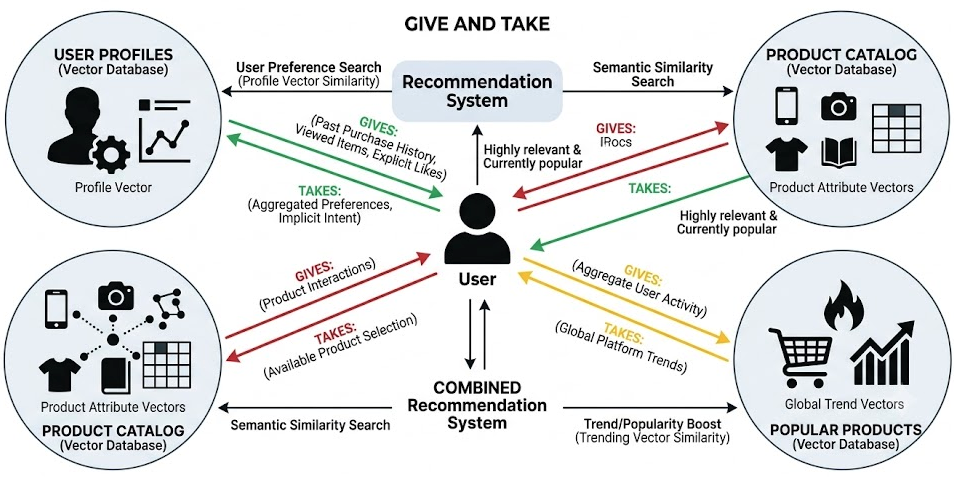
Collections: ProductCatalog: Stores vector embeddings representing each product's attributes (e.g., derived from descriptions, images, categories, features). Each product has a unique ID and its associated vector.UserProfiles: Stores vector embeddings for each user, capturing their aggregated preferences, past purchase history, viewed items, and explicit likes.PopularProducts: Stores vector embeddings of globally trending or highly-rated products, updated periodically based on overall platform activity.
How Multiple Collections Are Used: - User Preference Search: When a user logs in, their profile vector is retrieved from
UserProfiles. A similarity search is performed against the ProductCatalog to find products that are semantically similar to the user's past interests. - Trend/Popularity Boost: Concurrently, a search might be performed against the
PopularProducts collection to identify products that are currently trending or generally well-regarded. - Combined Recommendation: The results from both searches are aggregated. Products that are highly relevant to the user's individual preferences and also appear in the popular products list receive a higher combined score, leading to a more effective and balanced recommendation. For instance, a product might be highly recommended if it's similar to what the user bought before and is also currently popular.
Vector Database Reference 2 - Contextualized Knowledge Base SearchScenario: An internal company knowledge base needs to provide precise answers to employee queries, considering the document's content, its classification, and the user's typical areas of interest. 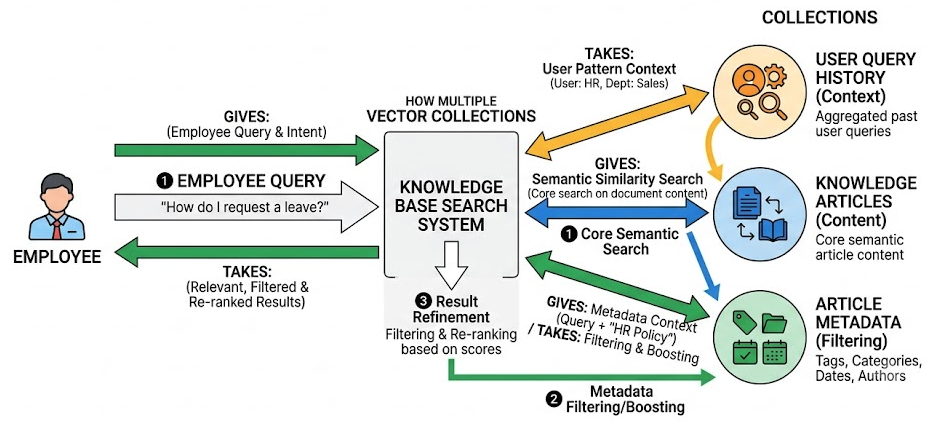
Collections: KnowledgeArticles: Stores vector embeddings of the main content of articles, FAQs, and guides.ArticleMetadata: Stores vector embeddings representing metadata associated with each article, such as categories (e.g., "HR Policy," "IT Support"), publication dates, authors, and keywords.UserQueryHistory: Stores vector embeddings representing aggregated past queries or common topics associated with specific users or departments, providing context about their information needs.
How Multiple Collections Are Used: - Core Semantic Search: An employee submits a query (e.g., "How do I request a leave?"). This query is embedded into a vector, and a similarity search is performed against
KnowledgeArticles to find semantically relevant documents. - Metadata Filtering/Boosting: Simultaneously, the system can leverage
ArticleMetadata. For instance, if the UserQueryHistory indicates the employee frequently searches for "HR" documents, the system might give higher preference to results from KnowledgeArticles whose associated metadata in ArticleMetadata strongly matches "HR Policy." The query could also be combined with metadata to search for "leave request" within "HR Policy" documents. - Result Refinement: The search results from
KnowledgeArticles are then filtered or re-ranked based on the relevance scores derived from ArticleMetadata and contextual cues from UserQueryHistory. This ensures that not only is the content relevant, but it also aligns with the expected document type and the user's typical search patterns.
Vector Database Reference 3 - Multi-modal Content Retrieval (Image and Text)Scenario: A media archive wants to allow users to find images based on either a textual description or by providing another image, combining both visual and semantic information for robust search. 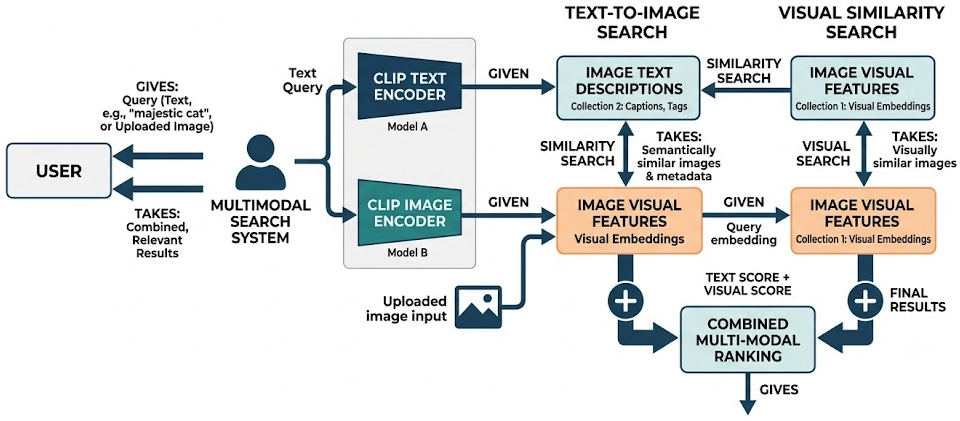
Collections: ImageVisualFeatures: Stores vector embeddings derived directly from the visual content of images (e.g., using a vision model like CLIP's image encoder).ImageTextDescriptions: Stores vector embeddings derived from the textual captions, tags, or alt-text associated with each image (e.g., using CLIP's text encoder).
How Multiple Collections Are Used: - Text-to-Image Search: A user provides a text query (e.g., "a majestic cat lounging in sunlight"). This query is embedded into a vector. A similarity search is performed against
ImageTextDescriptions to find images whose textual descriptions are semantically similar to the query. - Visual Similarity Search (Image-to-Image / Cross-modal): The same text query can also be used to generate a query vector in the visual embedding space (if using a cross-modal model like CLIP). This vector is then used to search
ImageVisualFeatures for images that are visually similar to the conceptual image described by the text. Alternatively, if a user uploads an example image, its visual embedding is used to search ImageVisualFeatures. - Combined Multi-modal Ranking: The results from both collections are combined. Images that are both visually similar (from
ImageVisualFeatures) and have similar textual descriptions (from ImageTextDescriptions) to the query receive a higher combined relevance score. This allows for finding images that not only contain the described elements but also visually match the overall intent, overcoming limitations of purely text-based or purely visual searches.
A pseudo-code implementation for the multi-modal ranking system, addressing both text and image queries, and emphasizing the combined ranking for text queries as described. 1. System Components and Global Definitions: - Data Structures for Collections (Vector Databases):
Collection_ImageVisualFeatures: A database/map storing ImageId -> ImageVisualEmbedding- Example:
{"img_001": [0.1, 0.2, ..., 0.9], "img_002": [...]}
Collection_ImageTextDescriptions: A database/map storing ImageId -> ImageTextEmbedding- Example:
{"img_001": [0.9, 0.8, ..., 0.1], "img_002": [...]}
ImageId: Unique identifier for an image.Vector: A numerical array (embedding) representing content.
- Embedding Models:
EmbedModel_Text(text_input_string) -> Vector: Takes text, returns its embedding (e.g., CLIP's text encoder output).EmbedModel_Image(image_object) -> Vector: Takes an image, returns its visual embedding (e.g., CLIP's image encoder output).
- Similarity Function:
Similarity(vector_A, vector_B) -> Float: Calculates the similarity between two vectors (e.g., Cosine Similarity, returns value typically between -1 and 1).
- Ranking Weights (Tunable Parameters):
WEIGHT_TEXT_MODALITY: Float (e.g., 0.5) - How much to weight text-based similarity.WEIGHT_VISUAL_MODALITY: Float (e.g., 0.5) - How much to weight visual similarity.- Note: These weights can be adjusted based on desired retrieval behavior or learned from data.
2. Main Function: MultiModalImageRetrieval FUNCTION MultiModalImageRetrieval(query_input, query_type_enum, top_k_results):
// query_input: Can be a String (for TEXT_QUERY) or an Image Object (for IMAGE_QUERY)
// query_type_enum: An ENUM { TEXT_QUERY, IMAGE_QUERY }
// top_k_results: Integer, desired number of top results to return
IF query_type_enum IS TEXT_QUERY THEN
RETURN SearchByTextQuery(query_input, top_k_results)
ELSE IF query_type_enum IS IMAGE_QUERY THEN
RETURN SearchByImageQuery(query_input, top_k_results)
ELSE
PRINT "Error: Invalid query type provided."
RETURN EMPTY_LIST
END FUNCTION
3. Helper Function: SearchByTextQuery (Handles multi-modal ranking) FUNCTION SearchByTextQuery(text_query_string, top_k_results):
// --- Phase 1: Generate Query Embeddings ---
query_text_embedding = EmbedModel_Text(text_query_string)
// For cross-modal models like CLIP, the text encoder can generate an embedding
// that is semantically aligned with the visual embedding space.
query_visual_conceptual_embedding = EmbedModel_Text(text_query_string)
// --- Phase 2: Perform Individual Modality Searches ---
text_similarity_scores = Map<ImageId, Float> // Stores {ImageId: text_similarity_score}
visual_similarity_scores = Map<ImageId, Float> // Stores {ImageId: visual_similarity_score}
// Search ImageTextDescriptions for textual semantic similarity
FOR EACH (image_id, image_text_embedding) IN Collection_ImageTextDescriptions:
score = Similarity(query_text_embedding, image_text_embedding)
text_similarity_scores[image_id] = score
// Search ImageVisualFeatures for visual similarity (cross-modal from text query)
FOR EACH (image_id, image_visual_embedding) IN Collection_ImageVisualFeatures:
score = Similarity(query_visual_conceptual_embedding, image_visual_embedding)
visual_similarity_scores[image_id] = score
// --- Phase 3: Combine and Rank Results (Multi-modal Fusion) ---
combined_relevance_scores = Map<ImageId, Float>
// Get all unique ImageIds that appeared in either search
all_involved_image_ids = UNION(KEYS(text_similarity_scores), KEYS(visual_similarity_scores))
FOR EACH image_id IN all_involved_image_ids:
// Retrieve individual scores, defaulting to 0.0 if not found in a modality
score_from_text = GET_VALUE_OR_DEFAULT(text_similarity_scores, image_id, 0.0)
score_from_visual = GET_VALUE_OR_DEFAULT(visual_similarity_scores, image_id, 0.0)
// Combine scores using predefined weights
combined_score = (WEIGHT_TEXT_MODALITY * score_from_text) + (WEIGHT_VISUAL_MODALITY * score_from_visual)
combined_relevance_scores[image_id] = combined_score
// --- Phase 4: Sort and Return Top K Results ---
// Sort images by their combined_score in descending order
sorted_results = SORT_MAP_BY_VALUE_DESC(combined_relevance_scores)
// Return the top K images (ImageId and their combined score)
RETURN TOP_K_ENTRIES(sorted_results, top_k_results)
END FUNCTION
4. Helper Function: SearchByImageQuery (Primarily visual search as per scenario) FUNCTION SearchByImageQuery(input_image_object, top_k_results):
// --- Phase 1: Generate Query Embedding ---
query_visual_embedding = EmbedModel_Image(input_image_object)
// --- Phase 2: Perform Visual Similarity Search ---
visual_similarity_scores = Map<ImageId, Float> // Stores {ImageId: visual_similarity_score}
// Search ImageVisualFeatures for pure image-to-image visual similarity
FOR EACH (image_id, image_visual_embedding) IN Collection_ImageVisualFeatures:
score = Similarity(query_visual_embedding, image_visual_embedding)
visual_similarity_scores[image_id] = score
// --- Phase 3: Rank Results ---
// For an image query, the scenario primarily focuses on visual similarity.
// No explicit multi-modal combination with ImageTextDescriptions is specified
// unless an intermediate text query is derived from the image (e.g., via captioning),
// which is beyond the current scenario description.
// --- Phase 4: Sort and Return Top K Results ---
// Sort images by their visual_similarity_scores in descending order
sorted_results = SORT_MAP_BY_VALUE_DESC(visual_similarity_scores)
// Return the top K images (ImageId and their visual score)
RETURN TOP_K_ENTRIES(sorted_results, top_k_results)
END FUNCTION
Explanation of Key Concepts in Pseudo-code: - Collections (Vector Databases): Represented as Maps where
ImageId maps to its respective embedding vector. In a real system, these would be managed by a dedicated vector database (e.g., Milvus, Pinecone, Qdrant) which offers efficient approximate nearest neighbor (ANN) search. - Embedding Models: Abstract functions for converting raw text or images into high-dimensional vector representations.
- Similarity Function: A metric (like Cosine Similarity) to quantify how "alike" two vectors are. Higher scores mean greater similarity.
- Text Query Flow:
1. Dual Embedding: The text query is embedded twice: once as a "text embedding" (for comparison with ImageTextDescriptions) and once as a "visual conceptual embedding" (for comparison with ImageVisualFeatures). This leverages cross-modal models like CLIP, where text and image embeddings can exist in a shared, semantically meaningful space.
2. Separate Searches: Two independent similarity searches are performed against ImageTextDescriptions and ImageVisualFeatures.
3. Combined Ranking: The scores from both searches are fused using weighted summation. This ensures that images performing well in both textual and visual aspects receive a higher final score, aligning with the "robust search" goal.
4. Top K: Results are sorted by the combined score, and the top k are returned. 1. Visual Embedding: The input image is embedded into its visual vector representation.
2. Visual Search: A single similarity search is performed against ImageVisualFeatures to find visually similar images.
3. Ranking: Results are ranked solely based on their visual similarity score, as per the scenario's emphasis on visual similarity for image-to-image search.
4. Top K: The top k most visually similar images are returned. GET_VALUE_OR_DEFAULT: Handles cases where an image might only appear in one of the similarity search results (e.g., an image has a visual feature but no associated text description, or vice-versa for the top results of each search). This ensures all images considered for ranking get a score for both modalities, even if one is zero.
|