Image embeddings are numerical representations (vectors) of images that capture their semantic meaning and visual characteristics.
Instead of storing raw pixel data, an embedding transforms an image into a high-dimensional vector where images with similar content or style are located closer to each other in the vector space.
This transformation allows computers to understand and compare images based on their underlying features rather than just pixel-level differences.
The Role of Image Embeddings in Vector Databases
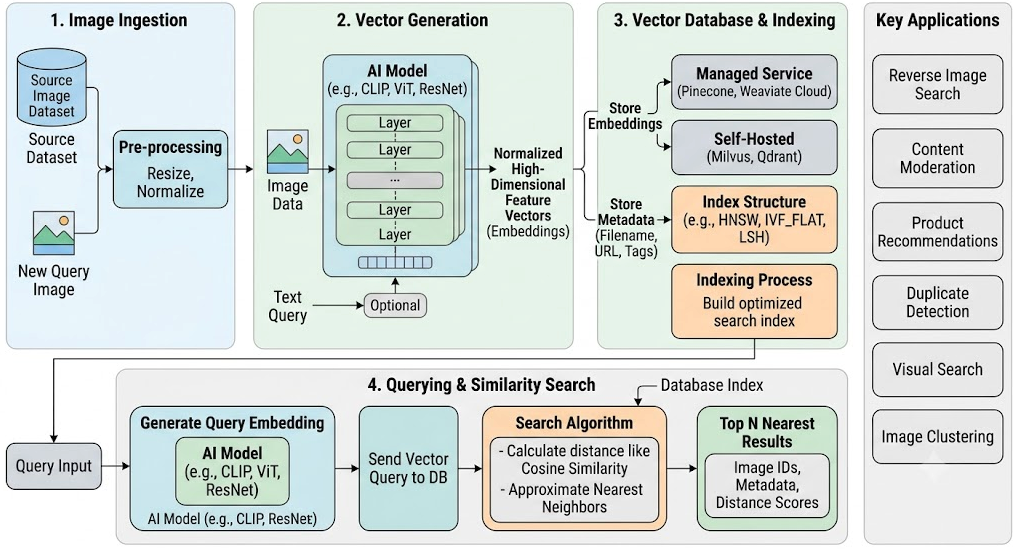
Vector databases are specialized databases designed to store, index, and query these high-dimensional vectors efficiently. When building a vector database with image embeddings:
Semantic Search: It enables querying images based on their visual content and meaning, not just exact keywords or metadata. For example, you can search for "images of happy dogs playing" even if the image files aren't explicitly tagged with those keywords.
Similarity Search: The primary use case is finding images that are "similar" to a given query image or a textual description (if using multimodal embeddings). This is done by calculating the distance (e.g., cosine similarity, Euclidean distance) between vectors.
Scalability: Vector databases are optimized for performing similarity searches across millions or billions of vectors quickly, which is crucial for large image collections.
Generating Image Embeddings
The process of generating image embeddings typically involves using pre-trained deep learning models.
Models and Techniques
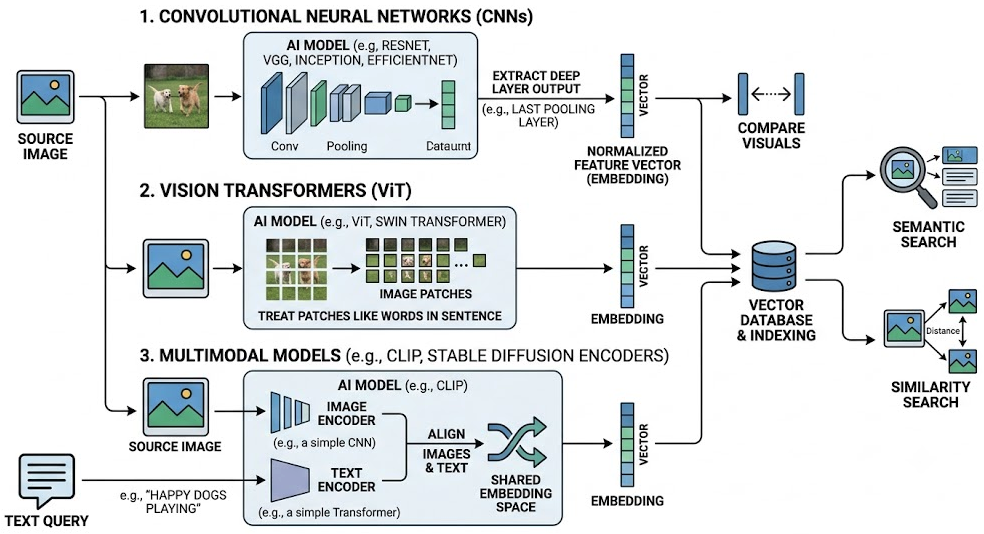
Convolutional Neural Networks (CNNs): Traditional state-of-the-art for image processing. Models like ResNet, VGG, Inception, or EfficientNet can be used. The output from a layer deep within the network (e.g., the last pooling layer before the classification head) is often taken as the embedding vector. These models are typically trained on large datasets like ImageNet for image classification.
Vision Transformers (ViT): Based on the transformer architecture, originally designed for NLP. ViT models process images by splitting them into patches and treating these patches like words in a sentence.
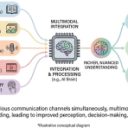
Multimodal Models (e.g., CLIP, DALL-E 2, Stable Diffusion's Encoders): These models are trained to understand both images and text, often by aligning them in a shared embedding space.
CLIP (Contrastive Language–Image Pre-training): A popular choice, CLIP can generate embeddings for both images and text such that visually similar images have embeddings close to text descriptions that describe them. This is excellent for zero-shot image classification and text-to-image search.
Diffusion Model Encoders: Components of models like Stable Diffusion (e.g., the VAE encoder or a separate text encoder in a multimodal setup) can also produce useful embeddings.
Image Embedding Process
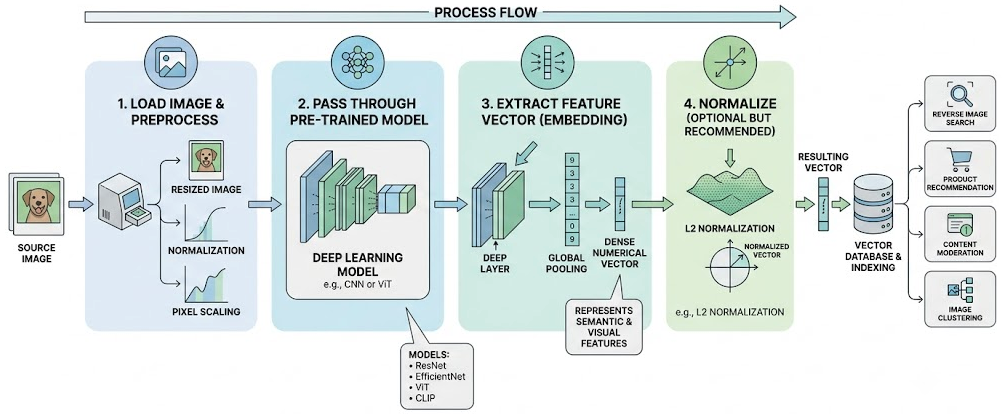
Load Image: The image is loaded into memory, often resized and preprocessed according to the requirements of the chosen model (e.g., normalization, pixel value scaling).
Pass Through Model: The preprocessed image is fed into the pre-trained deep learning model.
Extract Feature Vector: An intermediate layer's output (often a global pooling layer or the final embedding layer) is extracted. This output is the dense numerical vector representing the image's features.
Normalize (Optional but Recommended): The vector is often normalized (e.g., L2 normalization) to a unit vector, which is beneficial for cosine similarity calculations.
Image Embedding Tools and Libraries
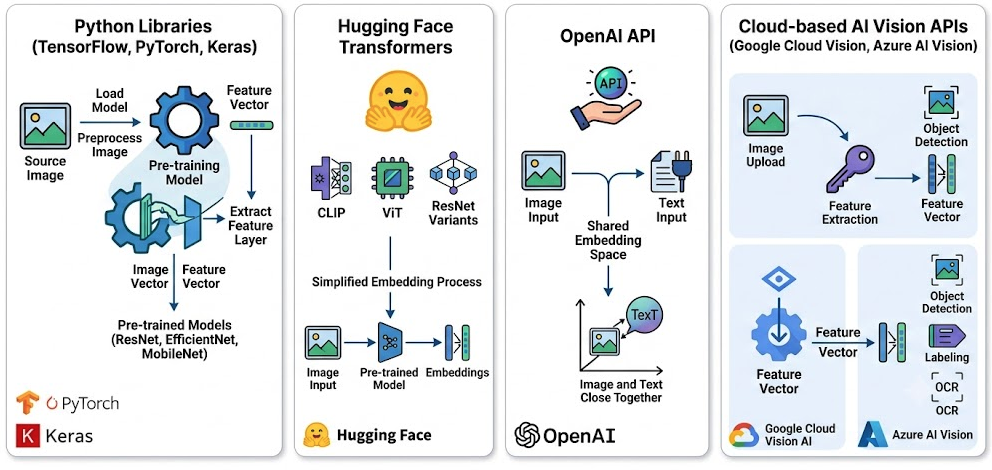
Python Libraries: TensorFlow, PyTorch, Keras for loading models and processing images.
Hugging Face Transformers: Provides easy access to many pre-trained models (ViT, CLIP, ResNet variants) and simplifies the embedding generation process.
OpenAI API: Offers access to models like CLIP for generating embeddings, particularly useful for integrating text and image search.
Google Cloud Vision AI/Azure AI Vision: Cloud-based APIs that can perform various image analysis tasks, including feature extraction which can be used to derive embeddings.
Building a Vector Database with Image Embeddings
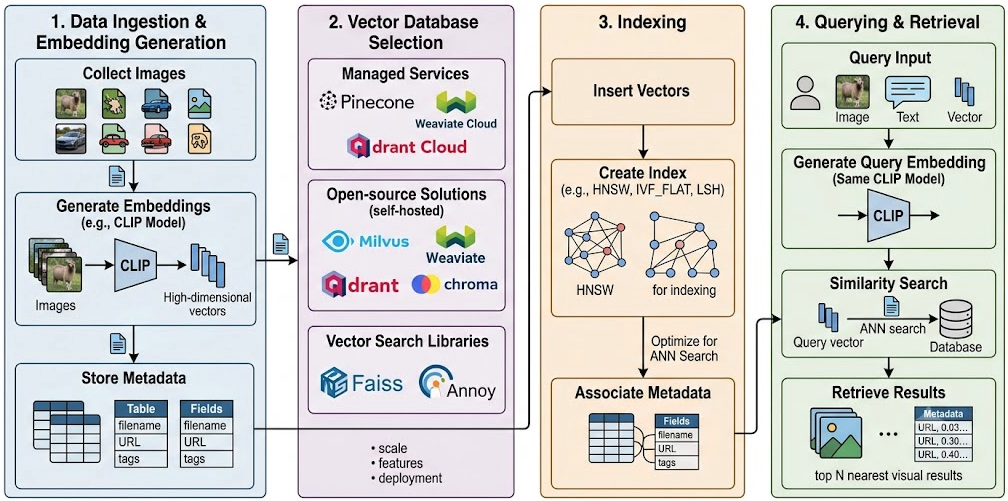
The steps to construct a functional vector database for images are:
1. Data Ingestion and Embedding Generation
Collect Images: Gather your dataset of images.
Generate Embeddings: For each image, use a chosen model (e.g., CLIP) to generate its corresponding high-dimensional vector embedding.
Store Metadata: Optionally, but highly recommended, extract and store any relevant metadata associated with each image (e.g., filename, original URL, category, tags, captions, upload date).
2. Vector Database Selection
Choose a vector database or library based on your requirements for scale, features, and deployment:
Vector Search Libraries: Faiss (Facebook AI Similarity Search) or Annoy (Approximate Nearest Neighbors Oh Yeah) for building custom indexing solutions within existing databases.
3. Indexing
Insert Vectors: Ingest the generated image embeddings into your chosen vector database.
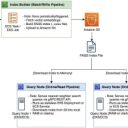
Create Index: The vector database will automatically or through configuration create an index (e.g., HNSW - Hierarchical Navigable Small World, IVF_FLAT, LSH - Locality Sensitive Hashing). This index optimizes approximate nearest neighbor (ANN) search, making queries fast even with millions of vectors.
Associate Metadata: Link the image metadata with its corresponding vector entry in the database.
4. Querying and Retrieval
Query Input: A user provides a query, which can be:
Another image: To find visually similar images.
Text description: To find images matching a semantic description (requires a multimodal model like CLIP for embedding the text query).
A vector: If the query is already an embedding.
Generate Query Embedding: If the query is an image or text, it is passed through the same embedding model used for the database images to generate its vector.
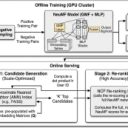
Similarity Search: The query embedding is sent to the vector database, which performs an ANN search against its indexed embeddings.
Retrieve Results: The database returns the top N nearest (most similar) image embeddings, along with their associated metadata (e.g., image IDs, URLs, captions). These results can then be displayed to the user.
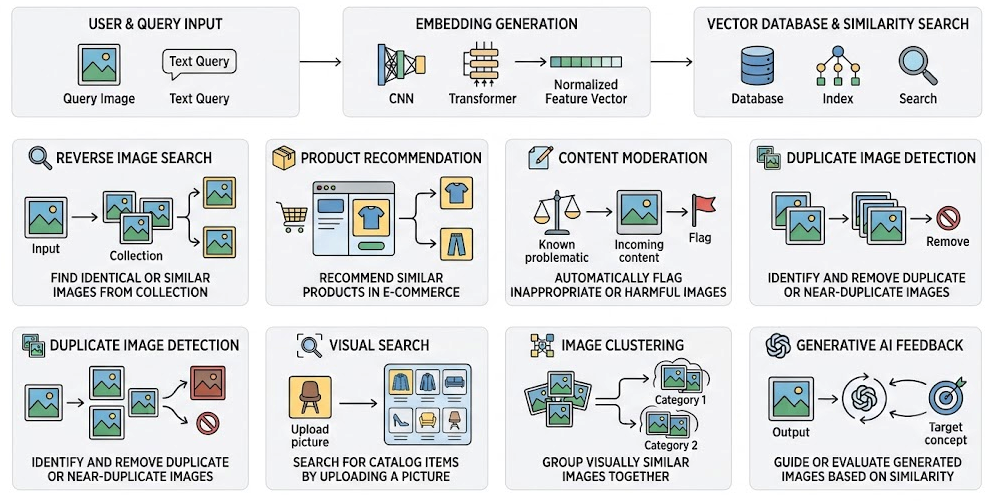
Applications and Use Cases
Reverse Image Search: Find identical or visually similar images from a large collection using an input image.
Product Recommendation: Recommend similar products in e-commerce based on visual features.
Content Moderation: Automatically flag inappropriate or harmful images by comparing them to known problematic content.
Duplicate Image Detection: Identify and remove duplicate or near-duplicate images in large datasets.
Visual Search: Search for items in a catalog by simply uploading a picture, common in fashion and home decor apps.
Image Clustering: Group visually similar images together for organization or analysis.
Generative AI Feedback: Use image embeddings to guide or evaluate generated images based on similarity to target images or concepts.
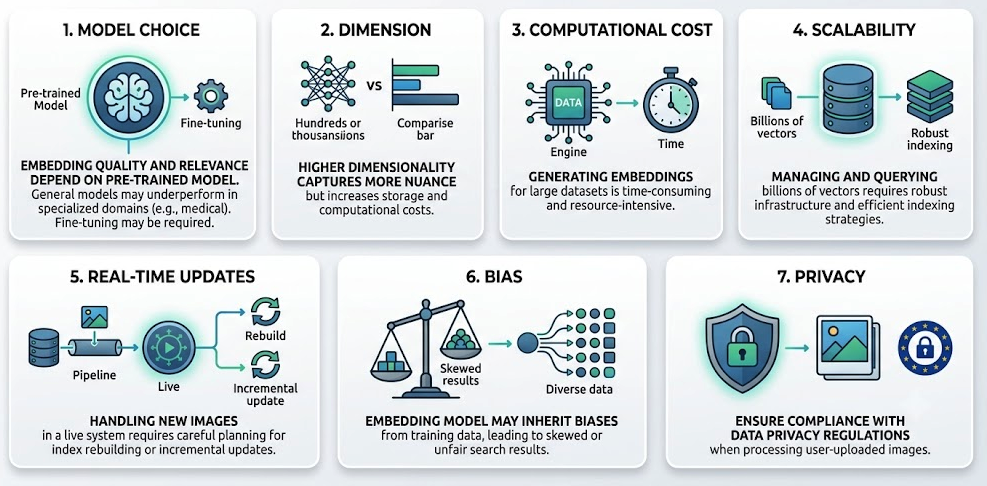
Challenges and Considerations
Model Choice: The quality and relevance of embeddings heavily depend on the pre-trained model used. A model trained on a general dataset might not perform optimally for highly specialized image domains (e.g., medical imaging). Fine-tuning might be necessary.
Dimensionality: Embeddings can have hundreds or thousands of dimensions. Higher dimensionality can capture more nuanced information but increases storage and computational costs.
Computational Cost: Generating embeddings for large datasets can be time-consuming and resource-intensive.
Scalability: Managing and querying billions of vectors requires robust infrastructure and efficient indexing strategies.
Real-time Updates: Handling new images or updates to the embedding model in a live system requires careful planning for index rebuilding or incremental updates.
Bias: The embedding model may inherit biases from its training data, leading to skewed or unfair search results.
Privacy: If processing user-uploaded images, ensure compliance with data privacy regulations.