Vector Database Integration on Fully Managed Multi-Agent Environment
CK 3788 Created at Updated at
31900
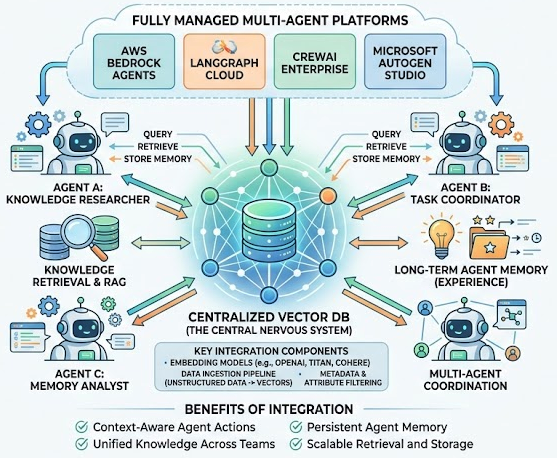
Integrating a Vector Database (Vector DB) into a Fully Managed Multi-Agent Environment (such as AWS Bedrock Agents, LangGraph Cloud, CrewAI Enterprise, or Microsoft AutoGen Studio) requires a highly structured architectural approach.
In a multi-agent system, agents act as autonomous entities that need to retrieve knowledge, store short-term/long-term memories, and coordinate actions. The Vector DB acts as the central nervous system for agent memory and knowledge retrieval.
Here is a comprehensive approach to building and integrating a Vector Database in this environment.
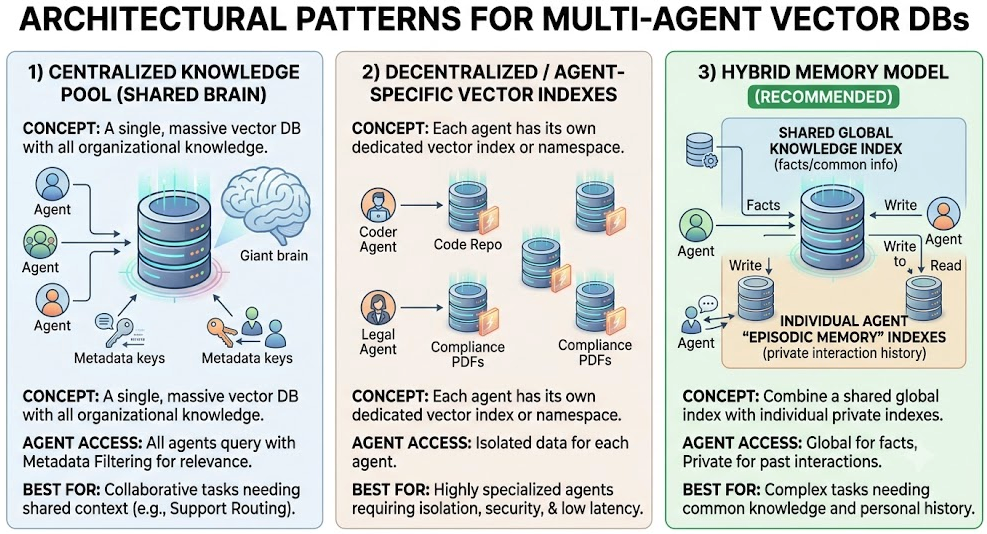
1. Architectural Patterns for Multi-Agent Vector DBs
Depending on your use case, you should choose one of three structural patterns:
1) Centralized Knowledge Pool (Shared Brain)
Concept: A single, massive vector database instance containing all organizational knowledge.
Agent Access: All agents query the same database but use metadata filtering to access relevant partitions.
Best For: Collaborative tasks where agents need a shared understanding of the context (e.g., customer support routing).
2) Decentralized / Agent-Specific Vector Indexes
Concept: Each agent has its own dedicated vector index or namespace.
Agent Access: Isolated. The "Coder Agent" has access only to code repositories, while the "Legal Agent" has access only to compliance PDFs.
Best For: Highly specialized agents requiring strict data isolation, security boundaries, and low latency.
3) Hybrid Memory Model (Recommended)
Concept: Combining a shared global knowledge index with individual agent "episodic memory" indexes.
Agent Access: Agents query global data for facts and write to/read from their private indices to remember past interactions and steps taken.
2. Step-by-Step Building Approach
Step 1: Selection of a Serverless/Managed Vector DB
Since the multi-agent environment is fully managed, the Vector DB should be too, ensuring seamless scaling, low maintenance, and pay-as-you-go pricing.
Top Choices:
Pinecone Serverless: Great for rapid scaling and low-latency keyword+vector search.
Qdrant Cloud: Highly customizable, excellent support for payload (metadata) filtering.
Milvus/Zilliz Cloud: Best for enterprise-grade, massive scale.
AWS OpenSearch Serverless / Azure AI Search: Best if your multi-agent system is natively hosted on AWS or Azure.
Step 2: Metadata Schema Design (Crucial for Multi-Agent)
In a multi-agent setup, pure vector similarity is not enough. Agents need to filter results dynamically. Define a strict metadata schema for every vector inserted:
Implement two pipelines for data entering the Vector DB:
Static/Batch Ingestion (Knowledge Base): Ingests company wikis, PDFs, and databases. Use advanced chunking (e.g., semantic chunking) and embed them using models like text-embedding-3-large or cohere-embed-v3.
Dynamic/Real-Time Ingestion (Agent Memory): As agents interact, they should write their thought logs, intermediate results, and tool outputs back into the Vector DB under a session_history tag.
Step 4: Building the "Retrieval Tool" for Agents
In a managed multi-agent environment, agents interact with external systems via "Tools" (or plugins/functions). You must build a Vector DB Retrieval Tool that the orchestrator can expose to the agents.
Example Tool Definition (Python pseudocode for an agent):
def query_vector_db(query: str, agent_context: str) -> str:
    """
    Search the company database for relevant information.
    Only returns documents authorized for the calling agent.
    """
    embedding = embedding_client.get_embedding(query)

    # Enforce security and relevance via metadata filtering
    results = vector_db.query(
        vector=embedding,
        top_k=3,
        filter={
            "access_control_level": {"$in": get_agent_permissions(agent_context)}
        }
    )
    return format_results_for_llm(results)
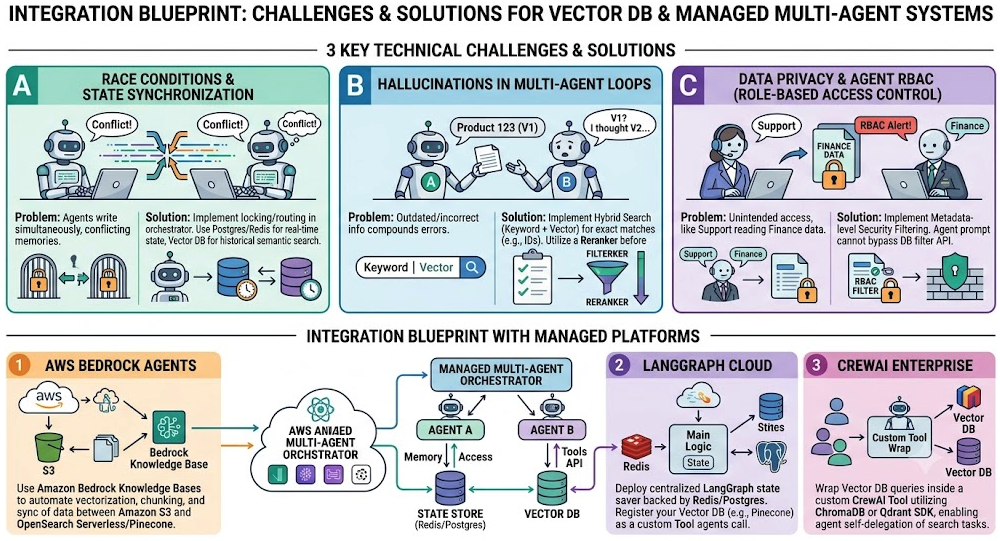
3. Key Technical Challenges & Solutions
A. Race Conditions and State Synchronization
The Problem: Two agents are writing to the Vector DB simultaneously regarding the same task, causing conflicting memories.
The Solution: Implement a locking mechanism or routing protocol in the multi-agent orchestrator. Use a relational database (like PostgreSQL/Redis) for real-time state tracking, and use the Vector DB only for semantic historical search.
B. Hallucinations in Multi-Agent Loops
The Problem: Agent A retrieves outdated or slightly incorrect information from the Vector DB and passes it to Agent B, compounding the error.
The Solution:
Implement Hybrid Search (combining sparse keyword search with dense vector search) to ensure exact matches (like product IDs) are retrieved accurately.
Utilize a Reranker (e.g., Cohere Rerank or BGE-Reranker) before feeding the retrieved context to the agent.
C. Data Privacy and Agent RBAC (Role-Based Access Control)
The Problem: A "Customer Support Agent" accidentally accesses financial data meant only for the "Finance Agent."
The Solution: Implement strict Metadata-level Security Filtering at the query layer. The agent's system prompt must not be able to bypass the Vector DB query filter API.
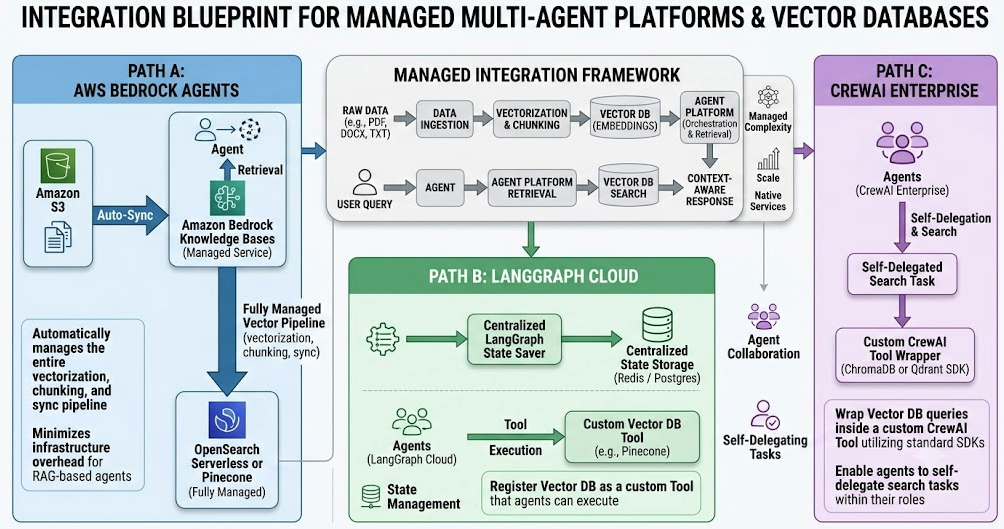
4. Integration Blueprint with Managed Platforms
If you are deploying in a managed environment:
If using AWS Bedrock Agents: Use Amazon Bedrock Knowledge Bases, which automatically manages the vectorization, chunking, and sync of data between Amazon S3 and OpenSearch Serverless/Pinecone.
If using LangGraph Cloud: Deploy a centralized LangGraph state saver backed by Redis/Postgres, and register your Vector DB (e.g., Pinecone) as a custom Tool that agents can call.
If using CrewAI Enterprise: Wrap your Vector DB queries inside a custom CrewAI Tool utilizing the ChromaDB or Qdrant SDK, enabling the agents to self-delegate search tasks.