Building GPU Clusters on GCP, Azure, and AWS: A Practical Guide and Head-to-Head Comparison
CK 3788 Created at
34600
Training frontier models, running large-scale simulations, or serving inference at production volume all come back to the same infrastructure question: how do you stand up a fleet of GPUs that actually behaves like one machine? Individual H100s are fast; a poorly wired cluster of them is not. This post walks through how to build GPU clusters on Google Cloud, Microsoft Azure, and Amazon Web Services in 2026, using the tooling each provider actually recommends today, and then compares them across the dimensions that matter when you are picking one.
What "GPU clustering" really means
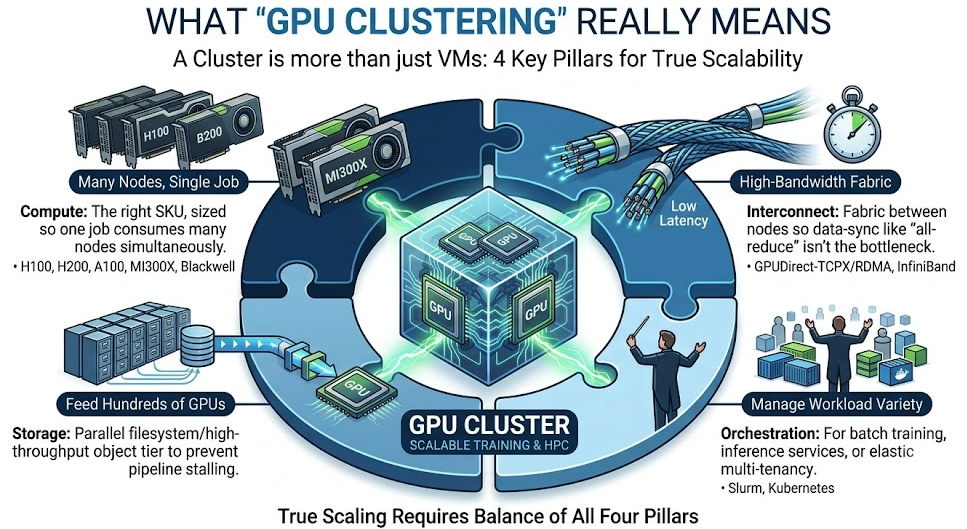
A GPU cluster is more than a group of GPU VMs. To make training or HPC workloads scale, four things have to line up:
Compute — the right GPU SKU (H100, H200, A100, MI300X, or the newer Blackwell parts), sized so a single job can consume many nodes at once.
Interconnect — high-bandwidth, low-latency fabric between nodes so all-reduce and all-gather do not become the bottleneck. This is where GPUDirect-TCPX/RDMA and InfiniBand live.
Storage — a parallel filesystem or high-throughput object tier that can feed hundreds of GPUs without stalling the pipeline.
Orchestration — Slurm for classical HPC-style batch training, or Kubernetes when workloads look more like services (inference, elastic training, multi-tenant research).
All three hyperscalers have converged on essentially the same shape of answer, but they package it differently. But before you provision anything, take a step back — not every workload needs a GPU, let alone a cluster of them.
When do you actually need a GPU (and when a cluster)?
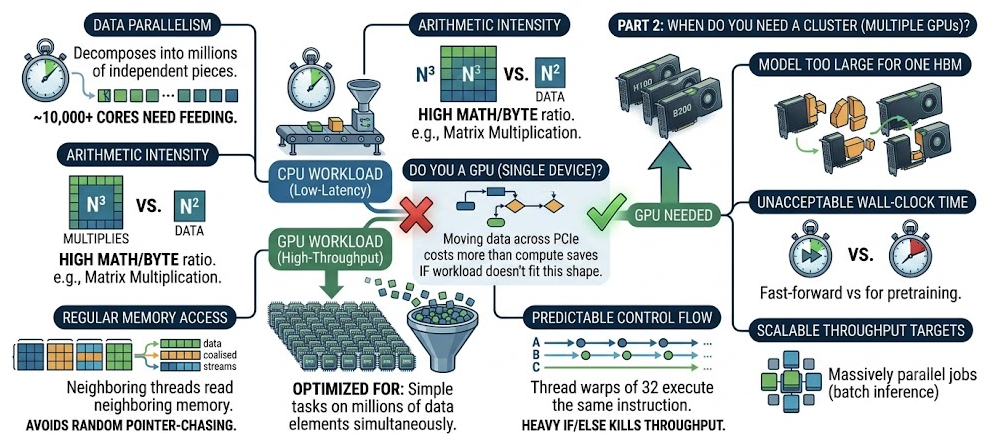
The one-line rule: use a GPU when the same simple operation has to run on a huge number of independent data elements at the same time. CPUs are optimized for doing complex things one after another with low latency; GPUs are optimized for doing one thing to millions of elements at once with high throughput. If your problem doesn't have that shape, a GPU won't help — it may even hurt, because moving data across PCIe costs more than the compute saves.
A workload is GPU-friendly when it has most of these four properties:
Data parallelism — the work decomposes into thousands or millions of independent pieces. A GPU has ~10,000+ cores; you need enough parallel work to feed them.
Arithmetic intensity — a lot of math per byte of data moved. This is why matrix multiplication is the poster child (N³ multiplies for N² data) and why plain "add two arrays" often runs faster on the CPU.
Regular memory access — neighboring threads read neighboring memory. Random pointer-chasing (linked lists, hash maps) is slow on a GPU because it can't coalesce loads.
Predictable control flow — every thread in a warp of 32 executes the same instruction. Heavy if/else divergence kills throughput.
Software patterns that fit
Dense linear algebra — matmuls, convolutions, FFTs. Foundation of deep learning and most scientific computing (cuBLAS, cuDNN, CUTLASS).
Element-wise and reduction ops on large arrays — Thrust, CUB, CuPy, RAPIDS.
Ray tracing and rasterization — millions of independent rays or pixels.
Signal, image, and video processing — convolutions, FFTs, video codecs.
Cryptography and brute force — hashing, password cracking.
GPU-accelerated analytics — RAPIDS cuDF, BlazingSQL, when the data fits in HBM.
Concrete examples
Workload
Why the GPU wins
Training a GPT-style LLM
Every forward/backward pass is a chain of huge matmuls. H100 tensor cores are literally purpose-built for this.
ResNet inference at high QPS
Each batch is one matmul chain; a GPU does thousands of images/sec vs. tens on CPU.
Weather forecasting (WRF, ICON)
Millions of atmospheric grid cells × identical stencil math per timestep.
Molecular dynamics (GROMACS, AMBER)
Millions of atom-pair force calculations, all independent per timestep.
Monte Carlo option pricing
Millions of independent random paths, same math on each.
Ray-traced 3D rendering
Every pixel is an independent ray bundle.
Genomics (Parabricks, BWA-GPU)
Sequence alignment scored across millions of reads in parallel.
Video transcoding (FFmpeg + NVENC)
Every macroblock encodes independently, and there's dedicated silicon for it (see Part 4).
When a GPU is the wrong tool
Serving a low-QPS REST API that calls a database. Compiling code. Parsing log files. Small ML models on 10k rows of tabular data. Any workload where the input is a few kilobytes and you need the answer in a millisecond — startup and copy overhead will dwarf any win.
From "one GPU" to "a cluster"
You need a cluster (rather than a single GPU box) when either the model doesn't fit in one GPU's HBM (LLMs above ~10B parameters at bf16), or the wall-clock time on one node is unacceptable (multi-week pretraining runs), or the throughput target requires many parallel workers (batch inference, video transcoding at scale). Everything below is about building that second thing.
A useful heuristic before you provision: prototype on one GPU and profile. If nvidia-smi shows SM utilization pinned above 70% during your job, you have a real GPU workload and scaling out will help. If it hovers below 20%, either your batch size is too small, your data pipeline is starving the device, or the problem itself isn't parallel enough — and no amount of adding more H100s will fix that.
Part 1 — Building a GPU cluster on Google Cloud
The stack, in one paragraph
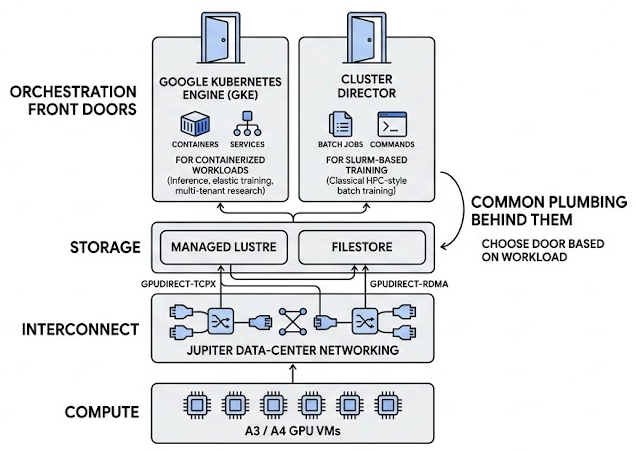
Google's story in 2026 is AI Hypercomputer: an opinionated bundle of A3/A4 GPU VMs, Jupiter data-center networking with GPUDirect-TCPX or RDMA, Managed Lustre or Filestore for storage, and two orchestration front doors — Google Kubernetes Engine (GKE) for containerized workloads and Cluster Director (built on the open-source Cluster Toolkit, formerly HPC Toolkit) for Slurm-based training. Choose one door based on how your workload runs; the plumbing behind them is the same.
Step 1 — Pick a machine family
The current families you will actually deploy:
A3 High / A3 Mega — 8×H100 per node, Sapphire Rapids CPUs. The workhorse for most H100 training in 2026.
A3 Ultra — 8×H200 with 3.2 Tbps of GPU networking (RDMA over Converged Ethernet).
Reservations, Flex-start, and Spot are all valid consumption models — plan for reservations if you need capacity guarantees on the Ultra/A4 tiers.
Step 2 — Choose your orchestration door
Slurm path (Cluster Director / Cluster Toolkit):
# Install the toolkit
git clone https://github.com/GoogleCloudPlatform/cluster-toolkit.git
cd cluster-toolkit && make

# Deploy a reference A3 Mega Slurm cluster
./gcluster deploy examples/machine-learning/a3-mega/a3-mega-slurm-cluster.yaml \
  --vars project_id=$PROJECT_ID,region=us-central1
The blueprint provisions the login node, Slurm controller, an A3 Mega compute nodeset, a Filestore or Managed Lustre volume, and the VPC — including the specialized GPU networking interfaces GPUDirect-TCPX needs. Health checks run NCCL bandwidth tests before the cluster is handed to you.
Add the NVIDIA GPU Operator or rely on GKE's managed driver installation, then layer JobSet or Kueue for gang scheduling of multi-node training jobs.
Step 3 — Wire up storage and networking
Storage: for training that reads many small files, use Managed Lustre (minimum ~10 TiB HIGH_SCALE_SSD for A3/A4 tiers). For checkpoints and shared code, Filestore or GCS with the Cloud Storage FUSE driver is enough.
Networking: A3 High/Mega use GPUDirect-TCPX over multiple NICs; A3 Ultra and above use GPUDirect-RDMA. Both require the multi-NIC VPC layout the Cluster Toolkit blueprints generate for you.
Step 4 — Validate before you burn budget
Run NCCL all-reduce benchmarks across the whole cluster. If you're seeing less than the advertised bandwidth per pair (e.g., ≥1.6 Tbps on Ultra), you have a fabric or placement problem, not a training problem. Fix it before you launch a two-week run.
Part 2 — Building a GPU cluster on Microsoft Azure
The stack, in one paragraph
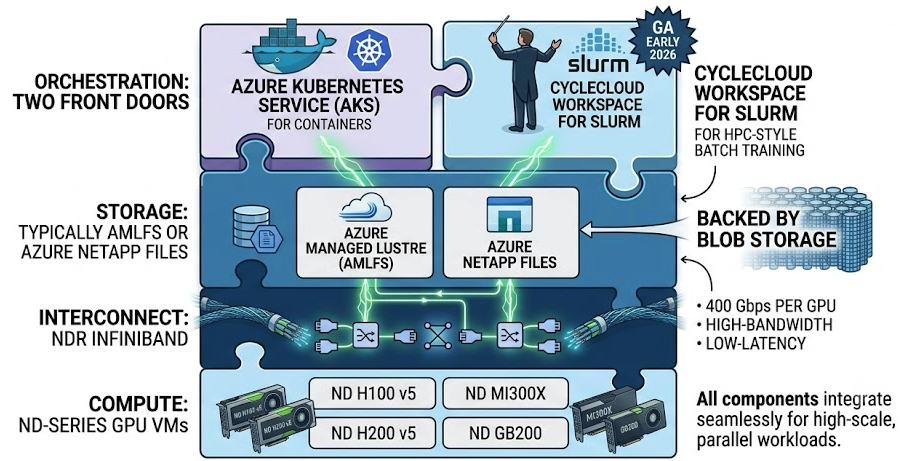
Azure's answer is built on the ND-series GPU VMs (ND H100 v5, ND H200 v5, and the newer ND MI300X and ND GB200 tiers), stitched together with NDR InfiniBand at 400 Gbps per GPU. The two orchestration front doors are Azure Kubernetes Service (AKS) for containers and CycleCloud Workspace for Slurm — which went GA in early 2026 as Microsoft's turnkey Slurm-on-Azure product — for HPC-style batch training. Storage typically means Azure Managed Lustre (AMLFS) or Azure NetApp Files, backed by Blob Storage.
Step 1 — Pick a machine family
ND H100 v5 (Standard_ND96isr_H100_v5) — 8×H100 SXM5, 3.2 Tbps NDR InfiniBand between nodes. The mainstream H100 SKU.
ND H200 v5 — 8×H200, same 3.2 Tbps IB fabric, more HBM.
ND MI300X v5 — 8×AMD MI300X for teams targeting ROCm.
ND GB200 v6 — Blackwell superchip nodes for the newest generation.
Availability is regional and often reservation-gated for the Blackwell tiers — check quota before you plan a launch.
Step 2 — Choose your orchestration door
Slurm path (CycleCloud Workspace for Slurm):
CycleCloud Workspace is deployed from the Azure Marketplace as an ARM template. You point it at a subscription, pick a region, and it provisions:
A CycleCloud server VM
A Slurm scheduler
Autoscaling ND-series node arrays (spun up on demand as jobs queue)
An AMLFS or ANF filesystem
The InfiniBand-enabled VNet
From there, sbatch and srun behave exactly as they would on-prem. The multi-node, multi-GPU NCCL benchmarks Microsoft publishes show the fabric works out of the box provided you use their VM image (Ubuntu HPC images ship with the OFED stack and NCCL topology files preinstalled).
Kubernetes path (AKS):
az aks create -g rg-gpu -n gpu-aks \
  --node-count 1 --generate-ssh-keys \
  --network-plugin azure

az aks nodepool add -g rg-gpu --cluster-name gpu-aks -n ndh100 \
  --node-count 4 \
  --node-vm-size Standard_ND96isr_H100_v5 \
  --node-taints sku=gpu:NoSchedule \
  --skip-gpu-driver-install false
Then follow Microsoft's GPU best-practices playbook:
Taint GPU nodes with nvidia.com/gpu: NoSchedule and add matching tolerations on GPU pods, so scheduler mistakes can't cost you an H100 for a nginx pod.
Validate the driver with kubectl exec … -- nvidia-smi and confirm the NVIDIA device plugin is running.
Split large GPUs with MIG (Multi-Instance GPU) for inference or multi-tenant research — an A100 or H100 becomes up to 7 isolated slices.
Use ephemeral NVMe (up to 28 TiB per ND-series VM) for checkpoint and dataset cache; move anything durable to AMLFS or Blob.
Isolate workloads with namespaces and NetworkPolicies when the cluster is shared.
For multi-node training on AKS, the Kubernetes AI Toolchain Operator (KAITO) or Kubeflow's training operator plus the NVIDIA network operator (for InfiniBand SR-IOV) is the usual pattern.
Step 3 — Wire up storage and networking
Storage: Azure Managed Lustre (AMLFS) is the default for high-throughput training I/O; Azure NetApp Files is the alternative for teams that need NFS semantics. Cold data sits in Blob Storage and is staged in.
Networking: NDR InfiniBand is always on between ND-series VMs — you don't need a separate NIC configuration, but you do need to place them in the same VM Scale Set and IB group. CycleCloud handles this; on AKS you configure it via the node pool.
Step 4 — Validate
Same rule as GCP: run NCCL all-reduce across the full cluster and compare against Microsoft's published numbers for your SKU before you commit to a long training run. Microsoft's HPC blog publishes a container-based NCCL benchmark you can drop straight into a CycleCloud job.
Part 3 — Building a GPU cluster on AWS
The stack, in one paragraph
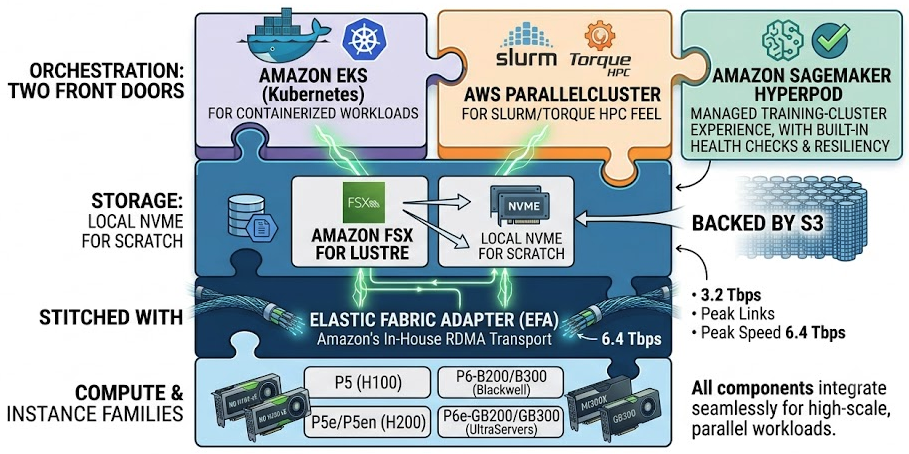
AWS packages GPU clusters around the P-family of EC2 instances (P5 for H100, P5e/P5en for H200, P6-B200 and P6-B300 for Blackwell, and P6e-GB200/GB300 UltraServers for the largest jobs), all stitched together with the Elastic Fabric Adapter (EFA) — Amazon's in-house RDMA transport that peaks at 3.2 Tbps on P5/P6-B200 and 6.4 Tbps on P6-B300. The orchestration front doors are more numerous than on GCP or Azure: Amazon EKS for containers, AWS ParallelCluster for a Slurm/Torque HPC feel, and Amazon SageMaker HyperPod for a managed training-cluster experience with built-in health checks and resiliency. Storage is almost always Amazon FSx for Lustre, backed by S3, with local NVMe on the instance for scratch.
Step 1 — Pick an instance family
p5.48xlarge — 8×H100 SXM5, 640 GB HBM3, 3.2 Tbps EFA. The 2026 mainstream for H100 training.
p5e.48xlarge / p5en.48xlarge — 8×H200, 1,128 GB HBM3e. Same fabric, more memory per GPU (helpful for MoE or long-context training).
p6-b300.48xlarge — 8×Blackwell Ultra (B300), 2,144 GB HBM3e, 6.4 Tbps EFA. The current top single-instance.
P6e-GB200 / P6e-GB300 UltraServers — 36 or 72 GPUs behind an NVLink switch presented as one logical server (e.g., u-p6e-gb200x72 with 72 Blackwell GPUs and 28.8 Tbps EFA). This is AWS's answer to trillion-parameter training.
Capacity is the interesting constraint here: P5 spot exists on paper but is famously scarce, so serious teams use Capacity Blocks for ML (buy a defined GPU cluster for a defined time window) or EC2 UltraClusters reservations rather than counting on spot.
ParallelCluster handles the VPC, EFA-enabled placement group, FSx for Lustre volume, the head node's Slurm controller, and autoscaling of the compute fleet. sbatch works exactly as on-prem.
Install the NVIDIA GPU Operator and the AWS EFA Kubernetes Device Plugin so pods can request vpc.amazonaws.com/efa resources alongside nvidia.com/gpu. For multi-node training, JobSet, Kubeflow, or Ray on EKS are the usual patterns.
Managed path (Amazon SageMaker HyperPod):
If you don't want to run either a Slurm cluster or a Kubernetes control plane, HyperPod gives you a persistent, resilient training cluster with baked-in features that matter at scale: automatic node replacement on hardware failure, deep health checks, and checkpoint auto-resume. You choose Slurm or EKS as the underlying orchestrator, but AWS operates the cluster's lifecycle. This is the closest thing on AWS to Azure's CycleCloud Workspace or GCP's Cluster Director.
Step 3 — Wire up storage and networking
Storage: FSx for Lustre is the default parallel filesystem, typically in PERSISTENT_2 mode, linked to an S3 bucket for cold data. Local NVMe (up to 8×3.84 TB per P5/P6 instance) handles checkpoint scratch and dataset cache.
Networking: EFA is the thing that makes an AWS GPU cluster a cluster. It must be enabled at instance launch, requires a cluster placement group, and needs a security group that allows all traffic to itself. NCCL uses EFA's SRD transport automatically once the AWS OFI NCCL plugin is installed (baked into the Deep Learning AMI).
Step 4 — Validate
Same discipline as the other two clouds: run the NCCL all-reduce benchmark across the whole cluster before you launch a real training job. On p5.48xlarge you should see near-3.2 Tbps aggregate at 8+ nodes; on p6-b300 you should see close to 6.4 Tbps. If you don't, check the placement group, the EFA security group, and that you're on the AWS Deep Learning AMI (or a container built from it).
Part 4 — A special case: media pipelines with FFmpeg
Not every GPU cluster is for training. A very common second use case is video transcoding at scale — batch VOD, live streaming, ML dataset preprocessing. It looks like it should just be "run FFmpeg on the training cluster," but there's a critical hardware caveat that catches teams off guard.
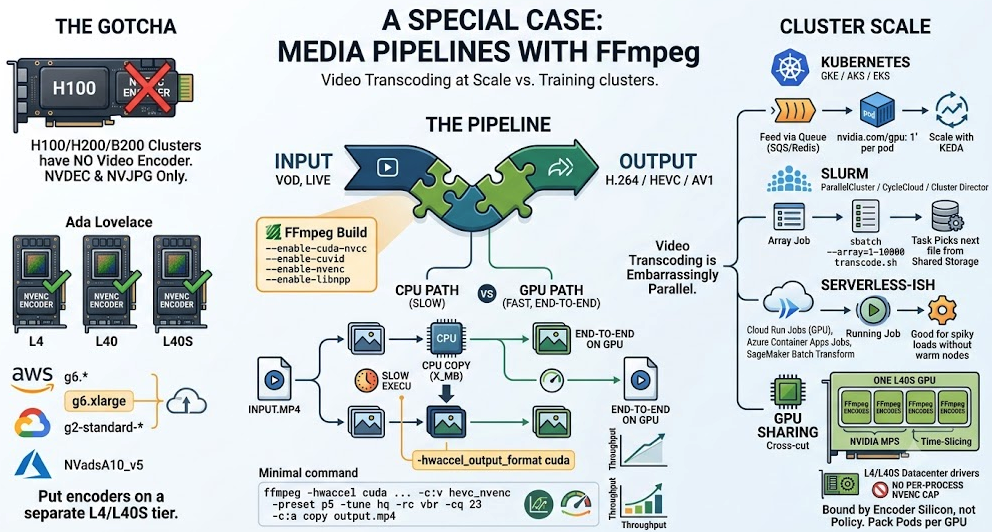
The gotcha: your H100/H200/B200 cluster has no video encoder
NVIDIA stripped the NVENC hardware block from the compute-focused datacenter GPUs — A100, H100, H200, and B200 all lack it. They keep NVDEC (decode) and NVJPG, but if you want hardware-accelerated H.264 / HEVC / AV1 encoding, you need the Ada Lovelace datacenter line: L4 (2 encoders), L40 or L40S (3 encoders each). NVIDIA A10 also works. On the three clouds:
AWS: g6.* (L4) and g6e.* (L40S). g6.xlarge is the cheap workhorse for transcoding fleets.
GCP: g2-standard-* (L4); L40S in selected zones.
Azure: NVadsA10_v5 (A10) or newer L40S-based NVL SKUs where offered.
You can still let the H100 cluster decode and run compute-side filters via CUDA, but put the encoders on a separate L4/L40S tier.
FFmpeg build and a minimal command
Grab an FFmpeg built with --enable-cuda-nvcc --enable-cuvid --enable-nvenc --enable-libnpp and the matching CUDA toolkit and Video Codec SDK headers (nv-codec-headers). Fastest path: an NVIDIA CUDA container with FFmpeg preinstalled. Verify with ffmpeg -hide_banner -encoders | grep nvenc — you should see h264_nvenc, hevc_nvenc, and on Ada, av1_nvenc.
A minimal transcoding command that keeps frames on the GPU end-to-end:
The -hwaccel_output_format cuda flag is what avoids the CPU-side memory copy that otherwise kills throughput.
Orchestration at cluster scale
Video transcoding is embarrassingly parallel — one file (or one HLS segment) per job — so you don't need NCCL or InfiniBand. Three patterns work in production:
Kubernetes (GKE / AKS / EKS) with the NVIDIA GPU Operator, each pod requesting nvidia.com/gpu: 1. Feed work in with a queue (SQS, Pub/Sub, Service Bus, or Redis) and scale the node pool with KEDA on queue depth. This is what most production VOD pipelines look like today.
Slurm (ParallelCluster / CycleCloud / Cluster Director) with an array job: sbatch --array=1-10000 transcode.sh, each task picking the next file off shared storage.
Serverless-ish: Cloud Run Jobs with GPU (L4 supported), Azure Container Apps Jobs, or SageMaker Batch Transform — good for spiky loads without keeping nodes warm.
Sharing a GPU across FFmpeg jobs
One L40S can run several concurrent FFmpeg encodes because NVENC is a separate silicon block from the CUDA cores. Enable NVIDIA MPS or the GPU Operator's time-slicing config to pack multiple pods per GPU. Datacenter drivers on L4/L40S have no per-process NVENC session cap (unlike consumer drivers), so throughput is bounded by encoder silicon, not by policy — benchmark your target codec/resolution and size the fleet from measured sessions-per-GPU.
Part 5 — Verifying the GPUs are actually doing the work
A common failure mode across all three clouds: the job runs, doesn't crash, and quietly falls back to CPU. Here's how to catch that.
The first command: nvidia-smi
Run it while the job is executing. The columns that tell the truth:
GPU-Util % — should be >0, ideally 50–95% at steady state. If it stays at 0, nothing GPU is happening.
Memory-Usage — your tensors/frames should show up. 0 MB means the CPU path is running.
Processes — your python or ffmpeg PID should be listed with its VRAM footprint.
For FFmpeg specifically, nvidia-smi dmon breaks out the encoder and decoder engines:
$ nvidia-smi dmon -s u
# gpu   sm   mem   enc   dec
#   0   72    41    83    12   ← encoder is at 83% = NVENC is actually running
If enc sits at 0% while your command claims h264_nvenc, something is wrong — usually a missing -hwaccel flag or a fallback because the input format wasn't uploaded to CUDA memory.
Continuous monitoring
nvtop — top-like curses UI with per-process GPU utilization and history graphs.
nvitop — Python-based, more info-dense, good process-tree view.
NVIDIA DCGM (dcgmi dmon) — the production option; per-second metrics for encoder/decoder/SM/memory bandwidth. Scrape it with the DCGM Prometheus exporter for cluster-wide Grafana dashboards.
On managed platforms, GCP Cloud Monitoring, Azure Monitor, and AWS CloudWatch all expose Accelerator/GPU metrics per instance without installing anything.
FFmpeg self-report
Run with -loglevel verbose. At startup FFmpeg prints which decoder/encoder was actually selected:
[h264_nvenc @ 0x...] Loaded Nvidia CUDA runtime
[h264 @ 0x...] Using hwaccel cuda
If you see no hwaccel line, the flags aren't taking effect. Also compare the fps in the progress line — NVENC on an L4 hits hundreds of fps at 1080p H.264; libx264 on CPU manages 30–80. The order-of-magnitude gap is the tell.
Application-level assertions
For ML frameworks, don't trust silence — assert on GPU presence in the code:
# PyTorch
import torch
assert torch.cuda.is_available(), "CUDA not available!"
print(torch.cuda.get_device_name(0), torch.cuda.device_count())
x = torch.randn(1024, device="cuda")
print(x.device)   # cuda:0

# TensorFlow
import tensorflow as tf
print(tf.config.list_physical_devices("GPU"))
For distributed training, log torch.cuda.utilization() per rank — very useful for spotting one rank silently running on CPU while the others crunch away.
Signs the GPU is technically used but the job is still CPU-bound
GPU-Util oscillates 0 → 100 → 0 → 100. Data loader is starving the GPU. Fix with more num_workers, prefetching, or a faster filesystem tier.
Power draw sits at idle (~70W on H100, ~30W on L4) despite an active process.
Fan and temperature barely move.
Throughput is a fraction of the datasheet number for your SKU.
The dumbest, most reliable check
Run once with the GPU disabled (CUDA_VISIBLE_DEVICES="" for CUDA workloads, or drop -hwaccel cuda for FFmpeg) and time it. Then run normally. If the two runtimes are within 20% of each other, the "GPU" run wasn't actually using the GPU for the hot path.
GCP's advantages. Predictable, mid-priced H100 and H200 capacity with the best-looking sticker prices at the mainstream tiers, sometimes meaningfully lower than AWS or Azure on spot. The Cluster Toolkit is genuinely well-designed — the same YAML blueprint that provisions your cluster is the artifact your platform team reviews and versions in Git, so "how was this built?" always has an answer. GKE has been running GPU workloads at scale for longer than AKS or EKS on the very newest SKUs, and it shows in the tooling around Kueue, JobSet, and DWS (Dynamic Workload Scheduler) for capacity-aware scheduling.
Azure's advantages. InfiniBand. If your training job is bandwidth-bound at very large scale — MoE models, dense LLM pretraining above 512 GPUs — the NDR IB fabric on ND H100/H200 v5 is a real advantage over Ethernet-based alternatives, both in raw performance and in how little tuning it requires to hit the number. CycleCloud Workspace for Slurm, now that it is GA, is the closest thing on the market to "on-prem Slurm cluster, but in the cloud" — teams migrating from an existing HPC center feel immediately at home. Enterprise integration (Entra ID, Purview, existing EA agreements) closes deals that pricing alone would not. And Azure is the only one of the three offering first-class AMD MI300X capacity.
AWS's advantages. The broadest and deepest lineup. AWS has the newest Blackwell tiers in general availability (P6-B200, P6-B300, and P6e-GB200/GB300 UltraServers with up to 72 GPUs behind a single NVLink switch), the fastest inter-node fabric on the market at 6.4 Tbps EFA on P6-B300, and — uniquely — three tiers of orchestration (ParallelCluster, EKS, and SageMaker HyperPod) instead of two. HyperPod's automated node replacement and checkpoint auto-resume genuinely change the economics of month-long training runs. On-demand H100 pricing on p5.48xlarge is currently the lowest of the three at the mainstream tier (~$6.88 / GPU-hour). The catch is capacity: P5 spot is scarce, so serious teams buy Capacity Blocks for ML or reservations rather than hoping for spot.
Which should you pick?
A few honest heuristics:
You're training frontier-scale models and network performance is your primary constraint. AWS P6-B300 (6.4 Tbps EFA) and Azure ND H200 v5 (3.2 Tbps NDR IB) are the two front-runners. Between them, AWS wins raw bandwidth on the newest generation; Azure wins simplicity and predictability on the H100/H200 generation. Confirm with your own NCCL benchmarks before committing.
You need to train a trillion-parameter model on a single logical machine. AWS P6e-GB200/GB300 UltraServers (36–72 GPUs behind an NVLink switch) are the current answer.
You're cost-sensitive and doing a lot of research iteration on spot capacity. GCP on A3 High/Mega spot has the most reliable spot supply of the three; AWS is often cheapest on-demand but spot is scarce.
You already run Kubernetes everywhere and want GPU nodes to look like just another node pool. All three are strong. GKE has the most mature story around gang scheduling; EKS has the best EFA integration; AKS integrates most naturally with the rest of the Microsoft stack.
You are lifting a Slurm-based HPC workload from on-prem. All three have credible answers. CycleCloud feels the most on-prem-like out of the box; ParallelCluster gives you the most control; Cluster Director is the most opinionated. If you'd rather not run the Slurm cluster yourself, SageMaker HyperPod is the most managed option.
You need AMD MI300X capacity. Azure is the only one of the three with a first-class ROCm offering.
You're already deep in one hyperscaler's ecosystem. Data gravity almost always wins this decision. Egress costs alone can dwarf the per-GPU-hour differences between clouds.
One thing that is true on all three
You will save yourself weeks by running the vendor's reference NCCL benchmark on a fresh cluster before you run anything else. GCP, Azure, and AWS all publish expected numbers per SKU. If you're 20% under, you have a placement or driver problem; if you're 50% under, you have a fabric problem. Fixing it costs a day. Discovering it three weeks into a training run costs a lot more.
Closing thought
The three hyperscalers have converged more than they've diverged in the last two years. All three give you a real Slurm option and a real Kubernetes option, all three give you a managed Lustre filesystem, all three give you the current generation of NVIDIA silicon with a working RDMA-class fabric between the nodes. The differences that remain — Ethernet vs. InfiniBand vs. EFA, spot availability, sticker price, managed-training features like HyperPod, enterprise fit, AMD availability — are real, but for most teams they are decision-shaping rather than showstoppers. Pick the one your team can operate confidently, benchmark it before you scale, and put your energy into the model, not the plumbing.