What ML Labeling Actually Is - And How to Design a Pipeline for It

CK CK 3788 
Created at
Updated at  
327 0 0

From fundamentals to autonomous vehicle architecture

If there's one thing that affects ML model performance more than architecture choices, most practitioners will tell you it's data quality — specifically, the quality of your labels. Yet clear, structured resources on what labeling actually involves and how to design a labeling pipeline are surprisingly rare.

This post walks through the concept of ML labeling, how to design a labeling process, an extreme case study (autonomous vehicles), and finally what a real production labeling architecture looks like. It's aimed at people preparing for ML interviews and practitioners who need to design a labeling pipeline for the first time.


1. What is labeling in machine learning?

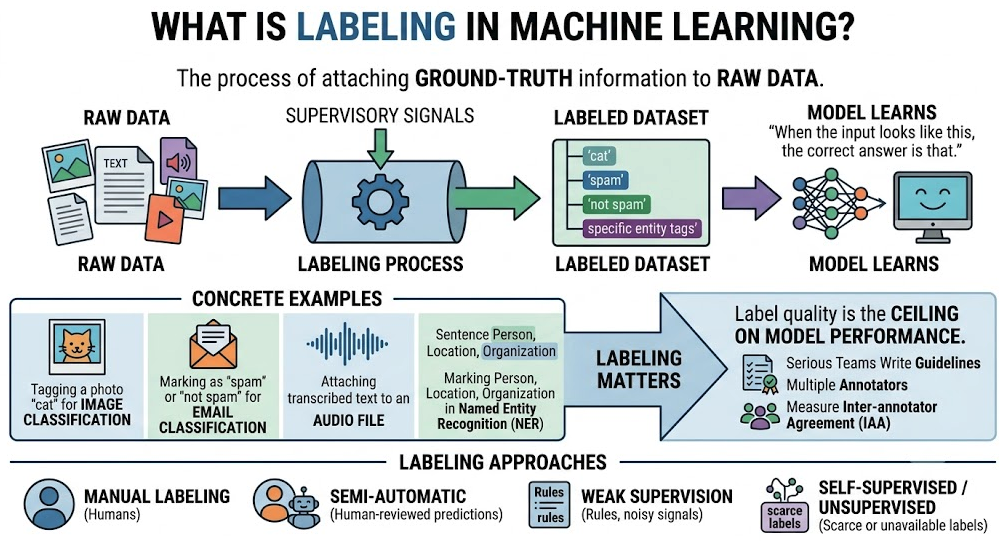
Labeling is the process of attaching ground-truth information to raw data so that a model can learn "when the input looks like this, the correct answer is that."

A few concrete examples:

  • Tagging a cat photo with "cat" for image classification
  • Marking emails as "spam" or "not spam"
  • Attaching the transcribed text to an audio file
  • Marking person names, locations, and organizations in a sentence for named entity recognition

Labeling matters because in supervised learning, label quality is the ceiling on model performance. If your labels are inaccurate or inconsistent, no algorithm will save you. This is why serious teams write labeling guidelines, have multiple annotators label the same data, and measure inter-annotator agreement (IAA).

Labeling approaches fall into a few broad categories: manual labeling by humans, semi-automatic labeling where humans review model predictions, weak supervision where labels are generated from rules or noisy signals, and self-supervised / unsupervised approaches for when labels are scarce or unavailable.


What ML Labeling Actually Is - And How to Design a Pipeline for It


2. Labeling is broader than categorization

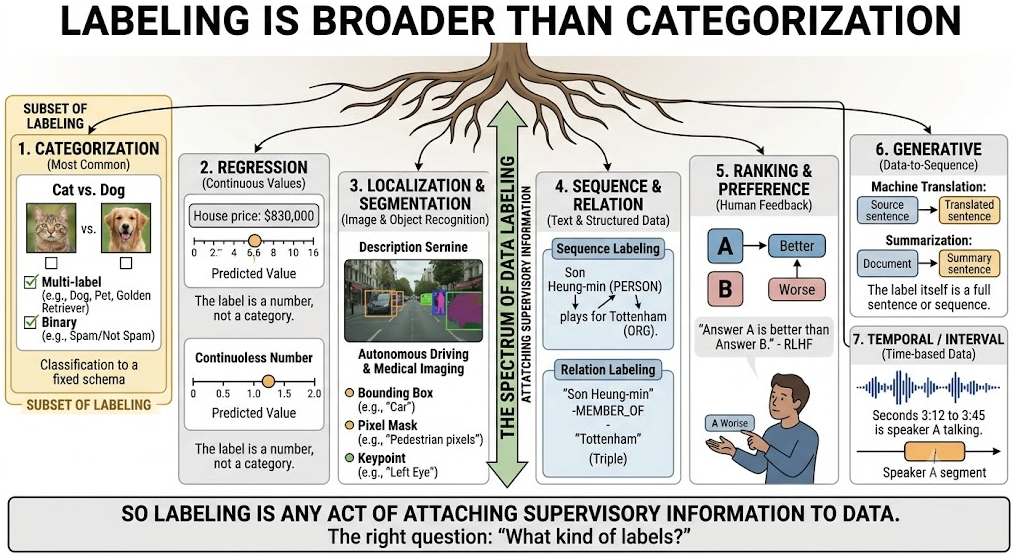
When people hear "labeling," most immediately think of categorization — cat vs. dog, spam vs. not spam. That's the most common case, but it's just one form of labeling. Categorization is a subset of labeling, not the whole thing.

Labels come in many forms:

  • Regression labels (continuous values) — attaching an actual house price ($830,000) to a real estate listing. The label is a number, not a category.
  • Localization and segmentation labels — in an image, not just "there's a cat in this image" but "these pixels form a cat," drawn as a bounding box or mask. Essential for autonomous driving and medical imaging.
  • Sequence labels — assigning part-of-speech tags or named entities at the token level. "Son Heung-min (PERSON) plays for Tottenham (ORG)."
  • Relation labels — marking the relationship between two entities. "Son Heung-min — MEMBER_OF — Tottenham" as a triple.
  • Ranking and preference labels — "Answer A is better than Answer B." This is exactly what RLHF (Reinforcement Learning from Human Feedback) uses to train LLMs.
  • Generative labels — the label itself is a full sentence: source-translation pairs in machine translation, document-summary pairs in summarization.
  • Temporal / interval labels — in audio or video, "seconds 3:12 to 3:45 is speaker A talking."

So labeling is any act of attaching supervisory information to data. When someone asks in an interview whether you have labeling experience, a good follow-up question is: "What kind of labels?" It often leads to a more precise conversation.


What ML Labeling Actually Is - And How to Design a Pipeline for It


3. How to design a labeling process

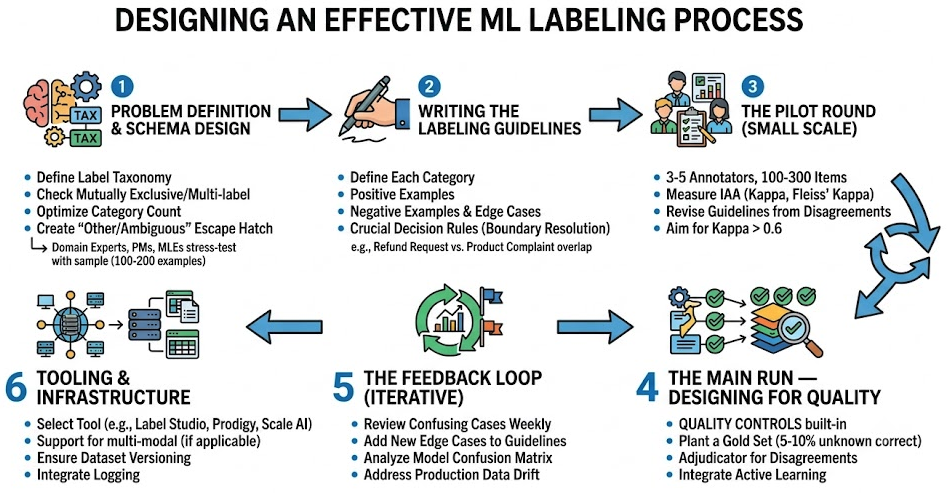
Labeling processes vary by task, but there's a well-tested pattern. Let's walk through it using a concrete example: classifying customer support emails into categories.


Step 1: Problem definition and schema design

The first thing to do is define the label taxonomy. A common mistake is to start labeling before the schema is stable — if the schema shifts, all your prior work is wasted.

Things to nail down at this stage:

  • Are the labels mutually exclusive, or is this a multi-label problem?
  • How many categories is the right number? Too many and annotator disagreement explodes; too few and the model isn't useful.
  • Should there be an "Other" or "Ambiguous" escape hatch?
  • How will you accommodate future category additions or changes?

Typically domain experts, PMs, and ML engineers sit down together, draft a schema, then sample 100–200 real examples and stress-test the schema against reality.


Step 2: Writing the labeling guidelines

Once the schema is set, write a guidelines document. For each category, specify:

  • Definition
  • Positive examples
  • Negative examples and edge cases
  • Decision rules for the boundary between adjacent categories

Decision rules matter most. If "Refund Request" and "Product Complaint" can overlap and you haven't documented which one wins, every annotator will decide differently.


Step 3: The pilot round

Before scaling up, always run a small pilot.

  • Have 3–5 annotators label the same 100–300 items
  • Measure inter-annotator agreement (Cohen's Kappa, Fleiss' Kappa)
  • Collect the disagreement cases, discuss them as a group, and revise the guidelines

If Kappa is below ~0.6, there's a structural problem with your schema or guidelines. Fix it now. Skip this step and you'll be re-labeling tens of thousands of items later.


Step 4: The main run — designing for quality

Build quality controls into the labeling process from the start.

  • Plant a gold set. Mix in 5–10% items with known-correct answers, unmarked, so you can continuously monitor each annotator's accuracy.
  • Redundant labeling. If budget allows, have 2–3 annotators independently label each item and use an adjudicator to resolve disagreements. On a tight budget, only apply redundant labeling to ambiguous cases.
  • Active learning. Train a model early and use it to surface the samples the model is most uncertain about. Prioritizing those is dramatically more efficient than random sampling.


Step 5: The feedback loop

Labeling isn't a one-shot event — it's iterative. Confusing cases annotators keep flagging get reviewed in a weekly meeting. Newly discovered edge cases get added to the guidelines. After training a model, examine the confusion matrix; if two classes keep getting mixed up, the schema itself may be the issue. When production data drifts, kick off another labeling round.


Step 6: Tooling and infrastructure

Tool choice is part of the process. Label Studio, Prodigy, Scale AI, Amazon SageMaker Ground Truth — pick based on team size, budget, and security requirements. Bake in logging and dataset versioning from day one.


The key tradeoff

On the quality-vs-cost tradeoff, I lean heavily toward investing more time in guidelines and pilots. An extra week upfront is far cheaper than re-labeling ten thousand items later. And rather than "label everything perfectly," the modern data-centric view is "label the data that will most improve the model first" — active learning and data-centric AI.


What ML Labeling Actually Is - And How to Design a Pipeline for It


4. What gets labeled in autonomous vehicles?

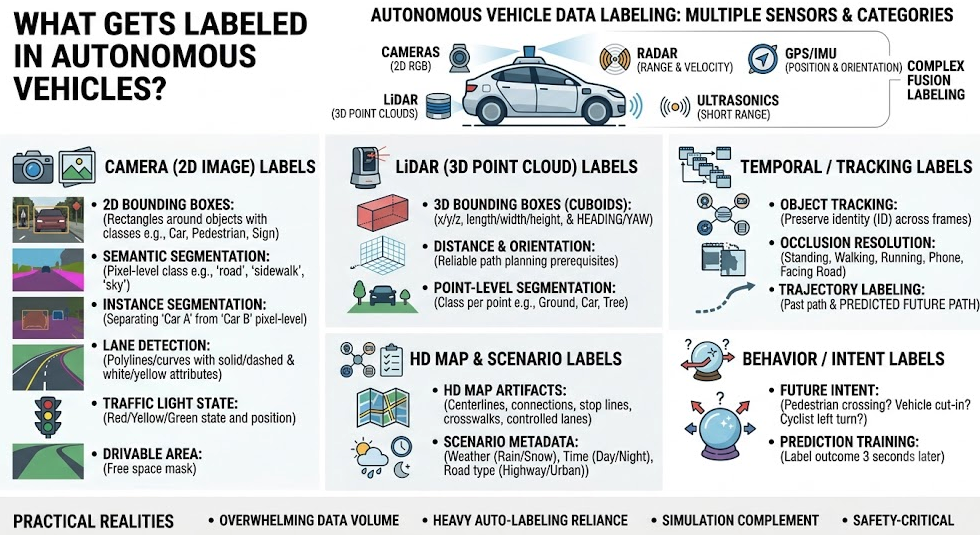
Autonomous vehicles sit at the most complex and expensive end of the ML labeling spectrum, because labels must be produced across multiple sensor modalities.

An AV typically has cameras (2D RGB), LiDAR (3D point clouds), radar (range and velocity), GPS/IMU (position and orientation), and ultrasonics (short range). Labeling happens both per-sensor and across sensors (fusion), which is what makes AV labeling uniquely hard.


Camera (2D image) labels

  • 2D bounding boxes: rectangles around cars, pedestrians, cyclists, traffic lights, and signs, each with a class
  • Semantic segmentation: pixel-level class assignment — "this pixel is road, this one is sidewalk, this one is sky"
  • Instance segmentation: separating car A from car B at the pixel level
  • Lane detection: drawing lane markings as polylines or curves, with attributes like solid/dashed and white/yellow
  • Traffic light state: not just the light's position but its current state (red/yellow/green, left-turn arrow) — without this, the model can't reason about right-of-way
  • Drivable area (free space): masking regions that are actually drivable


LiDAR (3D point cloud) labels

3D bounding boxes (cuboids) are the critical AV label. Unlike 2D boxes, they include x/y/z coordinates, length/width/height, and — crucially — heading (yaw).

This matters because accurate distance and orientation are prerequisites for path planning. Cameras alone can't produce reliable distance estimates, so LiDAR 3D boxes are essential.

Point-level segmentation assigns a class to every point in the cloud.


Temporal / tracking labels

One of the hardest parts of AV labeling.

  • Object tracking means preserving the identity of an object across frames. Car #47 in frame 1 must still be car #47 in frame 30. When a car is briefly occluded by another vehicle and then reappears, the same ID must be maintained.
  • Trajectory labeling goes further: not just where the object has been, but where it will go next, for training motion-prediction models.


Fusion and attribute labels

Fusion labeling links objects across sensors — the car seen in the camera image is the same as this cluster of LiDAR points. And within a class, attributes matter for behavior prediction. A pedestrian who is standing, walking, running, looking at a phone, or facing the road each implies a different next-step probability. Same for vehicles: parked, stopped, moving, turn signal on, brake lights on.


HD Map and scenario labels

Much of autonomous driving relies on HD maps, which are themselves labeled artifacts. Lane centerlines and their connection graph (which lane can transition to which), stop lines, crosswalks, the mapping between traffic lights and the lanes they control, speed limits — all human-produced labels.

Every driving clip also gets scenario metadata: weather (clear/rain/snow/fog), time of day (day/night/dusk), road type (highway/urban/residential/tunnel), and unusual events (construction, accidents, emergency vehicles). This tagging is what lets you diagnose "the model performs worse on rainy-night left turns" or mine for edge-case training data.


Behavior / intent labels

Increasingly important. "Is this pedestrian about to cross?" "Is this vehicle about to cut in?" "Is this cyclist about to turn left?" To train future-behavior prediction models, humans have to label what actually happened three seconds after the current frame.


Practical realities of AV labeling

  • Overwhelming data volume: a single vehicle generates terabytes per day. Labeling all of it is impossible, so data curation — deciding what to label — is itself a major problem.
  • Heavy reliance on auto-labeling: Waymo, Tesla, and Cruise use powerful offline models to produce first-pass labels, with humans only reviewing and correcting.
  • Simulation as a complement: rare and dangerous scenarios (near-accident situations) are generated in a simulator, where labels come for free.
  • Safety-critical: a labeling error can lead to a real accident. QA processes are far stricter than in most other domains — mandatory multi-annotator agreement, adjudication workflows, and formal labeling audits.


What ML Labeling Actually Is - And How to Design a Pipeline for It


5. Architecture: Simple vs Advanced

A labeling pipeline architecture changes dramatically with organizational maturity. Let's compare two ends of that spectrum.


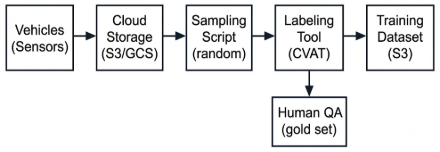
Simple version (MVP / early-stage startup)

Goal: produce a usable training dataset with minimum headcount

What ML Labeling Actually Is - And How to Design a Pipeline for It

Components:

  • Data collection: vehicles upload full logs to cloud storage
  • Sampling: a simple Python script does uniform random sampling (e.g., one frame every 10 seconds)
  • Labeling tool: an open-source option like CVAT or Label Studio, mostly 2D boxes
  • Labor: internal team or an outsourcing vendor
  • QA: 5–10% gold set to monitor annotator accuracy
  • Versioning: DVC or manifest JSON files

Characteristics and limits:

Human-centric (almost no automation), limited to 2D modalities, linear pipeline (no feedback loop), static dataset. Cost scales linearly with data volume, random sampling misses edge cases, and there's no path from model failures back into the labeling queue. Fine for prototyping and datasets up to hundreds of thousands of frames, and teams under about 10 people.


Advanced version (Waymo, Tesla, Cruise class)

Goal: keep labeling cost sub-linear while maximizing data quality

                    ┌────────────────────────────────────────────────┐
                    │                                                │
                    ▼                                                │
┌──────────┐   ┌─────────────┐   ┌─────────────────┐   ┌─────────────┴────┐
│ Vehicles │──▶│ Edge Filter │──▶│ Data Lake       │──▶│ Data Mining      │
│ (Fleet)  │   │ (on-vehicle)│   │ + Metadata      │   │ (curation engine)│
└──────────┘   └─────────────┘   │ Index (Elastic) │   └────────┬─────────┘
                                 └─────────────────┘            │
                                                                ▼
                                                      ┌─────────────────┐
                                                      │ Active Learning │
                                                      │ Sampler         │
                                                      └────────┬────────┘
                                                               │
                                                               ▼
                                                      ┌─────────────────┐
                                                      │ Auto-Labeling   │
                                                      │ Pipeline        │
                                                      │ (offline model  │
                                                      │  + tracking)    │
                                                      └────────┬────────┘
                                                               │
                                                    ┌──────────┼──────────┐
                                                    ▼          ▼          ▼
                                            ┌───────────┐ ┌────────┐ ┌──────────┐
                                            │ Tier-1    │ │ Tier-2 │ │ Expert   │
                                            │ Labelers  │ │ Review │ │ Adjudi-  │
                                            │ (verify)  │ │ (QA)   │ │ cator    │
                                            └─────┬─────┘ └───┬────┘ └────┬─────┘
                                                  └───────────┼───────────┘
                                                              ▼
                                                    ┌─────────────────┐
                                                    │ Versioned       │
                                                    │ Dataset Store   │
                                                    └────────┬────────┘
                                                             │
                                          ┌──────────────────┼──────────────────┐
                                          ▼                  ▼                  ▼
                                   ┌────────────┐    ┌────────────┐     ┌────────────┐
                                   │ Simulation │    │ Model      │     │ Evaluation │
                                   │ Pipeline   │    │ Training   │◀────│ + Failure  │
                                   └─────┬──────┘    └─────┬──────┘     │ Analysis   │
                                         │                 │            └──────┬─────┘
                                         └─────────────────┼───────────────────┘
                                                           │
                                                           └───▶ back to Data Mining
                                                                (closed loop)

Key components:

1. Edge filtering. On-vehicle models only upload "interesting" moments — hard braking, moments where the onboard model was uncertain, rare object sightings. Tesla's "Shadow Mode" is essentially this. Dramatically cuts upload bandwidth and storage cost.

2. Data lake + metadata index. Every frame is indexed by weather, time of day, road type, events, and geographic location, using something like Elasticsearch or Snowflake. This makes queries like "give me all rainy-night left-turn scenarios" possible.

3. Data mining / curation engine. Failure mining (auto-collecting moments the production model got wrong), similarity search (embedding-based lookup of similar scenarios), rarity scoring (up-weighting samples that are underrepresented in the current dataset).

4. Active learning sampler. Prioritizes samples the current model is uncertain about, using entropy, MC dropout, or ensemble disagreement. Alone, this can improve labeling efficiency 5–10×.

5. Auto-labeling pipeline (the biggest differentiator). A large offline model produces first-pass labels. Because it has no real-time constraint, it can be much heavier and more accurate than the production model. Temporal post-processing smooths trajectories using past and future frames — something the online model can never do. Multi-sensor fusion generates 3D boxes automatically. Humans only correct. This is Tesla's Auto-labeling and Waymo's Off-board Perception.

6. Tiered labeling workforce. Tier 1 does volume work (box adjustments, simple verification), Tier 2 reviews ambiguous cases, and expert adjudicators make final calls on contested items.

7. Multi-tier QA with consensus. Gold set plus N-way independent labeling plus automatic escalation when human labels disagree strongly with model predictions.

8. Versioned dataset store. Tools like DVC, lakeFS, or Pachyderm treat the dataset like code. "This model was trained on dataset v3.2.1" is reproducible. Essential for regulatory audit and safety compliance.

9. Simulation pipeline. Simulator-generated data comes with free labels (the simulator already knows the ground truth). Rare and dangerous scenarios can be produced at will. Sim-to-real domain adaptation runs in parallel.

10. Closed feedback loop. Train → evaluate → analyze failures → mine similar data → re-label → retrain. Automating this loop is the true power of the advanced version. The dataset becomes a living asset, not a static snapshot.


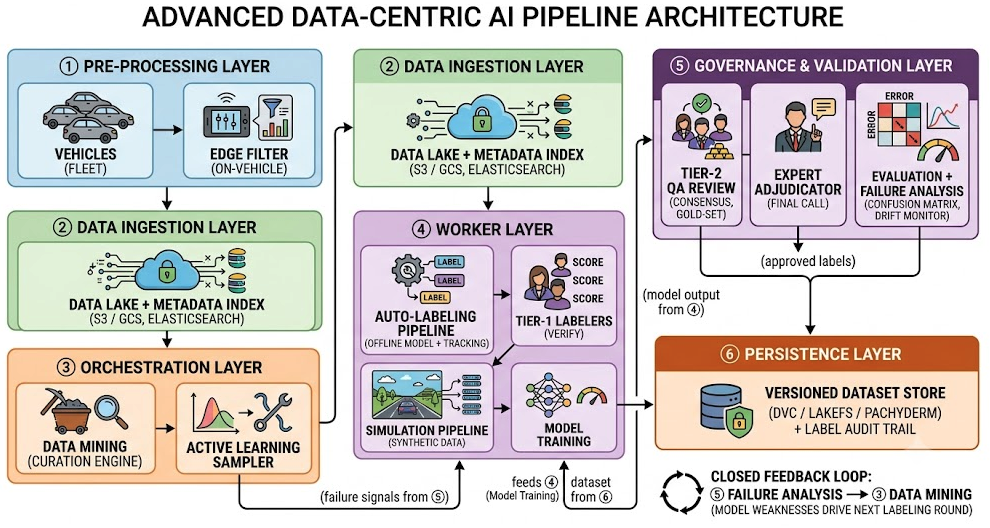
AI/ML Ops 6 Layer Version

What ML Labeling Actually Is - And How to Design a Pipeline for It

Here is how the distinction works within that architecture:

  • Auto-Labeling Pipeline (AI/Offline Model): This is the automated system that processes data first using heavy offline models, tracking algorithms, and multi-sensor fusion to generate initial predictions or pseudo-labels.
  • Tier-1 Labelers (Humans): This is the front-line human workforce. Their role is to review, verify, and adjust the pre-generated outputs (such as tweaking 3D bounding box boundaries or correcting class tags) rather than labeling everything from scratch.
  • Tier-2 Reviewers & Expert Adjudicators (Humans): Senior human annotators and domain experts who resolve complex, ambiguous, or disputed edge cases escalated by Tier-1 workers.


Simple vs Advanced at a glance

DimensionSimpleAdvanced
Data selectionRandom samplingActive learning + data mining
Label generation100% humanAuto-labeling → human review
ModalitiesMostly 2D2D + 3D + temporal + fusion
QAGold setGold + consensus + tiered review
Pipeline shapeLinear (one-way)Closed loop (model → data)
DatasetStatic snapshotVersioned, living asset
Cost scalingLinear with dataSub-linear
TeamLabelers + small MLLabelers + tooling + ML + infra + simulation


6. If you're moving from Simple to Advanced, start here

If I had to pick one thing to invest in first when graduating from the Simple architecture, it would be auto-labeling and active learning, in that order. These are the two levers that bend the cost curve. Everything else (fusion, simulation, HD maps) is refinement — but without auto-labeling, growing your dataset 100× also grows your cost 100×, and the operation becomes untenable. A big part of Tesla's competitive advantage in autonomy came from investing in an auto-labeling pipeline early.

One more practical piece of advice: even in the Simple version, put metadata indexing and dataset versioning in place from day one. Retrofitting these later is painful; adding them upfront costs almost nothing.


Closing thoughts

Model architectures are increasingly commoditized. Competitive differentiation now comes from data — and data quality ultimately comes down to the quality of your labeling pipeline.

If you treat labeling as "attaching answers to examples," your organization will hit a wall. If you treat labeling as a living pipeline where data flows, models improve, and labels evolve, models get better and datasets become durable assets. This principle holds even in domains far simpler than autonomous driving.

Before you agonize over the next model architecture, try sketching the labeling pipeline first. The result usually surprises you.

Tags Active Learning Auto Labeling Autonomous Vehicle Autonomous Vehicle Labeling Data Centric AI Data Labeling Pipeline Data Quality Ground Truth Data Labeling Guidelines ML Pipeline Architecture Machine Learning Labeling Facebook X
Comments 0
Similar posts
  1. End-to-End Autonomous Vehicle ML Training Pipeline
    306
  2. Designing a Data Curation System Around a Vector Database
    215
  3. The Continuous Learning Machine: Designing a Loop That Actually Turns
    217
  4. Advertiser Universal Commerce Protocol (UCP) Readiness Checklist
    439
  5. Why Reranking is Crucial for RAG and Agentic AI Systems?
    261
  1. Vector Search in Relational Databases (RDBs): Trends & Usage Environments
    280
  2. Designing a Skill Registry Architecture: Minimize Token Usage and Maximize AI Performance
    224
  3. TPU & GPU Cluster Management Tools
    232
  4. The Concept of Scaffolding in AI Agents
    221
  5. Beyond Static Pipelines: Architecting LLM Multi-Agent Systems for Autonomous Workflow Orchestration
    575
  6. AI-DLC vs. AI-SDLC: Model-Centric vs. System-Centric AI Development
    252
  7. Fine-Tuning Open-Weight LLMs: Training, Licensing, and Deploying Custom Models with Ollama
    326
  8. Machine Learning: Training vs. Ranking
    213
  9. The Continuous Learning Machine: Designing a Loop That Actually Turns
    217
  10. Designing a Data Curation System Around a Vector Database
    215
  11. Designing MLOps Architectures to Handle Seasonal Data Drift in EV Fleet Models
    185
  12. From 15 to 40+ FPS: Accelerating PyTorch Object Detection on Automotive ECUs
    207
  13. Understanding Data Lineage
    252
  14. GPU & LLM Cluster Infrastructure & Task Scheduling Architecture
    230
  15. When Do You Need Real-Time Model Registry Versioning Powered by Autonomous Agents?
    220
  16. Bridging the Gap: How Machine Learning Integrates with Infrastructure
    263
  17. Designing an Enterprise ML Experiment Tracking and Reproducibility Platform: System Requirements and Architecture
    302
  18. End-to-End AI/Machine Learning Architecture: AI/ML 6 Layers
    231
  19. Architecting an LLM-Powered Multi-Agent Orchestration System: Design and Requirements
    238
  20. End-to-End Autonomous Vehicle ML Training Pipeline
    306
  21. Building GPU Clusters on GCP, Azure, and AWS: A Practical Guide and Head-to-Head Comparison
    334
  22. Embeddings on the Lakehouse: What Snowflake and Databricks Actually Do (and Don't)
    280
  23. Vector Database Integration on Fully Managed Multi-Agent Environment
    293
  24. AWS Multi-Agent Collaboration Approach: Fully Managed vs. Code-based Implementation
    269
  25. Semantic Kernel: Microsoft's GenAI Orchestration SDK
    389
  26. LLM Application Development with LangGraph: Features and Architectures for Stateful Multi-Actor LLM Applications
    344
  27. Microsoft AutoGen: Next-Generation Multi-Agent Framework
    299
  28. Beyond SDLC: Why the Entertainment Sector Needs an AI Development Life Cycle Now
    282
  29. Why AI-DLC is the New Paradigm for Development?
    325
  30. Autonomous Vehicle Machine Learning (AV ML): An Architectural Review
    395
Recently updated
  1. Why 100% SEO Guarantees Better User Engagement and How to Achieve It in Your Service
    27
  2. Why SPF and DKIM Are Essential for Linux Email Servers?
    24
  3. How do I create animated background for Google Meet?
    19,709
  4. MaxMind GeoLite2 vs. DB-IP Lite vs. ip-api.com: Choosing the Right Free IP Geolocation Solution
    217
  5. Meet Valkey: Why Redis Changed Its License, Why Valkey is Better, and How to Use It as a Drop-in Replacement
    85
  6. How Rogue Web Scrapers Are Stealing My Content and Destroying My Server
    153
  7. Array of arguments passed to script in PHP
    85
  8. Invalid Auction Storms in Ad Tech
    93
  9. Building MRC-Compliant Instrumentation in Ad Tech: Implementation Steps and Key Challenges
    197
  10. The Two Clocks of Ad Server Architecture
    63
  11. Frequency Cap Architecture Overview
    509
  12. Collecting Proof-of-Play from 100,000 Screens
    141
  13. Vector Search in Relational Databases (RDBs): Trends & Usage Environments
    280
  14. What is RedisVL?
    105
  15. Designing a Skill Registry Architecture: Minimize Token Usage and Maximize AI Performance
    224
  16. TPU & GPU Cluster Management Tools
    232
  17. The Concept of Scaffolding in AI Agents
    221
  18. Beyond Static Pipelines: Architecting LLM Multi-Agent Systems for Autonomous Workflow Orchestration
    575
  19. AI-DLC vs. AI-SDLC: Model-Centric vs. System-Centric AI Development
    252
  20. Fine-Tuning Open-Weight LLMs: Training, Licensing, and Deploying Custom Models with Ollama
    326
  21. Inside the Next-Generation Streaming Architecture: Ultra-Low Latency, SGAI, and AI Codecs
    197
  22. Machine Learning: Training vs. Ranking
    213
  23. The Continuous Learning Machine: Designing a Loop That Actually Turns
    217
  24. The Next-Gen Low-Latency Standards: LL-HLS & MoQ
    189
  25. Designing a Data Curation System Around a Vector Database
    215
  26. Extracting Context from Live Video: The Architecture Got Simpler When We Stopped Building Features
    229
  27. The New Ad Stack Behind Live Sports Streaming: Inside SGAI, EABN, and the Standards Race to Fix Live Monetization
    649
  28. Designing MLOps Architectures to Handle Seasonal Data Drift in EV Fleet Models
    185
  29. From 15 to 40+ FPS: Accelerating PyTorch Object Detection on Automotive ECUs
    207
  30. Understanding Data Lineage
    252