Fine-Tuning Open-Weight LLMs: Training, Licensing, and Deploying Custom Models with Ollama | ||||||||||||||||||||||||||||||
| ||||||||||||||||||||||||||||||
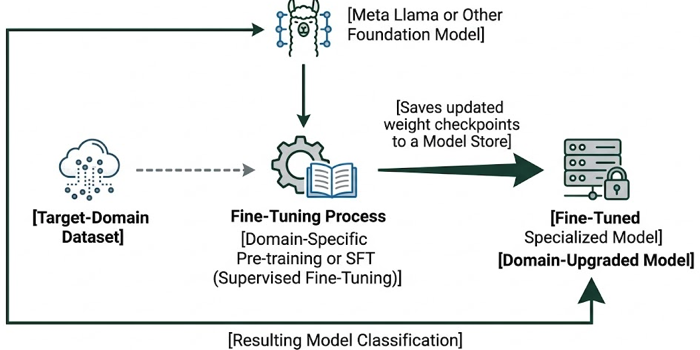
| When you take a foundation model such as Meta Llama, train it further using target-domain datasets (Domain-Specific Pre-training or Supervised Fine-Tuning/SFT), and save the updated weight checkpoints to a Model Store, the resulting model is technically classified as a Fine-Tuned Specialized Model or a Domain-Upgraded Model. It surpasses the base model in specific operational context, instruction-following capabilities, or internal knowledge, making it a customized enterprise asset.
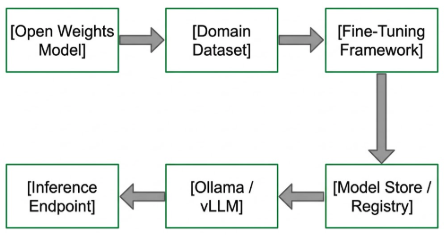
Applying the Workflow to Open-Weight Models (e.g., Kimi)This workflow applies universally to open-weight LLMs, including models like Moonshot AI’s Kimi series (e.g., Kimi k1.5) or other open-weight frameworks.
Note: Always verify the source model's underlying license terms prior to commercial deployment.
|

| Model Family | License | Developer / Creator | Country | Release Date | Key Characteristics |
|---|---|---|---|---|---|
| Qwen 2.5 (0.5B to 72B) | Apache 2.0 (3B/72B are Apache 2.0) | Alibaba Cloud (Qwen Team) | China | September 2024 | Outperforms Llama 3.1 in coding, mathematics, and multilingual tasks. Fully supports Hugging Face and vLLM training/serving stacks. |
| DeepSeek-R1 / DeepSeek-V3 | MIT License (Fully Open) | DeepSeek (High-Flyer) | China | Dec 2024 / Jan 2025 | DeepSeek-R1 achieves reasoning capabilities comparable to OpenAI o1. MIT license permits unrestricted commercial use, modification, and training. |
| Mistral 7B / Mixtral 8x7B | Apache 2.0 | Mistral AI | France | Sept 2023 / Dec 2023 | Pioneered Sparse Mixture-of-Experts (MoE). High throughput, low latency, and highly customizable using standard PyTorch frameworks. |
| Phi-3.5 (Mini / MoE) | MIT License | Microsoft | USA | August 2024 | Highly optimized for edge devices and lightweight footprint. Outstanding reasoning per parameter ratio. |
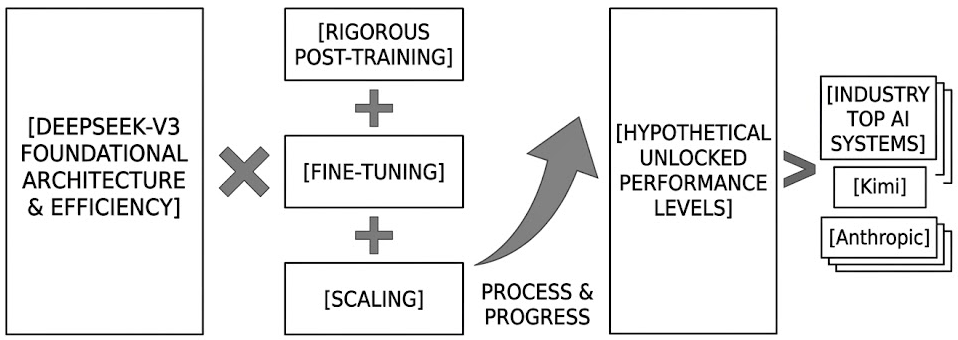
If we take DeepSeek-V3 and train it intensively, wouldn't it be possible for it to surpass even Kimi or Anthropic?
Given its strong foundational architecture and efficiency, rigorous post-training, fine-tuning, and scaling could unlock performance levels that challenge and even outperform the current top AI systems in the industry.
Enterprise System Architecture for Open-Source LLMs
Below is an enterprise-grade, end-to-end system architecture blueprint designed for self-hosted open-source models (such as Qwen 2.5 or DeepSeek-R1).
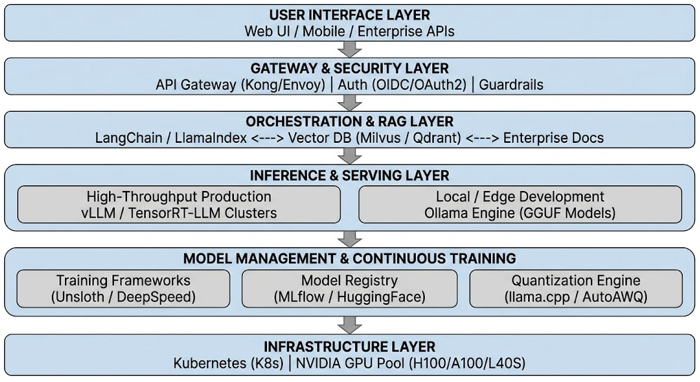
Component Breakdown
- Infrastructure & GPU Layer: Managed Kubernetes cluster (EKS/GKE/Bare-Metal) running NVIDIA GPU nodes, isolated on private VPC subnetworks.
- Continuous Training & Pipeline Layer:
- Data Pipeline: Preprocessing and anonymizing proprietary data.
- Training Engine: Executing LoRA/SFT pipelines using Unsloth or Axolotl with DeepSpeed ZeRO-3 optimizations.
- Model Registry: Storing baseline and fine-tuned checkpoints in MLflow.
- Quantization & Build Pipeline:
- Automated conversion pipeline generating high-throughput weights (AWQ for vLLM) and edge/local runtimes (GGUF via
llama.cpp).
- Automated conversion pipeline generating high-throughput weights (AWQ for vLLM) and edge/local runtimes (GGUF via
- Inference & Serving Layer:
- Production Serving: vLLM or TensorRT-LLM running on multi-GPU nodes with continuous batching and PagedAttention enabled for maximum throughput.
- Internal Dev Serving: Ollama endpoints servicing internal developer sandboxes using quantized GGUF models.
- Orchestration, RAG & Security Layer:
- RAG Pipeline: Context augmentation using vector databases like Qdrant or Milvus.
- Guardrails: Input/output sanitization and PII masking via NeMo Guardrails or Llama Guard.
- API Gateway: Load balancing, rate limiting, and standard authentication (OpenID Connect).
End-to-End Training Workflow Pipeline
A robust MLOps pipeline for fine-tuning LLMs consists of five distinct, sequential phases:
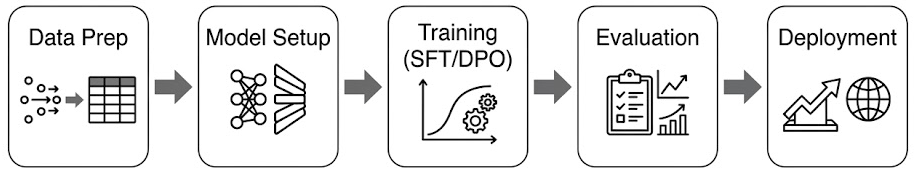
1. Data Preparation
- Collection: Gathering domain-specific text, instruction-response pairs, or conversation logs.
- Cleaning: Removing PII (Personally Identifiable Information), duplicates, low-quality text, and formatting errors.
- Formatting: Structuring into standardized JSONL formats (e.g., Alpaca format or OpenAI messages format:
{"messages": [{"role": "user", ...}, {"role": "assistant", ...}]}).
2. Model & Environment Setup
- Base Weight Loading: Fetching the base MIT model from repositories like Hugging Face.
- Quantization Setup: Applying 4-bit or 8-bit quantization (NF4/FP4 via
bitsandbytes) if using QLoRA. - Tokenizer Configuration: Ensuring correct padding tokens, eos tokens, and chat templates.
3. Training Execution
- Supervised Fine-Tuning (SFT): Training the model on instruction-output pairs to learn style, domain knowledge, or tone.
- Alignment Fine-Tuning (Optional): Using Direct Preference Optimization (DPO) or Reinforcement Learning from Human Feedback (RLHF) to align model output preferences.
- Distributed Training: Utilizing tools like DeepSpeed, PyTorch FSDP, or Hugging Face
Acceleratefor multi-GPU scaling.
4. Evaluation & Validation
- Automated Benchmarks: Running evaluation suites (e.g., LM-Evaluation-Harness, MMLU, GSM8K).
- LLM-as-a-Judge: Using a stronger model (e.g., GPT-4) to score fine-tuned responses against a test set.
- Human Evaluation: Domain experts reviewing edge cases.
5. Deployment
- Export/Merge: Merging LoRA adapters back into base weights if lower latency is required, or serving adapters dynamically.
- Inference Engines: Loading the model into high-performance engines like vLLM, TGI (Text Generation Inference), or Ollama.
JSONL-based Dataset Example for LLM Training?
Refer to https://strcpy.com/engineering/982/A-Complete-Guide-to-LLM-Dataset-Formats-From-PreTr/ for more information
Versioning and Artifact Management Strategy
To ensure reproducibility and enable reuse of trained models, you must version three distinct components independently: Data, Code, and Model Weights.
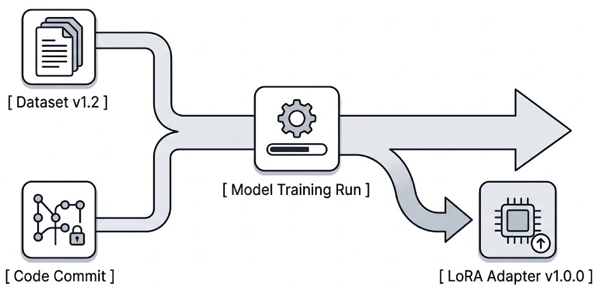
1. Model & Adapter Versioning
- Decoupled Weights: Never re-save the massive base model if you used LoRA. Save only the lightweight LoRA adapters (~10MB to ~500MB).
- Semantic Versioning (SemVer): Tag adapters logically (e.g.,
adapter-v1.0.0-domain-finance). - Model Registry: Use platforms like Hugging Face Hub (private/public), MLflow Model Registry, or Weights & Biases (W&B) Artifacts to store adapter weights along with metadata (hyperparameters, base model hash, metrics).
2. Dataset Versioning
- Tools: Use DVC (Data Version Control) or W&B Artifacts paired with Git.
- Lineage Tracking: Map exact dataset versions (e.g.,
data_v2023_10_12.jsonl) to specific training runs.
3. Execution Environment Versioning
- Containerization: Freeze CUDA drivers, PyTorch, Transformers, and PEFT library versions inside a Docker Image.
- Config Files: Store all hyperparameters (learning rate, rank, alpha, batch size) in version-controlled YAML files.
Continuous Learning via "Loop Engineering" (Data Flywheel)
Runtime user logs and feedback can be directly converted into training pipelines. This pattern is commonly known as the Data Flywheel or Continuous Fine-Tuning Loop.
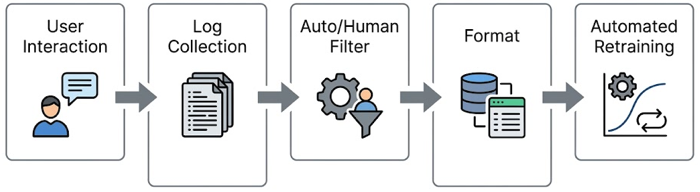
Architecture of a Loop Engineering Pipeline
Step 1: Interaction & Feedback Capture
- Capture user input prompts and generated responses.
- Collect explicit feedback (thumbs up/down, edits, ratings) and implicit feedback (copying text, session duration, regeneration requests).
Step 2: Curation and Quality Filtering (Automated Gatekeeper)
Raw logs cannot be directly fed to a model due to noise, hallucination risk, and security risks.
- Rule-based Filters: Filter out short responses, error codes, and PII.
- LLM-as-a-Judge Filter: Use a stronger LLM to grade user interactions. Only retain prompt-response pairs that score above a specific quality threshold (e.g., 8/10).
- Preference Dataset Generation: If a user rejects an answer and generates a new one (or edits it), format this directly into a DPO Dataset Pair (
{prompt, chosen_response, rejected_response}).
Step 3: Dataset Ingestion & Formatting
- Append validated, high-quality entries into an staging dataset store (e.g., BigQuery, S3).
- Automate conversion into the training schema (e.g., standard conversation JSONL format).
Step 4: Trigger-Based Automated Retraining (Continuous MLOps)
- Threshold Trigger: Automatically launch an orchestration pipeline (via Airflow, Prefect, or GitHub Actions) when
Nnew high-quality samples (e.g., 5,000 samples) accumulate. - Continuous SFT/DPO: Run a new fine-tuning job taking the previous LoRA adapter checkpoint as the base, or retrain from the original base model using the expanded cumulative dataset.
- Regression Guardrails: Run automated evaluations against a baseline evaluation set. If the newly trained model outperforms the production model without regressing on core tasks, automatically deploy it to staging/production.
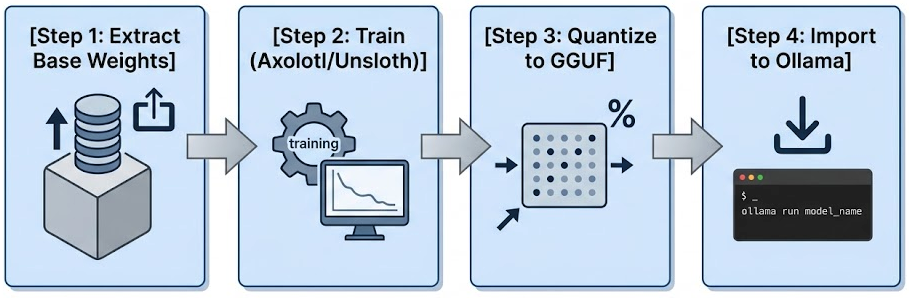
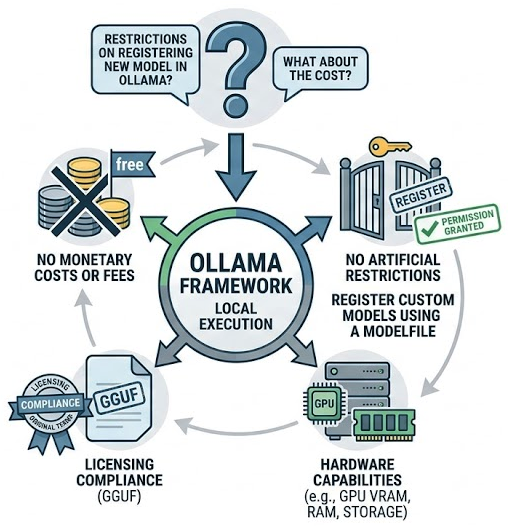
The ultimate goal of the Automated Retraining process is to generate newly trained model weights (or LoRA adapters) with improved performance, convert them into the GGUF format readable by Ollama, and register them.
The basic mechanism and operational workflow are as follows:
- Ollama Model Update: Once the automated retraining pipeline (e.g., Airflow, GitHub Actions, etc.) completes, it executes the command
ollama create custom-model -f Modelfilebased on the generated latest GGUF file and Modelfile to overwrite the existing model name with the latest weights or register it with a new version tag (e.g.,custom-model:v2).- Automatic Reflection upon Application Restart: If the existing model name (e.g.,
custom-model:latest) is updated directly, the integrated application or service will naturally load and use the newly updated model the next time it restarts and calls the Ollama API.Therefore, by connecting the entire process—from data collection to evaluation, GGUF conversion, and Ollama model registration—into a single pipeline, you can fully achieve a Data Flywheel (continuous learning loop) structure that automatically and continuously improves.