Automating machine learning pipelines while managing GPU and TPU clusters requires efficient scheduling, which is critically important because high user demand constantly competes against strictly limited hardware resources. Properly orchestrating these workflows maximizes resource utilization, minimizes idle time, and prevents bottlenecks, ensuring that numerous users can effectively share the constrained compute infrastructure to train and deploy their models without unnecessary delays.
1. TPU & GPU Cluster Management Tools Overview
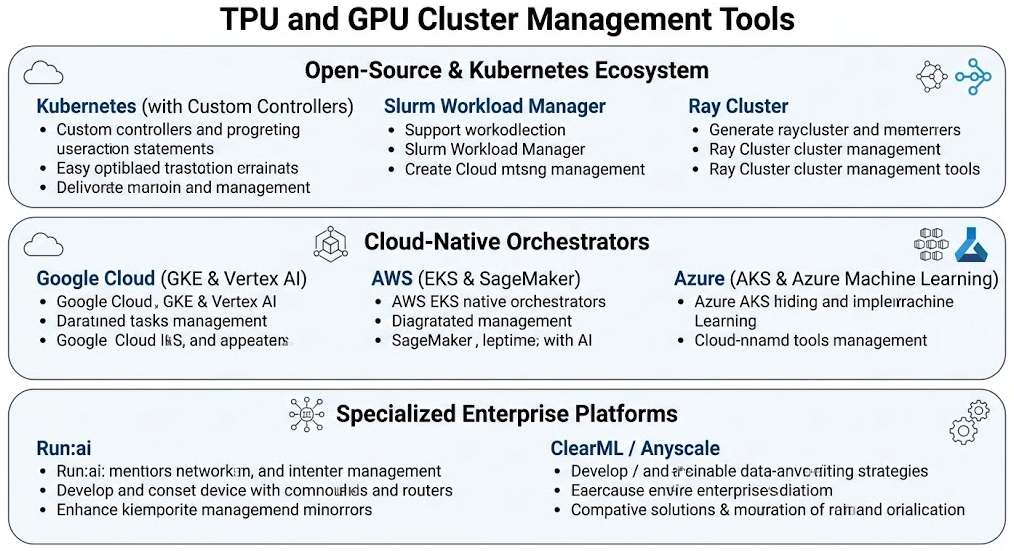
Open-Source & Kubernetes Ecosystem
Kubernetes (with Custom Controllers): The industry standard for container orchestration. Extended with batch schedulers like Volcano or Kueue for advanced AI/ML workloads.
Slurm Workload Manager: The traditional High-Performance Computing (HPC) standard. Highly optimized for bare-metal GPU clusters and complex inter-node communication topologies.
Ray Cluster: Designed specifically for distributed Python and AI applications, handling task execution, hyperparameter tuning, and data processing seamlessly across heterogeneous nodes.
Cloud-Native Orchestrators
Google Cloud (GKE & Vertex AI): The primary solution for TPUs (v4, v5e, v5p) and GPUs. GKE provides native support for TPU Slices and TPU Pod topologies.
AWS (EKS & SageMaker): Tailored for NVIDIA GPUs and AWS proprietary chips (Trainium, Inferentia), utilizing EKS with specialized CNI plugins and Node Termination Handlers.
Azure (AKS & Azure Machine Learning): Offers automated orchestration for NVIDIA A100/H100 clusters integrated with Azure Blob and ONNX Runtime.
Specialized Enterprise Platforms
Run:ai: Sits on top of Kubernetes to provide dynamic GPU fractioning, GPU virtualization, auto-scaling, and fair-share scheduling for multi-tenant environments.
ClearML / Anyscale: Managed orchestration layer providing workload scheduling, dataset tracking, and execution across hybrid environments (On-prem + Cloud).
2. Key Features & Customization Capabilities
Key Features
Advanced Scheduling Patterns:
Gang Scheduling: Ensures all N nodes/workers required for distributed training are allocated simultaneously before starting execution (prevents deadlock).
Bin-Packing vs. Spread: Optimizes node density to reduce fragmentation or spreads workloads to prevent overheating and maximize memory bandwidth.
Hardware Topology Awareness: Schedulers recognize NVLink, NVSwitch, InfiniBand, and TPU mesh topologies to place interconnected tasks on physically adjacent accelerators.
GPU Sharing & Partitioning:
NVIDIA MIG (Multi-Instance GPU): Hardware-level splitting of A100/H100 GPUs into isolated instances.
Time-Slicing & Fractional GPU: Software-level context switching for lighter inference or development workloads.
Preemption & Priority Queuing: Suspends low-priority jobs (e.g., dev/test) when high-priority distributed training jobs enter the queue.
Customization Possibilities
Custom Kubernetes CRDs & Operators: Build domain-specific custom resource definitions (e.g., custom PyTorchJob or TPUJob operators) to define job lifecycles.
Scheduler Plugins: Extend the Kubernetes Scheduler framework via Go plugins or Slurm Prolog/Epilogue scripts (C/Bash) to implement custom node ranking logic based on real-time temperature, memory degradation, or cost.
Dynamic Autoscaling Policies: Implement custom metrics (e.g., Queue Depth, GPU Duty Cycle) using KEDA (Kubernetes Event-driven Autoscaling) to trigger cluster expansion/contraction.
3. API-Level Capabilities
Modern cluster managers expose REST, gRPC, and Python SDK interfaces. Key operations performable via API include:
Domain
API Capability
Example API Action
Cluster Management
Provisioning/Deprovisioning
Scale node pool to N GPU nodes; Request a TPU v5e-256 slice via Google Cloud API.
Workload Lifecycle
Job Submission & Control
Submit a distributed job spec; Pause, resume, or terminate specific worker ranks.
Resource Allocation
Dynamic Quota Management
Reassign GPU quota limits dynamically across research teams without restarting nodes.
Send webhook notifications 30 seconds before a spot instance or preemptible TPU node is reclaimed.
4. System Architecture Examples
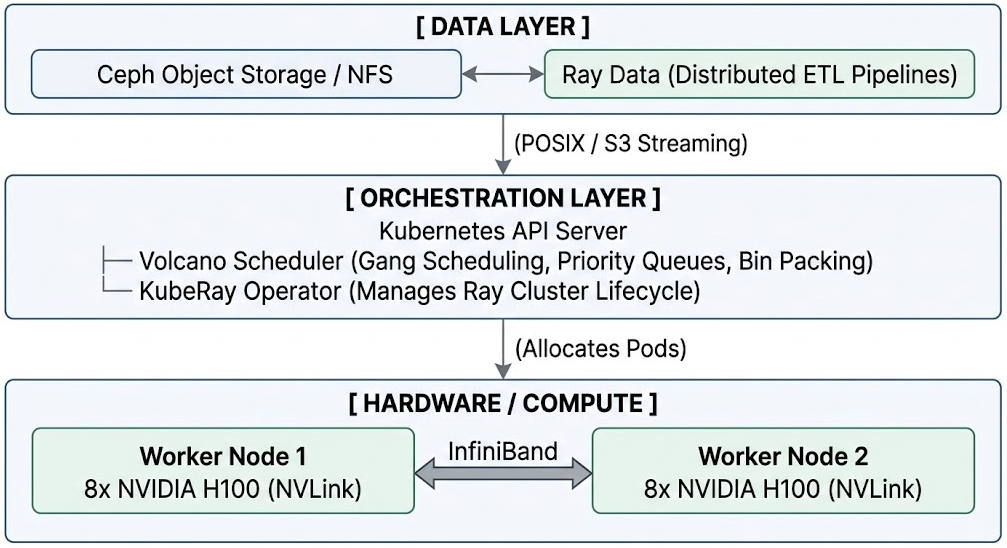
Architecture 1: Open-Source Kubernetes Native (Volcano + Ray + Ceph)
Target Environment: On-Premise or Agnostic Cloud GPU Cluster
Data Flow: Data resides in Ceph object storage. Ray Data workers load, preprocess, and cache training batches into shared RAM (/dev/shm).
Scheduling Flow: The ML engineer submits a job manifest via the Volcano API. Volcano enforces gang scheduling: it verifies that all 16 requested H100 GPUs across both nodes are available before spinning up the pods.
Execution: Training runs using PyTorch DDP over InfiniBand interconnects.
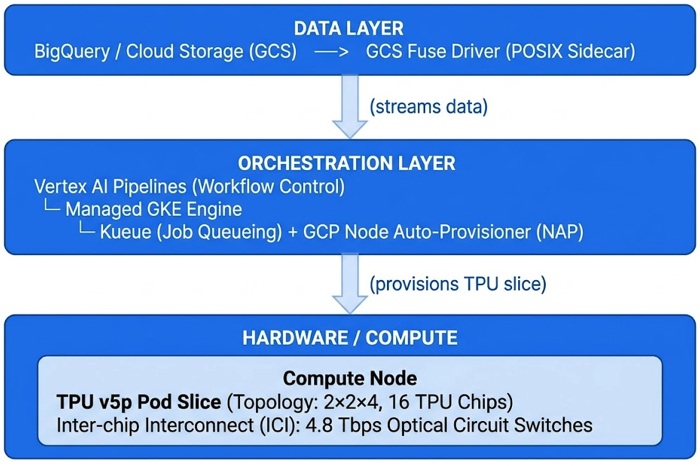
Architecture 2: Cloud-Native Google Cloud (GKE + Vertex AI + TPU Pods)
Data Flow: Dataset stored in GCS is directly mounted to container pods using the GCS Fuse CSI driver, streaming files on-demand.
Scheduling Flow: Vertex AI triggers a GKE pipeline. Kueue holds the job until the GCP Node Auto-Provisioner dynamically builds a GKE node pool containing the exact requested TPU Pod Topology (e.g., 2x2x4 mesh).
Execution: JAX/Flax distributed code executes across the TPU topology via low-latency ICI (Inter-Chip Interconnect) networks.
Atomic Checkpointing: Always write checkpoints to a .tmp file and perform an atomic rename (os.replace) to prevent corrupt checkpoint files if the pod is killed mid-write.
Non-blocking Data Transfer: Use non_blocking=True when pushing tensors to host/device memory (.to(device)) to allow CUDA stream asynchronous execution while overlapping CPU data prefetching.
Graceful Exit Code 0: Upon catching SIGTERM, execute cleanup logic, save state, and terminate with code 0. This informs cluster managers that the job exited safely and can be cleanly requeued.