Vector Search in Relational Databases (RDBs): Trends & Usage Environments
CK 3788 Created at
30400
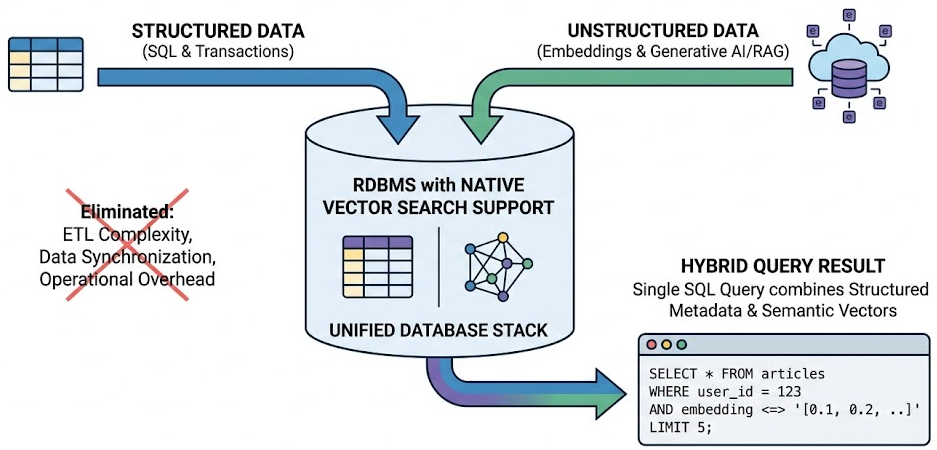
The integration of Approximate Nearest Neighbor (ANN) vector search into traditional Relational Database Management Systems (RDBMS) represents a major shift in database technology. Driven by the explosion of Generative AI and Retrieval-Augmented Generation (RAG), mainstream databases are adopting vector search capabilities to allow developers to query unstructured data (embeddings) alongside structured transactional data.
1. Key Industry Trends
Convergence of Relational and Vector Data: Instead of running a dedicated Vector Database (e.g., Pinecone, Milvus, Qdrant) alongside an RDB, organizations prefer a single database stack to eliminate ETL pipeline complexity, data synchronization delays, and operational overhead.
ACID Compliance for Vectors: Combining transactional integrity (ACID) with vector embeddings ensures that data modifications and vector updates happen atomically.
HNSW Indexing Standard: Hierarchical Navigable Small World (HNSW) has become the gold standard algorithm for fast, high-recall vector search. RDBs are rapidly integrating native HNSW support.
RAG System Simplification: Querying traditional relational metadata (e.g., user_id, created_at, status) and high-dimensional semantic vectors in a single SQL statement dramatically simplifies RAG architectures.
2. PostgreSQL Vector Search Ecosystem
PostgreSQL is currently the frontrunner among traditional RDBs for vector search capabilities, primarily driven by strong open-source community extension support.
Key Technologies
pgvector Extension: The de facto standard open-source extension for vector search in PostgreSQL.
Supported Indexes:IVFFlat (Inverted File Flat) and HNSW (added in v0.5.0 for superior speed and recall without requiring training steps).
PGVector-Python & Framework Integration: Deeply integrated into AI frameworks such as LangChain, LlamaIndex, and AutoGen.
Adopted Managed Services
Cloud Providers: AWS Aurora PostgreSQL, GCP Cloud SQL / AlloyDB, Azure Database for PostgreSQL natively support pgvector.
AI-First Postgres Platforms: Supabase and Neon have positioned PostgreSQL as primary vector databases for AI startups by offering managed pgvector environments out-of-the-box.
Key Strengths
Maturity: Highly stable and battle-tested in production environments.
Hybrid Search: Combines full-text search (BM25 via tsvector), structured filtering, and semantic vector search in a single SQL query.
3. MySQL & MariaDB Vector Search Ecosystem
MySQL has historically lagged behind PostgreSQL in vector capabilities, but official updates and ecosystem additions are closing the gap.
Key Solutions & Updates
MySQL 9.0 Innovation Release (Official Native Support):
Introduced a native VECTOR data type.
Added vector helper functions such as STRING_TO_VECTOR(), VECTOR_TO_STRING(), and DISTANCE().
Oracle MySQL HeatWave:
Offers integrated vector store capabilities directly within the HeatWave in-memory engine.
Built-in support for automatic vector generation from unstructured files stored in Object Storage.
MariaDB Vector (MariaDB 11.4+):
Introduced a native VECTOR data type and VECTOR_DISTANCE() functions.
Enterprise Infrastructure Reuse: Enables legacy enterprise systems heavily reliant on MySQL to implement lightweight vector operations without migrating to PostgreSQL or adopting a new database stack.
4. Usage Environments & Recommendation Matrix
Choosing between PostgreSQL, MySQL, or a Dedicated Vector DB depends on existing infrastructure, performance requirements, and workload scale.
Feature / Criteria
PostgreSQL (pgvector)
MySQL / MariaDB
Dedicated Vector DBs (Milvus, Pinecone, Qdrant)
Vector Ecosystem Maturity
High
Medium (Emerging)
Very High
Indexing Algorithm
HNSW, IVFFlat
Basic/Custom (Engine dependent)
HNSW, IVF, DiskANN, Custom
Data Scale (Vectors)
< 10–50 Million vectors
< 5–10 Million vectors
100M+ to Billion scale
Operational Complexity
Low (Single DB)
Low (Single DB)
High (Separate cluster to manage)
Metadata Filtering
Best (Native SQL)
Best (Native SQL)
Good (Payload filtering)
5. Deployment Decision Guide
Choose PostgreSQL (pgvector) if:
You are building a new Generative AI or RAG application from scratch.
You need low-latency semantic search on datasets under 50 million vectors.
You rely on complex joins between structured data and vector embeddings.
You use developer platforms like Supabase, Neon, or cloud-managed Postgres services.
Choose MySQL / MariaDB Vector if:
Your application architecture is strictly locked into the MySQL ecosystem and database migration is cost-prohibitive.
You are running enterprise workloads on Oracle MySQL HeatWave.
You require basic vector search or low-volume RAG features integrated into existing transactional systems.
Your system handles billions of high-dimensional vectors.
Ultra-low query latencies (sub-10ms at massive scale) are required.
You need specialized features like dynamic quantization, advanced hybrid search algorithms, or dedicated real-time streaming ingestion pipelines for vectors alone.
6. MySQL 9.0+ Example
Here is a sample demonstrating how to perform a vector similarity search in MySQL 9.0+ using its native VECTOR data type and helper functions.
Step 1: Create a Table with a Vector Column
Define a table containing a column with the VECTOR(dimensions) data type.
-- Create a table to store product embeddings (e.g., 3-dimensional vectors)
CREATE TABLE products (
    id INT PRIMARY KEY AUTO_INCREMENT,
    name VARCHAR(255) NOT NULL,
    description TEXT,
    description_embedding VECTOR(3) NOT NULL  -- Vector column with 3 dimensions
);
Step 2: Insert Vector Data
Insert data by converting string representations of array vectors into binary vector format using STRING_TO_VECTOR().
-- Insert sample product data with vector embeddings
INSERT INTO products (name, description, description_embedding)
VALUES
('Lightweight Running Shoes', 'Ultra-light shoes for jogging and marathons', STRING_TO_VECTOR('[0.1, 0.9, 0.2]')),
('Hiking Boots', 'Rugged boots built for rough mountain terrain', STRING_TO_VECTOR('[0.9, 0.1, 0.1]')),
('Gym Training Shoes', 'Designed for indoor weightlifting and cardio workouts', STRING_TO_VECTOR('[0.2, 0.8, 0.4]')),
('Casual Sneakers', 'Everyday fashion sneakers for casual wear', STRING_TO_VECTOR('[0.3, 0.4, 0.8]'));
Step 3: Run the Similarity Search Query
Use the DISTANCE() function to compute distance metrics between a target query vector and stored embeddings. Smaller distance values indicate higher similarity.
MySQL Supported Distance Metrics:
L2_SQUARED: Squared Euclidean distance (default).
COSINE: Cosine distance.
Query: Search for products similar to a query vector [0.2, 0.8, 0.4] using Cosine distance:
-- Search for the top 3 products most similar to 'Gym Training Shoes' [0.2, 0.8, 0.4]
SELECT
    name,
    description,
    DISTANCE(description_embedding, STRING_TO_VECTOR('[0.2, 0.8, 0.4]'), 'COSINE') AS distance
FROM
    products
ORDER BY
    distance ASC -- Order by closest distance (highest similarity)
LIMIT 3;
Step 4: Sample Output Result
name
description
distance
Gym Training Shoes
Designed for indoor weightlifting and cardio workouts