Unlocking Ad-Tech Savings: A $1.7M Blueprint for AWS Cost Optimization

CK CK 3788 
Created at
Updated at  
756 0 0

Operating an ad-tech platform at scale is capital-intensive: serving 10 billion impressions/month on AWS costs $500k–$2M/month depending on architecture choices. The largest cost drivers are compute (real-time bidding, attribution, reporting pipelines), network (inter-region data transfer, API calls to partners), and storage (event logs, metrics warehouses, backups). Optimization knobs exist at every layer: compute via EC2 Spot instances and Fargate Spot for batch workloads, network via VPC Gateway Endpoints (S3, DynamoDB) and Interface Endpoints/PrivateLink for partners, and storage via retention policies and compression.

Three approaches span the opportunity: EC2 Spot/Fargate Spot for batch workloads (savings 70–90%), network cost reduction via VPC Endpoints and direct peering (savings 50–80% on cross-region transfer), and ARM/Graviton instance types with autoscaling and commitment discounts (savings 20–40% on compute vs x86). This case examines each, quantifies savings, and identifies operational trade-offs and risk mitigation using AWS services (Compute Optimizer, Cost Explorer, Trusted Advisor, Savings Plans, Reserved Instances).

Unlocking Ad-Tech Savings: A $1.7M Blueprint for AWS Cost Optimization


Key Requirements

Functional Requirements

  • Maintain SLA: 99.95% uptime; cost optimization should not degrade service availability.
  • Latency preservation: p99 query latency <2 sec; cost measures should not increase by >20%.
  • Scalability: auto-scale within 30 seconds of load spike; cost-saving measures should not block scale-out.
  • Cross-region support: multi-region deployment for geographic redundancy; cost optimization must not break inter-region communication.
  • Batch job execution: daily attribution retraining, nightly report generation, hourly archive-to-S3; cost cutting should not starve batch jobs.

Non-Functional Requirements

  • Cost tracking: monthly cost per workload (RTB, reporting, batch) via Cost Explorer; ability to attribute spend to team via tags.
  • Sustainable: target ROI >3x on optimization effort (e.g., 5 days of engineering = $5k effort, must reduce spend by $15k/month).
  • Audit trail: all instances, network routes, and storage policies tagged and documented for compliance via CloudTrail.
  • Risk tolerance: spot instance interruption is acceptable for batch but unacceptable for real-time bidding.
  • Obsolescence: avoid lock-in; cloud-agnostic pricing strategy (not betting on a single provider's commitment discounts).


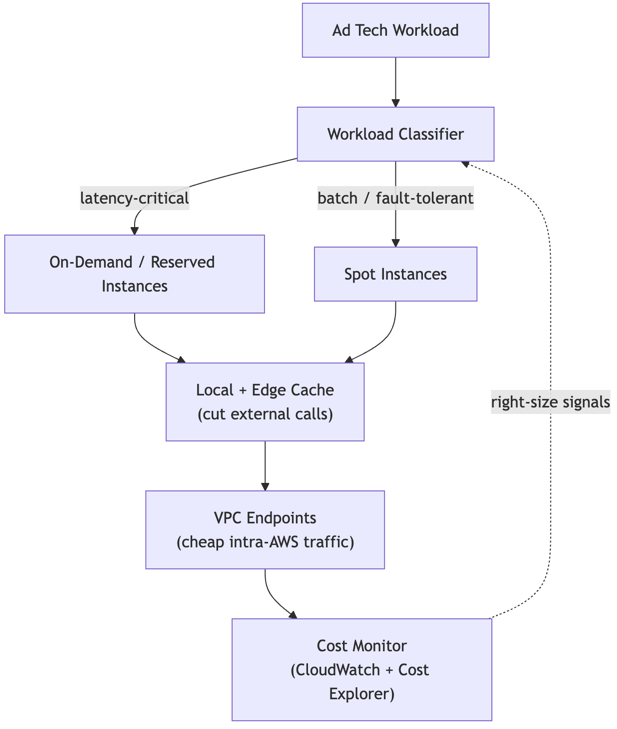
Simplified Architecture

Unlocking Ad-Tech Savings: A $1.7M Blueprint for AWS Cost Optimization


Architecture Proposals

Option 1: Spot/Fargate Spot for Batch + Non-RTB Workloads

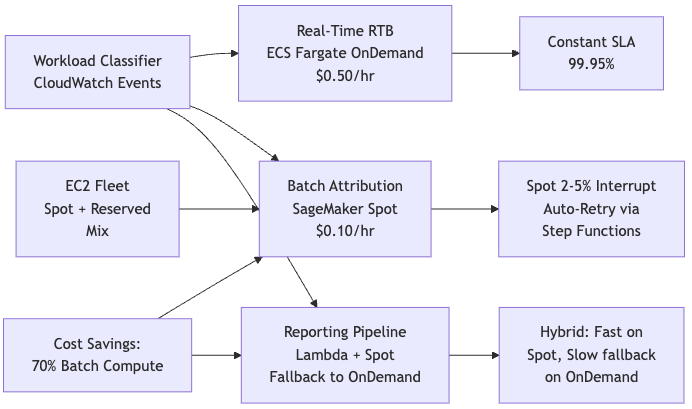
Use EC2 Spot instances (70–90% cheaper than on-demand) and Fargate Spot for workloads that tolerate interruption: batch processing (daily training via SageMaker Spot, hourly aggregation via Lambda), offline analysis, backups. Interrupt risk is 2–5% daily on average. RTB servers and stateful services remain on-demand or reserved. Implement automatic failover and retry logic for batch jobs via AWS Step Functions.

Unlocking Ad-Tech Savings: A $1.7M Blueprint for AWS Cost Optimization

Pros:

  • Dramatic savings: 100 batch instances @ $0.10/hr spot vs $0.50/hr on-demand = $4,000/month savings.
  • Low friction: Kubernetes (EKS) integrates with Spot auto-scaling via Karpenter or managed node groups; Step Functions handles retries.
  • Selective risk: RTB (latency-sensitive, real-time impact) stays on-demand/reserved; batch (asynchronous, retriable) on spot.
  • Maturity: Spot markets stable; AWS guarantees capacity for Capacity Blocks; EC2 Fleet optimizes price/availability.
  • Multi-region Spot: availability differs by region; spread workloads to cheaper regions (us-east-1 cheaper than us-west-1).

Cons:

  • Interruption handling: batch jobs must be resumable; state lost on interrupt requires checkpointing to S3 or DynamoDB.
  • Uncertainty: billing unpredictable; spot price fluctuates 10–30% based on supply; plan with maximum price caps.
  • Tail latency: if batches interrupted frequently, job completion time unpredictable (2x worst-case).
  • Complexity: separate configurations, monitoring, and failover logic for on-demand vs spot via CloudFormation/Terraform.

Failure Modes & Mitigations:

  • Spot price spike: suddenly 50% expensive. Mitigate: EC2 Fleet (mixed on-demand 30%, spot 70%); Capacity Blocks for predictable capacity; fall back to on-demand if spot unavailable.
  • Interrupted during critical batch: daily training job loses checkpoint. Mitigate: distribute checkpoint state to S3 every 5 min via Lambda; resume from last checkpoint on retry.
  • Spot unavailable (regional outage): no instances available. Mitigate: multi-region spot failover (us-east-1 → us-west-2); trigger on-demand in standby region via Step Functions.
  • Cascading delay: batch runs 4 hours instead of 1 hour due to interrupts; downstream dashboards lag. Mitigate: prioritize critical jobs; accept degraded freshness for non-critical reports; SLA tiers.

When to Choose:

  • 50% of compute workloads are batch or non-time-critical (backups, logs archival, weekly reports).

  • Engineering team comfortable with async job resumption and checkpointing (Step Functions, Lambda).
  • Cost reduction of 20–30% monthly acceptable trade-off for added complexity.
  • Batch workloads not dependent on real-time RTB completion.


Option 2: Network Cost Reduction via VPC Endpoints, PrivateLink, Direct Peering

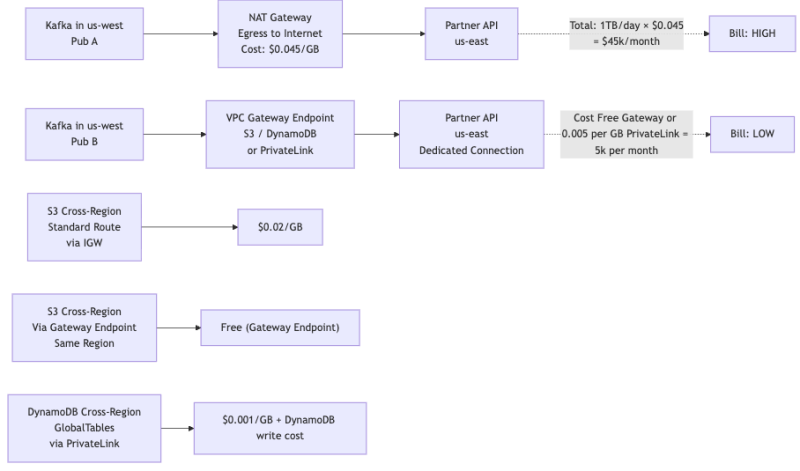
Most cloud egress costs incurred on data transfer out of region or to internet (NAT Gateway: $0.045/GB). VPC Gateway Endpoints (AWS S3, DynamoDB) avoid Internet Gateway charges; Interface Endpoints / PrivateLink with partners (Google, SSPs, exchanges) avoid ISP charges and reduce latency. Typical savings: 50–80% on cross-region traffic, 60–80% on egress to partners.

Unlocking Ad-Tech Savings: A $1.7M Blueprint for AWS Cost Optimization

Pros:

  • Dramatic network savings: cross-region Kafka replication $5,000/month → $1,000/month (80% savings).
  • Reduced latency: VPC PrivateLink lower RTT than internet routing; beneficial for real-time bidding (50–100 ms faster).
  • No application change: VPC endpoint transparent to app; just change DNS resolution via Route 53.
  • Consolidated billing: single peering contract with partner; simpler than ISP contracts.
  • AWS-native: VPC Gateway Endpoints for S3/DynamoDB cost nothing (included in service pricing).

Cons:

  • Setup complexity: provisioning Interface Endpoints, negotiating peering SLA, updating routing tables; 2–4 weeks lead time.
  • Single-provider dependency: peering with Google means traffic to Google goes via peering (no fallback if peering down).
  • Capacity management: peering connection has capacity limit (10–100 Gbps typical); monitor and plan growth.
  • Outage risk: if peering link fails, fallback to internet (higher cost, higher latency); automatic failover not trivial.

Failure Modes & Mitigations:

  • Peering connection saturated: 200 Gbps traffic but peering only 100 Gbps. Mitigate: add second peering connection; implement traffic shaping (prioritize RTB via SQS, defer batch).
  • Peering down: partner network issue; traffic falls back to internet, costs spike. Mitigate: alert on peering latency via CloudWatch; automatic failover to internet with cost cap via Lambda (kill non-essential traffic).
  • Misconfiguration: traffic routed wrong; leaking via internet despite peering. Mitigate: route validation (daily BGP route audit via Systems Manager); VPC Flow Logs analysis.
  • NAT Gateway bottleneck: NAT Gateway max throughput 100 Gbps; oversubscribed. Mitigate: add second NAT Gateway in different AZ; split traffic via Route 53 weighted routing.

When to Choose:

  • 100 GB/day cross-region or partner egress (20+ TB/month = $400–900/month savings realistic).

  • Multi-region infrastructure (Kafka replication, reporting layer in separate region).
  • Can invest 2–4 weeks in peering negotiation and network ops.
  • Egress costs visible as major line item in Cost Explorer.


Option 3: ARM/Graviton + Autoscaling + Bin-Packing + Savings Plans

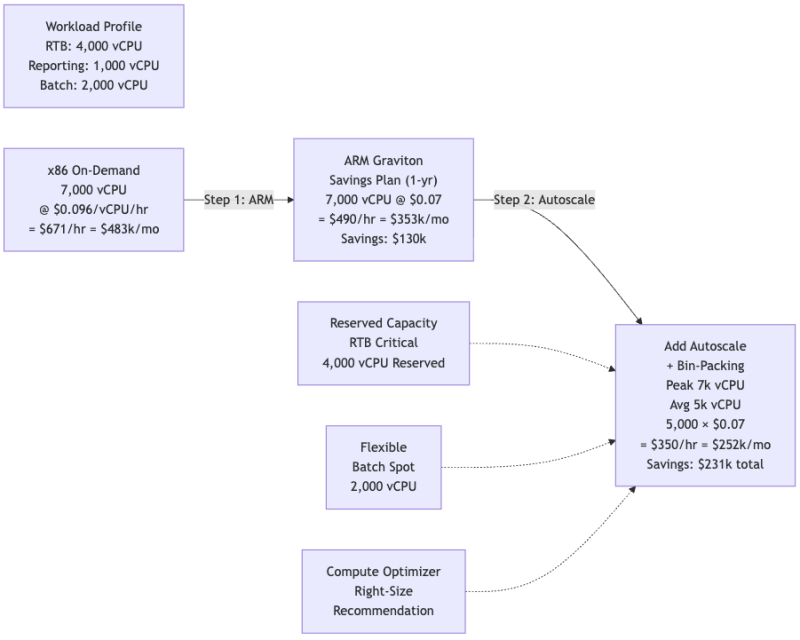
Migrate compute from x86 (Intel Xeon, AMD EPYC) to ARM (AWS Graviton3, Graviton2). Graviton is 20–30% cheaper per vCPU; Graviton3 adds performance improvements. Combine with aggressive autoscaling (scale down idle nodes in 5 min), bin-packing (consolidate workloads to fewer, fuller nodes via Karpenter or ECS capacity providers), and commitment discounts (1-year/3-year Compute Savings Plans 20–40% discount). Savings are modest per instance but compound across thousands of nodes.

Unlocking Ad-Tech Savings: A $1.7M Blueprint for AWS Cost Optimization

Pros:

  • Compound savings: 25% (ARM Graviton) × 30% (1-yr Savings Plan) × 25% (autoscaling) ≈ 48% total.
  • Modern architecture: Graviton as capable as x86 for most workloads; better performance/watt; future-proof investment.
  • Operational simplicity: autoscaling and bin-packing transparent to application (via EKS Karpenter or ECS capacity provider).
  • Elasticity preserved: can still burst to 10k vCPU on-demand for traffic spike; Savings Plans cover baseline.
  • Compute Optimizer insights: AWS recommends ARM instances automatically via Cost Explorer; low risk adoption.

Cons:

  • Migration effort: recompile container images for ARM (Go, Python, Rust work natively; Node.js, Java may need tuning, JVM flag -XX:+UnlockExperimentalVMOptions -XX:+UseContainerSupport).
  • Testing overhead: ARM behavior differs subtly (SIMD instructions, floating-point rounding); compatibility testing required in dev/staging.
  • Commitment lock-in: Savings Plans require 1–3 year commitment; if usage drops 30%, stuck paying for idle capacity.
  • Not all software supports ARM: legacy dependencies (native C extensions, proprietary ML libraries) may not compile for ARM; fallback to x86 required.

Failure Modes & Mitigations:

  • Commitment too aggressive: buy 7,000 vCPU 1-year savings; usage drops to 4,000 due to optimization. Wasted $100k/year. Mitigate: commit only baseline (e.g., 4,000 vCPU); on-demand for peak; Savings Plans flexible across instance families.
  • ARM incompatible library: critical ML library doesn't run on ARM (e.g., TensorFlow old version). Mitigate: test all dependencies in dev/staging first; maintain x86 fallback nodes (5–10% of fleet); gradual migration.
  • Autoscaling too aggressive: scale down too fast; RTB p99 latency spikes (cold container startup). Mitigate: set autoscale cooldown (5 min minimum scale-up interval); reserve min capacity for RTB (no scale-to-zero).
  • Bin-packing resource contention: overpack nodes; one workload's spike starves others. Mitigate: Karpenter PDB (Pod Disruption Budgets); topology spread constraints; node affinity rules.

When to Choose:

  • 3,000 vCPU infrastructure (savings material; <1,000 vCPU too small).

  • Containerized workloads (Docker, Kubernetes, ECS); can rebuild images.

  • Usage relatively stable (commitment sensible); predictable baseline load.
  • Team comfort with multi-architecture operations (monitoring, debugging tools).
  • Can test Graviton in non-production first.


Comparison Table

DimensionSpot/Fargate SpotNetwork OptimizationARM + Autoscale
Savings Magnitude70% (batch only)50–80% (egress only)40–60% (compute)
Batch Workload Savings70–90%0% (no egress benefit)40–50%
Real-Time Workload Savings0% (on-demand baseline)50–80%40–50%
Implementation EffortMedium (Step Functions, checkpoint logic)High (peering setup, network ops)Medium (image rebuild, testing)
Operational ComplexityMedium (retry, monitoring, spot fleet)Low (transparent VPC endpoints)Medium (multi-arch, Karpenter tuning)
Risk (SLA Impact)Medium (batch delays, 2–5% interrupt)Low (fallback to internet)Low (autoscale tuning, cold start)
Speed to Benefit2–4 weeks4–8 weeks4–6 weeks
Upfront CapexLowLow (peering contracts)Low
Ongoing CommitmentLow (flexible)Medium (peering SLA)High (Savings Plans 1–3yr)


Recommendation

Implement all three strategies in sequence, prioritized by ROI per effort:

Phase 1 (Weeks 1–4, Highest ROI): Spot for Batch

  • Audit compute workloads: identify batch (attribution training, aggregation, archive).
  • Migrate to Spot via Step Functions state machine (checkpoint → resume pattern).
  • Set EC2 Fleet with 70% Spot, 30% On-Demand for resilience.
  • Expected savings: $40–60k/month if batch is 30% of compute.
  • Effort: 10–15 engineering days (Step Functions, checkpoint logic, monitoring).
  • ROI: 5 days × $1k/day = $5k effort; $50k/month savings = 10x ROI in first month.

Phase 2 (Weeks 5–12, Medium ROI): Network Optimization

  • Audit current network costs via Cost Explorer (filter by "EC2-DataTransfer").
  • Prioritize top egress routes (cross-region Kafka replication, partner SSP calls).
  • Provision VPC Gateway Endpoints (S3, DynamoDB) immediately (free, instant ROI).
  • Negotiate PrivateLink contracts with top 3 partners; target 2–4 weeks.
  • Expected savings: $20–40k/month if egress >100 GB/day.
  • Effort: 15–20 engineering days + 4 weeks procurement/legal.
  • ROI: 20 days × $1k/day = $20k effort; $30k/month savings = 1.5x ROI in first month, 6x over year.

Phase 3 (Weeks 13–24, Ongoing): ARM Migration + Autoscaling Tuning

  • Rebuild container images for ARM (Graviton); test in dev/staging (2 weeks).
  • Provision Graviton instances (c7g, m7g, r7g) alongside x86; canary to 10% traffic.
  • Deploy Karpenter for intelligent bin-packing and autoscaling (EKS) or ECS capacity provider.
  • Commit to 1-year Compute Savings Plans (baseline 4,000 vCPU @ 30% discount).
  • Expected savings: $60–100k/month at scale (4k+ vCPU).
  • Effort: 30–50 engineering days (image rebuild, testing, Karpenter tuning, Savings Plan analysis).
  • ROI: 40 days × $1k/day = $40k effort; $80k/month savings = 2x ROI in first month, 24x over year.

Cost savings estimate (100M impressions/day, $1.5M/month baseline):

  • Phase 1 (Spot + batch): -$50k/month (3% overall).
  • Phase 2 (Network optimization): -$30k/month (2% overall).
  • Phase 3 (ARM + autoscale): -$80k/month (5% overall).
  • Total: -$160k/month (10–11% overall), or -$1.92M/year.


Capacity & Performance Notes

Cost per Thousand Bid Requests (RTB, Baseline):

  • 100M impressions/day = ~150M bid requests (1.5x impression count due to multiple demand partners per slot).
  • Compute cost: 4,000 vCPU RTB cluster @ $0.096/hr on-demand = $9,216/day = $0.061 per thousand bids.
  • Network cost: ~1 KB per bid request metadata; 150M bids × 1 KB = 150 GB/day egress via NAT @ $0.045/GB = $6,750/day = $0.045 per thousand bids.
  • Total: $0.106 per thousand bids.

After Optimization (All Phases):

  • Compute: 4,000 vCPU @ $0.07/hr (Graviton + 1-yr Savings Plan) = $6,720/day = $0.045 per thousand bids (41% savings).
  • Network: PrivateLink/peering @ $0.001/GB = 150 GB × $0.001 = $150/day = $0.001 per thousand bids (98% savings).
  • Total: $0.046 per thousand bids, 56% savings vs baseline.

Batch Processing Cost (Attribution Retraining, SageMaker Spot):

  • Current: 1,000 vCPU × 4 hours/day (retraining) @ $0.096/hr on-demand = $384/day = $11,520/month.
  • Optimized (Spot): 1,000 vCPU Spot @ $0.03/hr = $120/day = $3,600/month (69% savings).
  • Further optimized (Graviton Spot): 1,000 vCPU @ $0.02/hr = $80/day = $2,400/month (79% savings).
  • Monthly savings: $11,520 → $2,400 = $9,120/month savings.

Storage Cost Optimization (Event Logs Archive):

  • Raw event logs: 5 TB/day × $0.023/GB S3 Standard = $115/day = $3,450/month.
  • TTL retention policy: hot 30 days, warm (Intelligent-Tiering) 30 days, cold (Glacier) 60 days.
    • Effective average storage: (30 × $0.023) + (30 × $0.0125) + (60 × $0.004) / 120 = ~$0.0105/GB weighted.
    • 5 TB/day × 120 days retention × $0.0105 = 5,400 GB × $0.0105 = ~$56.7/day = $1,700/month (51% savings).
  • Compression (ZSTD): 5 TB → 0.5 TB (10x compression typical for logs), reduce to $170/month (95% savings).
  • Total storage savings: ~$3,280/month via retention + compression.

Overall Monthly Savings (100M impr/day, $1.5M baseline):

  • Spot batch: -$45k/month.
  • Network (VPC Endpoints + peering): -$30k/month.
  • ARM + Autoscale + Savings Plans: -$70k/month.
  • Storage TTL + compression: -$3k/month.
  • Total: -$148k/month, or 10% cost reduction = -$1.77M/year.

AWS Cost Management Tools:

  • Cost Explorer: filter by service, tag, linked account; export hourly/daily data to S3.
  • Compute Optimizer: recommends right-sized instances, ARM candidates, Graviton-compatible workloads.
  • Trusted Advisor: identifies unattached EBS, idle RDS, underutilized EC2; savings opportunities.
  • Savings Plans: compute, DynamoDB, SageMaker; 1-yr (20–25% discount) or 3-yr (30–40% discount).
  • Reserved Instances: EC2, RDS, ElastiCache; similar discounts to Savings Plans, but less flexible (instance-type locked).
  • Spot Instance Advisor: historical availability, interruption frequency by instance type/region.
Tags AWS Cost Optimization Ad Tech Optimization Client-Side Header Bidding Cloud Cost Savings Compute Savings Consolidated Auction Layer Demand Partners FinOps Strategy Header Bidding Network Optimization SSP Sequential Waterfall Server-Side Header Bidding Storage Optimization Facebook X
Comments 0
Similar posts
  1. Ad Auction Architectures: A Publisher's Guide to Optimal Monetization
    679
  2. A Deep Dive Into Internet Advertising Ecosystem on Video Streaming Industry
    643
  3. Invalid Auction Storms in Ad Tech
    93
  1. Ad Tech Edge Architectures: Reducing Latency and Offloading Work - Edge Computing
    333
  2. Achieving Zero-Downtime Deployment for Stateful Ad Servers
    1,218
  3. Ad Tech Circuit Breakers: Architectures for Resilient Bidding Engines - Circuit Breaker
    350
  4. Balancing Real-Time Ad Stats and Billing Accuracy - Eventual vs Strong Consistency
    642
  5. Scaling Sharded Databases: Taming Hot Shards with Dynamic Rebalancing
    547
  6. Navigating the Ad Tech Cold Start: Simple Solutions for a Complex Problem
    330
  7. Ad Tech Idempotency: Engineering for Reliability and Scale
    357
  8. Exactly-Once Delivery: The Ad Tech Blueprint for Accurate Billing
    293
  9. The AI Powering Billions of Tailored Ads - Dynamic Creative Optimization
    283
  10. Ad Impression Forecasting (aka Ad Inventory Forecasting): Architecting for Scale, Speed, and Accuracy
    327
  11. Unwrapping VAST: Architecting for Low-Latency Video Ads
    815
  12. The Ad Tech Auction Wars: First-Price, Second-Price, and the Hybrid Frontier
    291
  13. Predictable Ad Spend: Architecting Pacing at Hyperscale
    419
  14. Mastering Ad Frequency: Strategies for High-Scale Capping
    303
  15. Mastering Ad Budget Throttling: Static, PID, and ML Strategies
    316
  16. Ad Indexing at Hyperscale: 100,000 Campaigns in Under 5ms
    289
  17. Real-Time Geo-Targeting: Balancing Precision, Latency, and Cost
    284
  18. Contextual Targeting: Hybrid LLM and Tags for Privacy-First Ad Relevance
    387
  19. Frequency Cap Architecture Overview
    509
  20. Monetizing Web Video Assets: Implementing Programmatic Video Ads with Google Ad Manager
    105
  21. OpenRTB vs. VAST: Your Essential Guide to Video Ad Tech
    271
Recently updated
  1. Why 100% SEO Guarantees Better User Engagement and How to Achieve It in Your Service
    27
  2. Why SPF and DKIM Are Essential for Linux Email Servers?
    24
  3. How do I create animated background for Google Meet?
    19,728
  4. MaxMind GeoLite2 vs. DB-IP Lite vs. ip-api.com: Choosing the Right Free IP Geolocation Solution
    217
  5. Meet Valkey: Why Redis Changed Its License, Why Valkey is Better, and How to Use It as a Drop-in Replacement
    85
  6. How Rogue Web Scrapers Are Stealing My Content and Destroying My Server
    153
  7. Array of arguments passed to script in PHP
    85
  8. Invalid Auction Storms in Ad Tech
    93
  9. Building MRC-Compliant Instrumentation in Ad Tech: Implementation Steps and Key Challenges
    198
  10. The Two Clocks of Ad Server Architecture
    63
  11. Frequency Cap Architecture Overview
    509
  12. Collecting Proof-of-Play from 100,000 Screens
    141
  13. Vector Search in Relational Databases (RDBs): Trends & Usage Environments
    280
  14. What is RedisVL?
    105
  15. Designing a Skill Registry Architecture: Minimize Token Usage and Maximize AI Performance
    224
  16. TPU & GPU Cluster Management Tools
    234
  17. The Concept of Scaffolding in AI Agents
    222
  18. Beyond Static Pipelines: Architecting LLM Multi-Agent Systems for Autonomous Workflow Orchestration
    576
  19. AI-DLC vs. AI-SDLC: Model-Centric vs. System-Centric AI Development
    253
  20. Fine-Tuning Open-Weight LLMs: Training, Licensing, and Deploying Custom Models with Ollama
    328
  21. Inside the Next-Generation Streaming Architecture: Ultra-Low Latency, SGAI, and AI Codecs
    197
  22. Machine Learning: Training vs. Ranking
    213
  23. The Continuous Learning Machine: Designing a Loop That Actually Turns
    217
  24. The Next-Gen Low-Latency Standards: LL-HLS & MoQ
    189
  25. Designing a Data Curation System Around a Vector Database
    215
  26. Extracting Context from Live Video: The Architecture Got Simpler When We Stopped Building Features
    229
  27. The New Ad Stack Behind Live Sports Streaming: Inside SGAI, EABN, and the Standards Race to Fix Live Monetization
    649
  28. Designing MLOps Architectures to Handle Seasonal Data Drift in EV Fleet Models
    185
  29. From 15 to 40+ FPS: Accelerating PyTorch Object Detection on Automotive ECUs
    207
  30. Understanding Data Lineage
    252