Achieving Zero-Downtime Deployment for Stateful Ad Servers
CK 3776 Created at Updated at
1,21700
Ad servers must serve requests continuously; a 5-minute deployment window during which the old binary is offline and the new binary hasn't warmed up can lose thousands of dollars in impression revenue and harm publisher relationships. Zero-downtime deployment (ZDD) strategies ensure that during version rollout, traffic is never dropped, in-flight auction sessions are preserved, and latency remains stable.
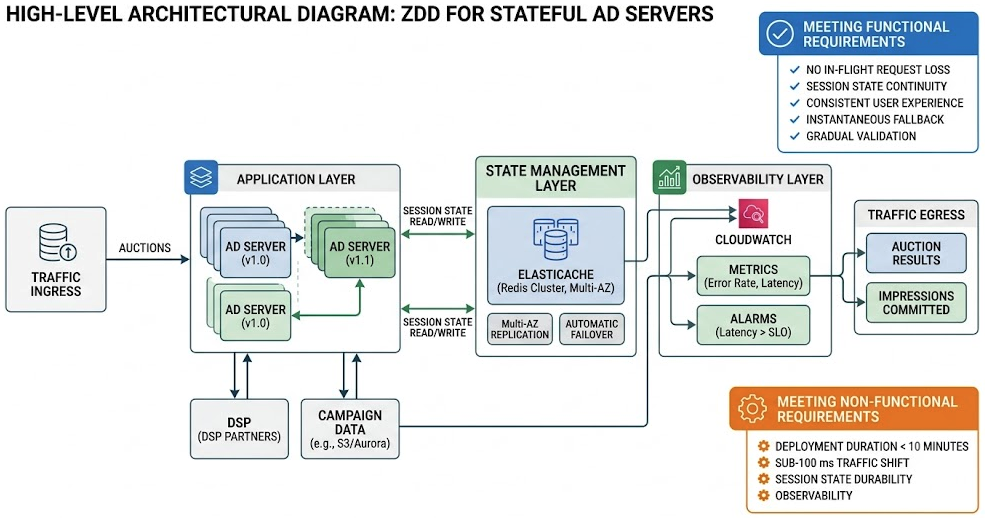
The key challenge: auctions are stateful. A bid request arrives, the server reserves session state (campaign pacing counters, budget tracking, user frequency caps), orchestrates calls to DSPs, and commits or rolls back based on results. If the server crashes mid-auction, the session is lost. ZDD must ensure that as old servers shut down, any in-progress auctions are either completed or their state is transferred to new servers via ElastiCache for Redis.
Three approaches offer different trade-offs: Blue-Green with shared session store on ElastiCache (atomic cutover, higher operational burden), Canary rollout with traffic shifting via ALB weighted target groups (gradual validation, higher risk if bugs slip through), and Rolling restart with connection draining on ECS (Kubernetes-native pattern, requires careful ordering).
Key Requirements
Functional Requirements
No in-flight request loss: All auctions that start before a server shuts down must complete; no dropped impressions or hung requests.
Session state continuity: If a user's auction session is in progress, the new binary must be able to complete it (read previous pacing counters, budget state, etc. from ElastiCache).
Consistent user experience: Users must not see divergent ad selections or pricing due to version differences.
Instantaneous fallback: If new version has critical bugs, rollback to previous version within 30 seconds without losing traffic.
Gradual validation: Before routing 100% of traffic to new version, validate on subset (5–10%) that error rates and latency are acceptable.
Non-Functional Requirements
Deployment duration under 10 minutes: Operator must be able to deploy a new version within the window users expect (peak traffic windows excluded).
Sub-100 ms traffic shift: When cutting over from old to new version, the ALB shift must happen fast enough that no batch of auctions lands on both versions (violates consistency).
Session state durability: If shared session store (ElastiCache) fails, deployment should still complete gracefully (fallback to in-memory state, accept some auction loss).
Observability during deployment: Operators must see real-time metrics (error rate, latency p99, traffic distribution) in CloudWatch to detect issues before they become customer-facing.
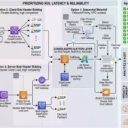
Simplified Architecture
Architecture Proposals
Option 1: Blue-Green with Shared Session Store (ElastiCache Redis)
Description
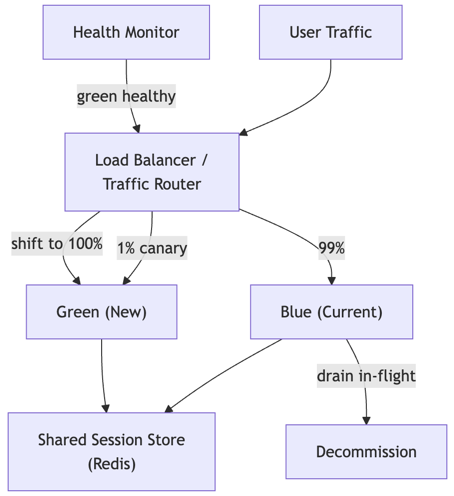
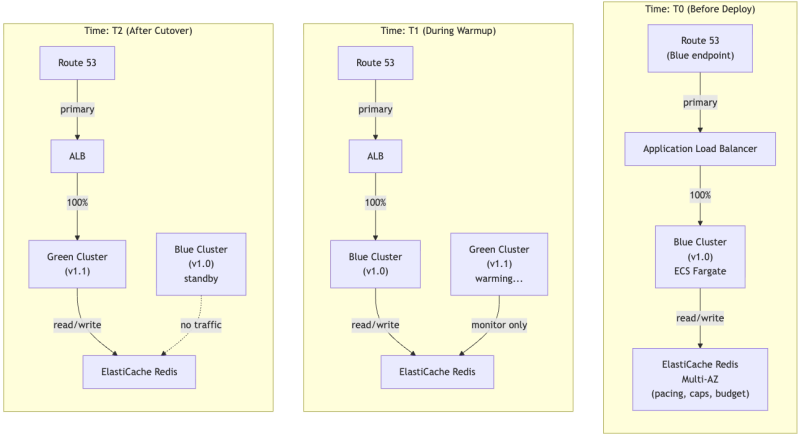
Maintain two identical ad server clusters: Blue (current production version) and Green (new version). Both are ECS Fargate task sets behind separate Application Load Balancers. All session state (campaign pacing, user frequency caps, budget reservations) is stored in ElastiCache for Redis (Multi-AZ), accessible to both clusters. Route 100% of traffic to Blue; deploy the new binary to Green servers, including a warm-up phase (pre-load campaign data, connections to DSPs). Once Green is warm, atomically switch traffic from Blue to Green using Route 53 or ALB rule changes. Keep Blue running for 5 minutes as a fast fallback; then decommission.
Pros
Atomic cutover: Switch from old to new is a single Route 53 or ALB rule change; all traffic moves at once, eliminating version-split issues.
Simple rollback: If new version has critical bug, revert Route 53 rule in < 5 seconds, and Blue is still warm.
Shared state simplicity: All servers (old and new) share one ElastiCache cluster, so auctions in-flight can continue uninterrupted.
Tested scenario: Blue-Green is well-understood in mature organizations; minimal surprises.
Cons
2x infrastructure cost: Maintaining two full clusters consumes double the ECS task resources (though Blue can run at lower utilization during normal times).
ElastiCache becomes critical path: If ElastiCache fails, both clusters are down. Requires ElastiCache HA (Multi-AZ, automatic failover), adding complexity.
Long synchronization windows: Waiting for Green cluster to warm up (load campaign data, pre-connect to DSPs, prime caches) can take 2–3 minutes, during which operators are anxious about downtime.
Higher environment complexity: Two versions running in parallel; higher chance of configuration drift or missing state in Green.
Failure Modes & Mitigations
ElastiCache latency spike during cutover: If Redis gets overloaded when traffic switches (all in-flight auctions suddenly writing session updates), auctions time out. Mitigate by pre-warming ElastiCache with a traffic spike simulation before cutover; monitor ElastiCache CPU and eviction rate via CloudWatch.
Green cluster not ready: If campaign data load incomplete, Green will see cache misses, latency spikes. Mitigate by automated warm-up checks: don't switch until campaign data loaded and DSP connections established.
Slow rollback: If new version has latency regression and operators notice 2 minutes into deployment, rolling back takes time (Blue needs to warm up again). Mitigate by pre-deployment performance testing (A/B test new version on 1% of traffic via canary before full deployment).
When to Choose
Choose this option if you have large ad server clusters (>100 instances) and can afford 2x infrastructure, or if you run ad servers in multiple AWS regions and can stagger deployments (Blue-Green in one region, canary in another). Typical in large ad exchanges where deployment windows are critical and downtime is measured in millions of dollars per minute.
Option 2: Canary Rollout with ALB Weighted Target Groups
Description
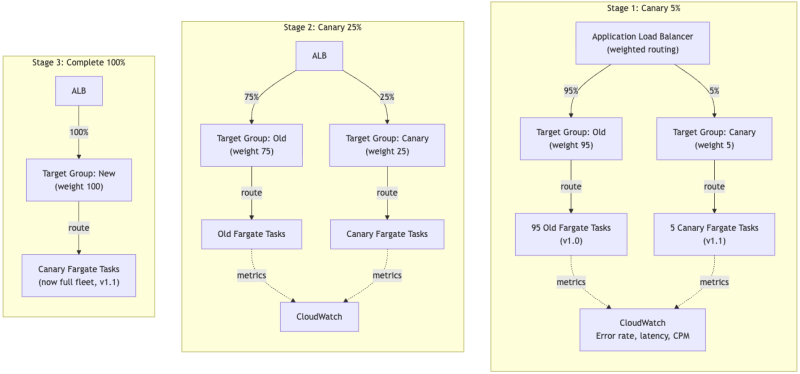
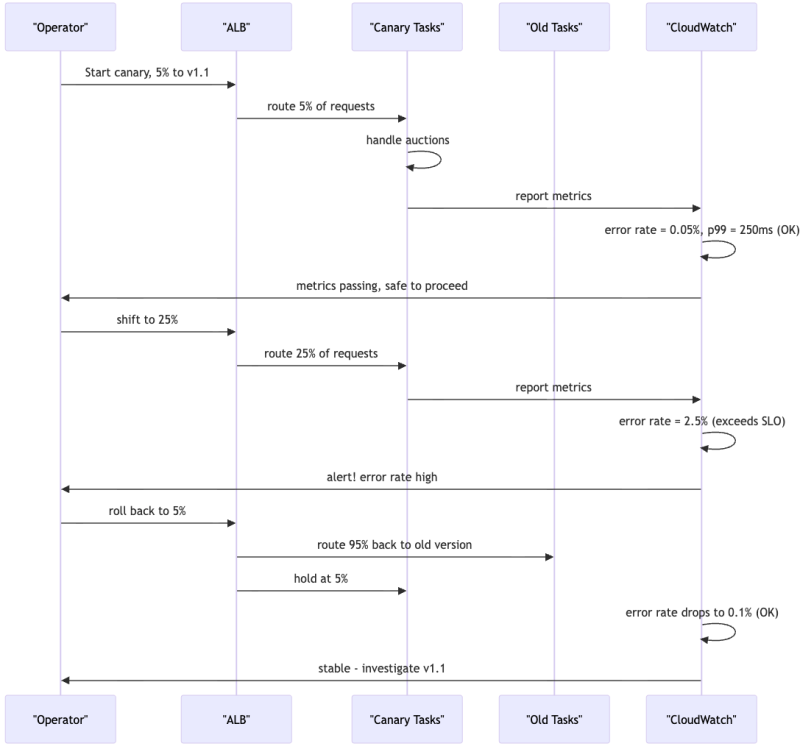
Deploy the new version to a small subset of ECS Fargate tasks (Canary, 5–10% of traffic). Use ALB weighted target groups to route a small percentage of requests to Canary; monitor error rates, latency, and business metrics (CPM, fill rate) via CloudWatch. If metrics stay within SLO (error rate < 0.1%, latency p99 < 300 ms), gradually shift more traffic (5% → 25% → 50% → 100%) over 10–30 minutes. If degradation is detected, stop the rollout and hold at the safe traffic level, or roll back to the previous version.
Session state is not explicitly shared; instead, sessions are ephemeral and short-lived (typically < 1 second). If a canary task crashes mid-auction, the request is retried upstream, and a stable task (old version) handles the retry. Optional: use ElastiCache to store session state for stateful auctions.
Sequence diagram for canary with auto-rollback
Pros
Gradual rollout: Small percentage of traffic validates new version in production before full deployment; reduces risk of bugs reaching all users.
Easy rollback: At any point, revert traffic to old version by changing ALB weighted target group; old tasks stay warm and accepting traffic.
Cost-efficient: Canary tasks are a small overhead (5–10 tasks for a 100-task cluster); minimal extra infrastructure.
Business metric validation: Monitor CPM, fill rate, and other revenue metrics; detect business-logic regressions early via CloudWatch dashboards.
Fast deployment: If all stages pass, full deployment completes in 15–30 minutes.
Cons
Complexity in rollback decision: Operators must decide when metrics are "bad enough" to roll back; edge cases (latency is 5% higher, error rate is 0.2%, CPM is flat) require judgment.
Version fragmentation: For 15–30 minutes, different versions serve users; if bugs are introduced, fixing them across versions becomes complicated.
Session continuity not guaranteed: If a canary task crashes, the session is lost; requests are retried upstream. For long auctions or stateful operations, this is risky. Mitigate with ElastiCache session sharing.
Observability overhead: Must instrument detailed metrics to distinguish canary vs. stable version performance; requires CloudWatch Insights queries.
Failure Modes & Mitigations
Slow degradation undetected: If latency degrades gradually (100ms → 120ms → 150ms) over 10 minutes, human operators might miss the trend. Mitigate by automated rollback triggers in CloudWatch: if p99 latency increases > 10% compared to baseline, auto-rollback via CodeDeploy or Lambda.
Session loss on canary crash: If a canary task crashes, in-flight auctions terminate. Mitigate by keeping session timeout short (< 100 ms) and designing auctions as stateless (each DSP call is independent), or by using ElastiCache for session state.
When to Choose
Choose this option if your deployments happen multiple times per day and you want fast validation with easy rollback. Common in fast-moving startups and in organizations with strong observability culture (detailed CloudWatch metrics, alarms). Works well for ad servers because auctions are short-lived and stateless.
Option 3: Rolling Restart with Connection Draining (ECS Rolling Update)
Description
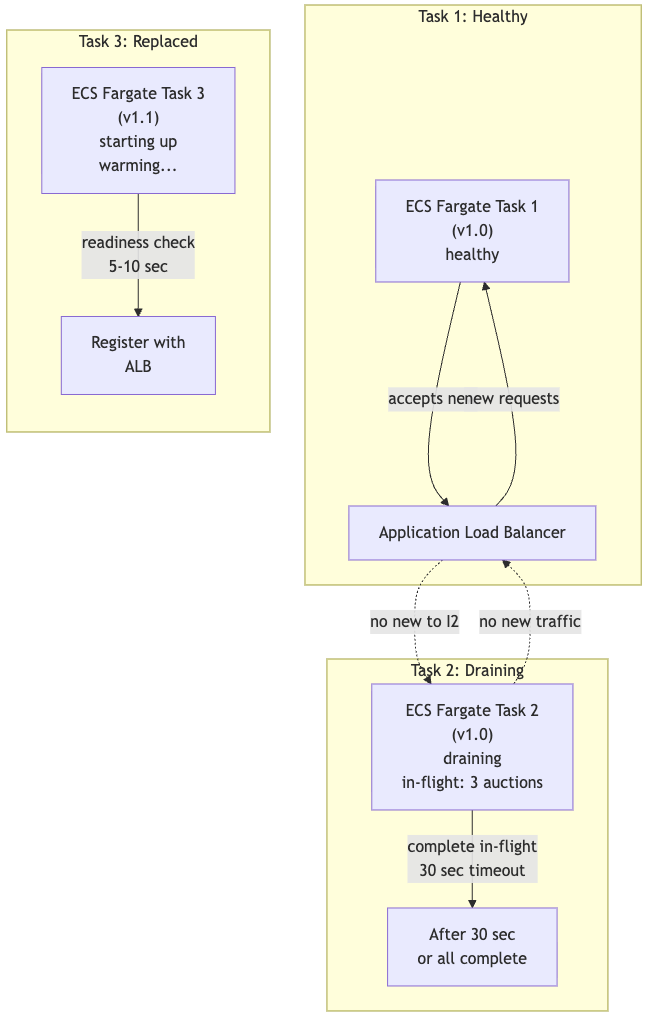
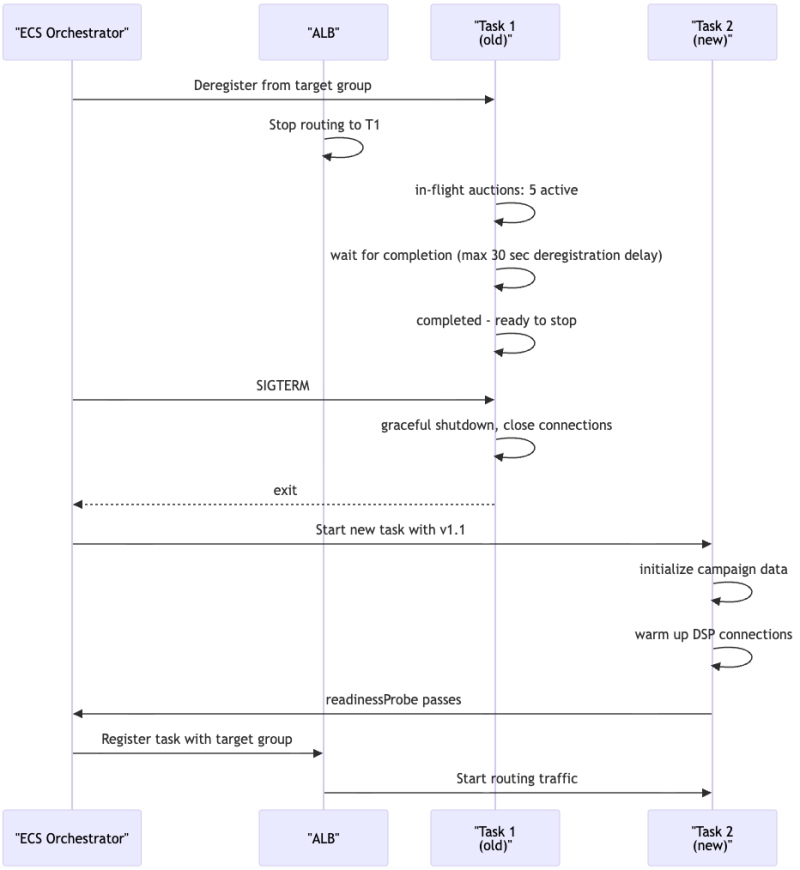
Use ECS rolling update policy to roll out the new version task-by-task. For each Fargate task: mark it as unhealthy (so ALB drains connections), wait for in-flight requests to complete (connection draining, configurable timeout via ALB deregistration delay), then stop the task and start a replacement with the new binary. Repeat for all tasks. No shared ElastiCache, no blue-green overhead; state is ephemeral and tied to the task.
ECS orchestrates the rolling update automatically based on deployment circuit breaker settings (max healthy percentage, deployment min healthy percentage).
Sequence for rolling update
Pros
No extra infrastructure: Roll out on existing ECS tasks; no blue-green overhead, no canary tasks.
ECS-native: Uses standard ECS constructs (task definition, rolling update deployment circuit breaker); well-integrated with container orchestration.
Deterministic: Each task goes through a known sequence (register -> drain -> stop -> replace); no ambiguous states.
Fast deployment: For a 100-task cluster, rolling out one task every 30 seconds = ~50 minutes total; acceptable for most organizations.
Cons
In-flight request loss if misconfigured: If deregistration delay is skipped or too short, auctions are killed mid-stream. Requires careful ECS task definition configuration (containerPort with ALB target group deregistration delay).
Version fragmentation during rollout: For the 50-minute window, some tasks run v1.0 and others run v1.1; inconsistency in cache warming, campaign data, etc.
Slow feedback on bugs: Operators don't see metrics until the deployment is underway; can't pause and investigate without stopping the entire rollout (pause via ECS deployment circuit breaker).
Rollback overhead: If bug is detected midway, rolling back requires another 50-minute rolling update (back to v1.0).
Failure Modes & Mitigations
Deregistration delay too short: If ALB deregistration delay is 10 seconds but auctions take 20 seconds, they'll be killed. Mitigate by observing p99 auction duration via CloudWatch and setting delay to 2x that (e.g., if p99 = 200ms, use 500ms delay, then 5 seconds to be safe).
Readiness probe flakiness: If task readiness check fails for a legitimate reason (slow startup, temporary DSP latency), ECS keeps the task unavailable, blocking the rollout. Mitigate by separating startup checks from steady-state readiness probes (initial delay + threshold).
When to Choose
Choose this option if you're already running on ECS and have mature operational practices (readiness probes, graceful shutdown, metrics shipping to CloudWatch). Standard for most cloud-native deployments. Works well if auctions are short-lived (< 1 second) and stateless.
Comparison Table
Aspect
Blue-Green + ElastiCache
Canary (ALB Weighted)
Rolling (ECS Update)
Deployment duration
10–15 min (including warmup)
20–30 min (5% → 100%)
30–60 min (rolling across fleet)
Infrastructure overhead
2x (full blue cluster standby)
10% (canary tasks)
0% (in-place)
Atomic cutover
Yes (single Route 53 switch)
No (gradual traffic shift)
No (progressive task replacement)
Rollback speed
< 30 sec (switch Route 53)
< 5 sec (change target group weight)
30–60 min (rolling back)
Session state continuity
Yes (ElastiCache shared)
No (stateless, retries)
No (ephemeral per-task)
Operational complexity
High (2 clusters, ElastiCache HA)
Medium (CloudWatch monitoring)
Low (ECS rolling policy)
Risk of bugs reaching users
Low (atomic switch after validation)
Medium (CloudWatch metrics)
High (bugs deployed progressively)
Observability
Good (pre-switch validation)
Excellent (metrics during rollout)
Fair (metrics post-deployment)
Suitable for stateful auctions
Yes
No
No
Recommendation
For most ad tech platforms on AWS, choose Option 3 (Rolling Restart with ECS Rolling Update) if you're already on ECS. Here's why:
Operational simplicity: No extra infrastructure, no shared ElastiCache, no canary fleet. Use ECS rolling update policy out of the box.
Cost efficiency: Deploy on existing hardware; no 2x overhead like blue-green.
ECS-native: Aligns with container orchestration platform; teams already understand readiness probes and graceful shutdown.
Fast iterations: If you deploy multiple times per day, rolling update completes in under an hour for most fleet sizes.
Use Option 1 (Blue-Green) only if:
Your auctions are long-lived (> 5 seconds) and deeply stateful, requiring session continuity.
You have large server fleets (> 500 tasks) and 50-minute rolling updates are unacceptable.
You can afford the 2x infrastructure cost and have operational capacity to maintain two clusters.
Use Option 2 (Canary) as a complementary validation step before full deployment: run canary on 5% for 10 minutes to catch obvious bugs, then roll out to the rest. Combine with CodeDeploy for automated rollback based on CloudWatch alarms.
Recommended hybrid approach:
Deploy new version to 5 canary tasks (5% traffic via ALB weighted target groups).
Observe CloudWatch metrics for 5 minutes; if CPM drops > 5% or error rate > 1%, roll back.
If canary is stable, use ECS rolling update to deploy to the rest of the fleet (gradually increase min healthy percentage).
Total time: ~60 minutes with safety guardrails; automated rollback via CloudWatch alarms and CodeDeploy.
Capacity & Performance Notes
Assume a 200-task ECS Fargate cluster, each handling 2,000 req/s. Typical auction duration (end-to-end): 150–200 ms.
ALB deregistration delay: Set to 3 × p99 auction duration = 600 ms. This allows the vast majority of auctions to complete (p99 = 200 ms) with headroom. Configure on target group deregistration delay setting.
Concurrent in-flight auctions per task: At 2,000 req/s and 150 ms average latency, each task has ~300 in-flight requests at any moment. Fargate task thread pools should be sized accordingly (e.g., 512 threads for 300 concurrent).
Campaign data warm-up: When a new task starts, it must load campaign data from a database or ElastiCache. Assume 5–10 seconds to load 10,000 active campaigns with targeting rules. Parallel load from ElastiCache reduces this to 1–2 seconds.
DSP connection pre-warming: Opening TCP connections to 20 DSPs (each with 2–3 backend servers) takes ~2 seconds (parallel connection attempts with 100 ms timeout). Recommended: pre-connect on startup via init container or application warmup, not in the critical path.
Blue-Green ElastiCache overhead: For 400k req/s total (200 tasks × 2k req/s), assume 100k session updates/sec to ElastiCache (25% of requests update session). At 1 KB per session update, this is 100 MB/sec throughput. ElastiCache cluster (multi-node) can handle this; ensure replication lag < 10 ms to avoid session loss.