Fault Tolerance & High Availability based on multi Availability zones in AWS
CK 3788 Created at Updated at
10,80500
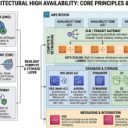
High Availability (HA) on the cloud refers to a system designed to ensure continuous operation and minimize downtime, even in the event of failures or disruptions. Here's how it works:
Redundancy: Critical components like servers, databases, and applications are duplicated across multiple instances. This creates a backup in case one fails.
Load Balancing: Traffic is distributed across multiple instances, ensuring no single point of failure overwhelms any one system.
Automatic Failover: If a component fails, the system automatically routes traffic to a healthy instance, minimizing the impact on users.
Monitoring and Management: Constant monitoring ensures early detection of potential issues, allowing for proactive maintenance and repairs.
Benefits of HA on the cloud:
Increased Uptime: Minimizes downtime, ensuring continuous service availability.
Enhanced Resilience: Protects against hardware failures, software bugs, and network outages.
Data Security: Redundancy ensures data backups and disaster recovery capabilities.
Examples of HA in the cloud:
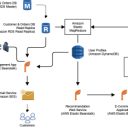
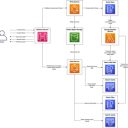
Multi-AZ deployments: Deploying databases and applications across multiple Availability Zones (AZs) in a region, ensuring resilience against local failures.
Cloud load balancers: Distributing traffic across multiple instances, ensuring even distribution of workload.
Auto-scaling: Automatically adjusting the number of instances based on demand, ensuring performance and availability even under peak load.
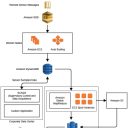
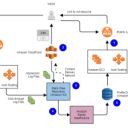
In AWS, most of the higher-level services, such as Amazon Simple Storage Service(S3), Amazon SimpleDB, Amazon Simple Queue Service (SQS), and Amazon Elastic Load Balancing (ELB), have been built with fault tolerance and high availability in mind. Service that provide basic infrastructure, such as Amazon Elastic Compute Cloud (EC2) and Amazon Elastic Block Store (EBS), provide specific features, such as availability zones, elastic IP address, and snapshots, that a fault-tolerant and high available system must take advantage of and use correctly. Just moving a system into the cloud doesn't make it fault-tolerant or highly available.
#
Description
1
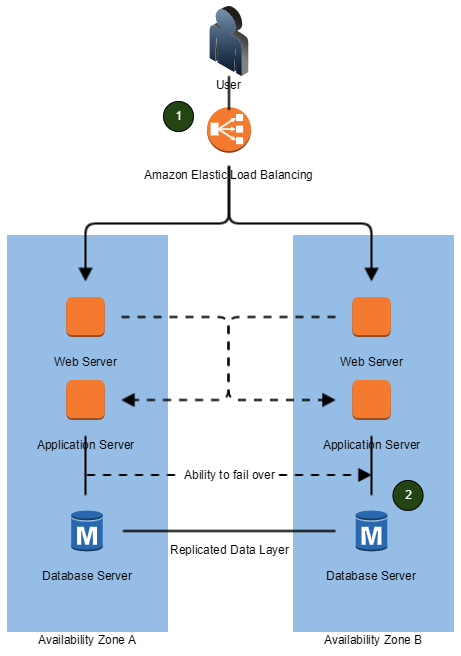
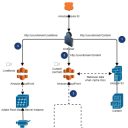
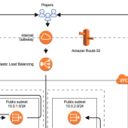
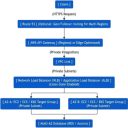
Load Balancing is an effective way to increase the availability of a system. Instances that fail can be replaced seamlessly behind the load balancer while other instances continue to operate. Elastic Load Balancing can be used to balance across instances in multiple availability zones of a region.
2
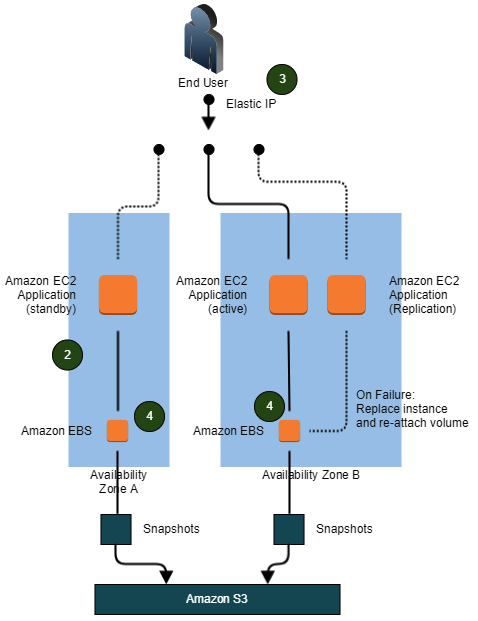
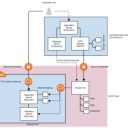
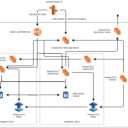
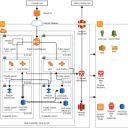
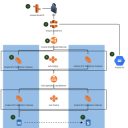
Availability zones (AZs) are distinct geographical locations that are engineered to be insulated from failure in other AZs. By placing Amazon EC2 instances in multiple AZs, an application can be protected from failure at a single location. It is important to run independent application stacks in more than one AZ, either in the same region or in another region, so that if one zone fails, the application in the other zone can continue to run. When you design such a system, you will need a good understanding of zone dependencies.
#
Description
3
Elastic IP addresses are public IP addresses that can be programmatically mapped between instances within a region. They are associated with the AWS account and not with a specific instance or lifetime of an instance.
Elastic IP addresses can be used to work around host or availability zone failure by quickly remapping the address to just started. Reserved instances can help guarantee that such capacity is available in another zone.
4
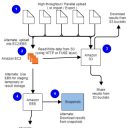
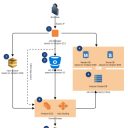
Valuable data should never be stored only on instance storage without proper backups, replication, or the ability to re-create the data. Amazon Elastic Block Store(EBS) offers persistent off-instance storage volumes that are about an order of magnitude more durable than on-instance storage. EBS volumes are automatically replicated within a single availability zone. To increase durability further, point-in-time snapshots can be created to store data on volumes in Amazon S3, which is then replicated to multipleAZs. While EBS volumes are tied to a specifica AZ, snapshots are tied to the region. Using a snapshot, you can create ne EBS volumes in any of the AZs of the same region. This is an effective way to deal with disk failure or other host-level issues, as well as with problems affecting an AZ. Snapshots are incremental, so it is advisable to hold on to recent snapshots.