AWS

Integrating VectorDB stored in S3 with Amazon Bedrock

CK CK 3788 
Created at  
422 0 0

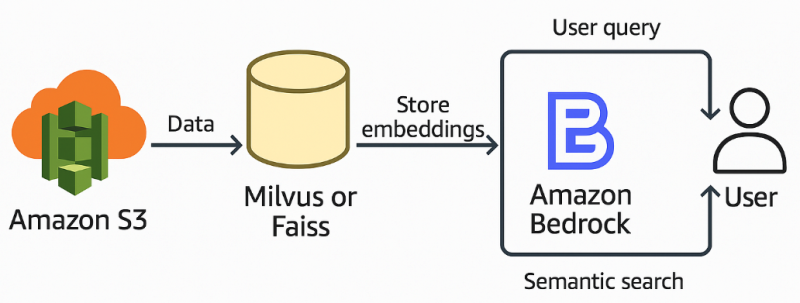
One of the rising area regarding smart search is to use Vector Database stored in S3 with Amazon Bedrock so you can use it for retrieval-augmented generation (RAG) or semantic search.

Amazon Bedrock is a fully managed service that allows developers to access various high-performing foundation models (FMs) from leading AI companies like AI21 Labs, Anthropic, Cohere, Meta, Stability AI, and Amazon itself through a unified API. This simplifies the process of building and scaling generative AI applications. The technical term is Platform as a Service (PaaS), specifically for foundation models.


Understand the components

  • Amazon Bedrock: Managed service for foundation models (like Claude, Jurassic-2, etc.). It allows you to call these models via API without managing the infrastructure. It doesn’t natively store embeddings or vectors.
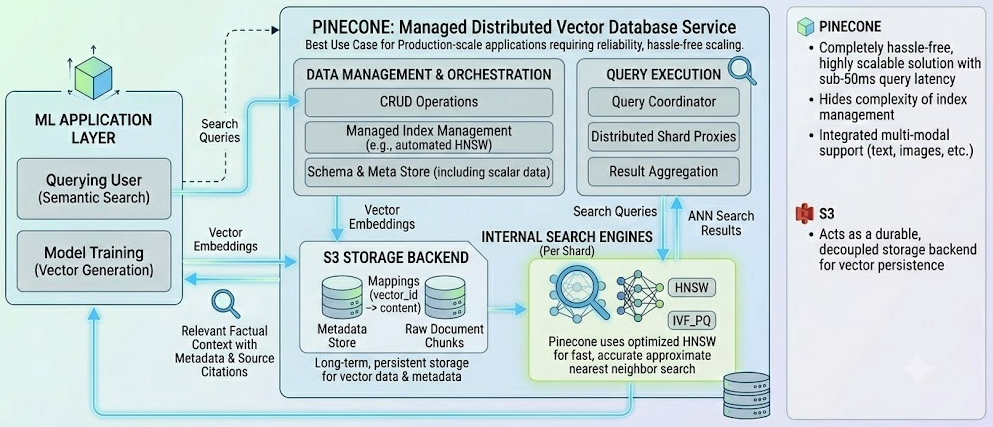
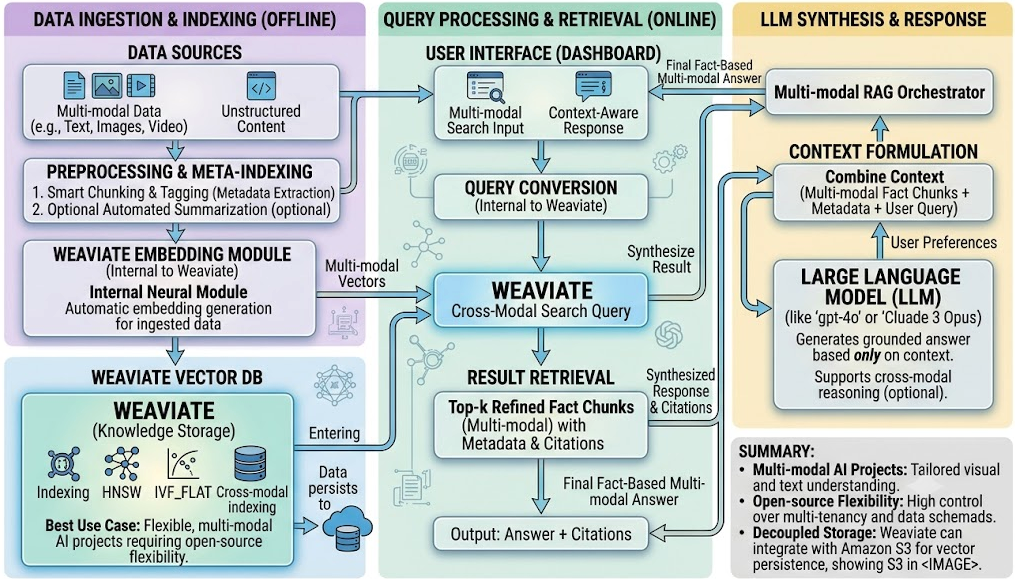
  • Vector Database (VectorDB): Stores embeddings for fast similarity search. Examples: Pinecone, Milvus, Weaviate, or self-hosted using S3 as storage backend.
  • S3: Can hold your raw data or precomputed vectors, but it’s not a query-optimized vector database itself. Typically, you’d use a DB engine that can read/write to S3.

Integrating VectorDB stored in S3 with Amazon Bedrock


Setup your Vector Database backed by S3

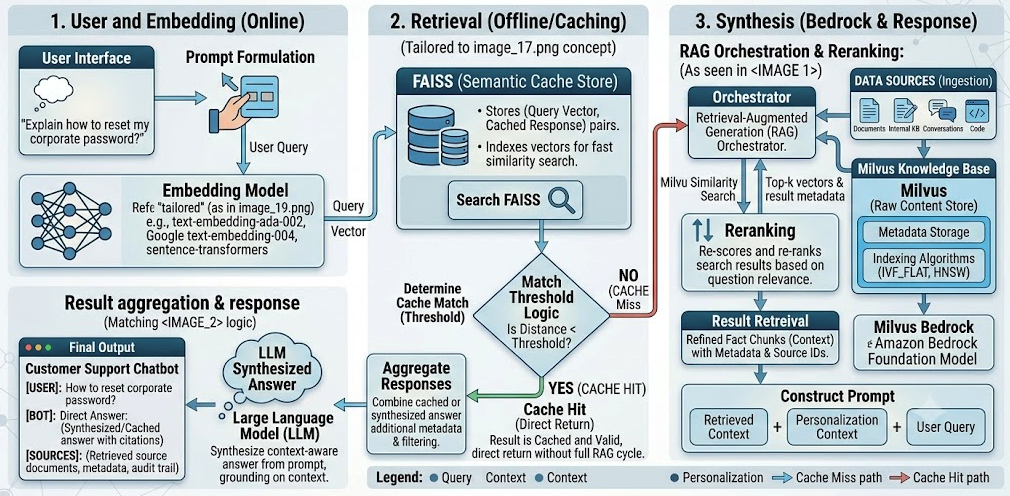
  • Option A: Self-hosted Milvus or FAISS with S3 storage
    • Compute embeddings of your data and store them as vectors.
    • Keep a mapping of vector_id -> original content (can be stored in S3).
    • Use a lightweight wrapper to query vectors by similarity.
  • Option B: Managed vector database (Pinecone, Weaviate)
    • Some managed VectorDBs can ingest data directly from S3.
    • They handle the indexing, scaling, and vector similarity queries.


Generate embeddings

Since Bedrock models don’t generate embeddings directly (unless the model supports it), you can:

  1. Use Amazon SageMaker or OpenAI embeddings API to compute embeddings for your S3 content.
  2. Store embeddings in your VectorDB.


Integrate with Bedrock (for RAG)

Workflow example:

  1. User query → Embedding
    • Use the same embedding model you used for your VectorDB to convert the query into a vector.
  2. Vector similarity search
    • Query your VectorDB for top-k relevant vectors.
    • Retrieve corresponding content from S3.
  3. Feed content to Bedrock model
    • Combine the retrieved documents into a prompt (RAG).
    • Call the Bedrock model API to generate the answer.


# Pseudo-code
query_embedding = embed_model.encode("User question")
top_docs = vector_db.similarity_search(query_embedding, k=5)
context = "\n".join([doc['content'] for doc in top_docs])
response = bedrock_client.generate(prompt=f"Answer using context:\n{context}\nQuestion: {user_query}")


Practical considerations

  • VectorDB on S3: If using S3 as the storage backend, you must have an indexing layer (like FAISS or Milvus). S3 alone is too slow for real-time vector search.
  • Latency: Bedrock API + VectorDB query may introduce noticeable latency if your dataset is large; consider caching frequently queried vectors.
  • Security: Ensure S3 bucket and Bedrock API calls have proper IAM permissions.
  • Batching: Precompute embeddings for S3 data to reduce runtime costs.


FAISS vs Pinecone vs Weaviate

FeatureFAISSPineconeWeaviate
DeploymentSelf-hostedFully managed cloud serviceSelf-hosted / Managed
PerformanceHigh-speed ANN searchSub-50ms query latencyFast query speeds
ScalabilityManual scalingAuto-scaling with high availabilityHorizontal scaling with multi-tenancy
CostFree (infrastructure costs apply)Usage-based pricing; potentially higher TCOFree (self-hosted); managed services have costs
Best Use CaseCustom, high-control environmentsProduction-scale applications requiring reliabilityFlexible, multi-modal AI projects


Recommendation

  • Choose FAISS if you require complete control over your vector search implementation and have the resources to manage infrastructure.

    Integrating VectorDB stored in S3 with Amazon Bedrock

  • Choose Pinecone for a hassle-free, scalable solution with robust performance and minimal operational overhead, suitable for enterprise-grade applications.

    Integrating VectorDB stored in S3 with Amazon Bedrock

  • Choose Weaviate if your project involves multi-modal data and you need an open-source solution with optional managed services for flexibility.

    Integrating VectorDB stored in S3 with Amazon Bedrock

For integration with Amazon S3, all three options can be configured to store vectors externally. However, Pinecone's managed service may offer more straightforward integration with cloud-native architectures.

Tags Amazon Bedrock Amazon S3 Bedrock FAISS Milvus Pinecone RAG Retrieval-Augmented Generation Semantic Search Vector DB Vector Database Weaviate 페이스 Facebook X
Comments 0
Similar posts
  1. How to overcome the prompt size limit when you use Claude via Bedrock - Chunking / Splitting the Input
    494
  2. Milvus and LLM Integration - Very Smart Approach!
    294
  3. When you need AWS_ACCESS_KEY_ID and AWS_SECRET_ACCESS_KEY for Amazon Bedrock
    532
  4. When you face 504 Gateway Timeout while you wait a response from Bedrock in Fast API
    532
  5. Default Timeout for Amazon Bedrock invoke_model
    732
  6. Architecting ML/LLM Ad Targeting with Kafka, Flink, FAISS, and Milvus
    279
  7. The Core of Vector Databases: Embeddings and LLM Dependency
    253
  8. Your Blueprint for an LLM & Vector DB Insurance Product Q&A
    256
  9. Building my own ChatGPT based on SageMaker and Milvus that is specialized to Shopping Mall
    264
  10. Why Reranking is Crucial for RAG and Agentic AI Systems?
    261
  11. Demystifying FAISS: Your Guide to ANN(Approximate Nearest Neighbor) Search
    314
  12. Technical Hierarchy of AI Agents
    808
  13. Understanding Amazon Bedrock Agent for AI-based ChatBot
    642
  14. AWS Multi-Agent Collaboration Approach: Fully Managed vs. Code-based Implementation

    270
  15. Vector Database Integration on Fully Managed Multi-Agent Environment
    293
  16. Embeddings on the Lakehouse: What Snowflake and Databricks Actually Do (and Don't)
    280
  17. Designing a Data Curation System Around a Vector Database
    215
  18. What is RedisVL?
    105
  19. Understanding Elasticsearch from Installation to Trouble Shooting
    909
  20. Getting Started with FAISS: A CentOS 7 Installation Guide
    279
  21. Milvus & FAISS: Decoding Their ML Synergy
    276
  22. Recommended Vector DB Structure for Amazon Bedrock Integration
    388
  23. Deep Dive into Vector Databases: Understanding Collections (Not Tables) and Embeddings
    230
  24. Image Embeddings for Vector Databases
    241
  25. Vector Databases: From Embeddings to Application
    310
  26. Scaling Vector Search: How to Architect FAISS on AWS EKS and ECS
    158
  27. Time series processing architecture in AWS
    10,557
  28. File synchronization service architecture in AWS
    10,375
  29. Content Distribution for VOD streaming services in AWS
    10,354
  30. Architecting for Resilience: AWS High Availability Components Including API Gateway
    133
  1. Architectural Diagram Gallery for Amazon MSK
    497
  2. Architectural Diagram Gallary for Amazon Kinesis
    517
  3. Real-time Data Streaming Solutions - Kafka vs. Kinesis Comparison
    847
  4. Building a Video Content Recommendation System with Amazon SageMaker
    521
  5. The Immense Scale and Management of Exabyte Data with AWS
    504
  6. How to change your AWS Credential Region in CLI?
    749
  7. Default Timeout for Amazon Bedrock invoke_model
    732
  8. When you face 504 Timeout Errors by Amazon ALB
    1,467
  9. When you face 504 Gateway Timeout while you wait a response from Bedrock in Fast API
    532
  10. How to overcome the prompt size limit when you use Claude via Bedrock - Chunking / Splitting the Input
    494
  11. When you need AWS_ACCESS_KEY_ID and AWS_SECRET_ACCESS_KEY for Amazon Bedrock
    532
  12. How Netflix Runs Recommendations for Hundreds of Millions of Users Using Amazon SageMaker & Metaflow
    171
  13. Why Amazon VPC satisfies with PCI-DSS and SOC 2 Type on Fintech Industry?
    642
  14. You shouldn't use Amazon CloudFront distribution as an origin
    631
  15. Amagi CLOUDPORT Architecture based on AWS for FAST for channel playout on AWS
    1,315
  16. Creating a serverless Apache Kafka publisher using AWS Lambda
    562
  17. AWS System Design Example - Instagram Architecture
    1,916
  18. A Python script to create an EC2 Spot instance using boto3
    1,598
  19. A Python/PHP code to deregister anormalous instaces in Amazon ECS
    1,855
  20. Where to get AWS API Key at AWS Management Console?
    1,063
  21. Understanding Amazon Bedrock Agent for AI-based ChatBot
    642
  22. Media sharing service architecture in AWS
    10,364
  23. Enterprise Data Lake Architecture based on AWS
    10,403
  24. "502 Bad Gateway" Error easy to happen at the combination of nginx and node.js in AWS Elastic Beanstalk
    10,485
  25. How to Set Up and Deploy Containerized Applications with AWS ECS
    10,672
Recently updated
  1. Why 100% SEO Guarantees Better User Engagement and How to Achieve It in Your Service
    27
  2. Why SPF and DKIM Are Essential for Linux Email Servers?
    24
  3. How do I create animated background for Google Meet?
    19,731
  4. MaxMind GeoLite2 vs. DB-IP Lite vs. ip-api.com: Choosing the Right Free IP Geolocation Solution
    217
  5. Meet Valkey: Why Redis Changed Its License, Why Valkey is Better, and How to Use It as a Drop-in Replacement
    86
  6. How Rogue Web Scrapers Are Stealing My Content and Destroying My Server
    153
  7. Array of arguments passed to script in PHP
    85
  8. Invalid Auction Storms in Ad Tech
    93
  9. Building MRC-Compliant Instrumentation in Ad Tech: Implementation Steps and Key Challenges
    198
  10. The Two Clocks of Ad Server Architecture
    63
  11. Frequency Cap Architecture Overview
    509
  12. Collecting Proof-of-Play from 100,000 Screens
    141
  13. Vector Search in Relational Databases (RDBs): Trends & Usage Environments
    280
  14. What is RedisVL?
    105
  15. Designing a Skill Registry Architecture: Minimize Token Usage and Maximize AI Performance
    224
  16. TPU & GPU Cluster Management Tools
    234
  17. The Concept of Scaffolding in AI Agents
    222
  18. Beyond Static Pipelines: Architecting LLM Multi-Agent Systems for Autonomous Workflow Orchestration
    576
  19. AI-DLC vs. AI-SDLC: Model-Centric vs. System-Centric AI Development
    253
  20. Fine-Tuning Open-Weight LLMs: Training, Licensing, and Deploying Custom Models with Ollama
    328
  21. Inside the Next-Generation Streaming Architecture: Ultra-Low Latency, SGAI, and AI Codecs
    197
  22. Machine Learning: Training vs. Ranking
    213
  23. The Continuous Learning Machine: Designing a Loop That Actually Turns
    217
  24. The Next-Gen Low-Latency Standards: LL-HLS & MoQ
    189
  25. Designing a Data Curation System Around a Vector Database
    215
  26. Extracting Context from Live Video: The Architecture Got Simpler When We Stopped Building Features
    229
  27. The New Ad Stack Behind Live Sports Streaming: Inside SGAI, EABN, and the Standards Race to Fix Live Monetization
    649
  28. Designing MLOps Architectures to Handle Seasonal Data Drift in EV Fleet Models
    185
  29. From 15 to 40+ FPS: Accelerating PyTorch Object Detection on Automotive ECUs
    207
  30. Understanding Data Lineage
    252