| When you use Claude via Bedrock: it has a prompt size limit, typically around 5,000 bytes for some models (Claude 1/2). Exceeding that triggers errors. Here’s how you can handle it: 1. Chunking / Splitting the InputBreak your large prompt into smaller pieces that are each under the byte limit: - Split text by logical units: paragraphs, sections, or bullets.
- Feed each chunk sequentially.
- Optionally, maintain context by sending a brief summary of previous chunks to Claude.
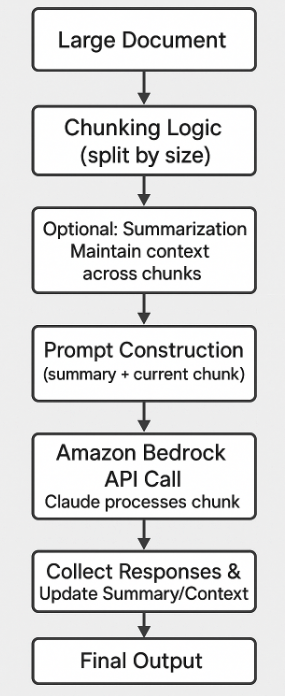
Example: Chunk 1 -> Processed by Claude -> Get summary
Chunk 2 -> Prepend summary from Chunk 1 -> Processed by Claude
2. Use a Memory / State Management Approach- Instead of sending the entire history each time, keep track of the context separately in your application.
- Send only:
- A short summary of prior conversation
- The current user input
- This reduces prompt size drastically.
3. Compress or Encode the Input- Convert verbose content into concise representations:
- Replace repeated patterns with shorthand.
- Remove unnecessary formatting, stop words, or extra whitespace.
- Optionally, you can encode tables or structured data in JSON for compactness.
4. External Reference (Recommended for Very Large Data)- Store the bulk of your data outside the prompt (S3, database, vector store).
- Only send a pointer, summary, or relevant snippet to Claude.
- For example, integrate Vector DB + Bedrock:
- Query relevant info from the vector store.
- Send only top-K relevant chunks to Claude.
- This avoids exceeding the prompt limit entirely.
5. Use a More Capable Model- If available, switch to Claude 3 (or higher), which may have higher token limits.
- Check Bedrock’s documentation for updated byte/token limits.
💡 Tip: Claude models count bytes roughly as UTF-8 characters. If your text has non-ASCII characters (like emojis or non-English text), 1 character may take more than 1 byte, so the actual character limit will be smaller than 5,000. Here’s a Python example for handling long prompts with Claude on Bedrock by splitting and summarizing chunks. This keeps the prompt under the 5,000-byte limit. import boto3
# Initialize Bedrock client
client = boto3.client("bedrock-runtime", region_name="us-east-1")
MODEL_ID = "anthropic.claude-v2" # Change to your Claude model
# Function to estimate byte size of a string def byte_size(text: str) -> int:
return len(text.encode("utf-8"))
# Function to split text into chunks under max_bytes def chunk_text(text: str, max_bytes: int = 4500):
chunks = []
current = ""
for line in text.split("\n"):
if byte_size(current + line + "\n") > max_bytes:
if current:
chunks.append(current.strip())
current = line + "\n"
else:
current += line + "\n"
if current:
chunks.append(current.strip())
return chunks
# Example long text
long_text = """Your very long text here ...""" # Could be thousands of lines
# Split the text
chunks = chunk_text(long_text)
# Optional: maintain a running summary for context
summary = ""
for i, chunk in enumerate(chunks, 1):
# Combine previous summary with current chunk
prompt = f"Summary of previous chunks:\n{summary}\n\nCurrent chunk:\n{chunk}"
response = client.invoke_model(
modelId=MODEL_ID,
body={
"inputText": prompt
}
)
# Extract Claude's output
output_text = response["body"].read().decode("utf-8")
# Update summary for next chunk (you can choose to summarize or just append)
summary += "\n" + output_text
print(f"Processed chunk {i}/{len(chunks)}")
print(output_text)
print("="*50)
How This Works:chunk_text(): Splits your text into pieces small enough to fit Claude’s byte limit.- Running summary: Keeps context between chunks without resending everything.
- Sequential processing: Each chunk is fed separately, avoiding the 5,000-byte error.
- Scalable: Works even for very large documents or logs.
For very large documents, it’s much more efficient to use a vector database (like FAISS, Milvus, or Pinecone) so Claude only sees relevant chunks instead of the entire text. Here’s an example: 1. Split and embed your documentfrom sentence_transformers import SentenceTransformer
import faiss
import numpy as np
# Load embedding model
embed_model = SentenceTransformer('all-MiniLM-L6-v2')
# Your large document
long_text = """Your very long document here..."""
# Split into paragraphs (or smaller chunks)
chunks = long_text.split("\n\n")
# Generate embeddings
embeddings = [embed_model.encode(chunk) for chunk in chunks]
embeddings = np.array(embeddings).astype('float32')
# Build FAISS index
dimension = embeddings.shape[1]
index = faiss.IndexFlatL2(dimension)
index.add(embeddings)
2. Query relevant chunks using your promptquery = "Explain the key insights about X from the document."
# Embed the query
query_vector = embed_model.encode(query).astype('float32')
# Search top 3 most relevant chunks
k = 3
distances, indices = index.search(np.array([query_vector]), k)
# Retrieve relevant chunks
relevant_chunks = [chunks[i] for i in indices[0]]
context_text = "\n\n".join(relevant_chunks)
3. Send only relevant chunks to Claudeimport boto3
client = boto3.client("bedrock-runtime", region_name="us-east-1")
MODEL_ID = "anthropic.claude-v2"
prompt = f"Use the following document excerpts to answer the question:\n\n{context_text}\n\nQuestion: {query}"
response = client.invoke_model(
modelId=MODEL_ID,
body={"inputText": prompt}
)
output_text = response["body"].read().decode("utf-8")
print(output_text)
Benefits of This Approach:- Never exceed Claude’s prompt limit — you only send top-K relevant chunks.
- Scales to huge documents — gigabytes of text can be indexed in a vector DB.
- Faster and cheaper — Claude processes less text.
- Works with any vector DB (FAISS, Milvus, Pinecone, Weaviate, etc.) — you can even store your data in S3.
|