| This article outlines a practical approach to building a video recommendation system using Amazon SageMaker, leveraging video viewership data and content metadata. We'll cover data preparation, model selection, training, deployment, and inference. What is the main feature of Amazon SageMaker?Amazon SageMaker's main feature is providing a fully managed service that simplifies and accelerates the entire machine learning lifecycle, enabling data scientists and developers to build, train, and deploy high-quality models quickly and efficiently without the burden of managing underlying infrastructure. How do we build a system for recommending video content with Amazon SageMaker?This guide outlines building a video content recommendation system with Amazon SageMaker, starting with critical data preparation that leverages viewership and content metadata, including steps like cleaning, feature engineering, and dataset splitting. It then discusses various model selections, emphasizing collaborative filtering using Matrix Factorization (ALS) implemented via SageMaker's Factorization Machines for training, deployment, and inference. The SageMaker workflow involves configuring the estimator, setting hyperparameters, training the model, deploying it to an endpoint for real-time predictions, and rigorously evaluating its performance using ranking and prediction accuracy metrics. Finally, it addresses deployment considerations, scaling, inference optimization, and A/B testing for continuous improvement of the recommendation engine. 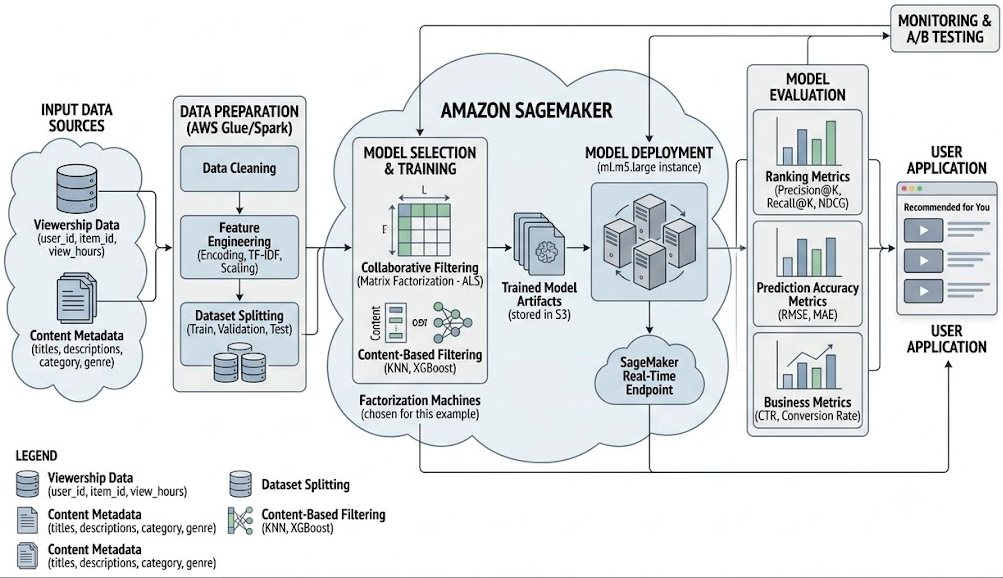
Data Preparation1) Our recommendation system relies on two key datasets- Viewership Data: Records the number of view hours for each video content. This data is the core signal for user preference and popularity. It should include user IDs, content IDs, and view hours.
- Content Metadata: Provides descriptive information about each video. Fields include category, title, description, duration, and genre. This enriches the recommendation process by enabling similarity-based recommendations.
2) Data Preprocessing Steps1. Data Cleaning: Handle missing values, inconsistencies, and outliers in both datasets. For example, impute missing durations with the median value or remove videos with excessively high view hours (indicating potential data errors).
2. Feature Engineering: Create meaningful features from the raw data. Examples include: - Categorical Encoding: Convert categorical features (category, genre) into numerical representations using techniques like one-hot encoding or label encoding.
- Text Processing: Use techniques like TF-IDF or word embeddings (e.g., using a pre-trained model like BERT and fine-tuning it for the content descriptions) to convert video titles and descriptions into numerical vectors that capture their semantic meaning.
- Normalization/Scaling: Normalize numerical features (duration, view hours) to a similar scale to prevent features with larger values from dominating the model. StandardScaler or MinMaxScaler are common choices.
3. Data Transformation: Transform data into the format required by the chosen SageMaker algorithm. For collaborative filtering models, a matrix of user-item interactions (view hours) is typical. Content-based models will require a feature vector for each video.
4. Dataset Splitting: Split the data into training, validation, and testing sets. The training set is used to train the model, the validation set to tune hyperparameters, and the testing set to evaluate the model's performance on unseen data. Model SelectionSeveral machine learning algorithms are suitable for video recommendation: - Collaborative Filtering: Recommends videos based on the viewing patterns of similar users. Common algorithms include:
- Matrix Factorization (ALS): Decomposes the user-item interaction matrix into latent factors representing user and item characteristics. The SageMaker implementation of factorization machines can be used.
- Item-Based Collaborative Filtering: Identifies videos similar to those a user has previously viewed.
- Content-Based Filtering: Recommends videos similar to those a user has liked in the past, based on video metadata (category, genre, description). Suitable algorithms include:
- K-Nearest Neighbors (KNN): Finds the k most similar videos based on a distance metric applied to their feature vectors.
- Classification/Regression Models: Train a model to predict a user's rating or likelihood of watching a video based on its features. Algorithms include Logistic Regression, Support Vector Machines (SVMs), and Gradient Boosting Machines (e.g., XGBoost, LightGBM).
- Hybrid Approach: Combines collaborative filtering and content-based filtering to leverage the strengths of both. For example, using content-based filtering to address the cold-start problem (recommending videos to new users with no viewing history) and collaborative filtering for users with sufficient history.
For this example, we will focus on the Matrix Factorization (ALS) approach, leveraging SageMaker's Factorization Machines algorithm. SageMaker Implementation: Matrix Factorization (ALS)This provides a simplified example. Adapt the placeholders with your S3 bucket and data locations. import boto3
import sagemaker
from sagemaker import get_execution_role
from sagemaker.inputs import TrainingInput
from sagemaker.algorithm import AlgorithmEstimator
from sagemaker.serializers import CSVSerializer
# 1. Setup
role = get_execution_role()
sess = sagemaker.Session()
bucket = 'your-s3-bucket-name' # Replace with your bucket
prefix = 'sagemaker/fm-video-recommendation' # Define a prefix for your S3 data
# Define paths to your training, validation, and test data in S3. Assume CSV format.
train_data_uri = f's3://{bucket}/{prefix}/train.csv'
validation_data_uri = f's3://{bucket}/{prefix}/validation.csv'
test_data_uri = f's3://{bucket}/{prefix}/test.csv'
# 2. Prepare Data (Assumes data is already preprocessed and in CSV format)
# In a real-world scenario, you would use a data processing framework like Apache Spark
# or AWS Glue to perform the data preparation steps described above. Then, upload
# the CSV files to your S3 bucket.
#
# Example train.csv format (assuming user_id, item_id, view_hours):
# user_id,item_id,view_hours
# 1,101,5
# 1,102,2
# 2,101,3
# ...
# 3. Configure the Factorization Machines Estimator
# Choose the appropriate instance type based on your dataset size.
fm = AlgorithmEstimator(
algorithm_name="factorization-machines",
role=role,
instance_count=1,
instance_type='ml.m5.large', # Or a more powerful instance like ml.m5.xlarge
predictor_cls=sagemaker.predictor.Predictor,
sagemaker_session=sess,
output_path=f's3://{bucket}/{prefix}/output',
base_job_name='fm-video-recommendation'
)
# 4. Set Hyperparameters
fm.set_hyperparameters(
feature_dim= <Number of Features>, # set number of features, including encoded data. For example, a one-hot encoded 10 category feature would be +10.
factors = 64, # set number of factors
epochs=20, # Number of training epochs
num_calibration_samples=10000, # Required for probabilistic predictions
mini_batch_size=1000
)
# 5. Define Data Channels
train_input = TrainingInput(
s3_data=train_data_uri,
content_type='text/csv',
distribution_type='FullyReplicated',
s3_data_type='S3Prefix'
)
validation_input = TrainingInput(
s3_data=validation_data_uri,
content_type='text/csv',
distribution_type='FullyReplicated',
s3_data_type='S3Prefix'
)
data_channels = {'train': train_input, 'validation': validation_input}
# 6. Train the Model
fm.fit(inputs=data_channels, wait=True)
# 7. Deploy the Model
predictor = fm.deploy(
initial_instance_count=1,
instance_type='ml.m5.large',
serializer=CSVSerializer()
)
# 8. Make Predictions
# Prepare a test dataset in CSV format
test_data = "user_id,item_id,feature1,feature2,...\n1,105,0.2,0.8,...\n2,108,0.5,0.3,..." # Replace with your actual test data
# Invoke the endpoint with the test data
response = predictor.predict(test_data)
# Parse the predictions
predictions = [float(r) for r in response.decode('utf-8').split(',')]
print(f"Predictions: {predictions}") #Predictions will be the estimated rating for each user-item pair. Higher scores indicate stronger recommendations.
# 9. Clean Up (Important to avoid incurring unnecessary costs)
# predictor.delete_endpoint() #Comment out for now to check the result.
Explanation:
1. Setup: Initializes SageMaker session, role, and defines S3 bucket and prefix for data storage.
2. Prepare Data: This highlights the critical data preparation stage. It assumes that the data is already preprocessed and uploaded to S3. The example format is specified as CSV with user_id, item_id, and view_hours. A robust solution would include a separate data processing script (e.g., using Spark or Glue).
3. Configure Estimator: Creates a SageMaker AlgorithmEstimator object for the Factorization Machines algorithm. It specifies the instance type, role, output path, and base job name.
4. Set Hyperparameters: Sets key hyperparameters for the FM algorithm. feature_dim should be set to the total number of features used for the model. factors determines the dimensionality of the latent factors. The optimal hyperparameters are data-dependent and may need to be tuned.
5. Define Data Channels: Defines the input data channels for training and validation data. TrainingInput objects specify the S3 locations, content type, and data distribution.
6. Train the Model: Starts the training job using the fit method. wait=True ensures that the code waits for the training job to complete before proceeding.
7. Deploy the Model: Deploys the trained model to a SageMaker endpoint for inference. Specifies the instance count and instance type.
8. Make Predictions: Sends a sample request to the endpoint and prints the predictions. The example provides a placeholder for the test data. Remember to replace it with your actual test data in CSV format. The predictions will be the estimated rating or interaction score for each user-item pair.
9. Clean Up: Delete the endpoint to avoid incurring unwanted costs. Leaving it running will continue to charge you. Important Notes: - Data Format: The code assumes your data is in CSV format. Adjust the
content_type parameter in TrainingInput if you're using a different format. Ensure column order is correct when testing. - Feature Engineering: The effectiveness of the recommendation system heavily relies on the quality of the features used. Invest time in feature engineering to extract meaningful signals from the data. The example uses
feature_dim but doesn't provide specifics on feature creation. The python implementation is needed here. - Hyperparameter Tuning: The provided hyperparameters are just starting points. Use SageMaker's hyperparameter tuning capabilities to find the optimal hyperparameter values for your dataset.
- Error Handling: Include error handling (e.g., try-except blocks) to gracefully handle potential errors during data loading, training, and deployment.
- Monitoring: Monitor the performance of your deployed model to detect and address issues such as data drift or model degradation. SageMaker provides monitoring capabilities to track key metrics and trigger alerts when necessary.
- Probabilistic Model: Factorization Machines are also useful to build classification or regressor models to assess how likely a certain category and genre are watched by a particular user.
EvaluationEvaluate the performance of your recommendation system using appropriate metrics: - Ranking Metrics:
- Precision@K: The proportion of relevant items (videos the user watched or liked) among the top K recommended items.
- Recall@K: The proportion of relevant items that are included in the top K recommended items.
- Mean Average Precision (MAP): The average precision across all users and queries.
- Normalized Discounted Cumulative Gain (NDCG): Measures the ranking quality, giving more weight to relevant items ranked higher.
- Prediction Accuracy Metrics:
- Root Mean Squared Error (RMSE): Measures the difference between predicted and actual ratings (if available).
- Mean Absolute Error (MAE): Another measure of the difference between predicted and actual ratings.
- Business Metrics:
- Click-Through Rate (CTR): The percentage of users who click on a recommended video.
- Conversion Rate: The percentage of users who complete a desired action (e.g., watch a video for a certain duration, subscribe to a channel) after being recommended a video.
Use the test dataset to calculate these metrics and compare the performance of different models or hyperparameter settings. SageMaker provides tools for model evaluation, including the ability to generate reports and visualizations. Deployment and ScalingOnce you have a satisfactory model, deploy it to a SageMaker endpoint for real-time inference. - Endpoint Configuration: Choose the appropriate instance type and number of instances based on your traffic volume and latency requirements. Consider using auto-scaling to automatically adjust the number of instances based on demand.
- Inference Optimization: Optimize the model for inference to reduce latency and improve throughput. Techniques include:
- Model Compilation: Use SageMaker Neo to compile your model for a specific hardware platform.
- Batch Inference: Process multiple requests in a single batch to improve throughput.
- Caching: Cache frequently requested recommendations to reduce latency.
- A/B Testing: Conduct A/B tests to compare the performance of different recommendation strategies in a live environment.
This comprehensive guide provides a roadmap for building a video recommendation system with Amazon SageMaker. Remember to adapt the code and techniques to your specific data and requirements. Continuously iterate on your model and deployment strategy to improve performance and meet the evolving needs of your users. |