Real-time Data Streaming Solutions - Kafka vs. Kinesis Comparison
CK 3788 Created at Updated at
84700
Both Apache Kafka and Amazon Kinesis are powerful, highly scalable distributed streaming platforms designed to handle high-throughput, low-latency real-time data feeds. They serve as central nervous systems for data, enabling the collection, processing, and analysis of vast amounts of event data as it's generated. Despite sharing a common core purpose, there are significant differences in their architectural approach, management model, and ecosystem, which influence the optimal choice between them.
Key Similarities
Real-time Data Processing: Both are designed for ingesting, processing, and storing streams of data in real-time.
High Throughput & Low Latency: Capable of handling millions of events per second with minimal delay.
Durability & Fault Tolerance: Messages are stored durably, and the systems are designed to withstand failures without data loss.
Publish-Subscribe Model: Producers publish data to topics/streams, and consumers subscribe to these to read data.
Scalability: Both are horizontally scalable to accommodate growing data volumes.
Key Differences
Feature
Apache Kafka
Amazon Kinesis
Management
Self-managed: Requires significant operational effort for deployment, scaling, monitoring, and maintenance. Can be run on-premise or any cloud.
Fully Managed (AWS): AWS handles all infrastructure, scaling, patching, and maintenance. Serverless approach.
Deployment
On-premise, any cloud (EC2, Kubernetes), hybrid. Cloud-agnostic.
AWS Cloud only. Tightly integrated with other AWS services.
Architecture
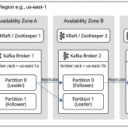
Clusters of brokers, topics with partitions, ZooKeeper (or Kraft). Open-source project.
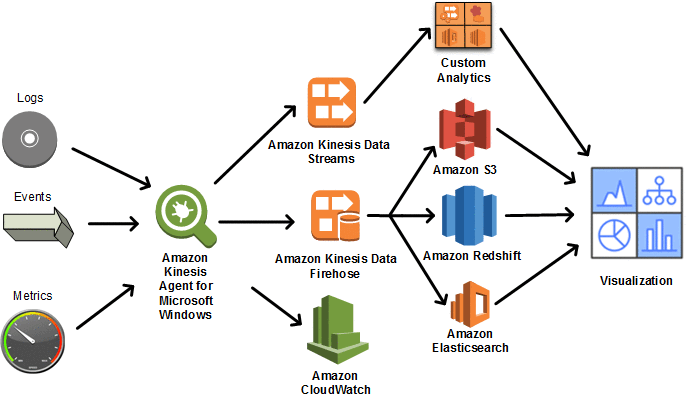
Managed service with different components: Kinesis Data Streams (shards), Kinesis Firehose, Kinesis Video Streams, Kinesis Data Analytics.
Integrates seamlessly with other AWS services (Lambda, S3, Redshift, DynamoDB, CloudWatch, etc.).
Scalability
Scales by adding more broker nodes and adjusting partitions. Requires manual scaling decisions (or automation scripts).
Kinesis Data Streams scales by adjusting shard count (can be automated). Firehose scales automatically based on data volume.
Data Retention
Configurable: typically days to weeks, but can be extended to months or years depending on storage.
Kinesis Data Streams: 24 hours to 7 days. Firehose delivers to S3/Redshift for long-term storage.
Pricing Model
Infrastructure + Operational Cost: Free software, but you pay for servers, storage, networking, and significant operational overhead.
Pay-per-use: Billed based on data ingested, data egress, and provisioned capacity (shards for Data Streams) or throughput (Firehose). No upfront infrastructure cost.
Complexity
Higher operational complexity, steep learning curve for advanced features and optimization.
Simpler to get started, less operational burden. Complexity often shifts to managing AWS IAM roles and integrations.
Flexibility
High flexibility, full control over configuration and underlying infrastructure.
Less flexibility, tied to AWS service limits and configurations.
When to Use Apache Kafka
Kafka is an excellent choice for organizations that:
Require full control and customization: When you need fine-grained control over your streaming infrastructure, configurations, and the underlying hardware.
Operate a multi-cloud or hybrid-cloud environment: Kafka is cloud-agnostic and can run anywhere, making it suitable for environments spanning multiple cloud providers or on-premises data centers.
Have significant operational expertise: If your team has the resources and skills to deploy, manage, monitor, and scale a complex distributed system.
Need very long-term data retention: While Kinesis Data Streams has a limit, Kafka's retention is only limited by your storage capacity.
Are building a large-scale, enterprise-grade data platform: Kafka is often the backbone for data lakes, event sourcing architectures, and real-time analytics platforms across various applications.
Utilize a rich open-source ecosystem: If you plan to leverage tools like Kafka Connect, Kafka Streams, or other open-source projects that integrate well with Kafka.
Are cost-sensitive at scale with dedicated resources: For very high volumes, if managed efficiently, the total cost of ownership for self-managed Kafka might be lower than Kinesis in some scenarios, provided the operational costs are well-managed.
Example Use Cases: Event sourcing, log aggregation across diverse systems, real-time fraud detection, microservices communication backbone, IoT data pipelines, stream processing with Kafka Streams.
When to Use Amazon Kinesis
Kinesis is ideal for organizations that:
Are heavily invested in the AWS ecosystem: If your existing infrastructure and applications are primarily on AWS, Kinesis offers seamless integration with other AWS services.
Prioritize ease of management and serverless operations: When you want to offload operational burdens to AWS and focus purely on application logic and data processing.
Need to get started quickly with real-time streaming: Kinesis allows for rapid deployment and scaling without needing to provision or manage servers.
Have fluctuating or unpredictable workloads: Kinesis Data Firehose, in particular, automatically scales to handle varying data ingestion rates without manual intervention.
Are building serverless architectures: Kinesis integrates well with AWS Lambda, enabling event-driven processing without managing any servers.
Have limited operational staff or expertise in distributed systems: Kinesis significantly reduces the overhead associated with managing a streaming platform.
Prefer a pay-per-use pricing model: You only pay for what you use, without upfront infrastructure costs, making it cost-effective for many scenarios, especially if usage is spiky or uncertain.
Example Use Cases: Real-time dashboards, ingesting IoT sensor data into AWS, streaming application logs to S3/Redshift for analysis, real-time analytics with Kinesis Data Analytics, building serverless data pipelines on AWS.
Amazon MSK (Managed Streaming for Kafka)
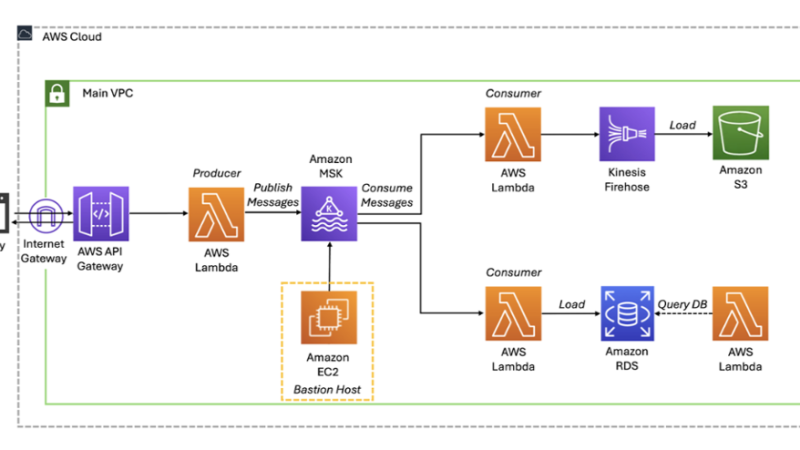
Amazon MSK is a fully managed service from AWS that makes it easy to build and run applications that use Apache Kafka. It is compatible with Apache Kafka APIs.
Nature: A fully managed AWS service based on Apache Kafka.
Management: AWS manages the operational heavy lifting. This includes provisioning brokers, handling patching, applying security updates, monitoring cluster health, and automatically replacing unhealthy brokers. Users focus on building their streaming applications.
Cost: A pay-as-you-go service based on broker instance hours, storage, and data transfer. It eliminates the capital expenditure and operational costs associated with self-managing Kafka.
Control: AWS handles the infrastructure and operational control. Users still manage Kafka-specific aspects like topics, producers, consumers, and client applications, while also having some control over cluster configuration (e.g., Kafka version, broker type).
Scalability: Supports managed scaling, allowing users to easily adjust the number and type of brokers in their cluster through the AWS console or API. MSK Serverless further abstracts scaling.
Integration: Deeply integrated with other AWS services like IAM for access control, CloudWatch for monitoring, VPC for network isolation, and AWS Glue Schema Registry for schema management.
Key Differences between Apache Kafka vs Amazon MSK
Feature
Apache Kafka (Self-managed)
Amazon MSK
Management Burden
High: Users manage all aspects (provisioning, patching, ops)
Low: AWS manages infrastructure, patching, and operational tasks
While both Amazon MSK and Amazon Kinesis are streaming data services on AWS, they serve different primary use cases and are built on different underlying technologies.
Amazon MSK (Managed Streaming for Kafka)
Core Technology: Based on Apache Kafka, an open-source distributed streaming platform.
API/Ecosystem: Offers native compatibility with the Apache Kafka API. This means existing Kafka clients, producers, consumers, and tools (like Kafka Streams, Kafka Connect) can be used with MSK with minimal or no code changes.
Target Audience: Ideal for users who want to leverage the Apache Kafka ecosystem, migrate existing Kafka workloads to AWS, or build new streaming applications using the familiar Kafka API.
Scalability Unit: Brokers and partitions. Scaling typically involves adding more brokers and potentially rebalancing partitions across them.
Data Retention: Configurable, often ranging from 24 hours to 7 days or more, depending on storage configuration.
Integration: Good integration with AWS services, but also with the broader Kafka open-source ecosystem.
Flexibility: Provides more control over Kafka-specific configurations compared to Kinesis.
Key Differences Summarized:
Feature
Amazon MSK
Amazon Kinesis Data Streams
Underlying Tech
Apache Kafka (open-source)
AWS proprietary
API/Ecosystem
Apache Kafka API, full Kafka ecosystem compatibility
In essence, if you need Kafka compatibility, the flexibility of the Kafka ecosystem, or are migrating existing Kafka applications, MSK is the more suitable choice. If you're building new, serverless, real-time analytics pipelines deeply integrated with other AWS services, Kinesis Data Streams often provides a simpler, more native AWS solution.