| Amazon Managed Streaming for Apache Kafka (Amazon MSK) is a fully managed service that makes it easy for you to build and run applications that use Apache Kafka as a data store. Apache Kafka is an open-source platform for building real-time streaming data pipelines and applications. MSK manages the underlying Kafka infrastructure, including the Kafka brokers, ZooKeeper nodes, and all associated compute, storage, and networking.
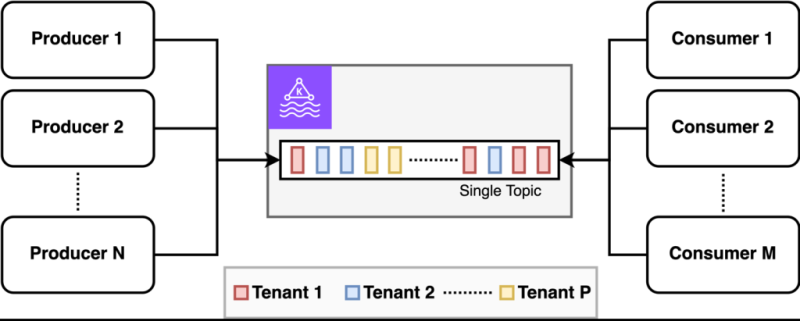
Key characteristics and benefits of Amazon MSK include: - Fully Managed: Eliminates the operational overhead of setting up, managing, and scaling Kafka clusters. AWS handles patching, backups, and failure recovery.
- Apache Kafka Compatibility: Fully compatible with Apache Kafka APIs, allowing you to migrate existing Kafka applications or use your favorite Kafka tools, frameworks, and plugins without code changes.
- Scalability: Allows for independent scaling of compute and storage. MSK automatically manages storage expansion based on your usage, and you can scale compute capacity by changing instance types.
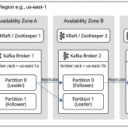
- High Availability: Deploys Kafka brokers across multiple Availability Zones (AZs) to ensure high availability and durability, providing automatic failover in case of an AZ outage.
- Security: Offers multiple layers of security, including network isolation (VPC), encryption at rest and in transit (TLS), integration with AWS Identity and Access Management (IAM), and SASL/SCRAM for client authentication.
- Monitoring and Logging: Integrates with Amazon CloudWatch for metrics and Amazon Kinesis Data Firehose or S3 for broker logs, providing comprehensive insights into cluster performance and health.
- Cost-Effective: You pay only for the Kafka broker capacity, storage, and data transfer you use, without upfront commitments.
Amazon MSK is ideal for various use cases, including building real-time data pipelines, streaming analytics, event sourcing, log aggregation, and connecting microservices. Synchronize data lakes with CDC-based UPSERT using open table format, AWS Glue, and Amazon MSK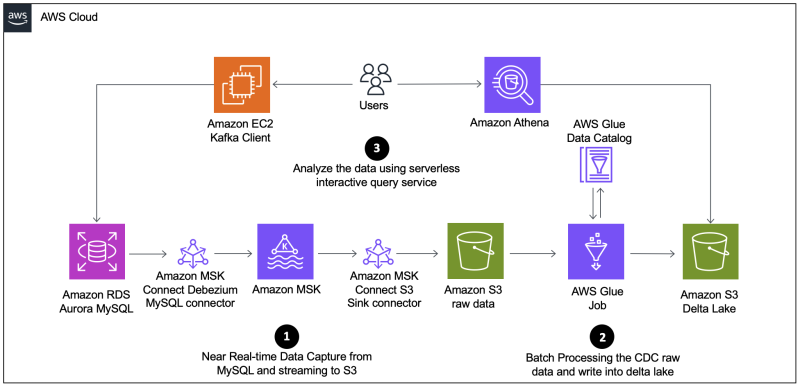
How EchoStar ingests terabytes of data daily across its 5G Open RAN network in near real-time using Amazon Redshift Serverless Streaming Ingestion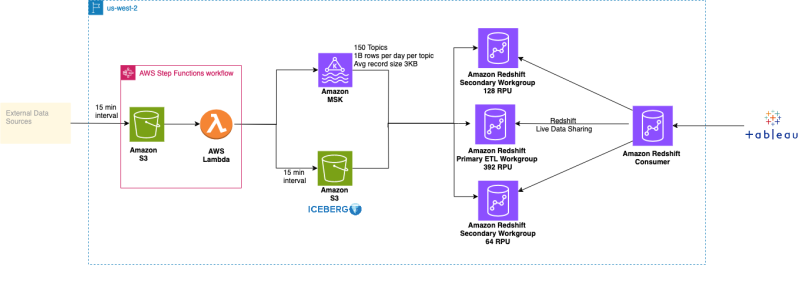
Do we still need Amazon Kinesis if we use Amazon MSK?The need for Amazon Kinesis when using Amazon MSK depends on your specific use case, existing technology stack, and integration requirements. While both services provide real-time data streaming capabilities, they serve different primary purposes and offer distinct advantages: Amazon Kinesis- AWS Native: A suite of native AWS services (Data Streams, Firehose, Video Streams, Data Analytics) designed for real-time data ingestion and processing within the AWS ecosystem.
- Simplicity: Generally simpler to operate for basic streaming needs, especially Kinesis Data Firehose for easy data delivery to destinations like S3, Redshift, or OpenSearch Service.
- Serverless Integration: Tightly integrated with other AWS serverless services like AWS Lambda, making it a natural fit for serverless architectures.
- Managed Service: Offers very low operational overhead, as AWS manages almost everything.
Amazon MSK- Managed Apache Kafka: Specifically provides a fully managed service for Apache Kafka, bringing the full power and ecosystem of Kafka to AWS.
- Kafka Ecosystem: Ideal for organizations that have existing investments in Apache Kafka, require specific Kafka features (e.g., Kafka Streams, Kafka Connect, advanced consumer group management), or want to leverage the vast Kafka community and tooling.
- Migration: Facilitates easy migration of self-managed Kafka clusters to the cloud.
- Control: Offers more granular control over Kafka configurations compared to Kinesis.
You might not need Kinesis if- Your application solely relies on Apache Kafka and its ecosystem.
- You are migrating an existing Kafka workload.
- You prefer to standardize on a single streaming technology (Kafka) for all your needs.
You might still need Kinesis (or find it beneficial) if- You have simpler data ingestion needs that don't require the full Kafka ecosystem.
- You want to leverage Kinesis Data Firehose for easy delivery to other AWS services (S3, Redshift).
- You are building serverless applications where Kinesis Data Streams and Lambda offer tighter integration and simpler development.
- You need to bridge data between native AWS services and your Kafka-based applications.
Example code based on Amazon Kinesis Data StreamsThis script will send log entries to an Amazon Kinesis Data Stream. import boto3
import json
import time
import random
from datetime import datetime
# --- Kinesis Configuration ---
KINESIS_STREAM_NAME = "api-call-logs-stream" # <<--- IMPORTANT: Replace with your Kinesis Stream Name
AWS_REGION = "us-east-1" # <<--- IMPORTANT: Replace with your AWS Region
# Initialize Kinesis client
try:
kinesis_client = boto3.client('kinesis', region_name=AWS_REGION)
print(f"Kinesis client initialized for region: {AWS_REGION}")
except Exception as e:
print(f"Error initializing Kinesis client: {e}")
exit(1)
def generate_api_log_entry():
"""Generates a simulated API call log entry."""
http_methods = ["GET", "POST", "PUT", "DELETE"]
status_codes = [200, 201, 204, 400, 401, 403, 404, 500, 503]
api_paths = [
"/users", "/products", "/orders", "/payments", "/search",
"/auth/login", "/items/{id}", "/reports", "/admin/dashboard"
]
ip_addresses = [
f"192.168.1.{random.randint(1, 254)}",
f"10.0.0.{random.randint(1, 254)}",
f"172.16.0.{random.randint(1, 254)}"
]
log_entry = {
"timestamp": datetime.now().isoformat(),
"method": random.choice(http_methods),
"path": random.choice(api_paths),
"status_code": random.choice(status_codes),
"latency_ms": random.randint(10, 1500),
"client_ip": random.choice(ip_addresses),
"user_agent": "Mozilla/5.0 (simulated)",
"request_id": str(random.uuid4()) # Unique ID for each request
}
return log_entry
def send_log_to_kinesis(log_entry):
"""Sends a single log entry to the Kinesis Data Stream."""
try:
# Kinesis expects data as bytes
partition_key = log_entry.get("client_ip", str(random.uuid4())) # Use client_ip as partition key
response = kinesis_client.put_record(
StreamName=KINESIS_STREAM_NAME,
Data=json.dumps(log_entry).encode('utf-8'),
PartitionKey=partition_key
)
print(f"Sent record to Kinesis. ShardId: {response['ShardId']}, SequenceNumber: {response['SequenceNumber']}")
return True
except Exception as e:
print(f"Error sending record to Kinesis: {e}")
return False
if __name__ == "__main__":
print(f"Starting to send API call logs to Kinesis stream: {KINESIS_STREAM_NAME}")
print("Press Ctrl+C to stop.")
while True:
log = generate_api_log_entry()
print(f"\nGenerated Log: {json.dumps(log)}")
if send_log_to_kinesis(log):
print("Log successfully sent to Kinesis.")
else:
print("Failed to send log to Kinesis.")
time.sleep(random.uniform(0.5, 2.0)) # Simulate traffic by waiting
Amazon MSK (Managed Streaming for Apache Kafka) Versionfrom confluent_kafka import Producer, KafkaException
import json
import time
import random
from datetime import datetime
import uuid
# --- MSK/Kafka Configuration ---
# IMPORTANT: Replace with your MSK cluster's bootstrap servers (e.g., b-1.yourcluster.abc.msk.us-east-1.amazonaws.com:9092)
# Use the "Public access" endpoint if configured, otherwise the VPC internal one.
# Make sure your client can reach these servers (VPC, security groups, public access settings).
MSK_BOOTSTRAP_SERVERS = "b-1.yourclustername.abcde.c1.kafka.us-east-1.amazonaws.com:9092,b-2.yourclustername.abcde.c1.kafka.us-east-1.amazonaws.com:9092"
KAFKA_TOPIC_NAME = "api-call-logs-topic" # <<--- IMPORTANT: Replace with your Kafka Topic Name
# Kafka producer configuration
# For MSK, often 'SSL' or 'SASL_SSL' is used for security.
# This example uses 'SSL' for simplicity, assuming a publicly accessible cluster or client in same VPC with proper security groups.
# If your MSK cluster uses IAM authentication, the config will be more complex.
# Example for SASL_SSL with SCRAM:
# 'sasl.mechanism': 'SCRAM-SHA-512',
# 'sasl.username': 'your_msk_username',
# 'sasl.password': 'your_msk_password',
# For IAM authentication, you'd need the MSK IAM authenticator library.
conf = {
'bootstrap.servers': MSK_BOOTSTRAP_SERVERS,
'security.protocol': 'SSL', # Use 'SASL_SSL' if your cluster requires SASL authentication
# 'ssl.ca.location': '/path/to/your/custom-ca-cert.pem' # Optional: if using custom CA
}
# Initialize Kafka Producer
producer = None
try:
producer = Producer(conf)
print(f"Kafka Producer initialized for bootstrap servers: {MSK_BOOTSTRAP_SERVERS}")
except KafkaException as e:
print(f"Error initializing Kafka Producer: {e}")
exit(1)
def delivery_report(err, msg):
"""Callback function for message delivery."""
if err is not None:
print(f"Message delivery failed: {err}")
else:
print(f"Message delivered to topic {msg.topic()} [{msg.partition()}] at offset {msg.offset()}")
def generate_api_log_entry():
"""Generates a simulated API call log entry."""
http_methods = ["GET", "POST", "PUT", "DELETE"]
status_codes = [200, 201, 204, 400, 401, 403, 404, 500, 503]
api_paths = [
"/users", "/products", "/orders", "/payments", "/search",
"/auth/login", "/items/{id}", "/reports", "/admin/dashboard"
]
ip_addresses = [
f"192.168.1.{random.randint(1, 254)}",
f"10.0.0.{random.randint(1, 254)}",
f"172.16.0.{random.randint(1, 254)}"
]
log_entry = {
"timestamp": datetime.now().isoformat(),
"method": random.choice(http_methods),
"path": random.choice(api_paths),
"status_code": random.choice(status_codes),
"latency_ms": random.randint(10, 1500),
"client_ip": random.choice(ip_addresses),
"user_agent": "Mozilla/5.0 (simulated)",
"request_id": str(uuid.uuid4()) # Unique ID for each request
}
return log_entry
def send_log_to_kafka(log_entry):
"""Sends a single log entry to the Kafka Topic."""
if not producer:
print("Kafka producer not initialized.")
return False
try:
# Kafka expects key and value as bytes
log_bytes = json.dumps(log_entry).encode('utf-8')
# Using client_ip as message key helps ensure logs from the same IP go to the same partition
# and maintain order (if desired). Or use request_id for unique keys.
message_key = log_entry.get("client_ip", str(uuid.uuid4())).encode('utf-8')
producer.produce(KAFKA_TOPIC_NAME, key=message_key, value=log_bytes, callback=delivery_report)
# Poll to handle delivery reports and events
producer.poll(0) # Non-blocking poll
return True
except KafkaException as e:
print(f"Error sending record to Kafka: {e}")
return False
except Exception as e:
print(f"Unexpected error sending record to Kafka: {e}")
return False
if __name__ == "__main__":
print(f"Starting to send API call logs to Kafka topic: {KAFKA_TOPIC_NAME}")
print("Press Ctrl+C to stop.")
try:
while True:
log = generate_api_log_entry()
print(f"\nGenerated Log: {json.dumps(log)}")
if send_log_to_kafka(log):
print("Log successfully queued for Kafka.")
else:
print("Failed to queue log for Kafka.")
time.sleep(random.uniform(0.5, 2.0)) # Simulate traffic by waiting
except KeyboardInterrupt:
print("\nStopping log producer.")
finally:
# Flush any outstanding messages to Kafka before exiting
if producer:
print("Flushing pending Kafka messages...")
producer.flush(timeout=10) # Wait up to 10 seconds for messages to be delivered
print("Producer flushed. Exiting.")
|