FAISS Already Does ANN... So Why Do Top Teams Still Pay for SageMaker?
CK 3788 Created at
31500
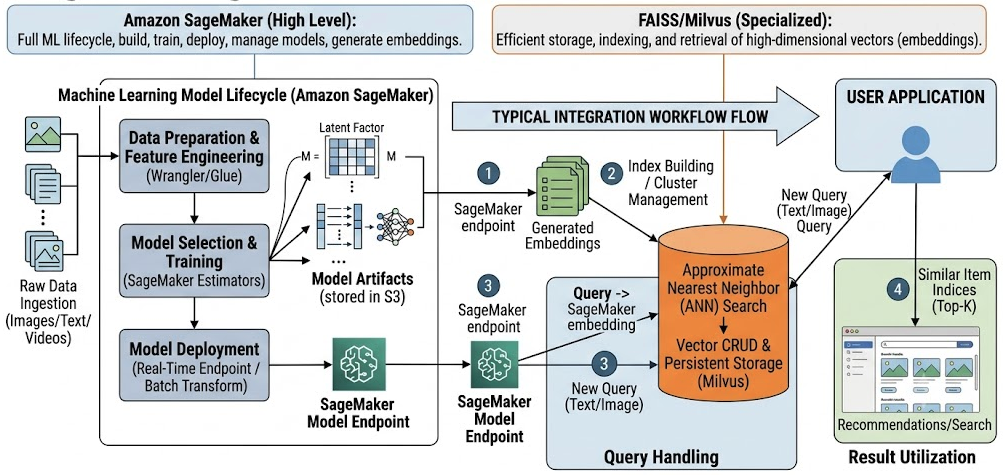
Amazon SageMaker and vector similarity search libraries/databases like FAISS and Milvus serve distinct yet often complementary roles in a machine learning ecosystem. It is worth comparing them to understand how they fit into the broader ML workflow, as they are not direct competitors but rather different layers of the ML stack. SageMaker is a comprehensive platform for the entire ML lifecycle, while FAISS and Milvus are specialized tools for efficient vector similarity search, a specific, albeit crucial, component of many ML applications.
Core Relationship: Complementary Roles
The perceived overlap arises because Approximate Nearest Neighbor (ANN) search, which FAISS and Milvus excel at, is a fundamental feature in many ML applications (e.g., recommendation systems, semantic search, and anomaly detection).
Amazon SageMaker operates at a higher level, providing the infrastructure and tools to build, train, deploy, and manage machine learning models throughout their lifecycle. This includes everything from data preparation and feature engineering to model training (which might involve creating embeddings) and deploying those models for inference.
FAISS and Milvus are specialized tools that efficiently store and retrieve high-dimensional vectors (embeddings). These embeddings are typically generated by models that have been trained and deployed using platforms like SageMaker.
In a typical workflow:
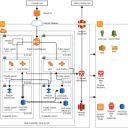
A machine learning model (e.g., a deep learning model for image recognition or natural language processing) is developed, trained, and deployed using Amazon SageMaker. This model's purpose might be to transform raw data (images, text) into high-dimensional numerical representations called embeddings.
These generated embeddings are then ingested into a FAISS index (for in-memory, high-performance use cases) or a Milvus cluster (for persistent, scalable vector database solutions).
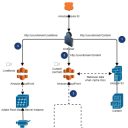
When a query comes in (e.g., a new image or text), SageMaker can be used to generate its embedding, which is then passed to FAISS/Milvus to find the most similar existing embeddings.
The results from FAISS/Milvus (i.e., the indices of similar items) are then used by the application, possibly integrating back with other services or SageMaker-deployed components, to provide recommendations, search results, etc.
Therefore, SageMaker provides the "brains" (model training and inference orchestration) that generate and utilize the "data" (embeddings) that FAISS/Milvus specialize in managing and searching.
What does this process mean for the model artifacts that are stored in S3?
Storing Model Artifacts in S3 means these crucial components—including the trained model weights, configuration files, preprocessing scripts, vocabulary lists, and any associated metadata necessary for the model's functionality and reproducibility—are persistently and scalably archived in a highly available and durable object storage service. This ensures that the complete, versioned state of a machine learning model is preserved independently of its training or deployment environment, enabling easy sharing across teams, reliable deployment to production systems, disaster recovery, auditing, and the ability to reproduce past model behavior or revert to previous versions as needed.
The example of SageMaker-generated embeddings
When SageMaker generates embeddings, it typically returns them as a JSON object, where the actual embedding vector is an array of floating-point numbers.
Here's an example of what a SageMaker-generated embedding might look like in a string format, often as part of a JSON response from an endpoint:
"embeddings" key: This is a common key used by many embedding models (e.g., Hugging Face models, Amazon Titan Embeddings) to encapsulate the results.
Outer Array []: The value of "embeddings" is often an array, even if you submitted only a single input, because the model might support batch processing. Each element in this outer array corresponds to the embedding for one input item.
Inner Array []: This is the actual embedding vector. It's a list (or array) of floating-point numbers. The number of elements in this array represents the dimension of the embedding (e.g., 384, 512, 768, 1024, 1536 are common dimensions).
Floating-Point Numbers: Each number is a float, typically ranging between -1 and 1, though the exact range can vary depending on the specific embedding model.
The specific string representation you get would be the JSON string as shown above. If you were to extract just the embedding vector itself (the inner array), it would be:
No (FAISS library), Milvus can be self-hosted or offered as a managed service by vendors (e.g., Zilliz Cloud)
Scalability
Highly scalable for compute, storage, endpoints. Handles scaling of underlying infrastructure.
Scalable for vector search (Milvus designed for distributed scaling; FAISS more for single-node optimization or custom distributed setups).
Integration
Deeply integrated with other AWS services, supports custom code and frameworks.
Can be integrated into any application, including those deployed on SageMaker or other cloud platforms.
Vendor/Ecosystem
AWS ecosystem
Open-source, vendor-agnostic (can run anywhere)
Cost Model
Pay-as-you-go for compute, storage, endpoints.
Free (open-source), but incurs infrastructure costs if self-hosted. Managed versions have their own pricing.
Use Case Examples
Building and deploying a recommendation engine, training a custom computer vision model, MLOps pipelines.
Finding similar items/users based on embeddings, semantic search, nearest neighbor classification.
Amazon SageMaker
Features:
SageMaker Studio: Web-based IDE for ML development.
SageMaker Data Wrangler: Tool for data preparation and feature engineering.
SageMaker Feature Store: Centralized repository for ML features.
Managed Training: Scales compute resources for training jobs, supports built-in algorithms, custom code, and popular frameworks (TensorFlow, PyTorch, MXNet).
Hyperparameter Tuning: Automates finding optimal model hyperparameters.
Model Deployment: Manages real-time inference endpoints, batch transform jobs, and serverless inference.
MLOps Tools: SageMaker Pipelines for CI/CD, Model Monitor for drift detection, SageMaker Clarify for bias and explainability.
Reinforcement Learning & Edge ML: Specialized capabilities for these advanced areas.
Pros:
Comprehensive: Covers the entire ML lifecycle, reducing the need for multiple disparate tools.
Scalability & Elasticity: Automatically scales resources up or down based on demand for training and inference.
Integration: Deeply integrated with other AWS services (S3, Lambda, EC2, etc.), simplifying data access and application development.
Robust MLOps: Provides tools for automating, monitoring, and governing ML workflows.
Cons:
Cost: Can be more expensive than self-hosting components, especially for continuous, large-scale usage.
Learning Curve: Its vast feature set and AWS ecosystem integration can be daunting for new users.
Vendor Lock-in: While supporting open-source frameworks, the platform itself is AWS-specific.
Overhead for Simple Tasks: For very simple ML tasks, SageMaker might introduce unnecessary complexity.
FAISS (Facebook AI Similarity Search)
Features:
High Performance: Written in C++ with highly optimized implementations for various ANN algorithms.
Multiple Index Types: Supports a wide range of indexing structures like IVF (Inverted File Index), HNSW (Hierarchical Navigable Small World), PQ (Product Quantization), LSH (Locality Sensitive Hashing), and various combinations.
GPU Support: Can leverage GPUs for even faster index building and search operations.
Exact and Approximate Search: Offers both brute-force (exact) and ANN search options.
Python Bindings: Easy to use within Python applications.
Pros:
Extreme Speed & Efficiency: Unmatched performance for vector similarity search, especially for large datasets.
Flexibility & Control: Provides fine-grained control over indexing parameters and search strategies.
Widely Adopted & Proven: A standard in the industry for vector search.
Free & Open-Source: No licensing costs.
Cons:
In-Memory Library: Not a persistent database. Indexes are typically loaded into RAM, meaning you need to manage index files and memory for scale.
No Out-of-the-Box Distributed Scaling: Requires custom engineering to scale horizontally across multiple machines or nodes.
Manual Management: Lacks built-in features for data persistence, replication, high availability, or CRUD operations on vectors (you manage the raw vectors and the index separately).
Complexity: Can be challenging to configure and optimize for very large-scale, dynamic datasets without deep knowledge of ANN algorithms.
Milvus
Features:
Cloud-Native Vector Database: Designed for distributed deployment and scalability.
Vector CRUD Operations: Supports inserting, deleting, updating, and querying vectors with associated metadata.
Scalar Filtering: Allows pre-filtering search results based on scalar attributes before vector similarity calculation.
Pluggable Index Types: Supports various ANN algorithms, including many FAISS-based indices.
Streaming Data Ingestion: Can handle real-time updates and additions to the vector database.
High Availability & Disaster Recovery: Built with a distributed architecture for resilience.
Multi-language SDKs: Provides client SDKs for Python, Java, Go, Node.js, and more.
Pros:
Scalability & Persistence: Solves the in-memory and scaling limitations of raw FAISS by providing a persistent, distributed vector database.
Dynamic Data Handling: Built for dynamic datasets that require frequent updates and deletions.
Easier Management: Abstracts away much of the underlying index and infrastructure management compared to FAISS.
Rich Features: Includes metadata filtering, which is crucial for many real-world search applications.
Open-Source & Active Community: Benefits from community development and support.
Cons:
Operational Overhead: If self-hosted, setting up and managing a Milvus cluster can still be complex and resource-intensive, requiring expertise in distributed systems.
Resource Consumption: Large Milvus clusters can consume significant computing and storage resources.
Learning Curve: Has its own architectural concepts and API, requiring a learning investment.
Not a General-Purpose Database: Strictly designed for vector search; not a replacement for traditional relational or NoSQL databases.