The Blueprint of Success: Why System Design and Architecture Matter?
CK 3788 Created at
40100
Why is the system design process important?
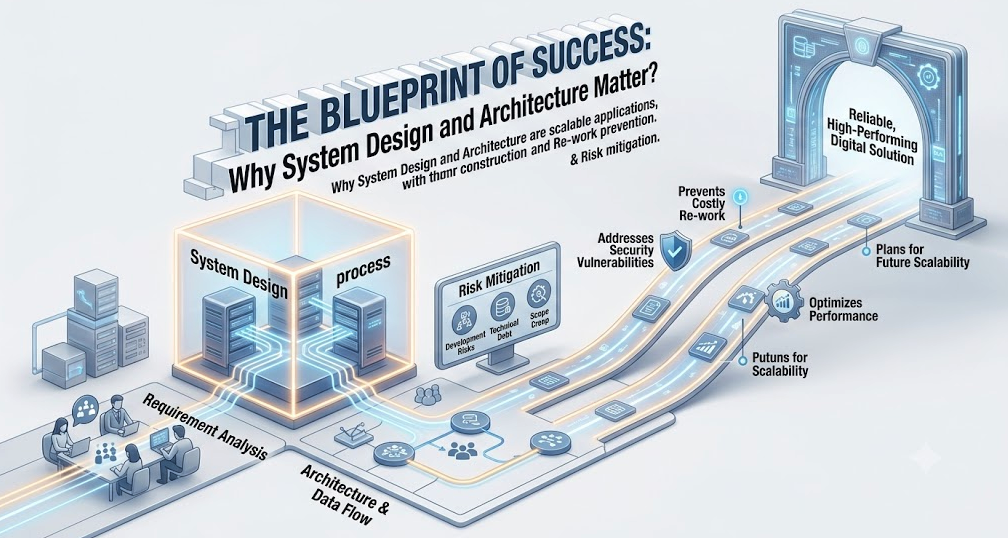
The system design process is crucially important because it serves as the foundational blueprint for building robust, scalable, and efficient software applications.
By initiating development with a thorough requirement analysis, organizations ensure that the final product aligns perfectly with user expectations and business goals, thereby preventing costly re-work and scope creep.
Furthermore, establishing a clear architecture and mapping out data flows allows engineers to address security vulnerabilities, optimize performance, and plan for future scalability before a single line of code is written.
Ultimately, this structured methodology mitigates development risks, minimizes technical debt, and facilitates seamless collaboration among cross-functional teams, transforming abstract ideas into reliable, high-performing digital solutions.
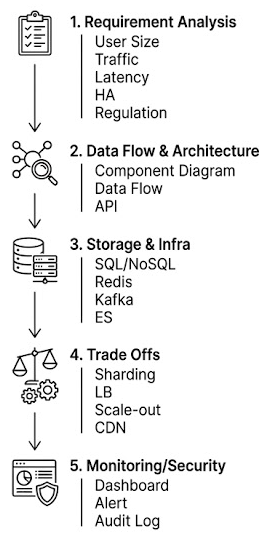
What is the common system design process?
1. Requirements Analysis
The foundation of any robust system architecture is a deep understanding of its requirements. This stage involves defining both functional constraints and non-functional goals to shape the final technical decisions.
1.1. User Size, Traffic Pattern
Scale Metrics: Define the target audience size using metrics like Daily Active Users (DAU) and Monthly Active Users (MAU).
Throughput (QPS/TPS):
Calculate average and peak Queries Per Second (QPS) or Transactions Per Second (TPS).
For example, a system with 10 million DAU might average 1,000 QPS but experience spikes of 50,000 QPS during peak events.
Read/Write Ratio:
Determine if the application is read-heavy (e.g., social media feeds, news sites with a 99:1 ratio) or write-heavy (e.g., IoT sensor telemetry, financial ledgers with a 1:1 or 1:5 ratio).
This heavily influences database selection and caching strategy.
1.2. Latency (sub-200ms...)
Service Level Agreements (SLAs) & SLOs:
Establish clear latency expectations.
A typical consumer-facing application aims for a P95 (95th percentile) latency under 200ms and a P99 under 500ms.
Network vs. Processing Latency:
Distinguish between the time spent traversing the network and the time spent processing requests on the server.
Low latency requirements dictate the use of Edge networks (CDNs), in-memory databases, and optimized application runtimes.
99.9% / "three nines" allows ~8.76 hours of downtime per year
99.99% / "four nines" allows ~52.6 minutes
Redundancy:
Design systems with no Single Point of Failure (SPOF).
This involves deployment across Multi-AZ (Availability Zones) or Multi-Region setups.
Disaster Recovery (DR):
Define RTO (Recovery Time Objective—how quickly the system must recover) and RPO (Recovery Point Objective—how much data loss is acceptable).
Strategies range from Backup & Restore to Active-Active multi-site deployments.
1.4. Regulation
Compliance Frameworks:
Identify applicable legal and industry standards such as GDPR (Europe), CCPA (California), HIPAA (healthcare), or PCI-DSS (payment processing).
Data Residency:
Determine geographic restrictions on where user data can be physically stored and processed (e.g., keeping EU citizen data within EU borders).
Data Retention & Erasure:
Implement mechanisms for automatic data purging after a specific period and "Right to be Forgotten" workflows.
2. Data Flow & Architecture
Once requirements are gathered, they must be translated into structural blueprints and behavioral models.
2.1. High-level Component Diagram
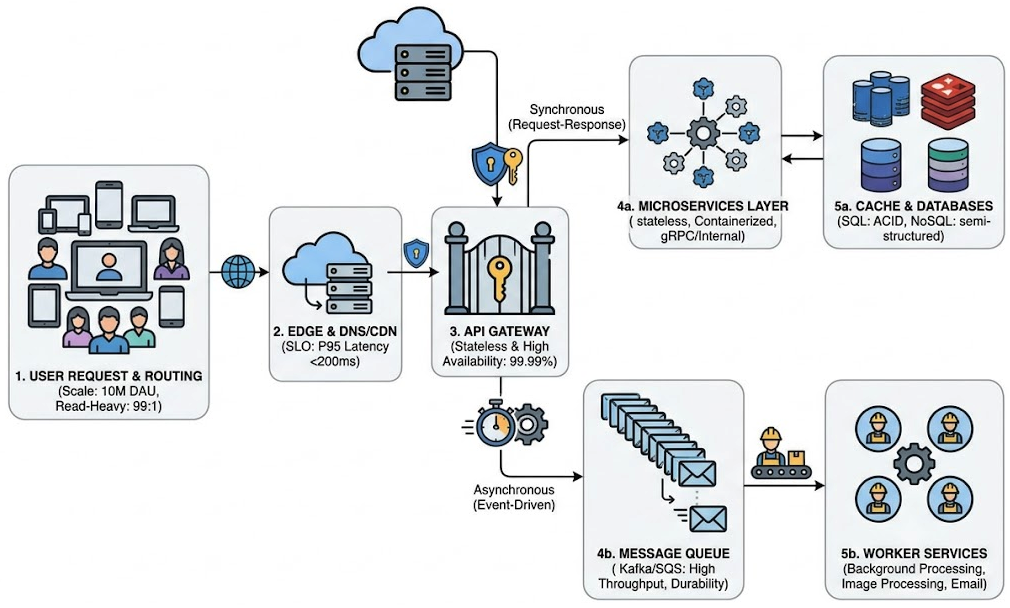
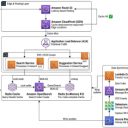
A macro view of the entire system architecture, typically divided into layers:
Client Layer: Web browsers, mobile apps, IoT devices.
Entry/Routing Layer: DNS (e.g., Route53), Content Delivery Networks (CDNs), and Web Application Firewalls (WAF).
Gateway Layer: API Gateways (e.g., Kong, AWS API Gateway) handling routing, rate limiting, and authentication.
Application/Microservices Layer: Stateless containerized services (e.g., running on Kubernetes or ECS) executing business logic.
Integration Layer: Message brokers and event buses.
Data Layer: Relational/NoSQL databases, caches, and analytical warehouses.
2.2. Data Flow
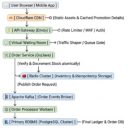
Synchronous Flow (Request-Response): Used for immediate actions (e.g., user login). The client sends a request, waits, and receives a response immediately via protocols like HTTP/HTTPS or gRPC.
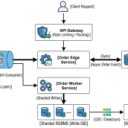
Asynchronous Flow (Event-Driven): Used for long-running, non-blocking tasks (e.g., image processing, email notifications). The client triggers an action, the gateway/service puts an event onto a queue, returns an immediate "Accepted" status, and worker nodes process the task in the background.
2.3. API Design
Protocols:
REST: Standard for public-facing APIs, utilizing HTTP methods (GET, POST, PUT, DELETE) and JSON payloads.
gRPC: Low-latency, high-performance RPC framework using Protocol Buffers over HTTP/2, ideal for internal microservice-to-microservice communication.
GraphQL: Best for client-driven queries where clients need to request specific, customized data structures in a single round-trip.
API Contracts & Versioning: Using OpenAPI/Swagger to define clear boundaries. Versioning APIs (e.g., /v1/, /v2/) ensures backward compatibility.
3. Storage & Infra
Choosing the right storage and infrastructure components depends on the nature of the data and access patterns.
Use Cases: Financial transactions, user identity management, inventory systems where data integrity and consistency are critical.
NoSQL (Non-Relational Databases):
Document (e.g., MongoDB): Best for semi-structured data, content management, and fast prototyping.
Key-Value (e.g., DynamoDB): Excellent for simple, highly scalable read/write patterns (e.g., user sessions, shopping carts).
Wide-Column (e.g., Cassandra): Ideal for massive datasets with high write volumes and predictable query patterns (e.g., timeseries data, logging).
3.2. Redis or Memcached
Redis:
Pros: Supports rich data structures (Strings, Lists, Sets, Hashes, Sorted Sets), data persistence, replication, clustering, and can act as an in-memory database, message broker, or pub/sub system.
Use Cases: Leaderboards, session stores, rate limiters, complex caching.
Memcached:
Pros: Multi-threaded, simple, highly efficient purely as a static key-value cache.
Use Cases: Straightforward, high-performance object caching to relieve database read pressure.
3.3. Message Queue (Kafka, SQS)
Apache Kafka:
Type: Distributed, partitioned commit log.
Strengths: Extremely high throughput, message replayability, guaranteed ordering within a partition, support for event streaming architectures.
Use Cases: Activity tracking, real-time data pipelines, event sourcing.
Use Cases: Standard decoupling of application components, processing background worker jobs.
3.4. Elasticsearch
Full-Text Search Engine: Built on Apache Lucene, designed to query massive volumes of unstructured text data with near real-time latency.
Inverted Index: Optimizes lookups by mapping words directly to their document locations rather than searching through document text sequentially.
Log Aggregation (ELK Stack): Acts as the storage and search engine for application logs and metrics, allowing developers to debug and monitor systems through Kibana.
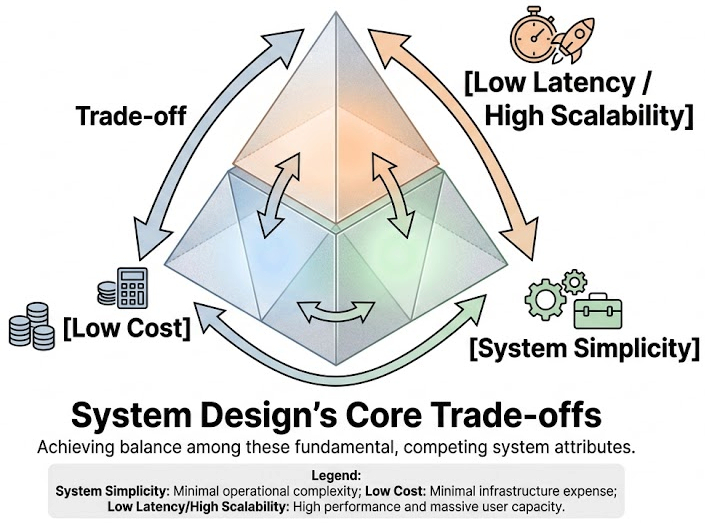
4. Flexibility, Latency, Cost Trade-Offs
System design is a continuous exercise in managing trade-offs. Scaling a system requires balancing cost against speed and complexity.
4.1. Sharding
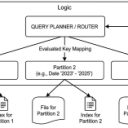
Definition: Horizontal partitioning of a database where data is split across multiple database instances based on a Shard Key (e.g., user_id % num_shards).
Trade-off: Increases write scale and database capacity, but introduces extreme complexity in query routing, makes cross-shard joins nearly impossible, and risks creating "hot shards" if the shard key is poorly selected.
4.2. Load Balancing
Layer 4 (L4) Load Balancing: Operates at the transport layer (TCP/UDP). It routes traffic based on IP and port numbers without inspecting packet contents. It is extremely fast but lacks routing intelligence.
Layer 7 (L7) Load Balancing: Operates at the application layer (HTTP/HTTPS). It routes traffic based on URLs, cookies, or headers. It supports advanced features like SSL termination and path-based routing (e.g., /api/v1/users -> Users Service) but consumes more CPU resources.
4.3. Scale-out (Horizontal Scaling)
Scale-up (Vertical): Adding more CPU/RAM to a single server. It is easy but has a physical ceiling and introduces a single point of failure.
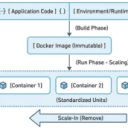
Scale-out (Horizontal): Adding more instances of servers/containers. It requires applications to be stateless (storing state like sessions in external databases or caches rather than memory) to allow seamless load distribution.
4.4. CDN & Caching Layer
Content Delivery Network (CDN - e.g., Cloudflare, CloudFront): Caches static content (images, JS, CSS, videos) and dynamic API responses at edge locations closest to the end-users, lowering latency and offloading traffic from origin servers.
Cache Invalidation Strategies:
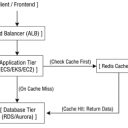
Cache-Aside (Lazy Loading): Application checks the cache; if a miss occurs, it queries the database and updates the cache. Good for read-heavy workloads.
Write-Through: Application writes data to both the cache and the database simultaneously. Ensures data consistency but adds latency to writes.
Time-To-Live (TTL): Automatically expires cached items after a set period to balance freshness and cache hit ratios.
5. Monitoring & Security
A production-ready architecture must be observable, secure, and compliant.
5.1. Dashboard (Prometheus / Grafana / Datadog)
Observability Pillars:
Metrics: Numeric data measured over time (e.g., CPU utilization, memory usage, request rates).
Logs: Text-based records of events that occurred at specific times (e.g., stack traces, HTTP access logs).
Traces: End-to-end journey of a single request across multiple microservices (APM).
Tools:
Prometheus: Collects metrics using a pull model and stores them in a time-series database.
Grafana: Visualizes data from Prometheus or other sources using customizable, real-time dashboards.
Datadog: An all-in-one SaaS platform that aggregates metrics, logs, and traces with minimal setup but higher costs.
5.2. Alerting
Alerting Rules: Set thresholds on key metrics (e.g., alert if CPU usage > 85% for 5 minutes, or if HTTP 5xx error rate > 1%).
Severity Tiers:
P1/Critical: Triggers immediate paging (via PagerDuty, Opsgenie) to wake up on-call engineers.
P2/Warning: Sends non-urgent notifications to communication channels (e.g., Slack, Microsoft Teams).
Alert Fatigue: Carefully tune thresholds to prevent developers from ignoring notifications due to "false alarms."
5.3. Security Layer
Network Isolation: Use Virtual Private Clouds (VPCs), public subnets (for load balancers), and private subnets (for databases and application servers) with strict Security Groups.
Encryption:
In-Transit: Implement TLS (HTTPS, gRPC secure) for all external and internal communications.
At-Rest: Encrypt database storage, caches, and backups using tools like AWS KMS.
Identity & Access Control: Implement OAuth 2.0 / OpenID Connect (OIDC) for user authentication and authorization. Apply the Principle of Least Privilege (PoLP) using IAM policies for service-to-service communication.
5.4. Audit Logs & Regulations
Audit Logging: Maintain an immutable ledger of system actions (e.g., who accessed what data, when a configuration was changed). This is vital for security forensics and compliance audits.
Tamper-Proof Storage: Store audit logs in dedicated, write-once-read-many (WORM) storage configurations (such as AWS S3 with Object Lock enabled) to ensure logs cannot be modified or deleted, even by administrative users.