Learning about Firestore: Architecture, Pros, Cons, and Real-World Deployments
CK 3788 Created at
16600
Firestore was developed by Google. It is part of the Google Cloud Platform (GCP) and is deeply integrated with Firebase, Google's mobile and web application development platform.
What is the main purpose of "Firestore"?
Firestore is a NoSQL document database designed for storing, syncing, and querying data for web, mobile, and server applications at global scale. Its main purposes include:
Real-time Data Synchronization: It allows clients (web browsers, mobile apps) to listen for changes to data and receive updates instantly, making it ideal for collaborative and live applications.
Offline Support: Its SDKs for mobile and web automatically cache data for offline use and synchronize local changes back to the database when the device comes online.
Scalability: It's built to scale automatically and seamlessly, handling large numbers of concurrent users and vast amounts of data without requiring developers to manage infrastructure.
Serverless Operation: Developers can focus o building their applications without managing database servers, patching, or backups. Google manages all the operational aspects.
Flexible Data Modeling: As a NoSQL database, it supports flexible, hierarchical data structures (documents and collections) that can evolve easily.
It is particularly well-suited for applications requiring reactive user experiences, robust offline capabilities, and global reach with minimal operational overhead.
What are the architectural features of "Firestore" including Pros and Cons?
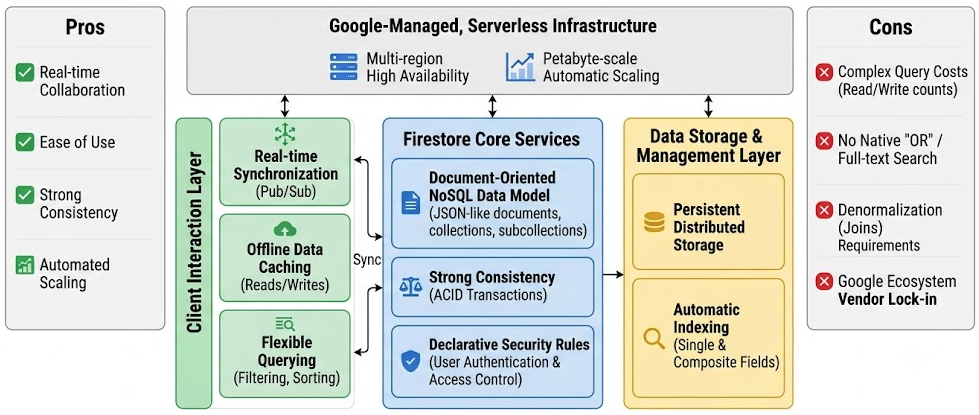
Firestore is a serverless, NoSQL document-oriented database with the following key architectural characteristics:
Document-Oriented: Data is stored in documents, which are flexible JSON-like objects. Documents are organized into collections, and documents can also contain subcollections, forming a hierarchical data model.
Strong Consistency: Unlike some other NoSQL databases, Firestore provides strong consistency, meaning all reads always see the latest write, and it supports ACID transactions.
Real-time Synchronization: Utilizes a publish/subscribe model where clients can attach listeners to documents or queries. Any changes to the matching data are pushed to the client in real-time.
Offline First: Client SDKs automatically handle data caching and synchronization. Reads are served from the cache, and writes are applied locally and then synced to the server, resolving conflicts if necessary.
Scalability: Leverages Google's global infrastructure for automatic horizontal scaling and high availability. It's designed to handle millions of concurrent users and petabytes of data.
Serverless: Fully managed by Google, eliminating the need for database administration, scaling, and patching.
Declarative Security Rules: Offers a powerful security model based on security rules that define who can access what data under which conditions directly from the client.
Flexible Querying: Supports rich querying capabilities including filtering, ordering, and pagination across multiple fields.
Pros of Firestore
Real-time Capabilities: Excellent for building highly interactive, collaborative, and live applications (e.g., chat apps, live dashboards, multiplayer games).
Scalability: Automatically scales to handle vast amounts of data and traffic without manual intervention.
Serverless: Significantly reduces operational overhead and allows developers to focus on application logic.
Offline Support: Provides a robust offline experience, making applications more resilient to network issues.
Ease of Use & Integration: Simple API and seamless integration with other Firebase and Google Cloud services.
Strong Consistency: Ensures data integrity with ACID transactions, making it reliable for critical data.
Flexible Data Model: Adaptable to evolving data structures, common in modern application development.
Cons of Firestore
Cost: Can become expensive for applications with very high read/write volumes, especially when complex queries involve reading many documents. Each document read, write, or delete counts towards billing.
Query Limitations:
No "OR" queries (directly; requires multiple queries combined on the client).
No full-text search out-of-the-box (requires integration with external services like Algolia or Elasticsearch).
No complex joins across collections (denormalization is often required, which can increase data duplication).
Requires indexes for most queries, which are automatically created but can be custom-tuned.
NoSQL Nature: Less suitable for highly relational data that would typically benefit from complex joins and referential integrity enforced at the database level.
Vendor Lock-in: Tightly coupled to the Google Cloud/Firebase ecosystem, making migration to other database systems potentially challenging.
Data Model Design: Designing an efficient data model for specific access patterns can sometimes be challenging and critical for cost optimization.
Core Differences as NoSQL Databases
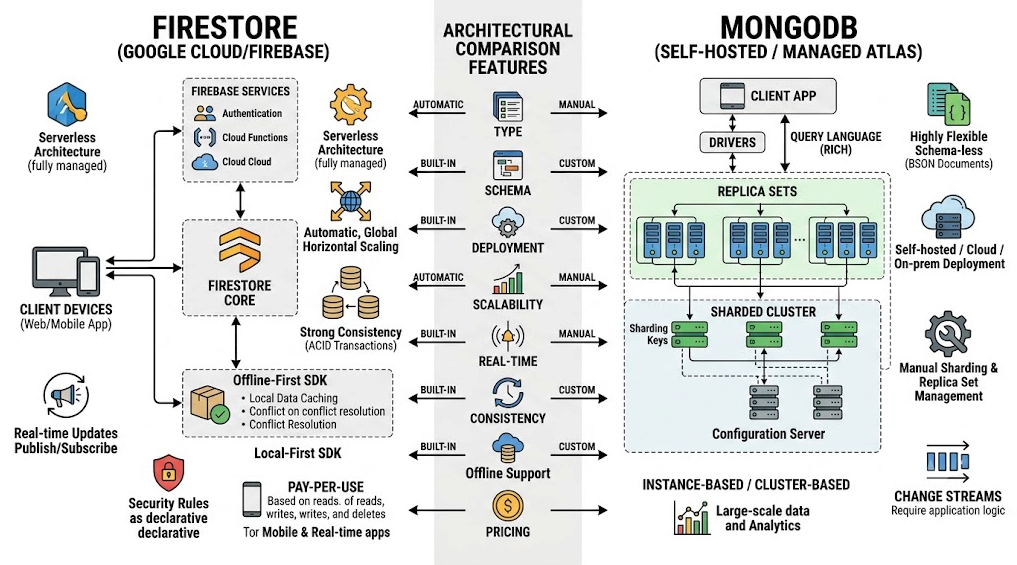
While both Firestore and MongoDB are prominent NoSQL databases, they diverge significantly in their underlying philosophy, data modeling, and operational characteristics, catering to different application needs.
Feature
Firestore
MongoDB
Type
Document-oriented (Collection-Document)
Document-oriented
Schema
Flexible, but encourages structured collections/docs
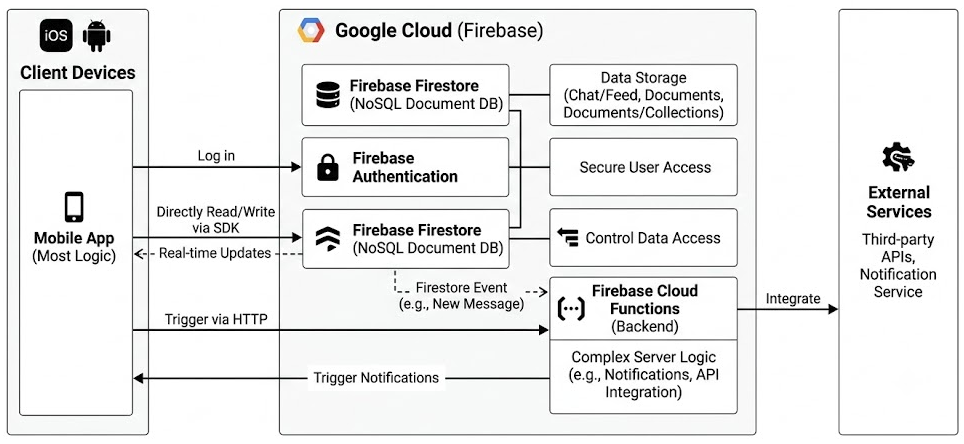
Reference Case 1. Mobile Application (e.g., a real-time chat or social feed app)
Application Logic: Most application logic resides within the mobile app itself (iOS/Android).
Data Storage: The mobile app uses the Firebase Firestore SDK to directly read from and write to Firestore.
Authentication: Firebase Authentication is used to secure user access and integrate with Firestore Security Rules.
Backend (Optional): For complex server-side operations (e.g., sending notifications, heavy data processing, integrating with third-party APIs), Firebase Cloud Functions are deployed. These functions can be triggered by Firestore events (e.g., a new message document created) or via HTTP requests from the mobile app.
Deployment Steps:
Configure a Firestore instance in the Firebase Console.
Write your mobile app using the Firestore SDK.
Define Firestore Security Rules to control data access.
(If needed) Write and deploy Cloud Functions for backend logic.
Deploy the mobile app to app stores (Apple App Store, Google Play Store).
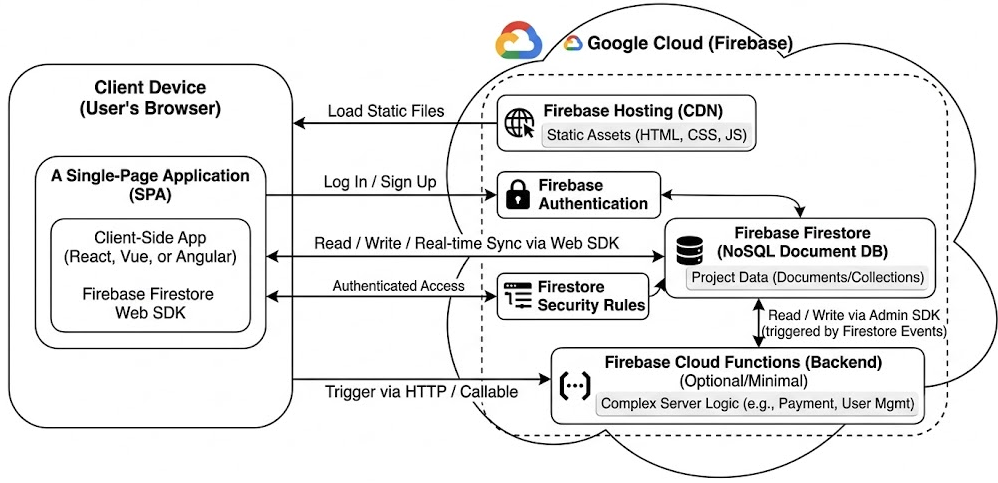
Reference Case 2. Web Application (e.g., a collaborative project management tool)
Client-Side: A Single-Page Application (SPA) built with frameworks like React, Vue, or Angular, running in the user's browser. It uses the Firebase Firestore Web SDK.
Backend (Optional/Minimal): Similar to mobile apps, Firebase Cloud Functions can handle server-side tasks (e.g., user account management, payment processing, sending emails, complex data validation).
Hosting: The static assets of the web application (HTML, CSS, JavaScript) are typically hosted on Firebase Hosting (or another static site hosting service like Netlify, Vercel, or Google Cloud Storage + CDN).
Deployment Steps:
Configure a Firestore instance.
Develop the web application using the Firestore Web SDK.
Implement Firestore Security Rules.
(If needed) Develop and deploy Cloud Functions.
Deploy the web application's static files to Firebase Hosting.
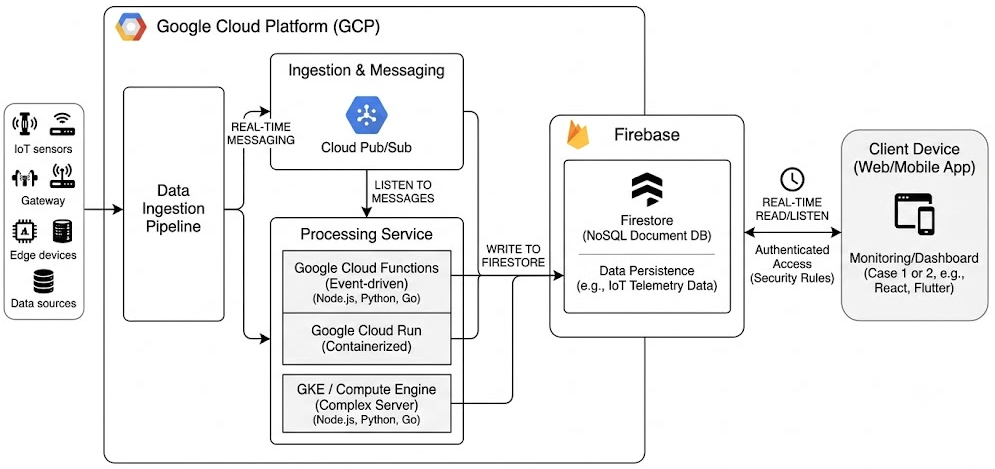
Reference Case 3. Backend Service with Firestore (e.g., an IoT data ingestion pipeline)
Ingestion Point: IoT devices or other data sources send data to a messaging queue or an API endpoint. For Google Cloud, this often involves Google Cloud Pub/Sub for real-time messaging.
Processing Service: A server-side application or microservice written in languages like Node.js, Python, or Go. This service might run on:
Google Cloud Functions: For event-driven, short-lived tasks (e.g., listening to Pub/Sub and writing to Firestore).
Google Cloud Run: For containerized microservices that need more flexibility and longer execution times, automatically scaling based on requests.
Google Kubernetes Engine (GKE) / Compute Engine: For more complex, persistent server applications where more control over infrastructure is desired.
Data Persistence: The processing service writes the incoming data into Firestore for storage and subsequent real-time display/analysis.
Monitoring/Dashboard: A separate web or mobile application (as in examples 1 or 2) connects to Firestore to display the ingested IoT data in real-time.
Deployment Steps:
Configure a Firestore instance.
Set up Cloud Pub/Sub topics.
Develop and deploy a Cloud Function or Cloud Run service that subscribes to Pub/Sub messages and writes data to Firestore.
Configure IoT devices or data sources to send data to Pub/Sub.
(Optional) Deploy a monitoring dashboard web/mobile app that reads from Firestore.
In all these examples, Firestore acts as a managed backend service that your application code interacts with, abstracting away database server management entirely.