| The core mission is to develop kernel-level implementations for a variety of Deep Neural Network (DNN) models, specifically targeting Arm architectures. The primary goals are to optimize these implementations for maximum power efficiency and performance, crucial for deploying DNNs in resource-constrained or high-performance Arm-based systems. What is DNN?A Deep Neural Network (DNN) is a type of artificial neural network characterized by its architecture, which includes multiple layers of nodes (neurons) between the input and output layers. These intermediate layers are known as "hidden layers," and the term "deep" refers to the presence of numerous such layers, allowing the network to learn complex patterns and representations from data. 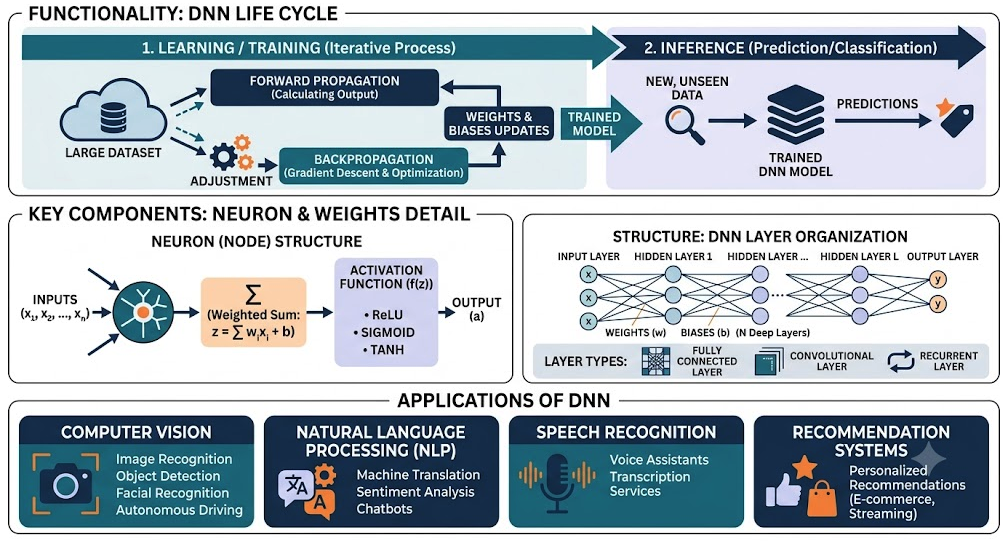
- Structure: DNNs are composed of an input layer, several hidden layers, and an output layer. Each layer consists of interconnected nodes, where connections have associated "weights" and each node has a "bias."
- Functionality:
- Learning: During a process called training, the network learns to map inputs to outputs by adjusting its weights and biases based on a large dataset. This involves forward propagation (calculating output) and backpropagation (adjusting weights based on error using optimization algorithms like gradient descent).
- Inference: After training, the DNN can be used to make predictions or classifications on new, unseen data, which is known as inference.
- Key Components:
- Neurons (Nodes): Basic processing units that receive inputs, apply an activation function, and produce an output.
- Weights and Biases: Parameters that the network learns during training to transform input data.
- Activation Functions: Non-linear functions (e.g., ReLU, Sigmoid, Tanh) applied to the output of each neuron to introduce non-linearity, enabling the network to learn complex relationships.
- Layers: Organize neurons into input, hidden, and output groups. Common types include convolutional layers (for image data), recurrent layers (for sequential data), and fully connected layers.
- Applications: DNNs power a wide range of modern AI applications, including:
- Computer Vision: Image recognition, object detection, facial recognition, autonomous driving.
- Natural Language Processing (NLP): Machine translation, sentiment analysis, chatbots.
- Speech Recognition: Voice assistants, transcription services.
- Recommendation Systems: Personalized recommendations on e-commerce and streaming platforms.
How to use DNN like LLM?First, let's clarify: Large Language Models (LLMs) are a specific type of Deep Neural Network (DNN). They are DNNs specialized for processing and generating human language. When you ask "How do I use DNN like LLM?", you're likely asking how to imbue a generic DNN (e.g., one that processes images, audio, or sensor data) with the kind of flexibility, generative power, contextual understanding, and prompt-based interaction that we see in LLMs. The core idea is to apply the principles and architectures that make LLMs so powerful to other data modalities. Here's how: 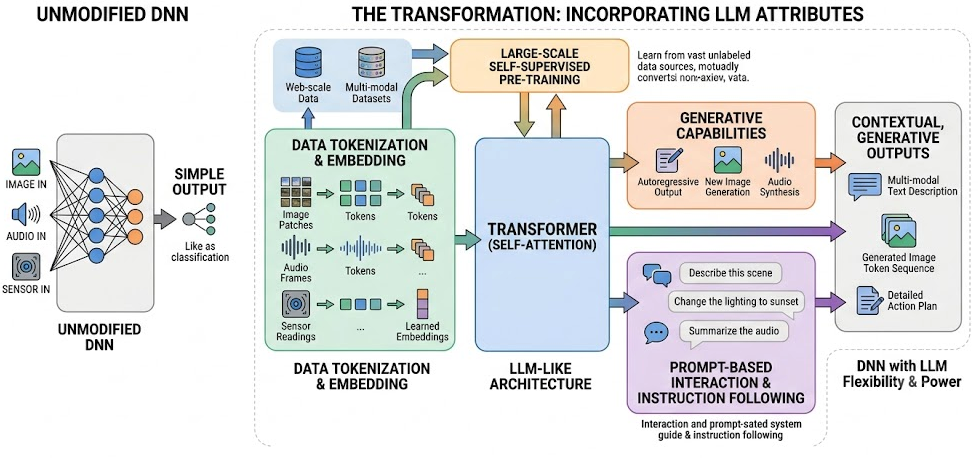
Core Principles of LLMs to Adapt:- Tokenization & Embedding: LLMs break down text into discrete tokens and convert them into numerical embeddings.
- Transformer Architecture: The self-attention mechanism of the Transformer allows LLMs to understand long-range dependencies and context.
- Large-Scale Pre-training: LLMs are pre-trained on vast amounts of unsupervised data to learn general representations and world knowledge.
- Generative Capabilities: LLMs are designed to generate new sequences (text, code, etc.) autoregressively.
- Prompt-based Interaction: LLMs can be guided to perform diverse tasks through natural language prompts, often without explicit fine-tuning for each task (zero-shot/few-shot learning).
- Instruction Following: Through supervised fine-tuning (SFT) and Reinforcement Learning from Human Feedback (RLHF), LLMs learn to follow instructions.
How to Make a DNN "Act Like an LLM" for Non-Text Data:1. Modality-Specific Tokenization & Embedding- Problem: Images, audio, video, sensor data aren't naturally "tokens."
- Solution: Convert your raw data into a sequence of discrete, learnable "tokens" or embeddings.
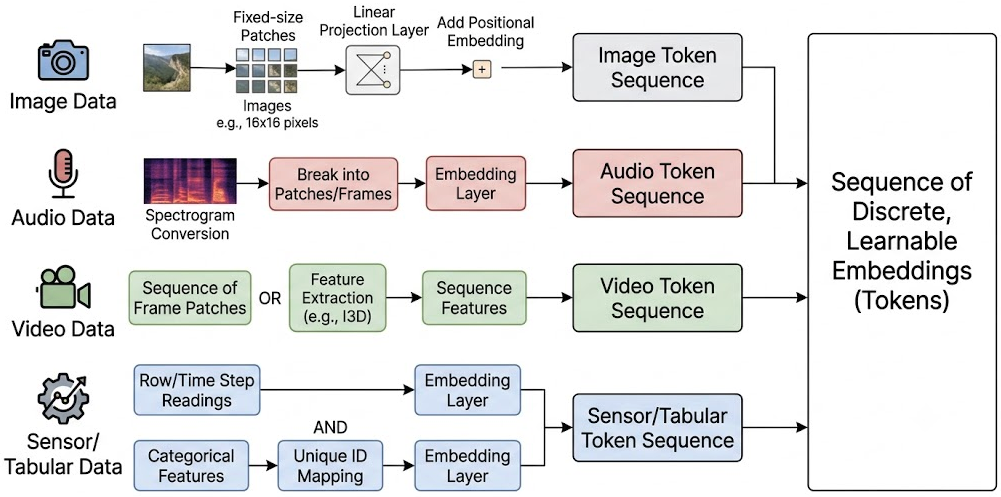 - For Images: Break an image into fixed-size patches (e.g., 16x16 pixels), project each patch into an embedding space using a linear layer, and add positional embeddings. This is how Vision Transformers (ViT) work.
- For Audio: Convert audio into spectrograms, then break the spectrogram into time-frequency patches or frames, embedding each.
- For Video: Process video as sequences of image patches across time, or extract features from individual frames and sequence them.
- For Sensor/Tabular Data: Each time step's readings or each row's features can be embedded and treated as a token in a sequence. Categorical features can be mapped to unique IDs and embedded.
2. Embrace the Transformer Architecture- Problem: Traditional DNNs (CNNs for images, RNNs for sequences) have limitations in handling long-range dependencies or processing global context efficiently.
- Solution: Replace or augment your modality-specific front-end with a Transformer encoder-decoder architecture.
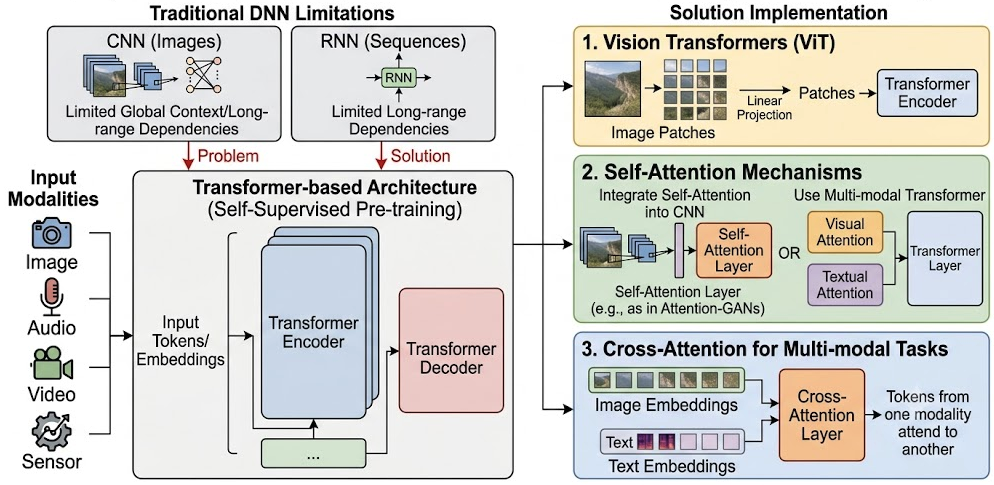 - Vision Transformers (ViT): Directly apply a Transformer encoder to image patches.
- Self-Attention Mechanisms: Integrate self-attention into existing CNNs (e.g., Attention-GANs) or use multi-modal transformers that combine visual and textual attention.
- Cross-Attention: For multi-modal tasks, use cross-attention layers where tokens from one modality (e.g., image embeddings) attend to tokens from another (e.g., text embeddings) and vice versa.
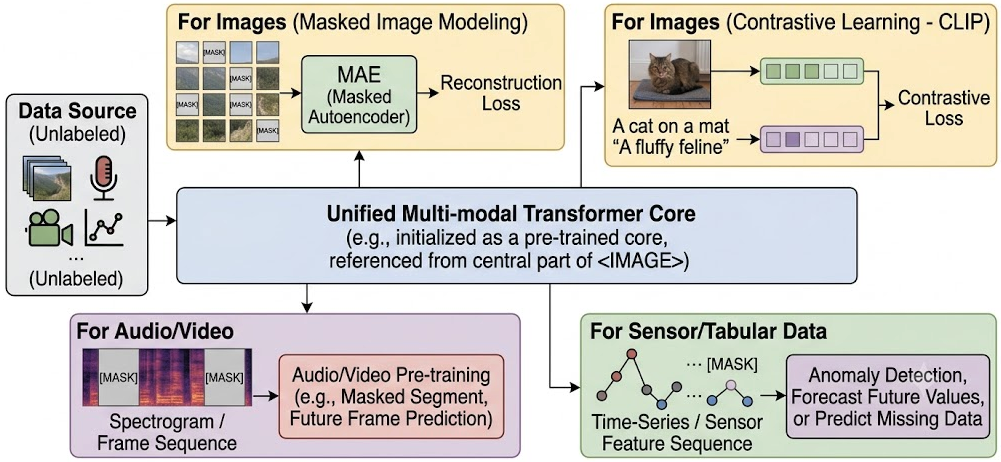
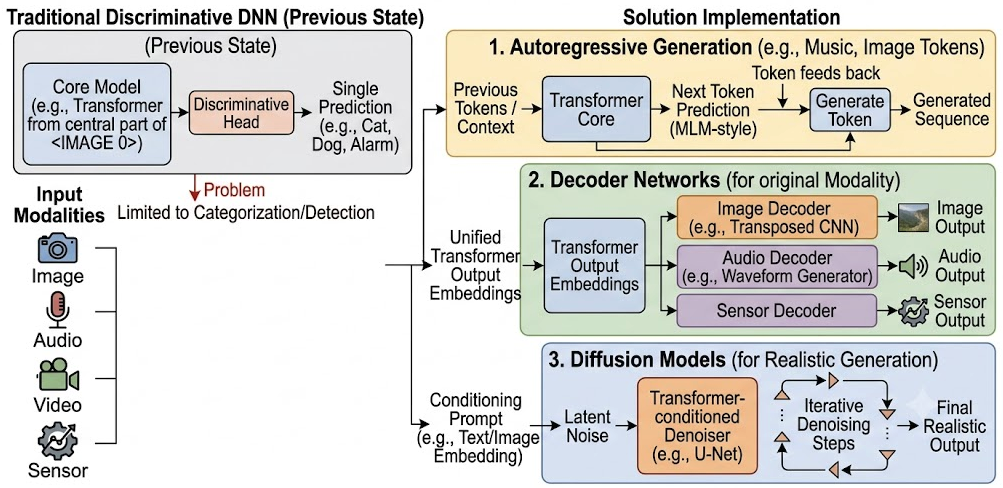
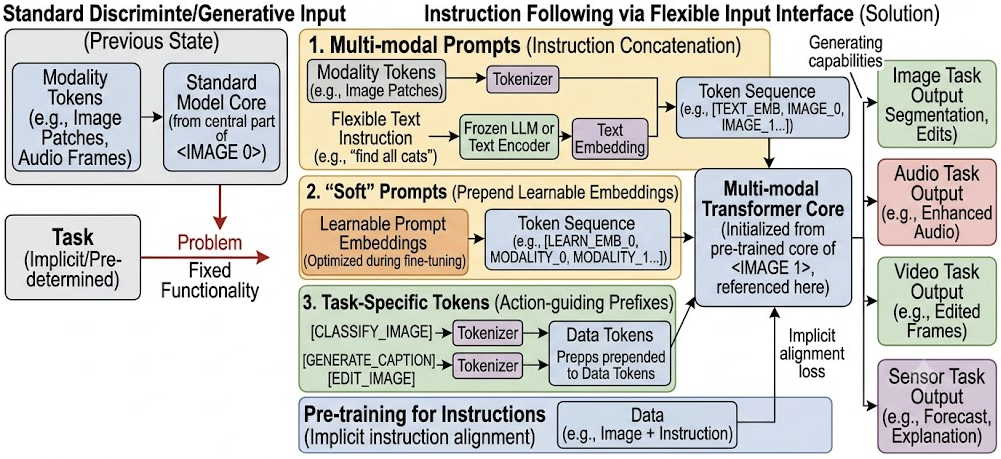
3. Large-Scale Self-Supervised Pre-training 4. Develop Generative Capabilities 5. Implement Prompt-Based Interaction (The "Instruction Following" Part) 6. Fine-tuning for Specific Tasks & Instruction Following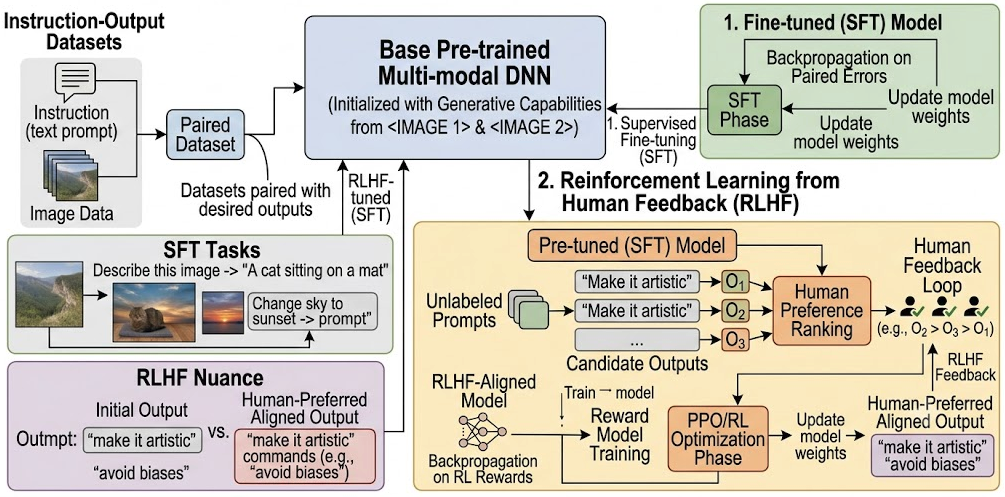
- Supervised Fine-tuning (SFT): Train the pre-trained model on datasets where specific instructions are paired with desired outputs (e.g., "Describe this image" -> "A cat sitting on a mat").
- Reinforcement Learning from Human Feedback (RLHF): Use human preferences to further align the model's outputs with human intentions and quality standards, making it better at following nuanced instructions (e.g., "make it more artistic").
Examples of DNNs Acting "Like LLMs":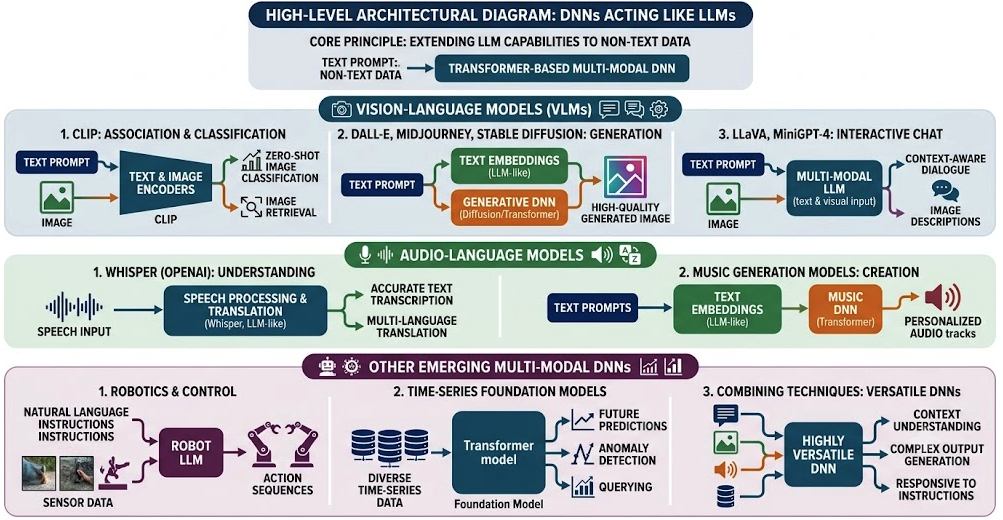
- Vision-Language Models (VLMs):
- CLIP: Learns to associate images with text descriptions, enabling zero-shot image classification and retrieval using text prompts.
- DALL-E, Midjourney, Stable Diffusion: Generate images from text prompts by mapping text embeddings to visual representations.
- LLaVA, MiniGPT-4: Multi-modal LLMs that take an image and a text prompt, allowing you to "chat" about images, ask questions, or generate descriptions.
- Audio-Language Models:
- Whisper (OpenAI): Not only transcribes speech to text but can also translate between languages, effectively understanding and processing spoken language like an LLM.
- Music Generation Models: Take text prompts (e.g., "a cheerful jazz piece with a piano solo") and generate audio.
- Robotics/Control: Using natural language instructions to control robots, where the robot's sensor data (images, depth, force) is processed by a "robot LLM" that can generate action sequences.
- Time-Series Foundation Models: Large Transformer models trained on diverse time-series data to predict future values, detect anomalies, or answer queries about the data.
By combining these techniques, you can build DNNs that are highly versatile, capable of understanding context, generating complex outputs, and responding to flexible instructions across various data modalities, much like a sophisticated LLM handles text. Development and Execution Environment for DNN on ArmDeveloping kernel-level DNN implementations for Arm requires a specialized environment that facilitates cross-compilation, hardware interaction, and efficient execution. Development Environment (Host PC)Typically, an x86-based workstation is used for development, with the Arm device acting as the target. 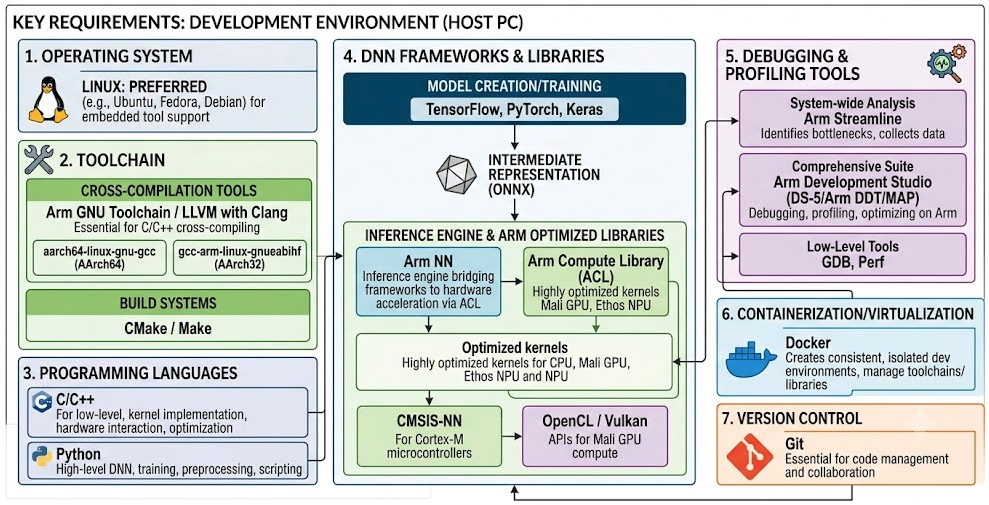
1. Operating System: - Linux: Preferred (e.g., Ubuntu, Fedora, Debian) due to strong support for embedded development tools, open-source libraries, and Arm toolchains.
2. Toolchain: - Arm GNU Toolchain / LLVM with Clang: Essential for cross-compiling C/C++ code for Arm targets. This includes
gcc-arm-linux-gnueabihf for 32-bit Arm (AArch32) and aarch64-linux-gnu-gcc for 64-bit Arm (AArch64). - CMake / Make: Build systems for managing compilation and linking processes.
3. Programming Languages: - C/C++: For low-level, kernel-level implementations, optimization, and interacting with hardware.
- Python: Often used for high-level DNN model development, training, data preprocessing, and scripting build/test processes.
4. DNN Frameworks and Libraries: - High-level Frameworks (for model creation/training): TensorFlow, PyTorch, Keras. Models are typically trained here and then exported.
- Intermediate Representation/Format: ONNX (Open Neural Network Exchange) is a common format for interoperability between frameworks and for deploying models.
- Arm-optimized Libraries:
- Arm Compute Library (ACL): Provides highly optimized low-level functions (kernels) for common DNN operations (e.g., convolutions, pooling, activation functions) for Arm CPUs, GPUs (Mali), and NPUs (Ethos). It's a key resource for "kernel-level implementations."
- Arm NN: An inference engine that bridges high-level DNN frameworks (like TensorFlow Lite, ONNX) with Arm's hardware acceleration (CPU, Mali GPU, Ethos NPU) by utilizing ACL.
- CMSIS-NN: Optimized for highly constrained Arm Cortex-M microcontrollers, focusing on small footprint and low power.
- OpenCL / Vulkan: APIs for programming Arm Mali GPUs for compute tasks.
5. Debugging and Profiling Tools: - Arm Development Studio (DS-5 / Arm DDT/MAP): A comprehensive suite for debugging, profiling, and optimizing code on Arm processors.
- Arm Streamline: A system-wide performance analyzer that collects data from Arm CPUs, GPUs, NPUs, and other system components to identify bottlenecks.
- GDB: GNU Debugger for low-level debugging.
- Perf: Linux profiling tool for CPU performance monitoring.
6. Containerization/Virtualization: - Docker: For creating consistent, isolated development environments, especially useful for managing toolchains and library versions.
7. Version Control: Git is essential for managing code changes and collaboration. Execution Environment (Target Arm Device)This refers to the actual Arm hardware where the optimized DNN models will run. 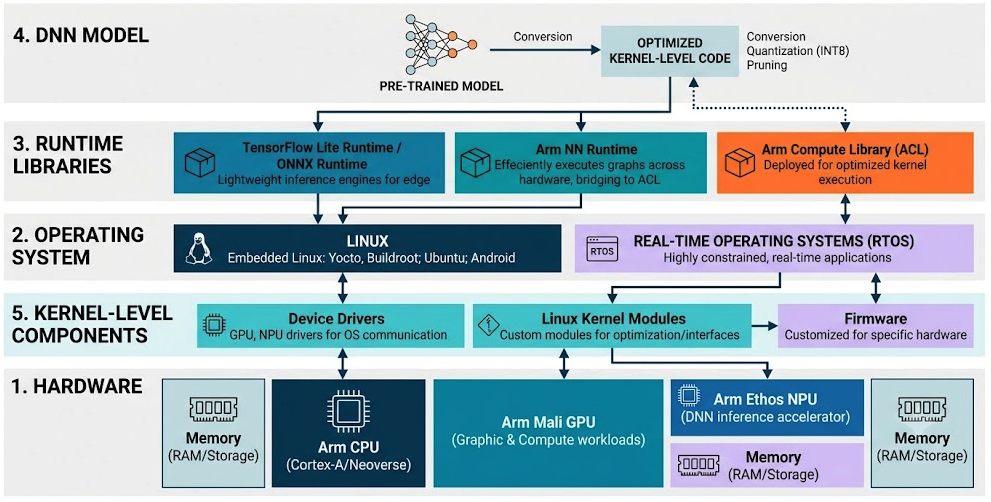
1. Hardware: - Arm CPU: Cortex-A series (e.g., Cortex-A53, A72, A76, X1, X2) for mobile, embedded, or edge devices; Arm Neoverse for servers/cloud.
- Arm Mali GPU: For accelerating graphic and compute workloads.
- Arm Ethos NPU (Neural Processing Unit): Dedicated hardware accelerators designed specifically for DNN inference.
- Memory: Sufficient RAM and storage for the operating system, runtime, and DNN models.
2. Operating System: - Linux: Embedded Linux distributions (e.g., Yocto Project, Buildroot), Ubuntu Server/Desktop (for more powerful boards like NVIDIA Jetson, Raspberry Pi 4), Android (for mobile).
- Real-time Operating Systems (RTOS): For highly constrained, real-time applications, potentially with specific DNN inference runtimes.
3. Runtime Libraries: - Arm Compute Library (ACL): Deployed on the target for optimized kernel execution.
- Arm NN Runtime: To execute DNN graphs efficiently across Arm hardware.
- Mali GPU Drivers: Essential for utilizing the Mali GPU via OpenCL/Vulkan.
- Ethos NPU Drivers: For interacting with the dedicated NPU.
- TensorFlow Lite Runtime / ONNX Runtime: Lightweight inference engines designed for edge devices.
4. DNN Model: - Pre-trained Model: The DNN model, often converted, quantized (e.g., to INT8), or pruned for deployment on the target device to reduce size and improve performance/power.
5. Kernel-level Components: - Device Drivers: For specific hardware accelerators (GPU, NPU) to enable communication between the operating system and the hardware.
- Linux Kernel Modules: Custom modules might be developed for specific hardware interfaces or to implement highly optimized, low-latency data paths relevant to DNN processing.
- Firmware: Potentially updated or customized firmware for specific hardware components.
Note that ARM processor cores don't store large training datasets, and while ARM-based systems have storage, it's typically for the trained model and operational data, not the original datasets. Test data is used for validation and is generally not re-used for future operational inference. Test Environment and Performance Verification for DNN on ArmSetting up a robust test environment and meticulously verifying performance and power are critical for kernel-level DNN optimization. 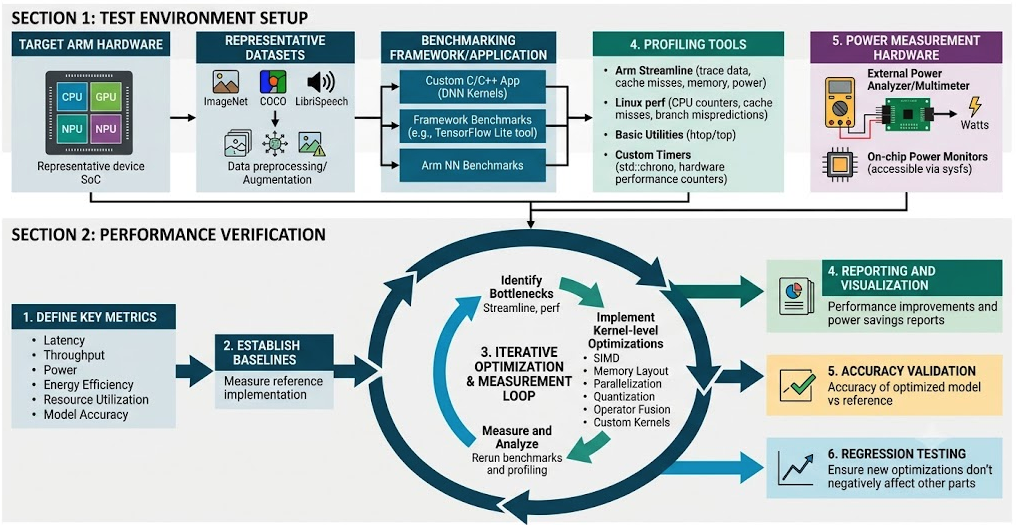
Test Environment Setup1. Target Arm Hardware: The actual Arm device (or a representative sample) where the DNN will be deployed. This is crucial as performance can vary significantly between different Arm SoCs.
2. Representative Datasets: - Use datasets that are typical for the DNN's intended application (e.g., ImageNet for classification, COCO for object detection, LibriSpeech for speech processing).
- Ensure data augmentation or preprocessing steps are consistent between training and testing.
3. Benchmarking Framework/Application: - Custom Applications: Develop C/C++ applications that load your optimized DNN kernels and models, feed them data, and measure execution time.
- Framework Benchmarks: Utilize built-in benchmarking tools from inference engines (e.g., TensorFlow Lite benchmark tool) if applicable.
- Arm NN Benchmarks: Arm NN provides benchmarking utilities to evaluate different backends (CPU, GPU, NPU).
4. Profiling Tools: - Arm Streamline: Connect to the target device to capture system-wide trace data including CPU core activity, GPU utilization, NPU activity, memory bandwidth, cache misses, and power (if hardware supports it).
- Linux
perf: For detailed CPU performance counter analysis (e.g., instruction count, cycles, cache misses, branch mispredictions). htop / top: Basic command-line utilities for monitoring CPU and memory usage.- Custom Timers: Integrate high-resolution timers (e.g.,
std::chrono in C++, time.perf_counter in Python, or hardware performance counters) directly into the DNN inference code to measure specific kernel latencies.
5. Power Measurement Hardware: - External Power Analyzer/Multimeter: For precise measurement of current and voltage, providing actual power consumption (Joules/Watts). This often requires breaking out power rails on a development board or using a dedicated power measurement setup.
- On-chip Power Monitors: Many modern Arm SoCs expose power consumption data via
sysfs or specialized APIs. While less precise than external hardware, they provide useful relative measurements.
Performance Verification1. Define Key Metrics: - Inference Latency: Time taken for a single forward pass through the DNN (e.g., milliseconds per image).
- Throughput: Number of inferences performed per unit of time (e.g., frames per second - FPS).
- Power Consumption: Average and peak power draw (Watts) during inference.
- Energy Efficiency: Energy consumed per inference (Joules/inference), or inferences per Joule. This is critical for battery-powered devices.
- Resource Utilization: Percentage of CPU, GPU, NPU cores utilized. Memory bandwidth usage.
- Model Accuracy: Crucially, ensuring that performance optimizations (especially quantization) do not lead to an unacceptable drop in model accuracy.
2. Establish Baselines: - Before optimization, measure the performance and power of a reference (unoptimized or off-the-shelf) implementation. This provides a baseline for comparison.
3. Iterative Optimization and Measurement Loop: - Identify Bottlenecks: Use profiling tools (Streamline,
perf) to pinpoint which DNN layers or operations consume the most time, CPU cycles, or memory bandwidth. Analyze memory access patterns, cache misses, and instruction stalls. - Implement Kernel-level Optimizations:
- SIMD (NEON, SVE/SVE2): Utilize Arm's Single Instruction, Multiple Data extensions for parallel processing of data.
- Memory Layout and Access: Optimize data structures and memory access patterns to improve cache locality.
- Parallelization: Implement multi-threading (e.g., OpenMP, Pthreads) for CPU-bound operations or offload to GPU/NPU.
- Quantization: Convert floating-point models to lower precision (e.g., INT8) to reduce memory footprint and enable faster execution on specialized hardware.
- Operator Fusion: Combine multiple DNN operations into a single, more efficient kernel.
- Custom Kernels: For specific, critical operations, write highly optimized custom kernels tailored to the Arm architecture.
- Measure and Analyze: After each significant optimization, re-run benchmarks and profiling. Compare against the baseline and previous iterations.
- Power Measurement: Systematically measure power consumption under different load conditions and optimizations.
4. Reporting and Visualization: - Generate reports and graphs to visualize performance improvements (latency, throughput) and power savings.
- Document the methodology, assumptions, and results clearly.
5. Accuracy Validation: - For any optimization that alters the numerical representation (like quantization), it's imperative to re-evaluate the model's accuracy on a validation dataset. Ensure the accuracy remains within acceptable bounds for the application.
6. Regression Testing: - Ensure that new optimizations do not negatively impact the performance or correctness of other parts of the DNN model or system.
|