| Kubernetes, often abbreviated as K8s, is an open-source system for automating deployment, scaling, and management of containerized applications. It groups containers that make up an application into logical units for easy management and discovery. Kubernetes provides a framework to run distributed systems resiliently, handling aspects like scaling, failover, deployment patterns, and more. 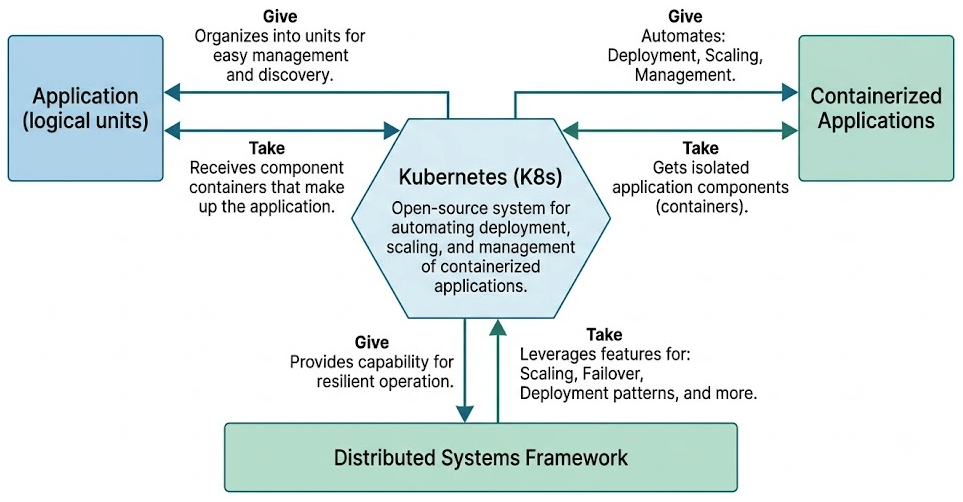
Origin and CreatorKubernetes was originally designed by Google and released as open-source in 2014. It was derived from Google's internal system called Borg (later Omega), which managed large clusters of machines and containerized applications for many years. Google then partnered with the Cloud Native Computing Foundation (CNCF) to help maintain and develop Kubernetes, making it a community-driven project. Key FeaturesKubernetes offers a robust set of features to manage containerized workloads: - Automated Rollouts & Rollbacks: Automatically deploy new versions of applications or roll back to a previous version if something goes wrong.
- Self-Healing: Automatically restarts failed containers, replaces and reschedules containers when nodes die, and kills containers that don't respond to user-defined health checks.
- Service Discovery & Load Balancing: Kubernetes can expose a container using a DNS name or its own IP address. If traffic to a container is high, Kubernetes can load balance it and distribute the network traffic so that the deployment is stable.
- Storage Orchestration: Automatically mounts a storage system of your choice, such as local storage, public cloud providers (GCP, AWS, Azure), or a network storage system (NFS, iSCSI, Ceph, Cinder, GlusterFS, etc.).
- Secret & Configuration Management: Stores and manages sensitive information like passwords, OAuth tokens, and SSH keys. It can deploy and update configurations without rebuilding your container images and without exposing secrets in your stack configuration.
- Automatic Bin Packing: Automatically places containers on nodes based on their resource requirements (CPU, memory) and other constraints, while not sacrificing availability.
- Batch Execution: Manages batch and CI workloads, replacing failed containers if desired.
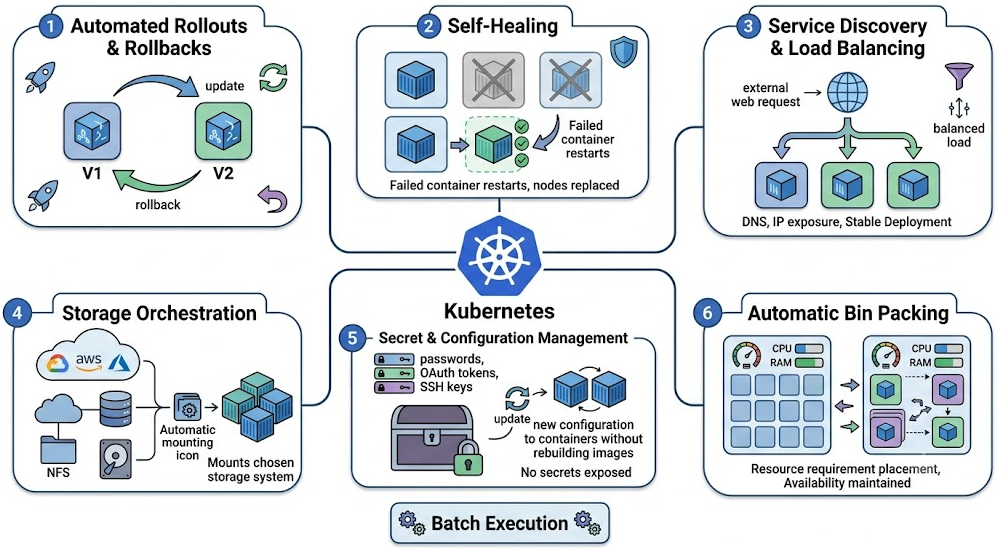
Kubernetes automates the mechanics of a rollout based on declared deployment strategies, efficiently managing updates to reach the desired state, and can execute rollbacks when explicitly instructed. However, the decision-making logic to automatically trigger a rollback in response to application failures or degraded performance typically resides outside of core Kubernetes controllers, requiring human-defined configurations, monitoring systems, or external CI/CD pipelines to provide that intelligence.
Why Use Kubernetes?Kubernetes addresses critical challenges faced when operating modern, distributed applications at scale: - Scalability: Easily scale applications up or down based on demand, either manually or automatically.
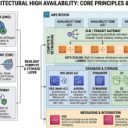
- High Availability & Resilience: Ensures applications remain available even if individual containers or nodes fail, by automatically detecting and replacing failures.
- Portability: Runs consistently across different environments—on-premises, public clouds (AWS, Azure, GCP), or hybrid setups—preventing vendor lock-in.
- Efficiency: Optimizes resource utilization by intelligently scheduling containers across a cluster, leading to cost savings.
- Simplified Operations: Automates many manual processes involved in deploying, managing, and scaling applications, freeing up operational teams.
- Developer Agility: Provides a consistent environment for developers to deploy and test their applications, accelerating release cycles.
How to Use KubernetesUsing Kubernetes primarily involves defining the desired state of your applications and infrastructure using declarative configuration files (typically YAML or JSON), and then applying these configurations to a Kubernetes cluster using the kubectl command-line tool. 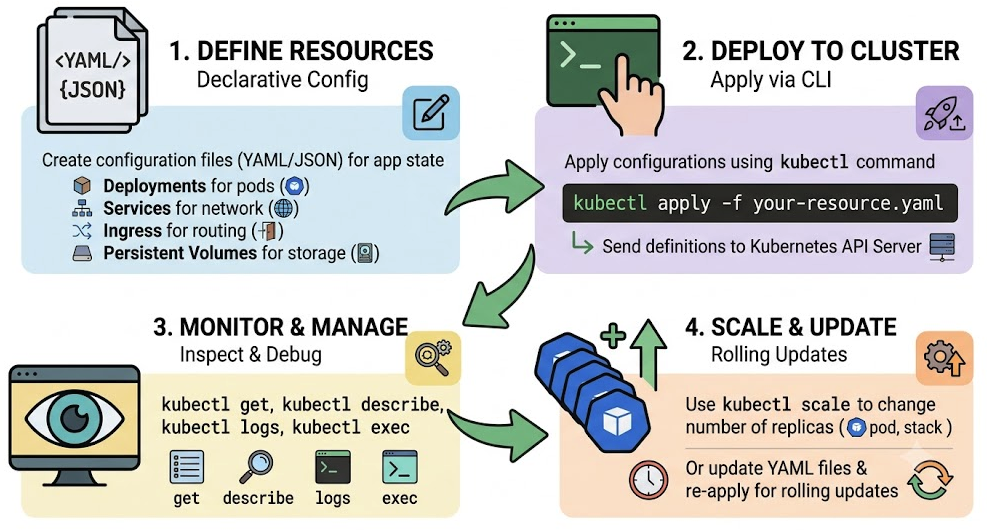
- Define Resources: Create YAML files that describe your applications (e.g., Deployments for pods, Services for network access, Ingress for external routing, Persistent Volumes for storage).
- Deploy to Cluster: Use
kubectl apply -f your-resource.yaml to send these definitions to the Kubernetes API server. - Monitor & Manage: Use
kubectl get, kubectl describe, kubectl logs, and kubectl exec to inspect, debug, and interact with your running applications. - Scale & Update: Use
kubectl scale to change the number of replicas, or update your YAML files and re-apply them for rolling updates.
The most fundamental and core flow in Kubernetes is to define and apply your desired state (YAML) and then get the current state, a method Kubernetes calls Declarative Management. However, when operating services stably in the real world, relying solely on apply and get proves insufficient, and the true power of Kubernetes is unleashed through its additional extended engineering features, which can be broadly categorized into five core areas.
Simple Usage Example 1. Deploying a Nginx Web ServerThis example deploys a simple Nginx web server and exposes it. nginx-deployment.yaml:
apiVersion: apps/v1
kind: Deployment
metadata:
  name: nginx-deployment
spec:
  selector:
    matchLabels:
      app: nginx
  replicas: 2 # Run two instances of Nginx
  template:
    metadata:
      labels:
        app: nginx
    spec:
      containers:
      - name: nginx
        image: nginx:latest # Use the latest Nginx image
        ports:
        - containerPort: 80
nginx-service.yaml:
apiVersion: v1
kind: Service
metadata:
  name: nginx-service
spec:
  selector:
    app: nginx # Selects pods with the label 'app: nginx'
  ports:
    - protocol: TCP
      port: 80 # The port the service exposes
      targetPort: 80 # The port the container listens on
  type: LoadBalancer # Exposes the service externally using a cloud provider's load balancer
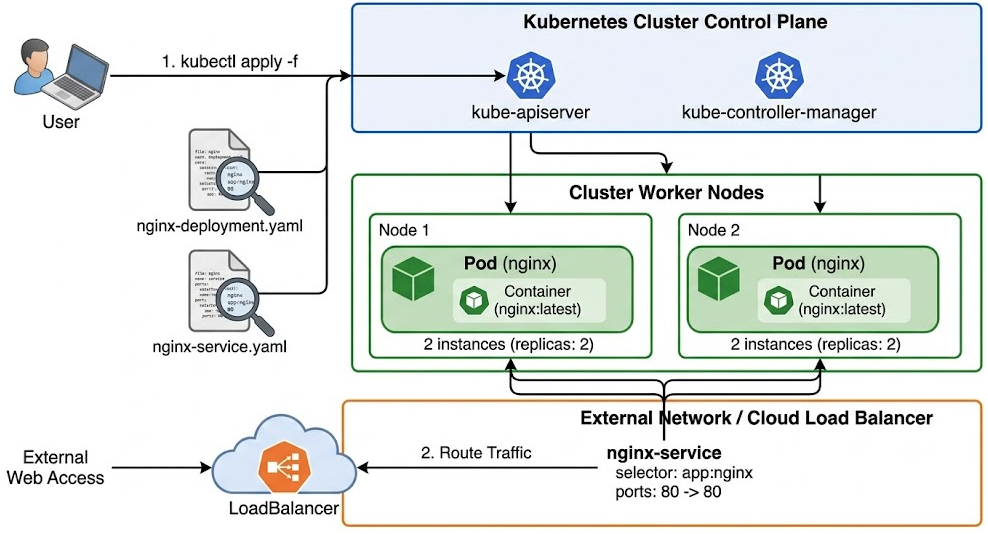
Steps: - Apply the deployment:
kubectl apply -f nginx-deployment.yaml - Apply the service:
kubectl apply -f nginx-service.yaml - Check the deployment status:
kubectl get deployments - Check the service to get its external IP:
kubectl get services
(You might need to wait a moment for the EXTERNAL-IP to be assigned by your cloud provider.)
Scaling an Application
Once the Nginx deployment is running, you can easily scale it.
To scale the Nginx deployment to 5 replicas: kubectl scale deployment/nginx-deployment --replicas=5
To scale down to 1 replica: kubectl scale deployment/nginx-deployment --replicas=1
Kubernetes is said to have a core feature that allows the system to survive and adjust on its own without requiring constant user intervention. How does it know if a container is dead or alive? Don't you need to set some conditions beforehand?Kubernetes determines if a container is alive or dead through configurable health checks called probes. Liveness probes detect when a container has entered a failed state and should be restarted, ensuring the system can self-heal. Readiness probes indicate whether a container is ready to serve traffic, allowing Kubernetes to direct requests only to healthy instances. Additionally, startup probes can be used for applications that take a long time to initialize. These conditions, including the type of check, such as HTTP GET, TCP socket check, or executing a command, along with thresholds and intervals, must indeed be predefined by the user within the pod specification for each container. 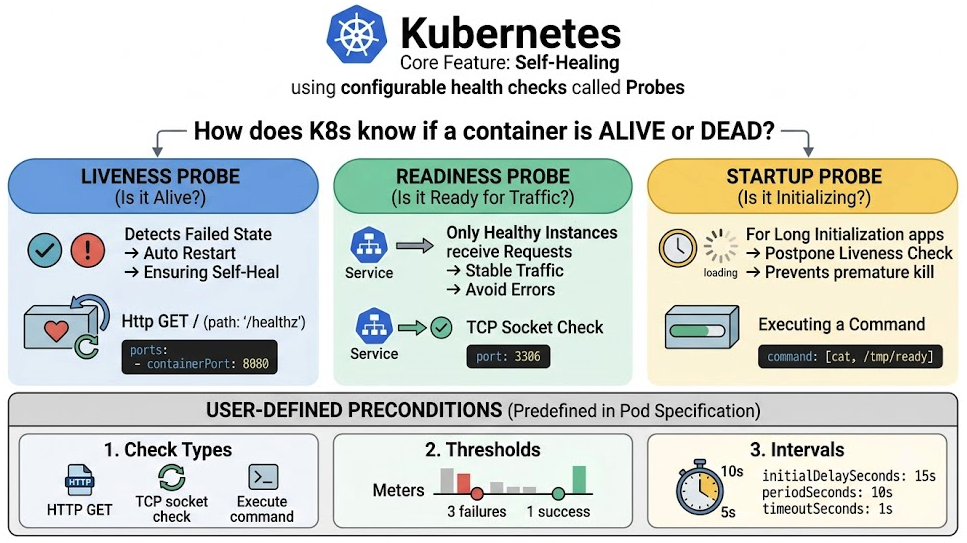
Simple Usage Example 2. Shopping Mall Application ExampleConsider a large online shopping mall with millions of users and a wide range of products. Such an application is typically built using a microservices architecture, where each business capability (e.g., user authentication, product catalog, order processing, payment, recommendation engine) is a separate, independently deployable service. Kubernetes is an ideal platform for managing this complexity: 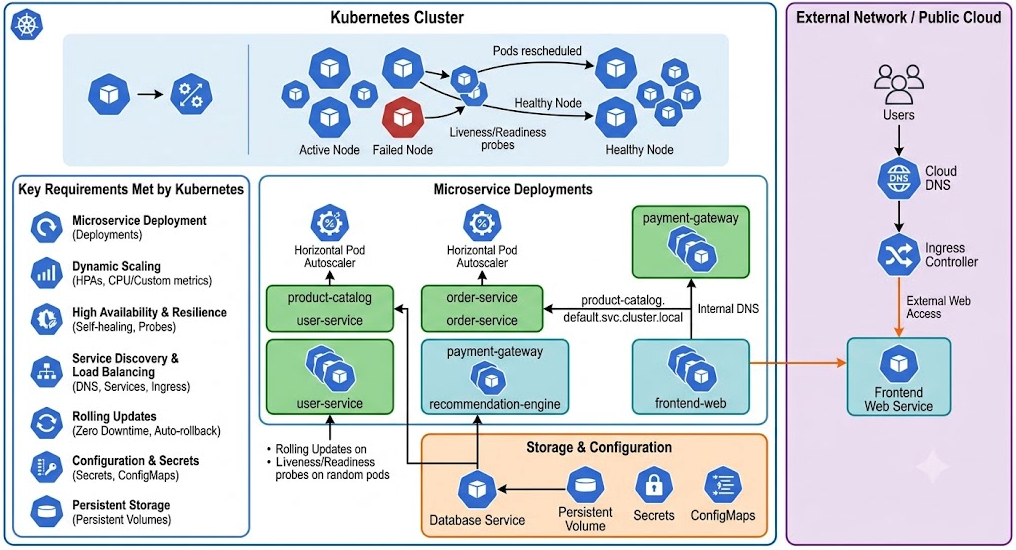
- Microservice Deployment: Each service (e.g.,
user-service, product-catalog, order-service, payment-gateway, recommendation-engine, frontend-web) is deployed as a separate Kubernetes Deployment. This allows independent development, testing, and deployment for each service.- Dynamic Scaling:
- During seasonal sales (e.g., Black Friday), the
product-catalog and order-service might experience massive spikes in traffic. Kubernetes can be configured with Horizontal Pod Autoscalers (HPAs) to automatically increase the number of pods for these services based on CPU utilization or custom metrics (e.g., requests per second). - The
payment-gateway might need to scale up during peak checkout times, while the recommendation-engine might scale down during off-peak hours to save resources.
- High Availability and Resilience:
- If a server hosting several
order-service pods crashes, Kubernetes automatically detects the failure and reschedules those pods onto healthy nodes, ensuring continuous order processing. - Readiness probes ensure that only healthy instances of services receive traffic, and liveness probes automatically restart containers that become unresponsive.
- Service Discovery and Load Balancing:
- The
frontend-web service needs to communicate with the product-catalog service. Kubernetes' internal DNS system allows services to discover each other using simple names (e.g., product-catalog.default.svc.cluster.local). - A Kubernetes Service exposes each microservice, automatically load-balancing incoming requests across all healthy pods of that service. An Ingress controller manages external access to the
frontend-web and API gateway services.
- Rolling Updates with Zero Downtime:
- When the
user-service needs an update (e.g., new login feature), Kubernetes performs a rolling update. It gradually replaces old pods with new ones, ensuring that there are always active user-service instances available to handle user authentication, preventing any downtime during the update. If the new version has issues, it can automatically roll back.
- Configuration and Secrets Management:
- Database connection strings, API keys for external payment providers, and various feature flags for different services are stored securely as Kubernetes Secrets and ConfigMaps, injected into the respective service pods at runtime.
- Persistent Storage:
- For stateful services like a database (e.g., a customer database or product inventory database), Kubernetes can provision Persistent Volumes from underlying storage systems (cloud provider disks, NFS, etc.) and attach them to the database pods, ensuring data persistence even if the pods are restarted or moved.
By leveraging Kubernetes, the shopping mall application can efficiently manage its complex microservices, ensuring high availability, scalability, and faster feature delivery, which are critical for a competitive e-commerce business. If you were to write a large-scale microservice architecture, such as for a shopping mall, all into a single file, it would become a huge and complex YAML file exceeding thousands of lines.
In my current work, to address this, we manage files by separating them or using automation tools. Here are three commonly used architecture management methods: 1. Service-specific File Separation (Most Basic)Instead of putting all configurations into a single file, we manage them by splitting folders and files on a service-by-service basis. frontend/deployment.yaml, frontend/service.yamlorder/deployment.yaml, order/service.yaml, order/hpa.yaml
When deploying, you can apply them all at once by issuing a command at the folder level, like kubectl apply -f order/. 2. Helm (The Package Manager for Kubernetes)Just like downloading an app from an app store, we most frequently use a tool called Helm, which packages Kubernetes configurations.
Repetitive and complex YAML structures are created as a template just once.
Each service, such as user-service and order-service, is reused by only replacing core values like the name, image address, and port number (typically defined in a values.yaml file). This significantly reduces the amount of code that needs to be managed. 3. GitOps and CI/CD Tools (e.g., ArgoCD)It is risky for humans to directly view large YAML files and type commands (e.g., kubectl apply).
If you upload the separated YAML files to a Git repository, tools like ArgoCD detect changes in Git and automatically apply them to the Kubernetes cluster. |