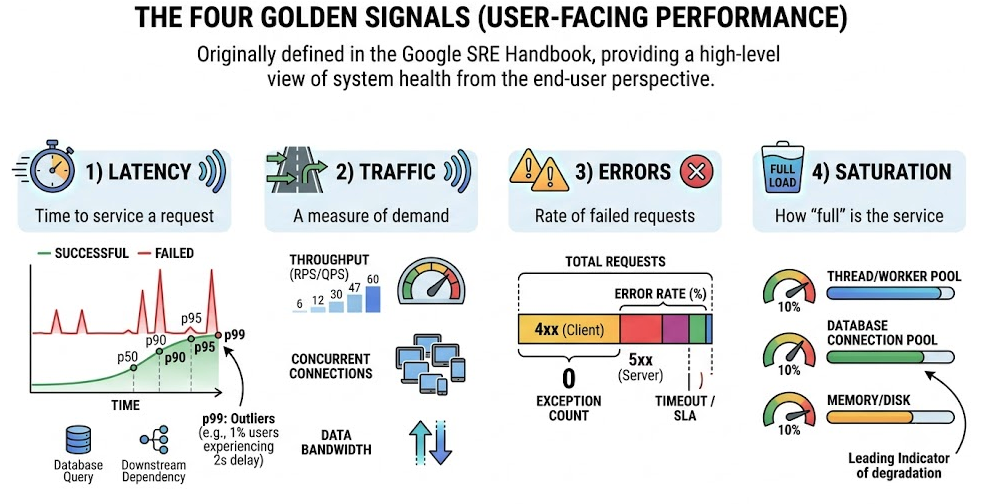
The Four Golden Signals (User-Facing Performance)Originally defined in the Google SRE Handbook, these metrics provide a high-level view of system health from the perspective of the end-user. 1) LatencyThe time it takes to service a request. It is critical to measure the latency of successful requests separately from failed requests. - Key Percentiles (p50, p90, p95, p99): Do not rely on averages, as they mask outliers. A p99 latency of 2 seconds means 1% of your users (which could be millions) are experiencing severe delays.
- Database Query Latency: Time taken to execute read/write operations.
- Downstream Dependency Latency: Time spent waiting for third-party APIs or internal microservices to respond.
2) TrafficA measure of how much demand is being placed on your system. - Throughput (RPS/QPS): Requests Per Second or Queries Per Second.
- Concurrent Connections: The number of active sessions or open TCP connections.
- Data Bandwidth: Input/output bytes per second moving through the network.
3) ErrorsThe rate of requests that fail, either explicitly (e.g., HTTP 500), implicitly (e.g., HTTP 200 but with an empty/wrong payload), or by policy (e.g., a request that took longer than a specified SLA timeout). - Error Rate: Percentage of total requests that result in errors.
- HTTP Status Codes: Monitoring the distribution of 4xx (client-side) and 5xx (server-side) errors.
- Exception Count: Frequency of unhandled exceptions logged by the application.
4) SaturationA measure of how "full" your service is. It points to the most constrained system resources and acts as a leading indicator of performance degradation. - Thread/Worker Pool Saturation: The percentage of available execution threads currently in use.
- Database Connection Pool Utilization: The ratio of active DB connections to the maximum limit.
- Memory/Disk Saturation: How close the system is to running out of physical limits.
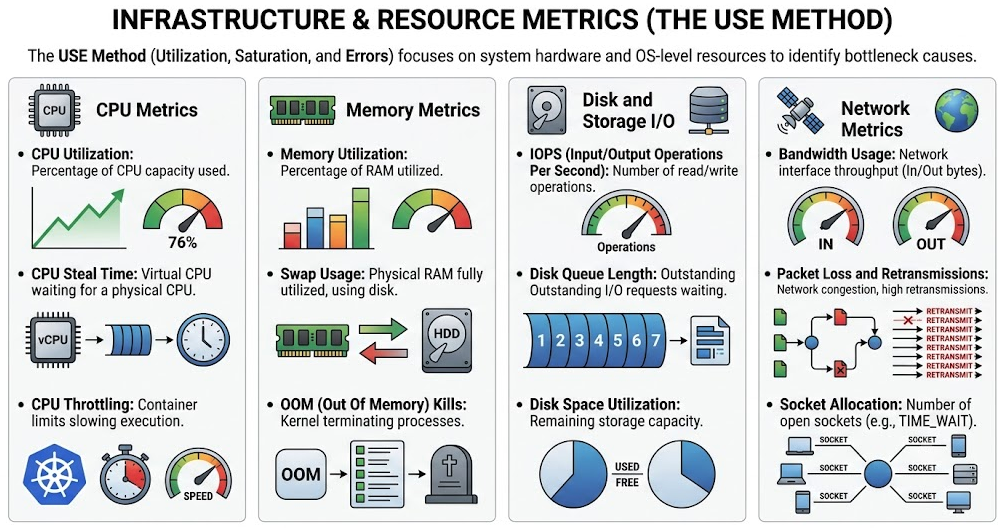
Infrastructure & Resource Metrics (The USE Method)The USE Method (Utilization, Saturation, and Errors) focuses on system hardware and OS-level resources to identify bottleneck causes. 1) CPU Metrics- CPU Utilization: The percentage of CPU capacity currently being used.
- CPU Steal Time: In virtualized/cloud environments, the time a virtual CPU waits for a physical CPU (indicates "noisy neighbors").
- CPU Throttling: Especially relevant in containerized environments (like Kubernetes), where CPU limits can cause container execution to be intentionally slowed down.
2) Memory Metrics- Memory Utilization: Percentage of RAM utilized.
- Swap Usage: Indicates that physical RAM is fully utilized and the system is reading/writing to slower disk space.
- OOM (Out Of Memory) Kills: Events where the OS kernel terminates processes to free up memory.
3) Disk and Storage I/O- IOPS (Input/Output Operations Per Second): The number of read/write operations.
- Disk Queue Length: The number of outstanding I/O requests waiting to be serviced.
- Disk Space Utilization: Remaining storage capacity. Running out of disk space often causes database and logging writes to fail immediately.
4) Network Metrics- Bandwidth Usage: Network interface throughput (In/Out bytes).
- Packet Loss and Retransmissions: High retransmissions indicate network congestion or faulty hardware.
- Socket Allocation: Number of open sockets in states like
TIME_WAIT or ESTABLISHED.
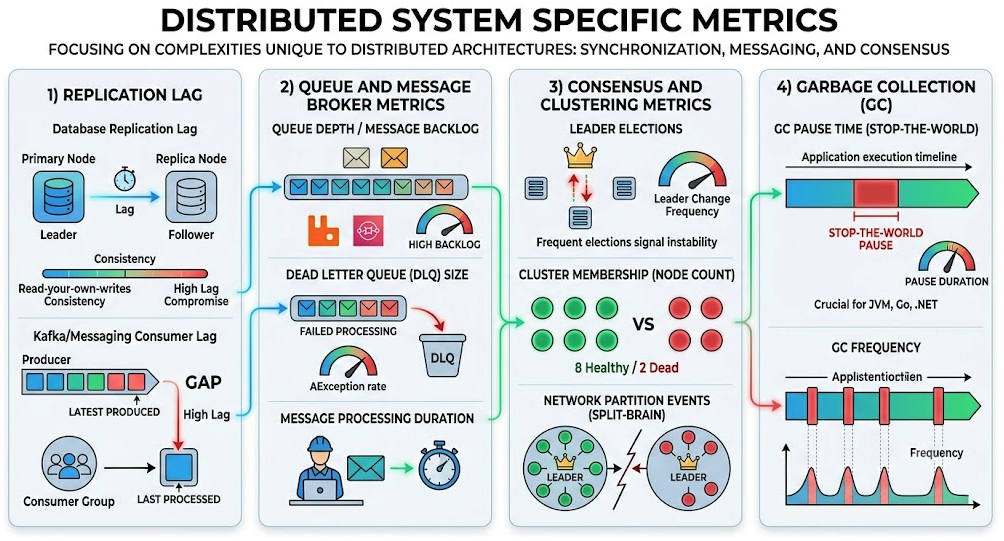
Distributed System Specific MetricsThese metrics focus on the complexities unique to distributed architectures, such as state synchronization, messaging, and consensus. 1) Replication Lag- Database Replication Lag: The time delay between data being written to the primary/leader node and being copied to replica/follower nodes. High lag compromises read-your-own-writes consistency.
- Kafka/Messaging Consumer Lag: The gap between the latest produced message and the last processed message by a consumer group. High lag indicates processing bottlenecks.
2) Queue and Message Broker Metrics- Queue Depth / Message Backlog: The number of messages waiting to be processed in queues (e.g., RabbitMQ, SQS).
- Dead Letter Queue (DLQ) Size: The rate of messages failing processing and being routed to the DLQ.
- Message Processing Duration: The time it takes for a worker to successfully process a single message from the queue.
3) Consensus and Clustering Metrics- Leader Elections: The frequency of leader changes in systems using consensus protocols (e.g., Raft, Paxos, ZooKeeper). Frequent elections signal network instability or node crashes.
- Cluster Membership (Node Count): Number of active, healthy nodes vs. dead nodes in a cluster.
- Network Partition Events (Split-Brain): Detection of cluster fragmentation where sub-clusters lose contact with each other.
4) Garbage Collection (GC)- GC Pause Time (Stop-the-World): The duration for which application execution is halted to free memory (crucial for JVM, Go, and .NET applications). Long pauses mimic node crashes and trigger false-positive failovers.
- GC Frequency: How often garbage collection cycles occur.
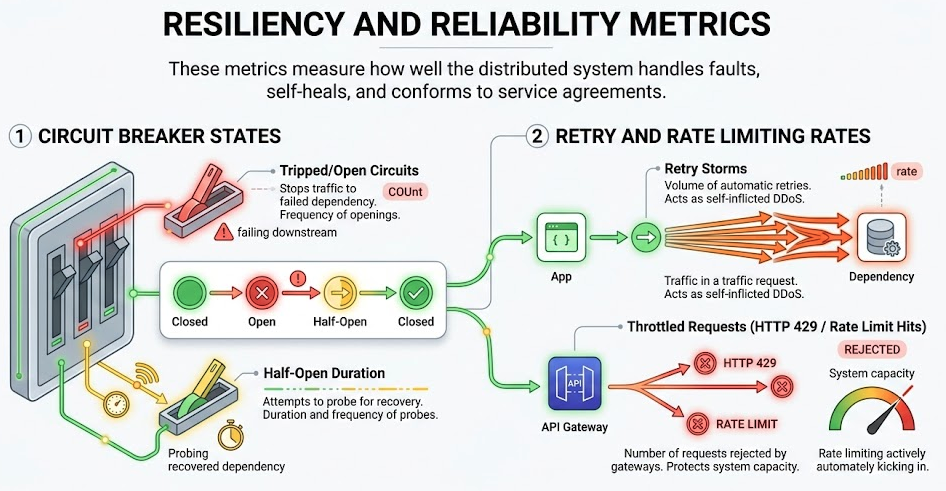
Resiliency and Reliability MetricsThese metrics measure how well the distributed system handles faults, self-heals, and conforms to service agreements. 1) Circuit Breaker States- Tripped/Open Circuits: How often circuit breakers open to stop traffic to failing downstream dependencies.
- Half-Open Duration: The frequency of attempts to probe if a failed downstream dependency has recovered.
2) Retry and Rate Limiting Rates- Retry Storms: The volume of automatic retries. High retry rates can act as a self-inflicted Distributed Denial of Service (DDoS) on downstream components.
- Throttled Requests (HTTP 429 / Rate Limit Hits): The number of requests rejected by API gateways or rate limiters to protect system capacity.
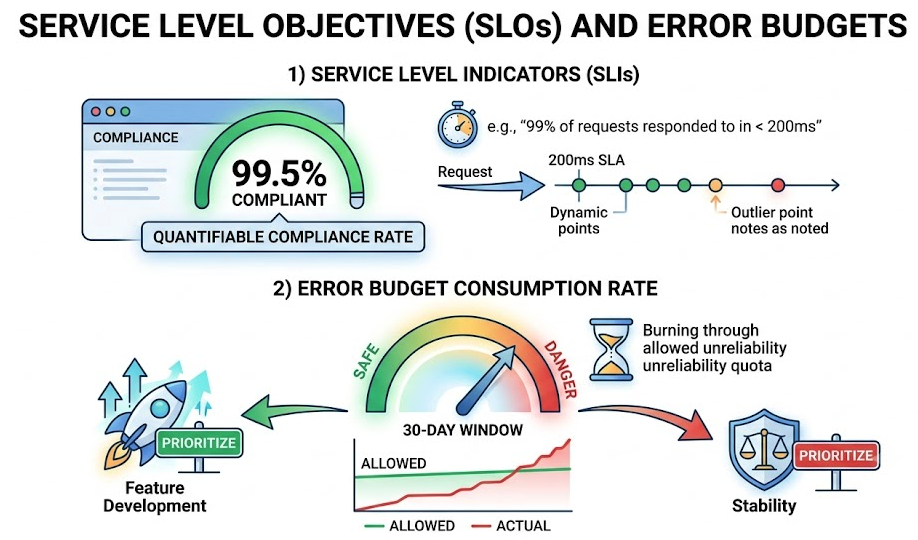
Service Level Objectives (SLOs) and Error Budgets- Service Level Indicators (SLIs): The quantifiable compliance rate of your service (e.g., "99% of requests responded to in < 200ms").
- Error Budget Consumption Rate: How fast the system is burning through its allowed unreliability quota over a 30-day window. This dictates whether to prioritize feature development or stability.
|