| This guide will walk you through installing Java and Apache Kafka on a CentOS 7 system, followed by providing three simple Java examples to interact with Kafka. 1. System Setup and PrerequisitesBefore installing Java and Kafka, ensure your system is up-to-date and necessary utilities are present. 1.1 Update SystemIt's always a good practice to update your system's package index and installed packages. sudo yum update -y
1.2 Install wget and tarThese utilities are essential for downloading and extracting files. They are usually pre-installed on CentOS, but it's good to ensure. sudo yum install -y wget tar
2. Java (OpenJDK) InstallationApache Kafka requires Java to run. OpenJDK 11 is a good, modern Long-Term Support (LTS) version to use. 2.1 Install OpenJDK 11sudo yum install -y java-11-openjdk-devel
2.2 Set JAVA_HOME (Optional but Recommended)Setting the JAVA_HOME environment variable is a good practice for many Java applications and build tools. # Find the actual Java installation path (e.g., /usr/lib/jvm/java-11-openjdk-11.x.x.x-x.el7.x86_64)
# You might need to adjust the path based on your installation.
# A common path for OpenJDK 11 installed via yum is: /usr/lib/jvm/java-11-openjdk
echo "export JAVA_HOME=$(dirname $(dirname $(readlink -f /usr/bin/java)))" | sudo tee -a /etc/profile.d/java.sh
echo "export PATH=\$PATH:\$JAVA_HOME/bin" | sudo tee -a /etc/profile.d/java.sh
source /etc/profile.d/java.sh
2.3 Verify Java Installationjava -version
You should see output similar to this: openjdk version "11.0.x" ...
OpenJDK Runtime Environment (build 11.0.x+y)
OpenJDK 64-Bit Server VM (build 11.0.x+y, mixed mode, sharing)
3. Apache Kafka InstallationApache Kafka relies on Apache Zookeeper for cluster management. We'll install both. 3.1 Download Apache KafkaNavigate to /opt or a similar directory for server software and download a stable Kafka version. (Using 3.6.1 as of writing). cd /opt
wget https://downloads.apache.org/kafka/3.6.1/kafka_2.13-3.6.1.tgz
3.2 Extract Apache Kafkatar -xzf kafka_2.13-3.6.1.tgz
mv kafka_2.13-3.6.1 kafka
3.3 Configure Kafka (Optional Basic Tweaks)By default, Kafka uses port 9092 and Zookeeper uses 2181. The default configurations are usually sufficient for a quick setup.
However, you might want to adjust log.dirs for Zookeeper and Kafka to a more dedicated location. # Zookeeper configuration
sudo mkdir -p /var/lib/zookeeper
sudo chown -R $USER:$USER /var/lib/zookeeper # Ensure permissions if not running as root
# Kafka configuration
sudo mkdir -p /var/lib/kafka
sudo chown -R $USER:$USER /var/lib/kafka # Ensure permissions
# Edit Zookeeper config to use /var/lib/zookeeper
sed -i 's/^dataDir=.*/dataDir=\/var\/lib\/zookeeper/' /opt/kafka/config/zookeeper.properties
# Edit Kafka config to use /var/lib/kafka
sed -i 's/^log.dirs=.*/log.dirs=\/var\/lib\/kafka/' /opt/kafka/config/server.properties
3.4 Start ZookeeperZookeeper must be running before Kafka can start.
We'll run it in the background using nohup. cd /opt/kafka
nohup bin/zookeeper-server-start.sh config/zookeeper.properties > zookeeper.log 2>&1 &
3.4.1 Verify ZookeeperCheck the Zookeeper log file for "binding to port". tail -f zookeeper.log
# Look for "binding to port /0.0.0.0:2181"
You can also check if the port is listening: netstat -tulnp | grep 2181
3.5 Start Kafka BrokerOnce Zookeeper is up, start the Kafka broker. cd /opt/kafka
nohup bin/kafka-server-start.sh config/server.properties > kafka.log 2>&1 &
3.5.1 Verify Kafka BrokerCheck the Kafka log file for "started". tail -f kafka.log
# Look for "KafkaServer id:0 started"
You can also check if the port is listening: netstat -tulnp | grep 9092
4. Kafka Topic ManagementBefore running Java applications, you need to create a Kafka topic for messages. 4.1 Create a TopicLet's create a topic named my-first-topic with one partition and one replica. cd /opt/kafka
bin/kafka-topics.sh --create --topic my-first-topic --bootstrap-server localhost:9092 --partitions 1 --replication-factor 1
4.2 List Topicsbin/kafka-topics.sh --list --bootstrap-server localhost:9092
4.3 Describe Topicbin/kafka-topics.sh --describe --topic my-first-topic --bootstrap-server localhost:9092
5. Java Examples with Apache KafkaWe'll use Maven to manage our Java project and dependencies. 5.1 Project Setup (Maven pom.xml)First, create a new directory for your Java project. mkdir ~/kafka-java-examples
cd ~/kafka-java-examples
Create a pom.xml file with the following content: <?xml version="1.0" encoding="UTF-8"?>
<project xmlns="http://maven.apache.org/POM/4.0.0"
xmlns:xsi="http://www.w3.org/2001/XMLSchema-instance"
xsi:schemaLocation="http://maven.apache.org/POM/4.0.0 http://maven.apache.org/xsd/maven-4.0.0.xsd">
<modelVersion>4.0.0</modelVersion>
<groupId>com.example.kafka</groupId>
<artifactId>kafka-java-examples</artifactId>
<version>1.0-SNAPSHOT</version>
<properties>
<maven.compiler.source>11</maven.compiler.source>
<maven.compiler.target>11</maven.compiler.target>
<project.build.sourceEncoding>UTF-8</project.build.sourceEncoding>
</properties>
<dependencies>
<dependency>
<groupId>org.apache.kafka</groupId>
<artifactId>kafka-clients</artifactId>
<version>3.6.1</version> <!-- Match with your Kafka server version or use a compatible client -->
</dependency>
<!-- Optional: SLF4J for logging, if you want to see Kafka client logs -->
<dependency>
<groupId>org.slf4j</groupId>
<artifactId>slf4j-simple</artifactId>
<version>2.0.7</version>
</dependency>
</dependencies>
<build>
<plugins>
<plugin>
<groupId>org.apache.maven.plugins</groupId>
<artifactId>maven-compiler-plugin</artifactId>
<version>3.8.1</version>
<configuration>
<source>${maven.compiler.source}</source>
<target>${maven.compiler.target}</target>
</configuration>
</plugin>
<plugin>
<groupId>org.codehaus.mojo</groupId>
<artifactId>exec-maven-plugin</artifactId>
<version>3.0.0</version>
<configuration>
<mainClass>${exec.mainClass}</mainClass>
</configuration>
</plugin>
</plugins>
</build>
</project>
Create the source directory structure: mkdir -p src/main/java/com/example/kafka
5.2 Example 1: Simple Kafka Producer5.2.1 DescriptionThis example demonstrates how to send a single string message to a Kafka topic. It sets up basic producer properties, creates a ProducerRecord, and sends it asynchronously. 5.2.2 Java Code (SimpleProducer.java)Create src/main/java/com/example/kafka/SimpleProducer.java: package com.example.kafka;
import org.apache.kafka.clients.producer.KafkaProducer;
import org.apache.kafka.clients.producer.ProducerConfig;
import org.apache.kafka.clients.producer.ProducerRecord;
import org.apache.kafka.common.serialization.StringSerializer;
import java.util.Properties;
public class SimpleProducer {
private static final String BOOTSTRAP_SERVERS = "localhost:9092";
private static final String TOPIC = "my-first-topic";
public static void main(String[] args) {
// 1. Configure Producer Properties
Properties props = new Properties();
props.setProperty(ProducerConfig.BOOTSTRAP_SERVERS_CONFIG, BOOTSTRAP_SERVERS);
props.setProperty(ProducerConfig.KEY_SERIALIZER_CLASS_CONFIG, StringSerializer.class.getName());
props.setProperty(ProducerConfig.VALUE_SERIALIZER_CLASS_CONFIG, StringSerializer.class.getName());
// 2. Create the Kafka Producer
KafkaProducer<String, String> producer = new KafkaProducer<>(props);
// 3. Create a Producer Record (message)
String key = "messageKey"; // Optional: for partitioning
String value = "Hello Kafka from Java!";
ProducerRecord<String, String> record = new ProducerRecord<>(TOPIC, key, value);
// 4. Send the message
System.out.println("Sending message: " + value + " to topic: " + TOPIC);
producer.send(record, (metadata, exception) -> {
if (exception == null) {
System.out.println("Message sent successfully!");
System.out.println("Topic: " + metadata.topic() + ", Partition: " + metadata.partition() +
", Offset: " + metadata.offset() + ", Timestamp: " + metadata.timestamp());
} else {
System.err.println("Error sending message: " + exception.getMessage());
}
});
// 5. Close the producer (flushes any unsent messages)
producer.close();
System.out.println("Producer closed.");
}
}
5.2.3 How to Runcd ~/kafka-java-examples
mvn compile
mvn exec:java -Dexec.mainClass="com.example.kafka.SimpleProducer"
5.3 Example 2: Simple Kafka Consumer5.3.1 DescriptionThis example demonstrates how to consume messages from a Kafka topic. It sets up basic consumer properties, subscribes to a topic, and polls for new records in a loop. 5.3.2 Java Code (SimpleConsumer.java)Create src/main/java/com/example/kafka/SimpleConsumer.java: package com.example.kafka;
import org.apache.kafka.clients.consumer.ConsumerConfig;
import org.apache.kafka.clients.consumer.ConsumerRecord;
import org.apache.kafka.clients.consumer.ConsumerRecords;
import org.apache.kafka.clients.consumer.KafkaConsumer;
import org.apache.kafka.common.serialization.StringDeserializer;
import java.time.Duration;
import java.util.Collections;
import java.util.Properties;
public class SimpleConsumer {
private static final String BOOTSTRAP_SERVERS = "localhost:9092";
private static final String TOPIC = "my-first-topic";
private static final String GROUP_ID = "my-java-consumer-group"; // A group ID is required
public static void main(String[] args) {
// 1. Configure Consumer Properties
Properties props = new Properties();
props.setProperty(ConsumerConfig.BOOTSTRAP_SERVERS_CONFIG, BOOTSTRAP_SERVERS);
props.setProperty(ConsumerConfig.KEY_DESERIALIZER_CLASS_CONFIG, StringDeserializer.class.getName());
props.setProperty(ConsumerConfig.VALUE_DESERIALIZER_CLASS_CONFIG, StringDeserializer.class.getName());
props.setProperty(ConsumerConfig.GROUP_ID_CONFIG, GROUP_ID);
// consumer.auto.offset.reset determines where to start reading if no offset is committed
// "earliest": read from the beginning of the topic
// "latest": read only new messages
// "none": throw exception if no offset committed
props.setProperty(ConsumerConfig.AUTO_OFFSET_RESET_CONFIG, "earliest");
// 2. Create the Kafka Consumer
KafkaConsumer<String, String> consumer = new KafkaConsumer<>(props);
// 3. Subscribe to the topic(s)
consumer.subscribe(Collections.singletonList(TOPIC));
System.out.println("Subscribed to topic: " + TOPIC);
// 4. Poll for new messages indefinitely
try {
while (true) {
// Poll for records with a timeout
ConsumerRecords<String, String> records = consumer.poll(Duration.ofMillis(100));
for (ConsumerRecord<String, String> record : records) {
System.out.println("Received message:");
System.out.println(" Key: " + record.key() +
", Value: " + record.value() +
", Topic: " + record.topic() +
", Partition: " + record.partition() +
", Offset: " + record.offset() +
", Timestamp: " + record.timestamp());
}
// Manually commit offsets (optional, auto-commit is enabled by default)
// consumer.commitSync();
}
} catch (Exception e) {
System.err.println("Error in consumer: " + e.getMessage());
} finally {
// 5. Close the consumer
consumer.close();
System.out.println("Consumer closed.");
}
}
}
5.3.3 How to RunRun the consumer. It will start listening. Then, in a separate terminal, run the producer. cd ~/kafka-java-examples
mvn compile
mvn exec:java -Dexec.mainClass="com.example.kafka.SimpleConsumer"
Keep this terminal open. In another terminal, run the SimpleProducer again. You should see the message appear in the SimpleConsumer's terminal. 5.4 Example 3: Kafka Consumer with Group5.4.1 DescriptionThis example highlights the concept of consumer groups in Kafka. When multiple consumers belong to the same group, Kafka ensures that each message is delivered to only one consumer within that group. If consumers are in different groups, they will each receive all messages. This demonstrates how to set up a consumer with a specific group.id. 5.4.2 Java Code (GroupConsumer.java)Create src/main/java/com/example/kafka/GroupConsumer.java: package com.example.kafka;
import org.apache.kafka.clients.consumer.ConsumerConfig;
import org.apache.kafka.clients.consumer.ConsumerRecord;
import org.apache.kafka.clients.consumer.ConsumerRecords;
import org.apache.kafka.clients.consumer.KafkaConsumer;
import org.apache.kafka.common.serialization.StringDeserializer;
import java.time.Duration;
import java.util.Collections;
import java.util.Properties;
import java.util.concurrent.atomic.AtomicBoolean;
public class GroupConsumer {
private static final String BOOTSTRAP_SERVERS = "localhost:9092";
private static final String TOPIC = "my-first-topic";
// This unique GROUP_ID identifies our consumer group
private static final String GROUP_ID = "my-group-consumer-app";
private final AtomicBoolean running = new AtomicBoolean(true);
public static void main(String[] args) {
// You can pass an argument to differentiate consumers in the same group
String consumerId = args.length > 0 ? args[0] : "Consumer-A";
new GroupConsumer().runConsumer(consumerId);
}
public void runConsumer(String consumerId) {
Properties props = new Properties();
props.setProperty(ConsumerConfig.BOOTSTRAP_SERVERS_CONFIG, BOOTSTRAP_SERVERS);
props.setProperty(ConsumerConfig.KEY_DESERIALIZER_CLASS_CONFIG, StringDeserializer.class.getName());
props.setProperty(ConsumerConfig.VALUE_DESERIALIZER_CLASS_CONFIG, StringDeserializer.class.getName());
props.setProperty(ConsumerConfig.GROUP_ID_CONFIG, GROUP_ID);
props.setProperty(ConsumerConfig.AUTO_OFFSET_RESET_CONFIG, "earliest");
// Disable auto-commit to demonstrate manual commit if desired, though not fully implemented here
props.setProperty(ConsumerConfig.ENABLE_AUTO_COMMIT_CONFIG, "true");
props.setProperty(ConsumerConfig.AUTO_COMMIT_INTERVAL_MS_CONFIG, "1000");
KafkaConsumer<String, String> consumer = new KafkaConsumer<>(props);
consumer.subscribe(Collections.singletonList(TOPIC));
System.out.println(consumerId + " subscribed to topic: " + TOPIC + " in group: " + GROUP_ID);
// Add shutdown hook for graceful exit
Runtime.getRuntime().addShutdownHook(new Thread(() -> {
System.out.println("Shutting down " + consumerId + "...");
running.set(false);
consumer.wakeup(); // Break out of poll()
}));
try {
while (running.get()) {
ConsumerRecords<String, String> records = consumer.poll(Duration.ofMillis(100));
if (!records.isEmpty()) {
System.out.println(consumerId + " received " + records.count() + " messages:");
}
for (ConsumerRecord<String, String> record : records) {
System.out.println(consumerId + " -> Key: " + record.key() +
", Value: " + record.value() +
", Partition: " + record.partition() +
", Offset: " + record.offset());
}
// If auto-commit is false, you would commit offsets here
// consumer.commitSync();
}
} catch (Exception e) {
if (running.get()) { // Only log if not a graceful shutdown
System.err.println(consumerId + " Error in consumer: " + e.getMessage());
}
} finally {
consumer.close();
System.out.println(consumerId + " consumer closed.");
}
}
}
5.4.3 How to Run1. Open two separate terminals for two consumers.
2. In Terminal 1 (for Consumer-A): cd ~/kafka-java-examples
mvn compile
mvn exec:java -Dexec.mainClass="com.example.kafka.GroupConsumer" -Dexec.args="Consumer-A"
3. In Terminal 2 (for Consumer-B):
cd ~/kafka-java-examples
mvn compile
mvn exec:java -Dexec.mainClass="com.example.kafka.GroupConsumer" -Dexec.args="Consumer-B"
4. Open a third terminal to run the producer, or use the SimpleProducer from the previous example.
cd ~/kafka-java-examples
mvn compile
mvn exec:java -Dexec.mainClass="com.example.kafka.SimpleProducer"
Run the producer several times. Observe how messages are distributed between Consumer-A and Consumer-B. Each message should only appear in one of the consumer terminals, demonstrating load balancing within the my-group-consumer-app consumer group. 6. Architecture Diagram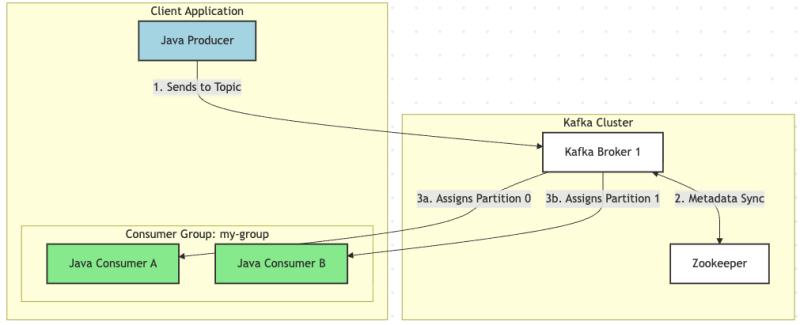
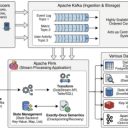
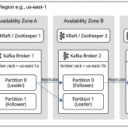
Metadata sync between Kafka brokers and Zookeeper is the continuous process where brokers register their presence and state with Zookeeper, and also retrieve the authoritative cluster configuration and operational status maintained by Zookeeper. Upon startup, each broker writes its identifier, host, and port to Zookeeper, signifying its availability. Furthermore, brokers, particularly the cluster controller, update Zookeeper with critical topic and partition metadata, including partition leaders, In-Sync Replicas (ISR) sets, and other configuration changes. Simultaneously, all brokers actively watch Zookeeper paths for updates, enabling them to discover new brokers, identify the current controller, and react to changes in topic configurations or partition leadership, ensuring a consistent and up-to-date view of the entire Kafka cluster for all its participants. |