| Apache Flink is an open-source, distributed stream processing framework that enables stateful computations over unbounded and bounded data streams. It is designed for high-throughput, low-latency, and fault-tolerant processing of data in real-time. Flink provides powerful capabilities for building stream analytics, data pipelines, and event-driven applications. Key features of Flink include: - Stream-first architecture: Processes data streams in true real-time, often using event time for accurate results.
- Stateful computation: Supports complex state management, allowing applications to maintain and update state across millions of events, crucial for aggregations, joins, and pattern detection.
- Exactly-once semantics: Guarantees that each event is processed exactly once, even in the event of failures, ensuring data consistency and correctness.
- Fault tolerance: Built-in mechanisms for checkpointing and recovery, allowing applications to resume from the last successful state after failures.
- Flexible APIs: Offers several APIs for developing applications:
- DataStream API: The core API for low-level stream processing.
- Table API & SQL: Declarative APIs for relational stream processing, optimized for common ETL and analytics tasks.
- DataSet API: (Deprecated in Flink 1.15+, use DataStream API for batch processing) For batch processing of bounded datasets.
- Multiple deployment options: Can run on YARN, Kubernetes, Mesos, or as a standalone cluster.
Why Flink is a good combination with KafkaApache Kafka is a distributed streaming platform that acts as a publish-subscribe message broker, capable of handling high volumes of data feeds. Its core strengths lie in its durability, scalability, and ability to act as a central nervous system for event-driven architectures. Flink and Kafka form a powerful synergy: - Durable and Scalable Data Source/Sink: Kafka provides a robust and highly scalable commit log that Flink can reliably consume from and write to. Kafka's ability to store data for extended periods ensures that Flink applications can restart or scale without losing data.
- Real-time Event Ingestion and Processing: Kafka excels at ingesting massive volumes of real-time events from various sources. Flink then takes these events, processes them with low latency, and performs complex stateful computations, providing real-time insights or triggering actions.
- Exactly-Once Guarantees: When configured correctly, Flink and Kafka can work together to provide end-to-end exactly-once processing semantics. Kafka's idempotent producers and transactional producers, combined with Flink's checkpointing mechanism, ensure that no data is lost or duplicated during the entire pipeline, even across failures.
- Decoupling and Replayability: Kafka decouples data producers from consumers. Flink applications can consume from Kafka topics, process data, and write results back to other Kafka topics. This allows multiple Flink applications or other downstream systems to consume the same data independently and enables replaying historical data for development, testing, or recovery.
- Scalability and Resilience: Both Flink and Kafka are designed for horizontal scalability and fault tolerance, making them suitable for mission-critical, high-volume streaming workloads.
Best Architecture with Flink and KafkaA common and highly effective architecture combining Flink and Kafka often follows a pattern of: Ingestion → Processing → Storage/Output. 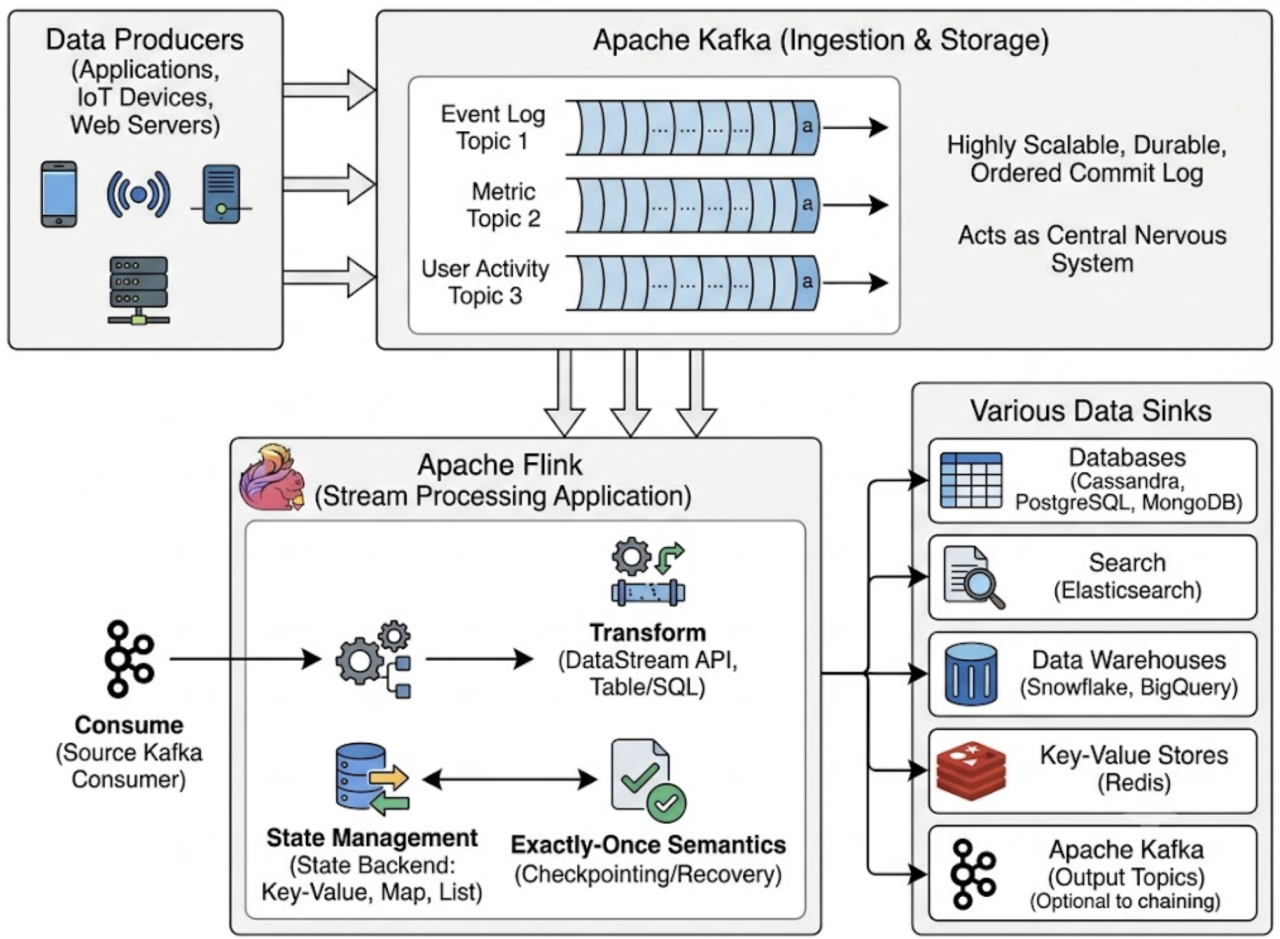
Components and Flow:
1. Data Producers: Any system or application that generates data (e.g., microservices, mobile apps, web servers, IoT sensors) publishes events to specific Kafka topics.
2. Apache Kafka (Input Topics): Acts as the central message bus. Events are ingested into Kafka topics, providing durability, order, and high availability.
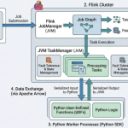
3. Apache Flink (Stream Processing Application): - Flink applications are deployed as jobs on a Flink cluster (YARN, Kubernetes, Standalone).
- They consume data from one or more Kafka input topics.
- Inside the Flink application, data is transformed, filtered, aggregated, enriched, joined, or analyzed using Flink's DataStream API, Table API, or SQL.
- Complex stateful computations are performed, leveraging Flink's robust state management and checkpointing.
4. Apache Kafka (Output Topics - Optional): Processed data can be written back to another Kafka topic. This is useful for: - Chaining multiple Flink applications.
- Serving processed data to other downstream stream processing services.
- Creating a "materialized view" as a stream of changes.
5. Various Data Sinks: Flink writes the final processed results to appropriate downstream systems based on the use case: - Databases: For operational data storage (e.g., Cassandra for high-volume writes, PostgreSQL for structured data).
- Search Engines: For real-time indexing and search (e.g., Elasticsearch).
- Data Warehouses: For analytical queries and reporting (e.g., Snowflake, Google BigQuery).
- Key-Value Stores: For low-latency lookups (e.g., Redis for caching or real-time feature stores).
Example Flink Kafka Reader Code (KafkaReaderJob.java)package com.example.flink;
import org.apache.flink.api.common.eventtime.WatermarkStrategy;
import org.apache.flink.connector.kafka.source.KafkaSource;
import org.apache.flink.connector.kafka.source.enumerator.initializer.OffsetsInitializer;
import org.apache.flink.streaming.api.datastream.DataStream;
import org.apache.flink.streaming.api.environment.StreamExecutionEnvironment;
import org.apache.kafka.common.serialization.StringDeserializer;
public class KafkaReaderJob {
public static void main(String[] args) throws Exception {
// 1. Set up the streaming execution environment
// This is the entry point for all Flink programs.
// It's used to create DataStreams and register transformations.
StreamExecutionEnvironment env = StreamExecutionEnvironment.getExecutionEnvironment();
// Optional: Set parallelism for local execution
// env.setParallelism(1);
// 2. Configure the Kafka Source
// KafkaSource is the modern way (Flink 1.15+) to connect to Kafka.
KafkaSource<String> source = KafkaSource.<String>builder()
.setBootstrapServers("localhost:9092") // Replace with your Kafka broker address(es)
.setTopics("my-input-topic") // Replace with your Kafka topic name
.setGroupId("my-flink-consumer-group") // Consumer group ID for Flink application
.setStartingOffsets(OffsetsInitializer.earliest()) // Start from the earliest available offset
// Other options: latest(), specificOffsets(), timestamps()
.setValueOnlyDeserializer(StringDeserializer.class) // Specify how to deserialize the message value (String in this case)
.build();
// 3. Create a DataStream from the Kafka Source
// The WatermarkStrategy is important for event-time processing.
// For simply reading events without time-based operations, noWatermarks() is sufficient.
DataStream<String> kafkaStream = env.fromSource(
source,
WatermarkStrategy.noWatermarks(), // No watermark generation needed for simple reading
"Kafka Source" // Name for the source operator in Flink UI
);
// 4. Perform a simple transformation (print to console)
// This will print each event received from Kafka to the standard output.
kafkaStream.print("Received from Kafka");
// 5. Execute the Flink job
// The job won't start processing until this line is called.
// The string argument is the job name that will appear in the Flink UI.
env.execute("Flink Kafka Reader Job");
}
}
Application for Flink and KafkaThe Flink-Kafka combination is ideal for a wide range of real-time applications: 1. Real-time Analytics Dashboards: 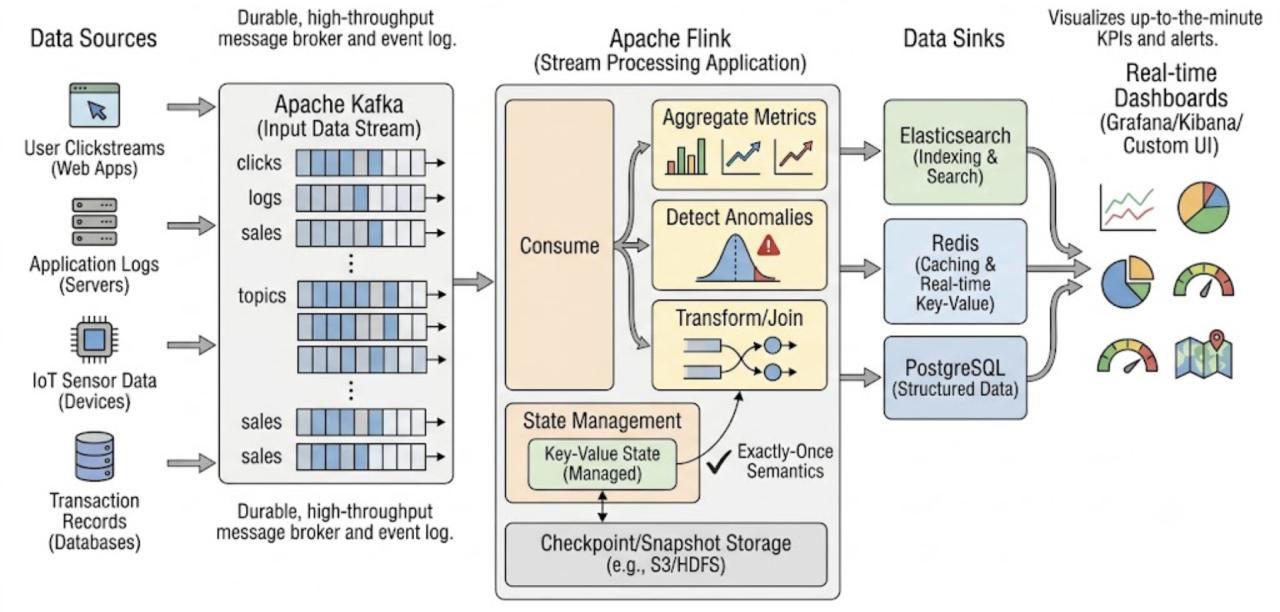
- Kafka: Ingests user clickstreams, application logs, and sensor data from various sources.
- Flink: Consumes these event streams, aggregates metrics (e.g., active users, page views per minute, sales totals), detects anomalies, and calculates KPIs in real-time.
- Sinks: Updates a real-time dashboard stored in a database (e.g., Elasticsearch, Redis, PostgreSQL) that frontend applications can query.
2. Fraud Detection: 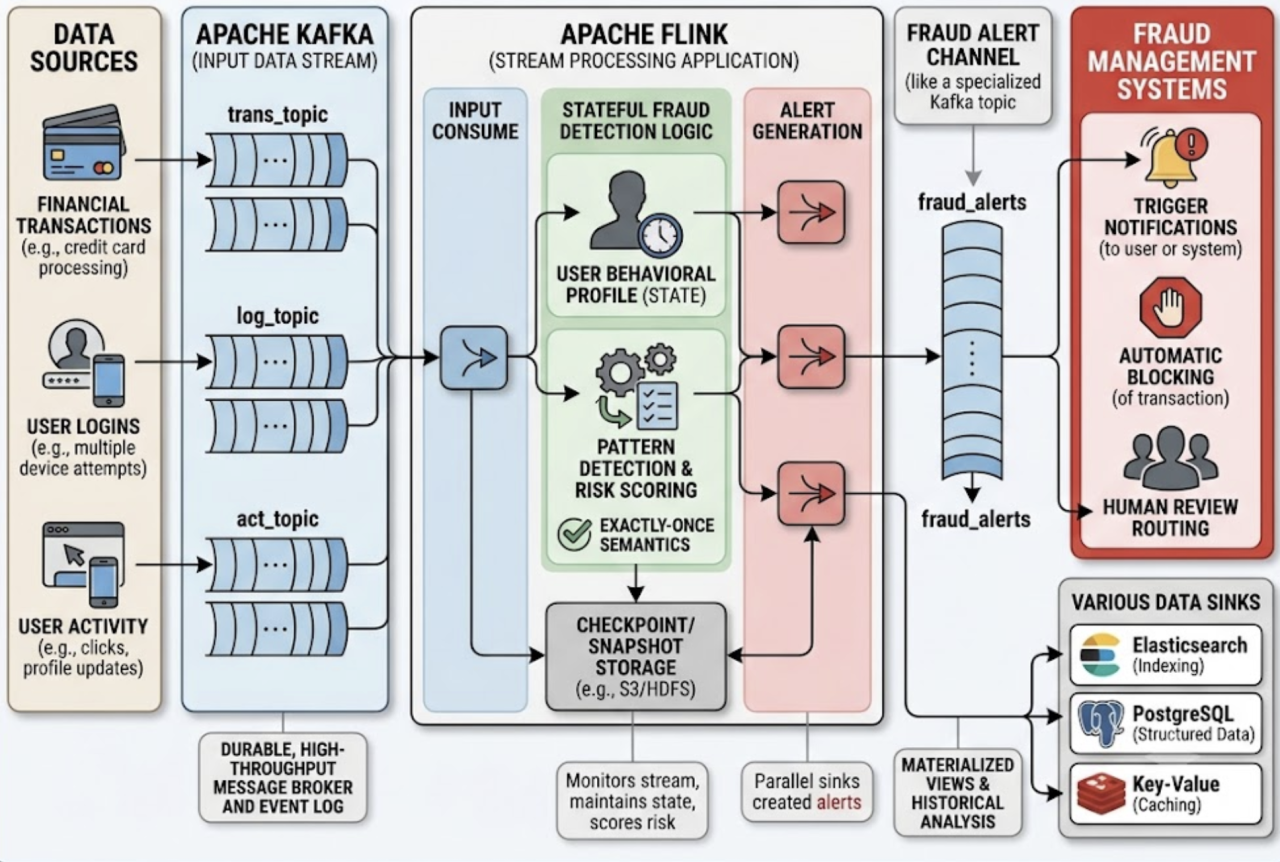
- Kafka: Receives all financial transactions, login attempts, and user activity events.
- Flink: Monitors these streams, maintains user behavioral profiles (state), detects suspicious patterns (e.g., multiple transactions from different locations in a short time, unusual spending habits), and scores transactions for risk.
- Sinks: Publishes fraud alerts to a dedicated Kafka topic, which can then trigger notifications, automatically block transactions, or route to a human review system.
3. Personalized Recommendations: 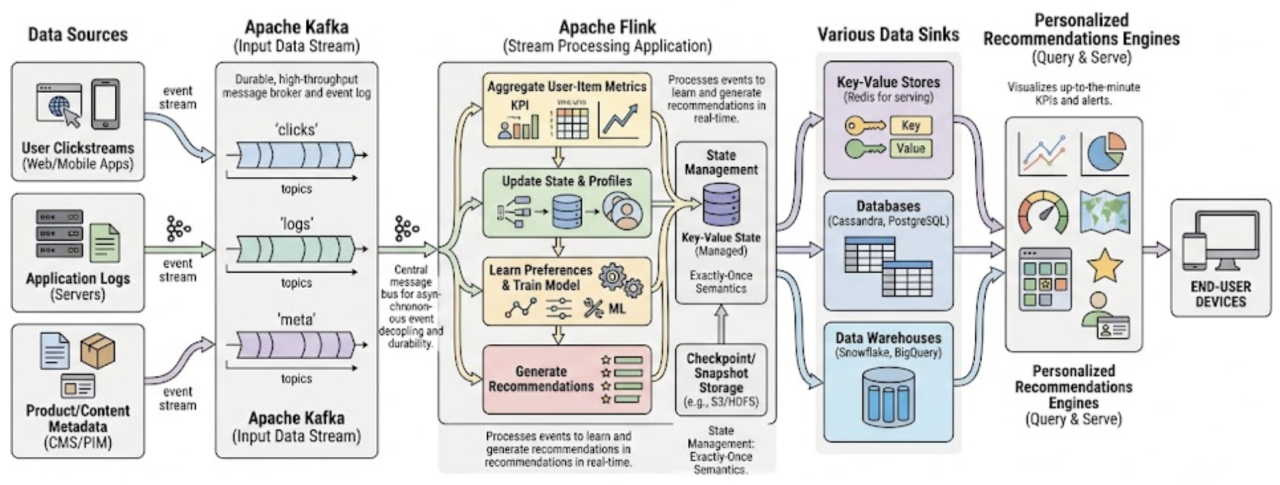
- Kafka: Collects user interactions (clicks, views, purchases, searches) with products or content.
- Flink: Processes these events to update user profiles, learn preferences, and generate real-time product/content recommendations based on current activity and historical data.
- Sinks: Stores updated recommendations in a low-latency key-value store (e.g., Redis) or a database, which recommendation engines can query instantly.
4. IoT Data Processing and Monitoring: 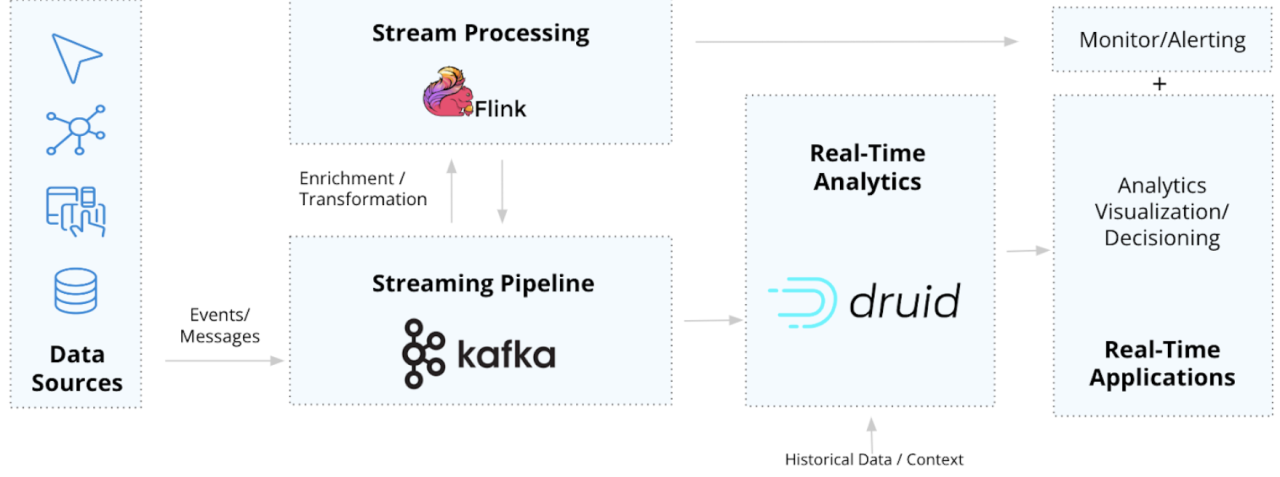
- Kafka: Gathers high-velocity sensor data from thousands of IoT devices (temperature, pressure, location).
- Flink: Filters noisy data, aggregates sensor readings over time windows, identifies anomalies or thresholds exceeded, and performs predictive analytics (e.g., for equipment failure).
- Sinks: Sends alerts to Kafka topics, updates operational dashboards, or archives processed data into a data warehouse for long-term analysis.
5. Continuous ETL (Extract, Transform, Load): 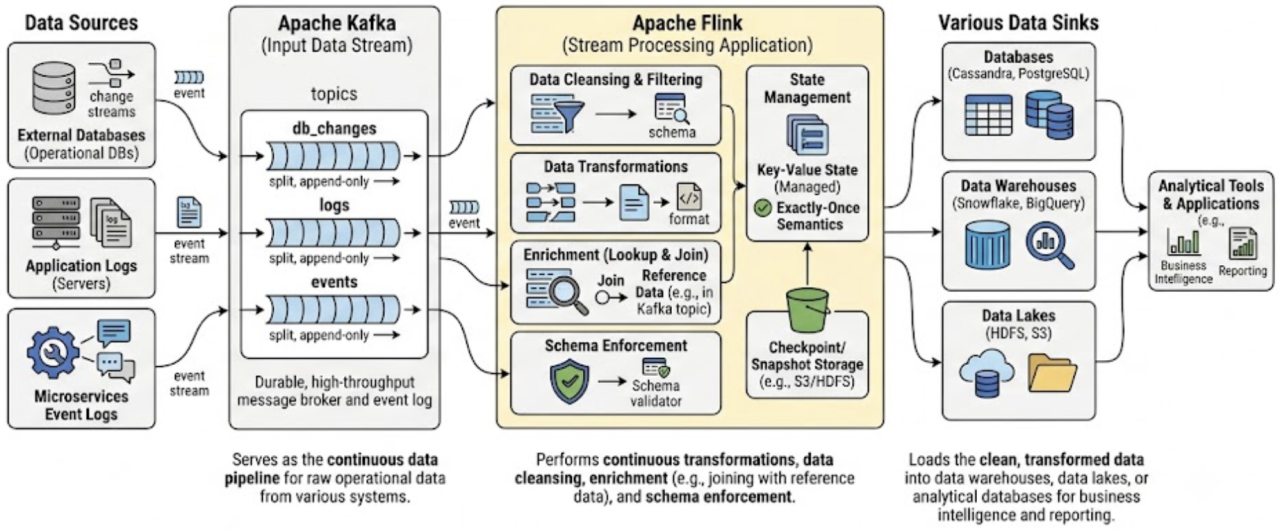
- Kafka: Serves as the continuous data pipeline for raw operational data from various systems.
- Flink: Performs continuous transformations, data cleansing, enrichment (e.g., joining with reference data from a database), and schema enforcement.
- Sinks: Loads the clean, transformed data into data warehouses, data lakes, or analytical databases for business intelligence and reporting.
Similar to FlinkSeveral other technologies offer similar stream processing capabilities, each with its own strengths and focus: 1. Apache Spark Structured Streaming: - Similarities: Distributed, fault-tolerant, scalable, supports real-time stream processing, integrates well with Kafka.
- Differences: Spark's core is batch processing, and Structured Streaming is built on its batch engine, treating streams as continuously growing tables. While it achieves low latency, Flink often offers lower true end-to-end latency for complex stateful operations and more precise control over event-time processing and state management. Spark has a broader ecosystem for general-purpose big data (batch, MLlib, GraphX).
2. Apache Kafka Streams: - Similarities: Designed for real-time stream processing, tightly integrated with Kafka, supports stateful operations.
- Differences: Kafka Streams is a client library, not a standalone cluster manager. It's ideal for building lightweight, highly scalable microservices that process data directly from Kafka topics. It's simpler to deploy for Kafka-centric use cases but might be less feature-rich and scalable than Flink for very complex, large-scale, distributed stateful processing across multiple external data sources/sinks.
3. Apache Storm: - Similarities: One of the earliest distributed real-time computation systems.
- Differences: Storm generally offers lower-level APIs and less robust state management or exactly-once semantics compared to Flink. It's more focused on pure, stateless stream processing or managing state manually.
4. Apache Samza: - Similarities: Distributed stream processing framework originally developed at LinkedIn, also built on Kafka.
- Differences: Samza is very tightly integrated with Kafka, often using Kafka for state storage. It generally provides a lower-level API and might have a smaller community compared to Flink or Spark.
5. Apache Beam (and Google Cloud Dataflow): - Similarities: Apache Beam provides a unified programming model for both batch and stream processing. It supports running pipelines on various execution engines (runners). Flink is one such runner for Apache Beam.
- Differences: Beam is an abstraction layer. While Flink is an execution engine, Beam defines how you write your pipeline, and then Flink (or Spark, or Google Cloud Dataflow) executes it. Google Cloud Dataflow is Google's managed service for running Apache Beam pipelines.
|