Is a Used M1 or M2 MacBook Pro a Smart Buy Over M4?
CK 3788 Created at Updated at
29100
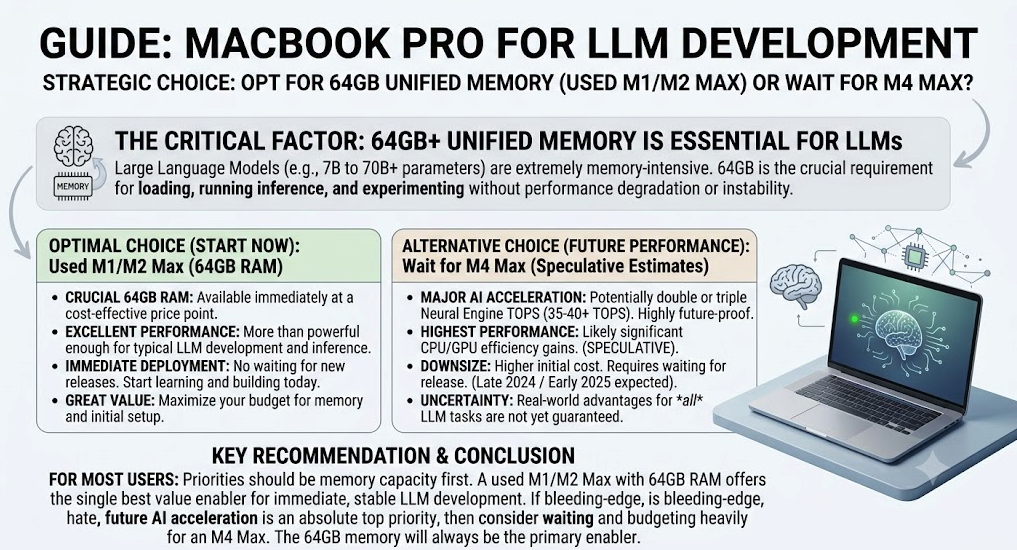
You are contemplating purchasing a MacBook Pro primarily for LLM development. Your core consideration is whether to opt for a cost-effective, used M1 or M2 MacBook Pro with 64GB of unified memory, rather than waiting for or investing in a new M4 model.
Your rationale for the M1/M2 choice hinges on the belief that 64GB of memory is crucial for the stable operation of LLMs, which is a very sound perspective given the memory-intensive nature of these models.
Key considerations driving your choice:
Memory Prioritization: For running and developing Large Language Models locally, having ample unified memory (64GB in your case) is often more critical than having the absolute latest generation chip. Larger models (e.g., 7B, 13B, 34B, 70B parameters, especially when quantized) heavily rely on memory to load and process.
Cost-Effectiveness: Opting for a used M1 or M2 model can significantly reduce your initial investment, allowing you to access high-capacity memory at a more affordable price point.
Performance vs. Availability: M1 and M2 chips are still incredibly powerful and capable, especially their Max variants. They can handle a wide range of LLM tasks. An M4, while potentially offering bleeding-edge performance, comes at a premium and requires waiting for its release.
MacBook Pro M-Series Performance Comparison
The table below compares the key specifications of M1, M2, M3, and speculative M4 Max chips for MacBook Pro, focusing on aspects relevant to LLM development.
Feature
M1 Max (MacBook Pro)
M2 Max (MacBook Pro)
M3 Max (MacBook Pro)
M4 Max (MacBook Pro - Speculative Estimates)
CPU Cores
Up to 10 (8P+2E)
Up to 12 (8P+4E)
Up to 16 (12P+4E)
Up to 18-20 (enhanced P-cores, higher IPC)
GPU Cores
Up to 32
Up to 38
Up to 40
Up to 48-52 (significant performance gains)
Neural Engine Cores
16
16
16
16 (significantly faster, higher TOPS)
Neural Engine TOPS
11
15.8
18
35-40+ (major leap in AI performance)
Max Unified Memory
64GB
96GB
128GB
128GB+
Memory Bandwidth
400GB/s
400GB/s
400GB/s
500GB/s+
Process Node
5nm
5nm (enhanced)
3nm
3nm (enhanced) / 2nm (potential)
Key LLM Advantage
Excellent performance for its era, high memory availability.
~20% faster CPU/GPU than M1, higher max RAM.
Significant efficiency, ~10-20% faster CPU/GPU than M2, faster NPU.
Expected major AI acceleration, future-proof, highest performance.
Release Date
Late 2021
Early 2023
Late 2023
Late 2024 / Early 2025 (Expected)
Note: M4 specifications are speculative based on industry rumors and Apple's typical generational improvements, particularly focusing on AI performance given recent trends.
Recommendation for Your Choice
Given your specific use case of LLM development and your prioritization of memory (64GB), here's a detailed recommendation:
1. Optimal Choice for Current Needs & Value: Used M1 Max or M2 Max (64GB RAM)
Why it's a great choice:
Crucial 64GB RAM: This is your primary need for stable LLM operation, and both M1 Max and M2 Max offer this capacity. You'll be able to load and experiment with a wide range of LLM sizes (e.g., 7B, 13B, even some quantized 34B models) effectively.
Excellent Performance: Even the M1 Max is an incredibly powerful chip, and the M2 Max offers an incremental boost. For many common LLM tasks like inference, basic fine-tuning, and embedding generation, these chips provide more than sufficient compute power.
Cost-Effective: You can likely acquire one of these models at a significantly lower price than a new M3 or future M4, allowing you to allocate budget elsewhere or save money.
Immediate Availability: No waiting for new releases.
Consider M2 Max over M1 Max if: You find a good deal where the M2 Max isn't substantially more expensive. It offers slightly better CPU/GPU performance and efficiency. However, the difference between M1 Max and M2 Max for many LLM workloads won't be as transformative as the jump from 32GB to 64GB RAM.
2. When to Consider M3 Max (64GB or 128GB RAM)
If budget is flexible and you want better future-proofing (without waiting for M4): The M3 Max offers a significant leap in efficiency (3nm process) and slightly better CPU/GPU performance than the M2 Max. Its Neural Engine is also faster, which can benefit AI workloads designed to leverage it.
If you might deal with even larger models or more aggressive fine-tuning: The M3 Max can be configured with up to 128GB of unified memory, which would further expand your capabilities for very large models or complex fine-tuning tasks.
Downside: Considerably more expensive than a used M1/M2.
3. When to Consider Waiting for M4 Max
If budget is not a concern and bleeding-edge AI performance is your absolute top priority: Rumors suggest the M4 chip will feature a heavily upgraded Neural Engine, potentially doubling or tripling the TOPS of the M3. If LLM frameworks and models become highly optimized to leverage this new hardware acceleration, the M4 could offer a noticeable advantage in specific AI tasks.
If you are willing to wait: The M4 isn't expected until late 2024 or early 2025 for the Pro/Max variants.
Downside: Likely the most expensive option, and its advantages for all LLM tasks (especially those not heavily optimized for the latest Neural Engine) might not outweigh the cost for your initial needs.
Conclusion
For your specific goal of stable LLM operation with 64GB of memory, a used MacBook Pro with an M1 Max or M2 Max and 64GB of unified memory is likely the most sensible and cost-effective choice right now. The performance of these chips is still exceptional, and the 64GB of RAM will be the biggest enabler for your LLM development. You can save a significant amount of money and start developing immediately. If your LLM needs evolve to demand even higher compute or more specialized AI acceleration, you'll have a better understanding of your specific requirements for a future upgrade.