Model Context Protocol (MCP)The Model Context Protocol (MCP) is a conceptual framework or specification designed to standardize the interaction between client applications and machine learning (ML) models. Its primary goal is to provide a consistent and rich interface for model inference, ensuring that models receive not only raw input data but also relevant contextual information necessary for accurate, personalized, and robust predictions. Key aspects of MCP include: - Contextualization: Beyond just input data (e.g., an image, a text string), MCP emphasizes sending rich context (e.g.,
userId, sessionId, deviceType, location, previousInteractions, systemState). This context helps models make more informed and tailored predictions, crucial for personalization, stateful interactions, and mitigating biases. - Model Abstraction: It abstracts away the underlying ML framework (TensorFlow, PyTorch, scikit-learn, etc.) and model-specific APIs. Client applications interact with a standardized MCP interface, regardless of how the ML model is implemented or served.
- Standardized Request/Response: Defines a common structure for requests (inputs + context) and responses (predictions + metadata). This consistency simplifies client integration and allows for easier swapping or updating of models.
- Decoupling: Promotes a clear separation of concerns between the application layer and the ML inference layer, enabling independent development, deployment, and scaling of both.
Building an MCP Server in PHPBuilding an MCP server in PHP involves creating an HTTP API endpoint that adheres to the MCP principles of receiving contextualized requests, forwarding them to an actual ML inference engine, and returning structured responses. 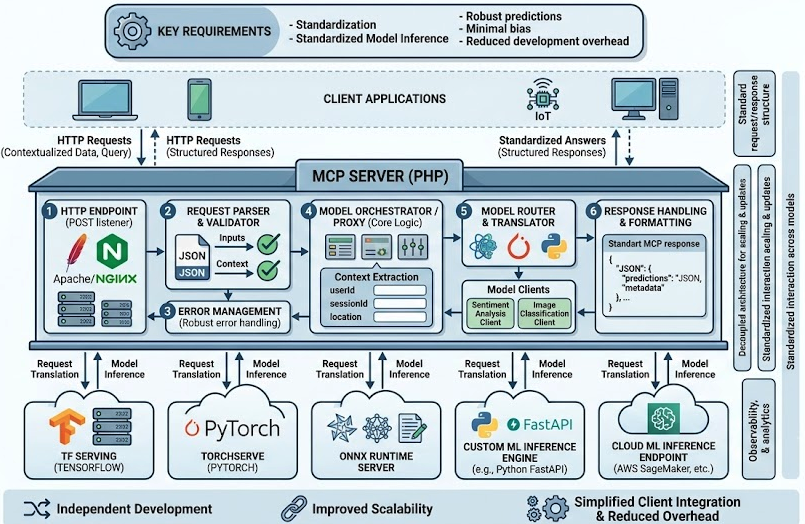
The general steps and considerations are: 1. HTTP Endpoint Setup: - Use a PHP web server environment (e.g., Apache with PHP-FPM, Nginx with PHP-FPM, RoadRunner, Swoole, or even PHP's built-in development server).
- Create a PHP script that listens for incoming HTTP POST requests, which are typically used for sending model inference data.
2. Request Parsing and Validation: - Receive the request payload, which will typically be in JSON format.
- Parse the JSON to extract the
inputs (the primary data for the model) and the context (additional information). - Validate the incoming data to ensure it meets expected formats and contains all required fields.
3. ML Model Integration (Core Logic): - PHP itself is generally not used for direct, high-performance ML model execution due to lack of extensive native ML libraries and performance considerations for complex models.
- Recommended Approach: The PHP MCP server acts as a proxy or orchestrator. It makes an HTTP request (e.g., using
curl) to a dedicated, language-agnostic ML inference service. This service could be:- A TensorFlow Serving, TorchServe, or ONNX Runtime server.
- A custom Python (Flask/FastAPI) application exposing your ML model.
- A cloud-based ML inference endpoint (e.g., AWS SageMaker, Google AI Platform).
- The PHP server translates the MCP request's
inputs and context into the format expected by the external ML service.
4. Response Handling and Formatting: - Receive the prediction/output from the external ML inference service.
- Format this output, along with any relevant metadata (e.g., model version, timestamp, the context that was used), into a standardized MCP response structure (usually JSON).
5. Error Management: - Implement robust error handling for invalid requests, issues communicating with the ML service, or errors returned by the ML model itself. Return appropriate HTTP status codes (e.g., 400 for bad request, 500 for internal server error).
Purpose of Building an MCP ServerThe decision to build an MCP server stems from several architectural and operational needs: - Decoupling Application Logic from ML Models: It creates a clean boundary, allowing front-end applications, microservices, or other backend systems to consume ML capabilities without needing to understand the underlying model's implementation details.
- Standardization Across Models: Provides a unified interface for interacting with various ML models (e.g., recommendation, sentiment analysis, image classification), simplifying client integration and reducing development overhead.
- Enhanced Contextualization: Ensures models receive all necessary information beyond just raw input, leading to more accurate, personalized, and relevant predictions.
- Improved Scalability and Resilience: The MCP server can be scaled independently of the ML inference engines. It can also act as a buffer, implementing caching, rate limiting, and retries for interactions with potentially flaky ML services.
- Easier Model Deployment and Versioning: Models can be updated, swapped out, or A/B tested without requiring changes to the client applications, as long as the MCP interface remains consistent.
- Centralized Observability: Provides a single point to log requests, monitor model usage, track performance, and gather metrics related to ML inference.
- Language Agnostic Clients: Any system capable of making HTTP requests can utilize the ML models, regardless of its programming language.
Core Components of an MCP ServerAn MCP server, regardless of the underlying language, typically consists of the following core components: - Request Handler:
- Receives incoming HTTP requests (often POST requests with JSON payloads).
- Parses the raw request body into a structured data format.
- Context Extractor & Validator:
- Identifies and extracts the
context block from the incoming request (e.g., userId, sessionId, environment). - Validates the structure and content of the context data.
- Input Processor & Validator:
- Extracts the primary
inputs data intended for the ML model (e.g., a text string, a URL to an image). - Validates the format and content of the model inputs.
- Model Orchestrator/Client:
- This is the central intelligence. It takes the extracted
inputs and context. - It then constructs a request specific to the actual ML inference engine (e.g., converts data into a TensorFlow Serving compatible format).
- It initiates communication with the external ML inference service (e.g., via HTTP
curl request, gRPC). - Handles network communication, timeouts, and potential errors from the ML service.
- Response Formatter:
- Receives the raw prediction/output from the ML inference engine.
- Transforms this raw output into the standardized MCP response format, including:
- The actual predictions/results.
- Metadata about the model used (name, version).
- The
context that was used for the prediction. - A status indicator (success/error).
- Error Management System:
- Catches and handles various types of errors (e.g., invalid input, ML service unavailability, internal processing errors).
- Returns appropriate HTTP status codes and informative error messages in the MCP error response format.
- Configuration Manager:
- Manages server settings, such as endpoints for external ML services, API keys, logging levels, and other operational parameters.
Example Code: Basic PHP MCP Server for Sentiment AnalysisThis example demonstrates a very basic MCP server in PHP. It simulates calling an external ML model for sentiment analysis. In a real-world scenario, the // Simulate ML Model Inference section would involve an actual HTTP call to a dedicated ML inference service (e.g., a Python Flask API running a sentiment model). File: public/index.php <?php
// Ensure the response is JSON
header('Content-Type: application/json');
// --- 1. Request Handler & Parsing ---
// Read the raw POST body, which is expected to be JSON
$input_json = file_get_contents('php://input');
$request_data = json_decode($input_json, true);
// Basic validation for JSON parsing
if (json_last_error() !== JSON_ERROR_NONE || !is_array($request_data)) {
http_response_code(400); // Bad Request
echo json_encode(['status' => 'error', 'message' => 'Invalid JSON payload.']);
exit();
}
// --- 2. Context Extractor & Input Processor ---
// Extract model inputs and context from the request
$model_inputs = $request_data['inputs'] ?? null;
$context = $request_data['context'] ?? []; // Default to empty array if no context provided
// Basic validation for required inputs
if (empty($model_inputs) || !isset($model_inputs['text'])) {
http_response_code(400); // Bad Request
echo json_encode(['status' => 'error', 'message' => 'Missing "inputs" or "inputs.text" in the request payload.']);
exit();
}
$text_to_analyze = (string) $model_inputs['text'];
// --- 3. Model Orchestrator/Client Simulation ---
// In a real scenario, this section would make an HTTP request to an actual ML model service.
// For demonstration, we simulate a simple sentiment analysis based on keywords.
// Example of what a CURL request to an external ML service might look like:
/*
$ml_inference_url = 'http://your-ml-inference-service.com/predict/sentiment';
$ml_payload = [
'instances' => [['text' => $text_to_analyze]], // Adapt to ML service's expected input format
'context' => $context // Pass context if the ML service can utilize it
];
$ch = curl_init($ml_inference_url);
curl_setopt($ch, CURLOPT_RETURNTRANSFER, true);
curl_setopt($ch, CURLOPT_POST, true);
curl_setopt($ch, CURLOPT_POSTFIELDS, json_encode($ml_payload));
curl_setopt($ch, CURLOPT_HTTPHEADER, ['Content-Type: application/json']);
$ml_response = curl_exec($ch);
$curl_error = curl_error($ch);
curl_close($ch);
if ($curl_error) {
http_response_code(500);
echo json_encode(['status' => 'error', 'message' => 'Failed to communicate with ML service: ' . $curl_error]);
exit();
}
$ml_output = json_decode($ml_response, true);
// Process $ml_output to extract predictions
*/
// --- Simulate ML Model Inference (replace with actual ML service call) ---
$sentiment = 'neutral';
$confidence = 0.5;
$lower_text = strtolower($text_to_analyze);
if (strpos($lower_text, 'good') !== false || strpos($lower_text, 'happy') !== false || strpos($lower_text, 'great') !== false) {
$sentiment = 'positive';
$confidence = 0.9;
} elseif (strpos($lower_text, 'bad') !== false || strpos($lower_text, 'sad') !== false || strpos($lower_text, 'terrible') !== false) {
$sentiment = 'negative';
$confidence = 0.8;
}
// Add contextual adjustment: If a 'grumpy_mode' is enabled in context, slightly adjust sentiment.
if (isset($context['user_settings']['grumpy_mode']) && $context['user_settings']['grumpy_mode'] === true && $sentiment === 'positive') {
$sentiment .= ' (adjusted for grumpy mode)';
$confidence -= 0.2; // Lower confidence due to grumpy mode
}
// --- 4. Response Formatter ---
$response_payload = [
'status' => 'success',
'model_name' => 'simulated-sentiment-analyzer',
'model_version' => '1.0.0',
'predicted_at' => (new DateTime())->format(DateTime::ISO8601),
'context_used' => $context, // Echo back the context that was used
'results' => [
[
'type' => 'sentiment',
'value' => $sentiment,
'confidence' => max(0, min(1, $confidence)), // Ensure confidence is between 0 and 1
'original_input' => $text_to_analyze,
]
],
// 'raw_ml_output' => $ml_output, // Optionally include raw ML service output for debugging
];
// Output the structured JSON response
echo json_encode($response_payload, JSON_PRETTY_PRINT);
exit();
How to Run This Example:
1. Save: Save the code above as index.php inside a directory, e.g., mcp-server/public/.
2. Web Server: - Apache/Nginx: Configure your web server to serve the
public/ directory and ensure index.php is the default file for requests. For Apache, you might need an .htaccess file in public/ to route all requests to index.php if you're using a framework, but for a single endpoint, it's often not strictly necessary. - PHP Built-in Server (for development): Navigate to your
mcp-server directory in your terminal and run:
php -S localhost:8000 -t public
This will start a server listening on http://localhost:8000.
3. Send a Request: Use a tool like Postman, Insomnia, curl, or a simple PHP script to send a POST request to your server.
Example curl Request: curl -X POST \
-H "Content-Type: application/json" \
-d '{
"inputs": {
"text": "This movie was absolutely great and made me so happy!"
},
"context": {
"userId": "user123",
"sessionId": "abc456",
"locale": "en_US",
"user_settings": {
"grumpy_mode": false
}
}
}' \
http://localhost:8000
Example curl Request with grumpy mode: curl -X POST \
-H "Content-Type: application/json" \
-d '{
"inputs": {
"text": "This product is fantastic!"
},
"context": {
"userId": "user123",
"sessionId": "def789",
"user_settings": {
"grumpy_mode": true
}
}
}' \
http://localhost:8000
|