| Below code is based on Python 3 to implement Linear Regression based on 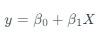
where: - Y is the dependent variable
- X is the independent variable
- β0 is the intercept
- β1 is the slope
Our primary objective while using linear regression is to locate the best-fit line, which implies that the error between the predicted and actual values should be kept to a minimum. There will be the least error in the best-fit line. The best Fit Line equation provides a straight line that represents the relationship between the dependent and independent variables. The slope of the line indicates how much the dependent variable changes for a unit change in the independent variable(s). 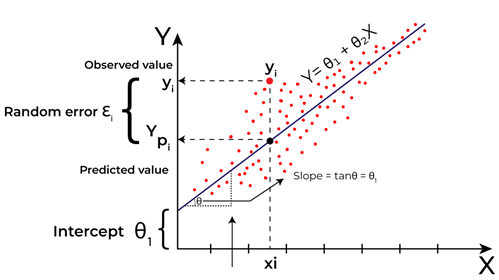
Here Y is called a dependent or target variable and X is called an independent variable also known as the predictor of Y. There are many types of functions or modules that can be used for regression. A linear function is the simplest type of function. Here, X may be a single feature or multiple features representing the problem. Linear regression performs the task to predict a dependent variable value (y) based on a given independent variable (x)). Hence, the name is Linear Regression. In the figure above, X (input) is the work experience and Y (output) is the salary of a person. The regression line is the best-fit line for our model. We utilize the cost function to compute the best values in order to get the best fit line since different values for weights or the coefficient of lines result in different regression lines. import pandas as pd
import numpy as np
import matplotlib.pyplot as plt
import matplotlib.axes as ax
from matplotlib.animation import FuncAnimation
url = 'https://media.geeksforgeeks.org/wp-content/uploads/20240320114716/data_for_lr.csv'
data = pd.read_csv(url)
data
# Drop the missing values
data = data.dropna()
# training dataset and labels
train_input = np.array(data.x[0:500]).reshape(500, 1)
train_output = np.array(data.y[0:500]).reshape(500, 1)
# valid dataset and labels
test_input = np.array(data.x[500:700]).reshape(199, 1)
test_output = np.array(data.y[500:700]).reshape(199, 1)
class LinearRegression:
def __init__(self):
self.parameters = {}
def forward_propagation(self, train_input):
m = self.parameters['m']
c = self.parameters['c']
predictions = np.multiply(m, train_input) + c
return predictions
def cost_function(self, predictions, train_output):
cost = np.mean((train_output - predictions) ** 2)
return cost
def backward_propagation(self, train_input, train_output, predictions):
derivatives = {}
df = (predictions-train_output)
# dm= 2/n * mean of (predictions-actual) * input
dm = 2 * np.mean(np.multiply(train_input, df))
# dc = 2/n * mean of (predictions-actual)
dc = 2 * np.mean(df)
derivatives['dm'] = dm
derivatives['dc'] = dc
return derivatives
def update_parameters(self, derivatives, learning_rate):
self.parameters['m'] = self.parameters['m'] - learning_rate * derivatives['dm']
self.parameters['c'] = self.parameters['c'] - learning_rate * derivatives['dc']
def train(self, train_input, train_output, learning_rate, iters):
# Initialize random parameters
self.parameters['m'] = np.random.uniform(0, 1) * -1
self.parameters['c'] = np.random.uniform(0, 1) * -1
# Initialize loss
self.loss = []
# Initialize figure and axis for animation
fig, ax = plt.subplots()
x_vals = np.linspace(min(train_input), max(train_input), 100)
line, = ax.plot(x_vals, self.parameters['m'] * x_vals +
self.parameters['c'], color='red', label='Regression Line')
ax.scatter(train_input, train_output, marker='o',
color='green', label='Training Data')
# Set y-axis limits to exclude negative values
ax.set_ylim(0, max(train_output) + 1)
def update(frame):
# Forward propagation
predictions = self.forward_propagation(train_input)
# Cost function
cost = self.cost_function(predictions, train_output)
# Back propagation
derivatives = self.backward_propagation(
train_input, train_output, predictions)
# Update parameters
self.update_parameters(derivatives, learning_rate)
# Update the regression line
line.set_ydata(self.parameters['m']
* x_vals + self.parameters['c'])
# Append loss and print
self.loss.append(cost)
print("Iteration = {}, Loss = {}".format(frame + 1, cost))
return line,
# Create animation
ani = FuncAnimation(fig, update, frames=iters, interval=200, blit=True)
# Save the animation as a video file (e.g., MP4)
ani.save('linear_regression_A.gif', writer='ffmpeg')
plt.xlabel('Input')
plt.ylabel('Output')
plt.title('Linear Regression')
plt.legend()
plt.show()
return self.parameters, self.loss
#Example usage
linear_reg = LinearRegression()
parameters, loss = linear_reg.train(train_input, train_output, 0.0001, 20)
Above code appears to be related to loading and preprocessing data for a machine learning task, specifically for linear regression. Let's break down what each part does: url = 'https://media.geeksforgeeks.org/wp-content/uploads/20240320114716/data_for_lr.csv': This line assigns a URL string pointing to a CSV file containing data for linear regression. 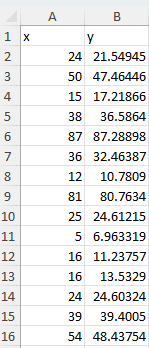
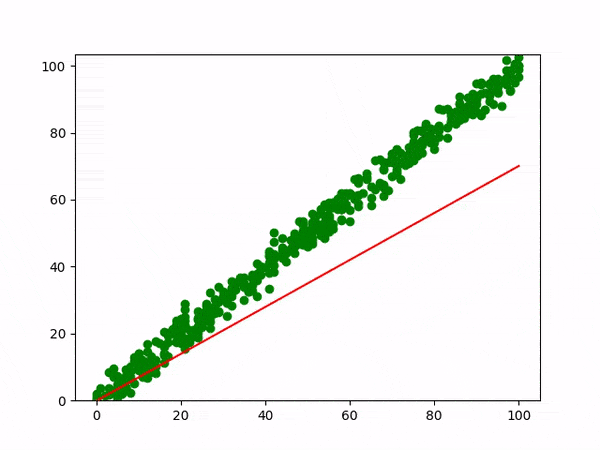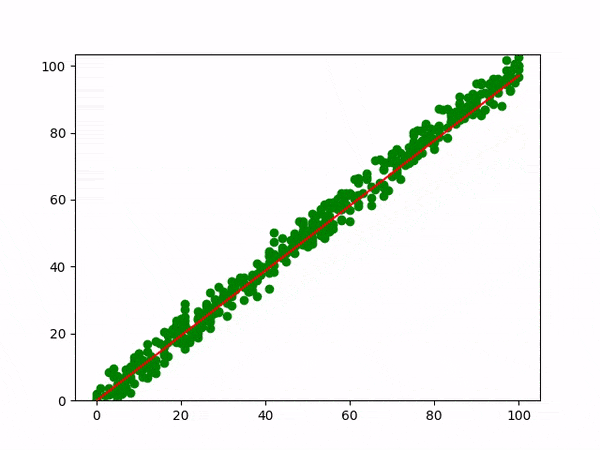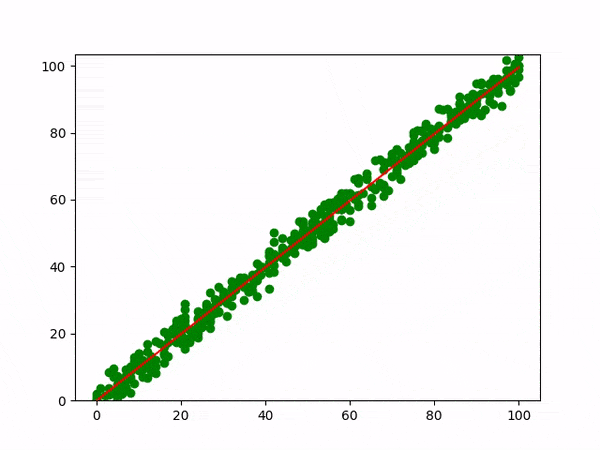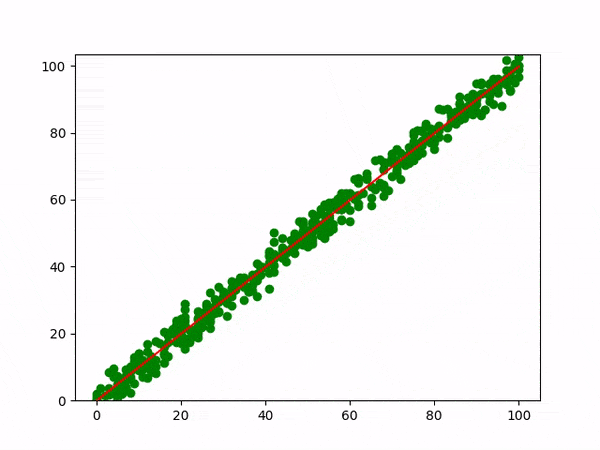
data = pd.read_csv(url): This line uses pandas (pd) library to read the CSV file from the given URL and store it in a DataFrame called data. data = data.dropna(): This line removes any rows with missing values (NaN) from the DataFrame. train_input = np.array(data.x[0:500]).reshape(500, 1): This line extracts the first 500 values from the 'x' column of the DataFrame, converts it into a numpy array, and reshapes it into a 2D array with 500 rows and 1 column. This is done to prepare the training input data. train_output = np.array(data.y[0:500]).reshape(500, 1): Similar to the previous line, this extracts the first 500 values from the 'y' column of the DataFrame, converts it into a numpy array, and reshapes it into a 2D array with 500 rows and 1 column. This is done to prepare the training output data. test_input = np.array(data.x[500:700]).reshape(199, 1): This line extracts values from index 500 to 699 from the 'x' column of the DataFrame, converts it into a numpy array, and reshapes it into a 2D array with 199 rows and 1 column. This is done to prepare the testing input data. test_output = np.array(data.y[500:700]).reshape(199, 1): Similar to the previous line, this extracts values from index 500 to 699 from the 'y' column of the DataFrame, converts it into a numpy array, and reshapes it into a 2D array with 199 rows and 1 column. This is done to prepare the testing output data. So overall, this code is loading data from a CSV file, removing any rows with missing values, and then splitting the data into training and testing sets for a linear regression model. Below is the output: Iteration = 1, Loss = 9130.407560462196
Iteration = 1, Loss = 1107.1996742908998
Iteration = 1, Loss = 140.31580932842422
Iteration = 1, Loss = 23.795780526084116
Iteration = 2, Loss = 9.753848205147605
Iteration = 3, Loss = 8.061641745006835
Iteration = 4, Loss = 7.8577116490914864
Iteration = 5, Loss = 7.8331350515579015
Iteration = 6, Loss = 7.830172502503967
Iteration = 7, Loss = 7.829814681591015
Iteration = 8, Loss = 7.829770758846183
Iteration = 9, Loss = 7.829764664327399
Iteration = 10, Loss = 7.829763128602258
Iteration = 11, Loss = 7.829762142342088
Iteration = 12, Loss = 7.829761222379141
Iteration = 13, Loss = 7.829760310486438
Iteration = 14, Loss = 7.829759399646989
Iteration = 15, Loss = 7.829758489015161
Iteration = 16, Loss = 7.829757578489033
Iteration = 17, Loss = 7.829756668056319
Iteration = 18, Loss = 7.829755757715535
Iteration = 19, Loss = 7.829754847466484
Iteration = 20, Loss = 7.829753937309139
|