| A random forest is an ensemble learning method that combines the predictions from multiple decision trees to produce a more accurate and stable prediction. It is a type of supervised learning algorithm that can be used for both classification and regression tasks. Every decision tree has high variance, but when we combine all of them in parallel then the resultant variance is low as each decision tree gets perfectly trained on that particular sample data, and hence the output doesn’t depend on one decision tree but on multiple decision trees. In the case of a classification problem, the final output is taken by using the majority voting classifier. In the case of a regression problem, the final output is the mean of all the outputs. This part is called Aggregation. 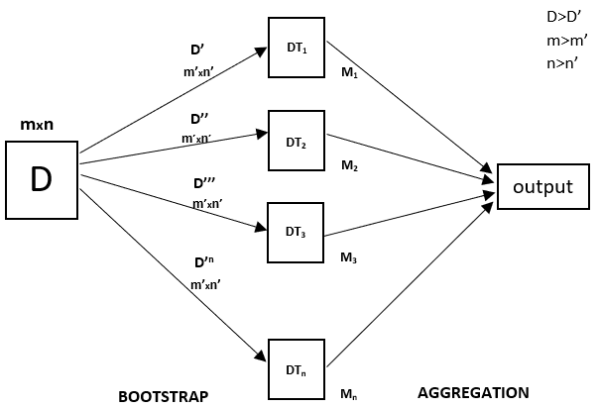
Random Forest Regression in machine learning is an ensemble technique capable of performing both regression and classification tasks with the use of multiple decision trees and a technique called Bootstrap and Aggregation, commonly known as bagging. The basic idea behind this is to combine multiple decision trees in determining the final output rather than relying on individual decision trees. Random Forest has multiple decision trees as base learning models. We randomly perform row sampling and feature sampling from the dataset forming sample datasets for every model. This part is called Bootstrap. We need to approach the Random Forest regression technique like any other machine learning technique. - Design a specific question or data and get the source to determine the required data.
- Make sure the data is in an accessible format else convert it to the required format.
- Specify all noticeable anomalies and missing data points that may be required to achieve the required data.
- Create a machine-learning model.
- Set the baseline model that you want to achieve
- Train the data machine learning model.
- Provide an insight into the model with test data
- Now compare the performance metrics of both the test data and the predicted data from the model.
- If it doesn’t satisfy your expectations, you can try improving your model accordingly or dating your data, or using another data modeling technique.
- At this stage, you interpret the data you have gained and report accordingly.
# Importing necessary libraries
import numpy as np
import matplotlib.pyplot as plt
from sklearn.datasets import make_regression
from sklearn.model_selection import train_test_split
from sklearn.ensemble import RandomForestRegressor
from sklearn.metrics import mean_squared_error
# Generating synthetic dataset
X, y = make_regression(n_samples=1000, n_features=1, noise=10, random_state=42)
# Splitting dataset into training and testing sets
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)
# Creating and training the Random Forest Regressor model
rf_regressor = RandomForestRegressor(n_estimators=100, random_state=42)
rf_regressor.fit(X_train, y_train)
# Predicting on the testing set
y_pred = rf_regressor.predict(X_test)
# Calculating Mean Squared Error (MSE)
mse = mean_squared_error(y_test, y_pred)
print("Mean Squared Error:", mse)
# Plotting the results
plt.figure(figsize=(10, 6))
plt.scatter(X_test, y_test, color='blue', label='Actual')
plt.scatter(X_test, y_pred, color='red', label='Predicted')
plt.title('Random Forest Regression')
plt.xlabel('X')
plt.ylabel('y')
plt.legend()
plt.show()
This code performs the following steps: - Generates a synthetic dataset using make_regression.
- Splits the dataset into training and testing sets using train_test_split.
- Creates and trains a Random Forest Regressor model using RandomForestRegressor.
- Predicts on the testing set.
- Calculates the Mean Squared Error (MSE) using mean_squared_error.
- Plots the actual vs predicted values.
Below is the example data set X (features):
[[ 0.9803]
[-0.3673]
[ 1.7859]
...
[-0.5468]
[-0.0486]
[ 1.4225]]
y (target):
[ 68.67792672 -15.16765572 131.63145767 ... -23.54596341 1.50704555 91.64105671]
Here's an example of Random Forest Regression in Python using scikit-learn library, with sample data containing three different variables, and including both training and testing phases:
# Import necessary libraries
import numpy as np
from sklearn.model_selection import train_test_split
from sklearn.ensemble import RandomForestRegressor
from sklearn.metrics import mean_squared_error

# Sample data generation
np.random.seed(0)
n_samples = 1000
X1 = np.random.rand(n_samples) * 10
X2 = np.random.rand(n_samples) * 5
X3 = np.random.rand(n_samples) * 3
y = 2 * X1 + 3 * X2 - 4 * X3 + np.random.randn(n_samples) * 0.5  # Some linear combination with noise

# Combine features
X = np.column_stack((X1, X2, X3))

# Split data into training and testing sets
X_train, X_test, y_train, y_test = train_test_split(X, y, test_size=0.2, random_state=42)

# Instantiate Random Forest Regression model
rf_regressor = RandomForestRegressor(n_estimators=100, random_state=42)

# Train the model
rf_regressor.fit(X_train, y_train)

# Make predictions on the testing set
y_pred = rf_regressor.predict(X_test)

# Calculate mean squared error
mse = mean_squared_error(y_test, y_pred)
print("Mean Squared Error:", mse)
In this example: - We generate sample data with three different variables (X1, X2, X3) and a target variable (y) which is a linear combination of these variables with some noise.
- We split the data into training and testing sets using train_test_split.
- We then instantiate the Random Forest Regression model with n_estimators=100, meaning we'll use 100 decision trees.
- Next, we train the model using the training data.
- We make predictions on the testing data.
- Finally, we evaluate
|