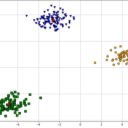
What is Clustering?Clustering is a machine learning technique used to group similar data points together into clusters. The goal is to find inherent structure in data by identifying groups where the points within each cluster are more similar to each other than to points in other clusters. This allows for data summarization, anomaly detection, and improved understanding of the underlying data relationships. 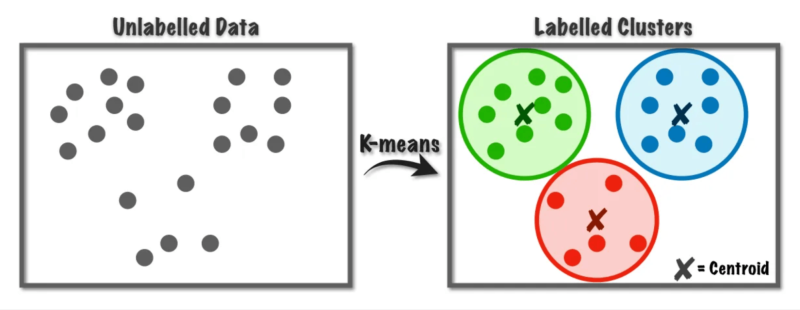
Example CodeHere’s an example of using Python to perform clustering on an array containing high school score data. The example uses the KMeans algorithm from the sklearn library. import numpy as np
from sklearn.cluster import KMeans
import matplotlib.pyplot as plt
from sklearn.preprocessing import StandardScaler
# Example high school score data (e.g., [Math Score, English Score, Science Score])
data = np.array([
[85, 78, 90],
[72, 88, 85],
[95, 92, 98],
[60, 65, 70],
[75, 80, 79],
[90, 85, 88],
[55, 60, 58],
[80, 83, 85],
[98, 99, 100],
[65, 70, 68]
])
# Standardize the data for better clustering performance
scaler = StandardScaler()
data_scaled = scaler.fit_transform(data)
# Perform K-Means clustering
kmeans = KMeans(n_clusters=3, random_state=42)
kmeans.fit(data_scaled)
# Get cluster labels and centroids
labels = kmeans.labels_
centroids = kmeans.cluster_centers_
# Display results
print("Cluster labels:", labels)
print("Centroids:", scaler.inverse_transform(centroids))
# Plot the data (2D visualization for simplicity)
plt.scatter(data_scaled[:, 0], data_scaled[:, 1], c=labels, cmap='viridis', marker='o', s=100, label="Students")
plt.scatter(centroids[:, 0], centroids[:, 1], c='red', marker='x', s=200, label="Centroids")
plt.title("High School Score Clustering")
plt.xlabel("Standardized Math Score")
plt.ylabel("Standardized English Score")
plt.legend()
plt.show()
Explanation- Data Input: The
data array simulates high school scores in subjects like Math, English, and Science for various students. - Standardization: Data is scaled using
StandardScaler to ensure all features contribute equally to the clustering process. - Clustering: The
KMeans algorithm is applied to partition the data into clusters. Adjust n_clusters as needed. - Results: The cluster labels and centroids are printed. The centroids are transformed back to the original scale for better interpretation.
- Visualization: A 2D scatter plot shows clusters and their centroids, focusing on the first two features for simplicity.
You can extend this to more features or use other clustering methods like DBSCAN or Agglomerative Clustering based on the data characteristics. DBSCAN Clustering
Here’s an example using the DBSCAN clustering algorithm to process high school score data. DBSCAN (Density-Based Spatial Clustering of Applications with Noise) identifies clusters based on the density of data points and can detect outliers. Example Codeimport numpy as np
from sklearn.cluster import DBSCAN
from sklearn.preprocessing import StandardScaler
import matplotlib.pyplot as plt
# Example high school score data (e.g., [Math Score, English Score, Science Score])
data = np.array([
[85, 78, 90],
[72, 88, 85],
[95, 92, 98],
[60, 65, 70],
[75, 80, 79],
[90, 85, 88],
[55, 60, 58],
[80, 83, 85],
[98, 99, 100],
[65, 70, 68]
])
# Standardize the data for better clustering performance
scaler = StandardScaler()
data_scaled = scaler.fit_transform(data)
# Perform DBSCAN clustering
dbscan = DBSCAN(eps=1.5, min_samples=2) # Adjust `eps` and `min_samples` as needed
dbscan.fit(data_scaled)
# Get cluster labels
labels = dbscan.labels_
# Display results
print("Cluster labels:", labels) # -1 indicates noise (outliers)
# Visualize the clustering results in 2D space
plt.scatter(data_scaled[:, 0], data_scaled[:, 1], c=labels, cmap='viridis', marker='o', s=100)
plt.title("High School Score Clustering with DBSCAN")
plt.xlabel("Standardized Math Score")
plt.ylabel("Standardized English Score")
plt.colorbar(label="Cluster")
plt.show()
Explanation- Data Input: The
data array contains high school scores in Math, English, and Science. - Standardization: Scores are standardized with
StandardScaler to make the features comparable. - DBSCAN Parameters:
eps: The maximum distance between two points to be considered part of the same neighborhood.min_samples: The minimum number of points required to form a dense region.
- Labels:
- A cluster label (
0, 1, 2, ...) is assigned to each data point. - A label of
-1 indicates that the point is considered noise or an outlier.
- Visualization: Only the first two features are plotted for clarity. Use tools like
PCA or t-SNE for better visual representation in higher dimensions.
Customization- Tune
eps and min_samples to better fit the density of your dataset. - Consider visualizing the results in a 3D plot or reducing dimensions with
PCA for more detailed datasets.
Agglomerative Clustering
Here’s an example of performing hierarchical clustering using the Agglomerative Clustering algorithm from the sklearn library. This example uses the same high school score dataset. Example Codeimport numpy as np
import matplotlib.pyplot as plt
from sklearn.cluster import AgglomerativeClustering
from sklearn.preprocessing import StandardScaler
from scipy.cluster.hierarchy import dendrogram, linkage
# Example high school score data (e.g., [Math Score, English Score, Science Score])
data = np.array([
[85, 78, 90],
[72, 88, 85],
[95, 92, 98],
[60, 65, 70],
[75, 80, 79],
[90, 85, 88],
[55, 60, 58],
[80, 83, 85],
[98, 99, 100],
[65, 70, 68]
])
# Standardize the data
scaler = StandardScaler()
data_scaled = scaler.fit_transform(data)
# Perform hierarchical clustering
agg_clustering = AgglomerativeClustering(n_clusters=3, linkage='ward')
labels = agg_clustering.fit_predict(data_scaled)
# Display results
print("Cluster labels:", labels)
# Visualize dendrogram
linkage_matrix = linkage(data_scaled, method='ward')
plt.figure(figsize=(10, 7))
dendrogram(linkage_matrix, labels=np.arange(1, len(data) + 1), leaf_font_size=12, color_threshold=0.7 * np.max(linkage_matrix[:, 2]))
plt.title("Dendrogram of High School Scores")
plt.xlabel("Student Index")
plt.ylabel("Ward's Distance")
plt.axhline(y=7, color='r', linestyle='--', label='Cluster Threshold')
plt.legend()
plt.show()
# Visualize clusters in 2D (using first two features for simplicity)
plt.scatter(data_scaled[:, 0], data_scaled[:, 1], c=labels, cmap='viridis', s=100)
plt.title("Agglomerative Clustering of High School Scores")
plt.xlabel("Standardized Math Score")
plt.ylabel("Standardized English Score")
plt.show()
Explanation- Data Scaling: Standardizes the data for better clustering.
- Agglomerative Clustering:
linkage='ward': Uses Ward's method to minimize the variance within clusters.n_clusters=3: Specifies the number of clusters to form.
- Dendrogram:
- Uses
scipy.cluster.hierarchy.dendrogram and linkage to visualize how the clusters are formed hierarchically. - The red dashed line indicates the threshold at which clusters are cut.
- 2D Visualization:
- Scatter plot of clusters (limited to the first two features for simplicity).
Customization- Change
linkage to complete, average, or single for different hierarchical clustering strategies. - Adjust
n_clusters or explore the dendrogram to decide an appropriate threshold.
|