| Saving processed data allows for significant time and resource savings by eliminating the need to re-process raw data each time an analysis is needed. Reloading previously processed data dramatically accelerates subsequent analyses, facilitates reproducibility of results, and reduces computational costs, especially with large datasets where initial processing can be computationally intensive. This reuse promotes efficiency and allows researchers or analysts to focus on interpretation and further analysis rather than repetitive data manipulation. 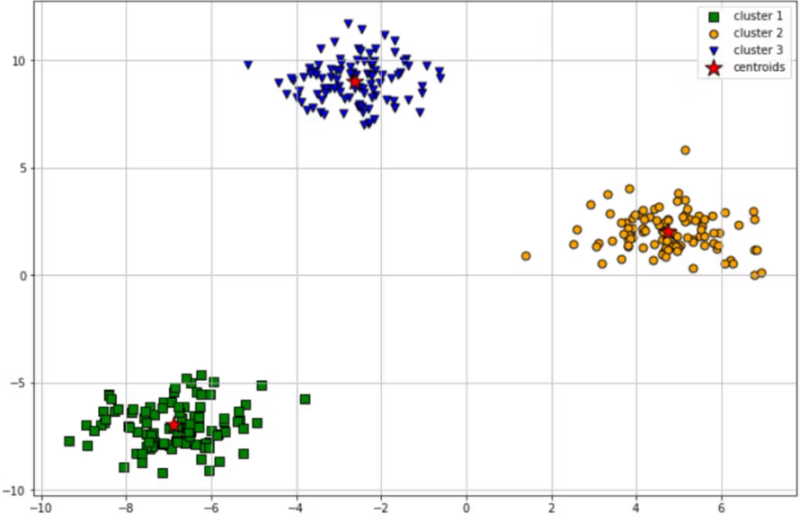
You can save the calculated clustering results (such as cluster labels and centroids if applicable) in a JSON file and reload them later. Here's how you can extend the example using Agglomerative Clustering to save the labels into a JSON file and reload them: Modified Code with JSON Saving and Loadingimport numpy as np
import json
from sklearn.cluster import AgglomerativeClustering
from sklearn.preprocessing import StandardScaler
from scipy.cluster.hierarchy import dendrogram, linkage
import matplotlib.pyplot as plt
# Example high school score data
data = np.array([
[85, 78, 90],
[72, 88, 85],
[95, 92, 98],
[60, 65, 70],
[75, 80, 79],
[90, 85, 88],
[55, 60, 58],
[80, 83, 85],
[98, 99, 100],
[65, 70, 68]
])
# Standardize the data
scaler = StandardScaler()
data_scaled = scaler.fit_transform(data)
# Perform Agglomerative Clustering
agg_clustering = AgglomerativeClustering(n_clusters=3, linkage='ward')
labels = agg_clustering.fit_predict(data_scaled)
# Save results to JSON
result = {
"data": data.tolist(),
"labels": labels.tolist(),
"scaler_mean": scaler.mean_.tolist(),
"scaler_scale": scaler.scale_.tolist()
}
with open("clustering_results.json", "w") as file:
json.dump(result, file, indent=4)
print("Clustering results saved to clustering_results.json")
# Reload results from JSON
with open("clustering_results.json", "r") as file:
loaded_result = json.load(file)
# Reconstruct data from the loaded JSON
data_reloaded = np.array(loaded_result["data"])
labels_reloaded = np.array(loaded_result["labels"])
scaler_mean = np.array(loaded_result["scaler_mean"])
scaler_scale = np.array(loaded_result["scaler_scale"])
# Validate reloaded results
print("Reloaded Data:\n", data_reloaded)
print("Reloaded Labels:", labels_reloaded)
# Rescale if needed
scaler_reloaded = StandardScaler()
scaler_reloaded.mean_ = scaler_mean
scaler_reloaded.scale_ = scaler_scale
data_rescaled = scaler_reloaded.transform(data_reloaded)
# Optional: Visualize reloaded labels
plt.scatter(data_rescaled[:, 0], data_rescaled[:, 1], c=labels_reloaded, cmap='viridis', s=100)
plt.title("Reloaded Agglomerative Clustering Results")
plt.xlabel("Standardized Math Score")
plt.ylabel("Standardized English Score")
plt.show()
Key Points- Save Results to JSON:
data.tolist() converts the NumPy array into a list, which is JSON serializable.- Save
labels, raw data, and scaling parameters (mean and scale) to reconstruct the process later.
- Reload and Reconstruct:
- Reload JSON and convert lists back into NumPy arrays.
- Use the saved scaling parameters to recreate the
StandardScaler and rescale the data.
- Validation:
- Print and visualize the reloaded data and labels to confirm the clustering results are correctly restored.
This approach allows you to save the clustering process for later analysis or use without rerunning the entire computation. Saving the clustering result in an array and reloadingYes, you can load the clustering results directly from an in-memory array rather than a file. This approach avoids file I/O and is useful when working in environments where data is transferred or stored in memory structures like Python dictionaries or NumPy arrays. Here's how to modify the code to load the results from an array: Example: Save and Load from Arrayimport numpy as np
from sklearn.cluster import AgglomerativeClustering
from sklearn.preprocessing import StandardScaler
import matplotlib.pyplot as plt
# Example high school score data
data = np.array([
[85, 78, 90],
[72, 88, 85],
[95, 92, 98],
[60, 65, 70],
[75, 80, 79],
[90, 85, 88],
[55, 60, 58],
[80, 83, 85],
[98, 99, 100],
[65, 70, 68]
])
# Standardize the data
scaler = StandardScaler()
data_scaled = scaler.fit_transform(data)
# Perform Agglomerative Clustering
agg_clustering = AgglomerativeClustering(n_clusters=3, linkage='ward')
labels = agg_clustering.fit_predict(data_scaled)
# Save results to an in-memory array (dictionary)
clustering_result = {
"data": data,
"labels": labels,
"scaler_mean": scaler.mean_,
"scaler_scale": scaler.scale_
}
# Simulate loading from an array
loaded_result = clustering_result # Directly use the saved array
# Extract data from the in-memory array
data_reloaded = np.array(loaded_result["data"])
labels_reloaded = np.array(loaded_result["labels"])
scaler_mean = np.array(loaded_result["scaler_mean"])
scaler_scale = np.array(loaded_result["scaler_scale"])
# Reconstruct the scaler
scaler_reloaded = StandardScaler()
scaler_reloaded.mean_ = scaler_mean
scaler_reloaded.scale_ = scaler_scale
data_rescaled = scaler_reloaded.transform(data_reloaded)
# Validate the reloaded results
print("Reloaded Data:\n", data_reloaded)
print("Reloaded Labels:", labels_reloaded)
# Visualize reloaded clustering results
plt.scatter(data_rescaled[:, 0], data_rescaled[:, 1], c=labels_reloaded, cmap='viridis', s=100)
plt.title("Reloaded Agglomerative Clustering Results (from Array)")
plt.xlabel("Standardized Math Score")
plt.ylabel("Standardized English Score")
plt.show()
Explanation- Save Results:
- Store clustering results in an in-memory dictionary (
clustering_result). - Save
data, labels, and scaler parameters (mean_ and scale_).
- Load Results:
- Directly access the dictionary (
loaded_result) to retrieve the saved data.
- Reconstruction:
- Use saved scaler parameters to recreate the
StandardScaler object. - Rescale the data if needed for further use or validation.
- Visualization:
- Ensure the results are consistent by reusing the saved labels and data for plotting.
This method is efficient for scenarios where data needs to be shared across functions or modules in memory without file-based serialization. |