| Python is not designed to be inherently single-threaded, although its Global Interpreter Lock (GIL) limits true parallelism for CPU-bound tasks within a single process. While the GIL prevents multiple native threads from executing Python bytecodes simultaneously, Python supports multiprocessing to leverage multiple CPU cores and asynchronous programming techniques to handle I/O-bound operations concurrently, achieving parallelism in practice. But sometimes, you may be able to see your code only use a single processor even though there are plenty of resources available with htop : 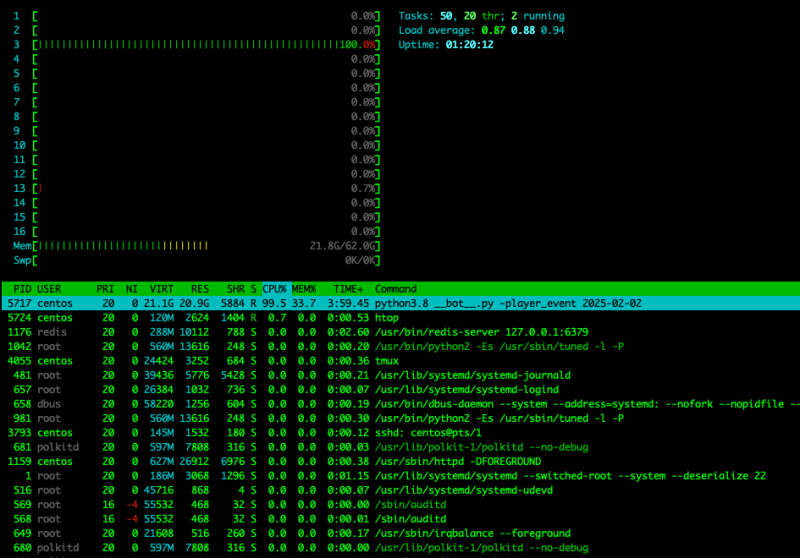
Running Python code to utilize multiple CPU cores effectively for computational tasks requires understanding Python's concurrency model, particularly the Global Interpreter Lock (GIL). For CPU-bound tasks, simple options primarily involve using separate processes rather than threads to achieve true parallelism. Simple Options for Parallel Processing1. multiprocessing ModuleThe multiprocessing module is a package that supports spawning processes using an API similar to the threading module. It allows you to leverage multiple CPU cores on a single machine by running tasks in separate processes. - When to use: Ideal for CPU-bound tasks where each sub-task is independent or requires minimal inter-process communication.
- Key components:
Process class: For more manual control, you can create and manage individual processes. This is similar to threading.Thread.Pool class: This is often the simplest and most common approach for "embarrassingly parallel" problems. A Pool manages a fixed number of worker processes (typically equal to the number of CPU cores) to which you can submit tasks.pool.map(func, iterable): Applies a function func to each item in iterable in parallel and returns a list of results in order. This is synchronous.pool.apply_async(func, args): Submits a single task asynchronously.pool.starmap(func, iterable_of_args): Similar to map but unpacks argument tuples.
Simple Example (Conceptual Pool usage): import multiprocessing
import os
def cpu_bound_task(number):
"""A placeholder for a CPU-intensive computation."""
# Simulate some heavy computation
_ = [x*x for x in range(10**6)]
return f"Processed {number} on PID {os.getpid()}"
if __name__ == "__main__":
# Get the number of CPU cores available
num_cores = os.cpu_count()
print(f"Number of CPU cores available: {num_cores}")
# Create a Pool of worker processes
# By default, Pool uses os.cpu_count() processes
with multiprocessing.Pool() as pool:
# Example using pool.map for an embarrassingly parallel task
data_to_process = range(10) # Process 10 items
results = pool.map(cpu_bound_task, data_to_process)
print("\nResults:")
for result in results:
print(result)
2. concurrent.futures ModuleThe concurrent.futures module provides a high-level interface for asynchronously executing callables. It offers two types of executors: ThreadPoolExecutor (for threads) and ProcessPoolExecutor (for processes). - When to use: Offers a slightly more modern and cleaner API than direct
multiprocessing for many use cases, especially when you want to submit tasks and retrieve results via "futures." ProcessPoolExecutor: This executor internally uses the multiprocessing module to create a pool of processes. It is the preferred choice for CPU-bound tasks when using concurrent.futures.
Simple Example (Conceptual ProcessPoolExecutor usage): from concurrent.futures import ProcessPoolExecutor
import os
def cpu_bound_task(number):
"""A placeholder for a CPU-intensive computation."""
_ = [x*x for x in range(10**6)]
return f"Processed {number} on PID {os.getpid()}"
if __name__ == "__main__":
num_cores = os.cpu_count()
print(f"Number of CPU cores available: {num_cores}")
# Create a ProcessPoolExecutor
# max_workers can be set to num_cores or left to default (os.cpu_count())
with ProcessPoolExecutor(max_workers=num_cores) as executor:
data_to_process = range(10)
# map method returns results in order, similar to multiprocessing.Pool.map
results = executor.map(cpu_bound_task, data_to_process)
print("\nResults:")
for result in results:
print(result)
3. Leveraging Libraries with C ExtensionsMany popular Python libraries for numerical computing and data science (e.g., NumPy, SciPy, Pandas, scikit-learn) have their core performance-critical routines implemented in optimized C, C++, or Fortran. - How it works: When these underlying C/C++/Fortran functions are called, they can release the GIL. This allows them to perform computations using multiple threads (often implicitly, relying on optimized linear algebra libraries like OpenBLAS or Intel MKL) without being constrained by Python's GIL.
- Simplicity: For many common data processing and scientific computing tasks, the "simplest" way to maximize CPU cores is often to just use these libraries correctly. If you perform array operations with NumPy or matrix multiplications with SciPy, they will often automatically utilize multiple cores if the underlying libraries are compiled to do so.
Example: A complex NumPy array operation might run on multiple cores without explicit multiprocessing code from you, as the underlying C implementation handles the parallelism. import numpy as np
# This operation might leverage multiple cores if NumPy is linked against
# a multi-threaded BLAS/LAPACK implementation (like OpenBLAS, MKL).
matrix_a = np.random.rand(5000, 5000)
matrix_b = np.random.rand(5000, 5000)
# Matrix multiplication (often parallelized by underlying C libraries)
result_matrix = matrix_a @ matrix_b
print(f"Matrix multiplication completed. Shape: {result_matrix.shape}")
General Considerations- Overhead: Creating processes has a higher overhead (memory and time) than creating threads. Only use multiprocessing when the computational gain outweighs this overhead.
- Inter-Process Communication (IPC): If your tasks need to share large amounts of data, consider the cost and complexity of inter-process communication (e.g., queues, pipes, shared memory), which
multiprocessing also supports. For simple map-like scenarios, data is often passed via pickling, which has its own overhead. - Number of Workers: Typically, set the number of worker processes to be equal to or slightly less than the number of physical CPU cores on your machine to avoid excessive context switching overhead.
- I/O-bound vs. CPU-bound: Remember that multiprocessing is primarily for CPU-bound tasks. For I/O-bound tasks (e.g., reading/writing files, network requests),
threading can be more suitable because the threads spend most of their time waiting, during which the GIL can be released to allow other threads to run.
|