Memory Problems with Python Arrays? Discover Dask Array
CK 3788 Created at
32900
Have you ever run out of memory while trying to perform operations using an array? So, were you upset because you had to spend more money while upgrading memory? I investigated whether there was a programming language-level solution, not a system-level one that uses disk as virtual memory. Then I learned that Python has something called Dask Array.
Dask Array is a parallelized, larger-than-memory, and out-of-core extension of NumPy arrays. It is designed to scale computations beyond the limits of a single machine's memory, making it ideal for large-scale data processing in scientific computing and data science. Its key characteristics include:
Lazy Evaluation: Dask Array operations don't immediately execute; instead, they build a "task graph." This graph represents all the computations to be performed. Actual computation only occurs when a .compute() method is explicitly called. This allows Dask to optimize the execution plan and manage memory efficiently.
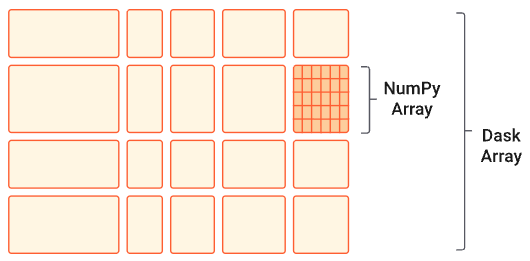
Out-of-Core/Larger-than-Memory: Dask Array can handle datasets that are larger than the available RAM. It achieves this by dividing large arrays into smaller NumPy arrays (chunks) and processing these chunks independently. Data can be streamed from disk, network, or other sources, ensuring only relevant chunks are loaded into memory at any given time.
Parallel and Distributed Computing: Dask automatically parallelizes operations across multiple cores on a single machine or distributes computations across multiple machines in a cluster. This significantly speeds up processing for large datasets.
NumPy API Compatibility: Dask Array strives to mimic the NumPy API as closely as possible. This makes it easy for existing NumPy users to transition to Dask Array, as many familiar functions and methods (e.g., mean, sum, slicing, element-wise operations) work similarly.
Chunking: The fundamental mechanism for Dask Array is dividing a large array into a collection of smaller, independent NumPy arrays called chunks. Operations are then performed on these individual chunks, allowing for parallelization and out-of-core processing.
Scalability: Dask Array scales seamlessly from local multi-core machines to large distributed clusters, providing a consistent API across different execution environments.
Optimized for Numerical Workloads: It is particularly powerful for numerical computations, array manipulations, and scientific workflows that involve high-dimensional data.
Dask Array vs. NumPy vs. Common Array: A Comparison Table
This table compares Dask Array with NumPy arrays and a "Common Array" (representing typical in-memory array structures like Python's list of list or basic fixed-size arrays in other languages), with a focus on how they handle memory constraints.
General-purpose data storage, often less optimized
Memory Management
Out-of-core/Disk-backed: Can handle datasets larger than RAM by processing data in chunks from disk/network. Only a subset of data needs to be in memory at any given time.
In-memory: Requires the entire dataset to fit into RAM. If data exceeds RAM, it will lead to memory errors or significant slowdowns due to swapping.
In-memory: Requires the entire dataset to fit into RAM. Can be highly memory inefficient for numerical data due to object overhead.
Computation Model
Lazy evaluation: Builds a task graph; computations are executed only when .compute() is called. This allows for optimized execution and memory management across chunks.
Eager execution: Computations happen immediately. The full input data is loaded and processed in one go.
Eager execution: Computations happen immediately. Data is processed directly.
Parallelism
Parallel & Distributed: Automatically parallelizes operations across multiple cores, machines, or clusters using its scheduler.
Single-machine (multi-core via underlying C/Fortran libraries): Operations are often highly optimized for single-machine CPU/GPU, but explicitly parallelizing across multiple machines is complex and not built-in.
Single-threaded: Typically operates in a single thread unless explicitly parallelized by the user, which is complex and often less efficient.
Scalability
Highly scalable from local machine to large clusters.
Limited to the resources (CPU, RAM) of a single machine.
Limited to the resources of a single machine.
API
NumPy-like API, making transition easy.
Standard for numerical operations in Python.
Basic operations, often less optimized for numerical tasks and lacking advanced array manipulation functions.
Use Cases
Big data analytics, scientific computing with large datasets (e.g., climate models, image processing), machine learning on large datasets.
Medium-to-large in-memory datasets, general scientific computing, small-to-medium-scale data analysis.
Small datasets, general-purpose data storage and manipulation, basic programming tasks.
Overhead
Higher overhead due to chunking, task graph building, and scheduling.
Minimal overhead for in-memory operations.
High overhead for numerical operations compared to NumPy due to Python object handling.
Dask Array Usage Example and Explanation
This example demonstrates how to create a Dask Array, perform some common operations, and trigger the computation.
import dask.array as da
import numpy as np

# 1. Create a Dask Array
# We'll create a 2D array of 10,000 x 10,000 random floating-point numbers.
# If stored as float64, this would be ~800MB (10000 * 10000 * 8 bytes).
# We specify 'chunks=(1000, 1000)', meaning Dask will break this large array
# into smaller 1000x1000 NumPy arrays.
shape = (10000, 10000)
chunks = (1000, 1000)

print("--- Creating a Dask Array ---")
x = da.random.random(shape, chunks=chunks)
print(f"Dask Array 'x' created:\n{x}")
print(f"Type of x before computation: {type(x)}")
print(f"Number of chunks: {x.numblocks}")

# 2. Perform some NumPy-like operations (Lazy Evaluation)
# These operations do not immediately compute results. Instead, they build a task graph
# representing the sequence of operations to be performed.

print("\n--- Performing Lazy Operations ---")

# Element-wise addition
y = x + 10
print(f"Operation 'x + 10' creates new Dask Array 'y':\n{y}")

# Mean along rows (axis=1)
z = y.mean(axis=1)
print(f"Operation 'y.mean(axis=1)' creates new Dask Array 'z':\n{z}")

# More complex operations can be chained
# For example, calculate the sum of squares of elements in z
result_dask = (z**2).sum()
print(f"Final lazy computation ' (z**2).sum() ' creates Dask Scalar 'result_dask':\n{result_dask}")
print(f"Type of result_dask before computation: {type(result_dask)}")

# At this point, no heavy numerical computation has occurred. Dask has only
# constructed a plan (a task graph) for how to perform these operations.

# 3. Trigger Computation
# The actual computation happens when .compute() is called on a Dask object.
# Dask will execute the entire task graph, managing memory and parallelism automatically.
print("\n--- Triggering Computation ---")
final_value = result_dask.compute()
print(f"Computed final value: {final_value}")
print(f"Type of final_value after computation: {type(final_value)}")

# You can also compute intermediate results
# intermediate_z_value = z.compute()
# print(f"\nComputed intermediate 'z' array of shape {intermediate_z_value.shape}")
This line creates a Dask Array. It doesn't immediately generate all 10,000x10,000 random numbers and store them in memory.
Instead, it creates a Dask object (da.Array) that knows how to generate these random numbers in chunks when needed.
The chunks=(1000, 1000) parameter is crucial. It tells Dask to conceptualize this large array as a grid of smaller 1000x1000 NumPy arrays. This allows Dask to process and store only a portion of the data in memory at any given time.
The output x is a dask.array.core.Array object, not a NumPy array. It contains metadata about the array's shape, data type, and chunking.
2. Lazy Operations (y = x + 10, z = y.mean(axis=1), result_dask = (z2).sum()):
When you perform operations on a Dask Array (like +, .mean(), 2, .sum()), Dask does not perform the actual calculation immediately.
Instead, it records these operations in a task graph. Each operation adds nodes to this graph, describing how the output chunks depend on the input chunks.
For example, y = x + 10 creates a new Dask Array y that represents "take the chunks of x and add 10 to each of them."
Similarly, z = y.mean(axis=1) defines how to compute the mean across the rows of the y chunks.
The result_dask object is a dask.array.core.Array (or a dask.array.reduction.Array which is a scalar Dask Array) representing the final, chained computation. Notice that its type is still a Dask object, not a standard Python float or int.
This is the moment when Dask actually executes the entire task graph built up from all the lazy operations.
Dask efficiently orchestrates the loading of necessary chunks, performs the operations (potentially in parallel across multiple cores or machines), and manages memory by only keeping relevant chunks in RAM.
The compute() method returns a standard NumPy array or a Python scalar (like a float in this case), which is the final, concrete result of all the calculations.
This example highlights Dask Array's ability to define complex computations on potentially huge datasets without requiring the entire dataset to fit into memory, thanks to its chunking and lazy evaluation model.