Demystifying FAISS: Your Guide to ANN(Approximate Nearest Neighbor) Search
CK 3788 Created at
32700
Approximate Nearest Neighbor (ANN) search is fundamental for many modern applications, from recommendation systems to generative AI. When dealing with millions or billions of high-dimensional vectors, exact search becomes computationally infeasible. This is where ANN algorithms, and powerful libraries like FAISS, come into play.
The Essence of ANN: Why Approximate?
When faced with a massive dataset of vectors, finding the truly closest (exact) neighbors for a given query vector means comparing it against every single vector in the dataset.
Approach
Complexity
1 Million (128-dim) Vectors
1 Billion Vectors
Exact (Brute-force)
O(N × d)
~100 ms
~100 seconds (impractical)
ANN (IVF+PQ)
O(Nprobe × k × d/M)
~1 ms
~10 ms
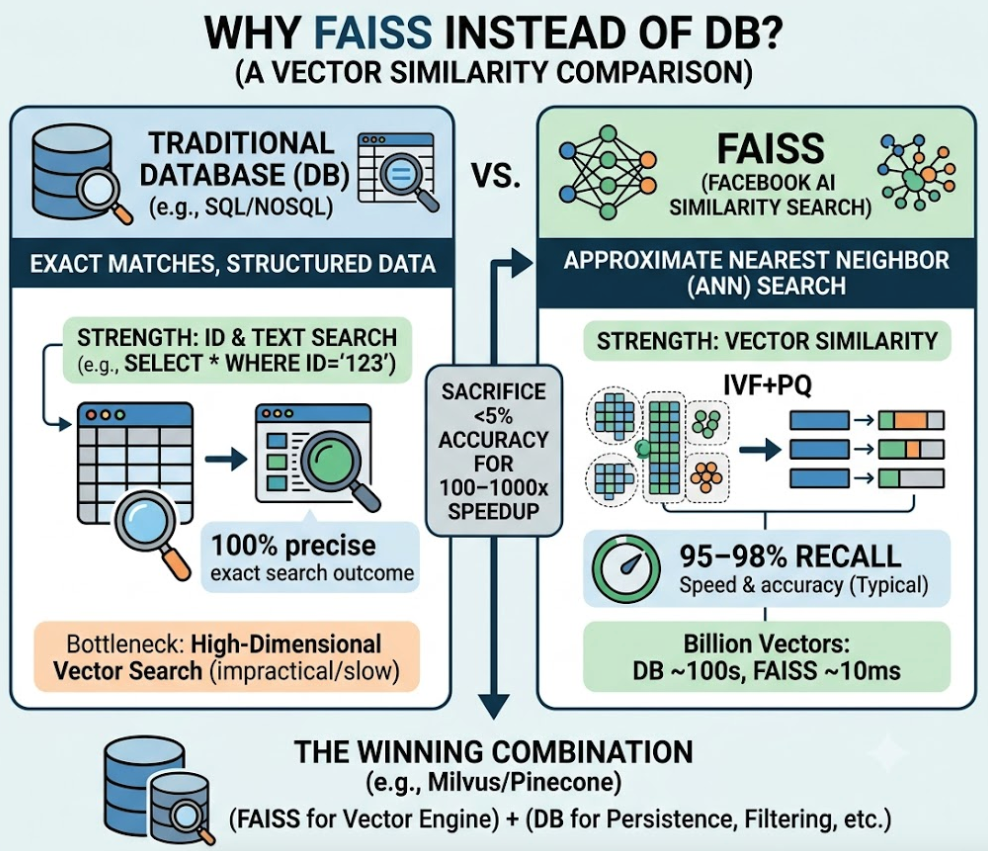
As the table illustrates, exact search's complexity O(N × d) (where N is the number of vectors and d is dimension) quickly becomes a bottleneck. ANN techniques sacrifice a small amount of accuracy (typically 2-5%) to achieve a 100-1000x speedup, making billion-scale vector search practical.
Why FAISS instead of DB?
FAISS, while handling data storage and retrieval, isn't a general-purpose database but a specialized library for efficient similarity search over high-dimensional vectors.
Traditional databases excel at exact matches, filtering structured data, and complex relational queries based on distinct attributes like IDs or text fields, making them highly inefficient for finding items similar to a given vector in high-dimensional space.
FAISS, however, employs optimized indexing algorithms like approximate nearest neighbor (ANN) search to quickly identify vectors that are geometrically close to a query vector, making it indispensable for applications like semantic search, recommendation systems, or deduplication, where speed and scale are critical for vector-based similarity without the overhead of general-purpose database operations.
Can FAISS be used as a recommendation system?
FAISS can be effectively utilized for recommendation systems by representing items or users as high-dimensional vectors.
To implement this functionality, first generate these vectors, often called embeddings, using techniques such as collaborative filtering (e.g., matrix factorization, ALS), deep learning models (e.g., autoencoders, transformers), or by extracting content-based features.
Once these item or user embeddings are created, build a FAISS index from them for efficient storage and similarity search.
When a recommendation is required, convert the query (e.g., the current user's vector or a seed item's vector) into its corresponding embedding and then query the FAISS index to rapidly retrieve its nearest neighbors, which then serve as the recommended items or users.
FAISS: The ANN Powerhouse
FAISS (Facebook AI Similarity Search) is a high-performance library designed for efficient similarity search and clustering of dense vectors. It's crucial to understand that FAISS is an ANN library; it implements various ANN algorithms rather than being "combined" with ANN as a separate entity. Think of it this way:
FAISS provides a unified API to access a wide range of these algorithms, allowing users to select the most suitable one based on their specific needs.
Core ANN Algorithms within FAISS
FAISS offers several sophisticated algorithms, each with its own strengths and trade-offs.
1. IVF (Inverted File Index): Clustering for Speed
IVF is one of the most widely used ANN methods in FAISS, leveraging a clustering approach.
How it Works:
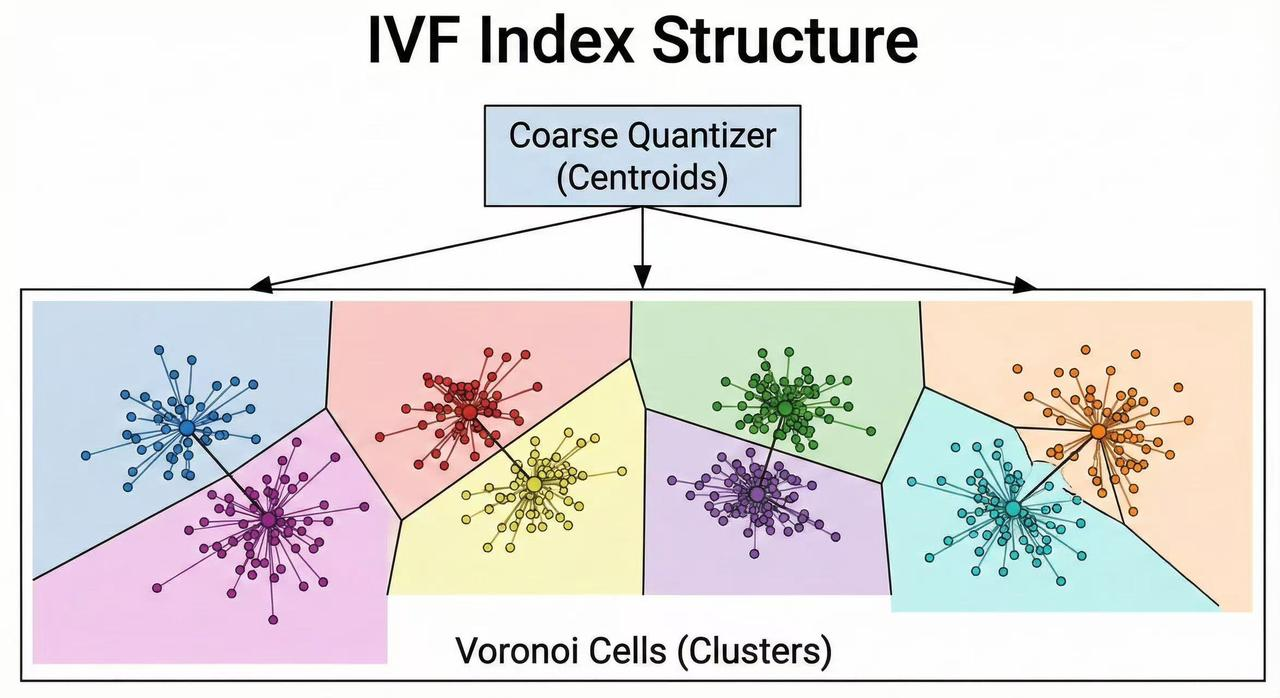
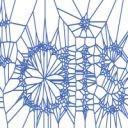
Training: The algorithm first partitions the vector space into nlist Voronoi cells (clusters) using a technique like k-means. This creates a set of centroids.
Adding Vectors: Each vector is assigned to its nearest centroid's cell. This creates an inverted index, mapping centroids to the vectors within their cells.
Searching: For a query vector, FAISS identifies the nprobe closest centroids. The search is then restricted to only the vectors within these nprobe cells, skipping the vast majority of the dataset.
Example: If you have 1 million vectors, nlist=1024, and nprobe=16, you are effectively comparing against only about 1M × (16/1024) ≈ 15,600 vectors, skipping over 98% of the data.
Tuning the Trade-off:
nlist: A larger nlist creates more, smaller cells. This can make the search faster initially but might cause boundary vectors to be missed if nprobe is too small.
nprobe: Increasing nprobe means more cells are searched, leading to higher recall (better accuracy) but at the cost of increased latency.
Rule of thumb: A common starting point is nlist ≈ sqrt(N) and nprobe between nlist/10 and nlist/4.
2. HNSW (Hierarchical Navigable Small World): Graph-Based Efficiency
HNSW is a powerful graph-based ANN algorithm, known for its excellent balance of speed and accuracy, particularly for datasets up to tens of millions of vectors.
How it Works:
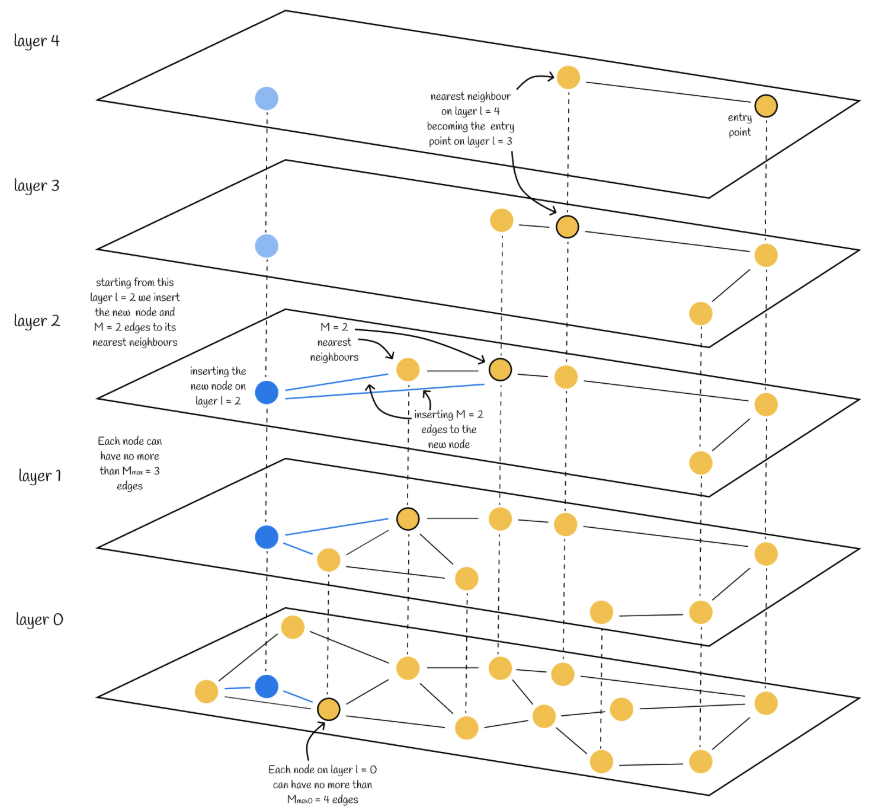
Graph Construction: HNSW builds a multi-layer graph where each layer is a "navigable small world" graph. Higher layers are sparser, providing shortcuts for long-range navigation, while lower layers are denser, enabling fine-grained searches.
Search: The search starts at the highest layer, greedily traversing the graph to find the nearest neighbors. It then moves down to a denser layer, refining the search until the lowest layer is reached for precise proximity.
Characteristics:
Lower Latency: Often achieves logarithmic search time O(log N), which can be faster than IVF for smaller nprobe settings.
Higher Memory Usage: Requires more memory to store the graph edges.
Slower Index Build Time: Graph construction can be computationally intensive.
Ideal for Medium Scale: Highly effective for datasets up to around 10 million vectors.
3. PQ (Product Quantization): The Compression Engine
While not an ANN search algorithm on its own, Product Quantization (PQ) is a crucial compression technique often combined with ANN methods like IVF to drastically reduce memory footprint and speed up distance calculations.
How it Works:
Subvector Splitting: A high-dimensional vector (e.g., 128 dimensions) is divided into M smaller subvectors (e.g., 8 subvectors of 16 dimensions each).
Quantization: For each subvector, a separate k-means clustering is performed, creating a small codebook of centroids. Each subvector is then replaced by the ID of its closest centroid in its respective codebook.
Compression: This converts a large floating-point vector (e.g., 512 bytes for 128 floats) into a compact sequence of centroid IDs (e.g., 8 bytes for 8 subvectors). This represents a massive compression (e.g., 97% reduction).
Distance Calculation: PQ utilizes Asymmetric Distance Computation (ADC). The query vector remains in its original form, while database vectors are in their compressed PQ code form. Distances are then calculated efficiently using pre-computed lookup tables between query subvectors and codebook centroids.
The Winning Combination: IVF + PQ
In practical, large-scale applications, the most common and effective strategy is to combine IVF for approximate search with PQ for vector compression. This addresses both search speed and memory efficiency.
# Example of creating an IVF+PQ index using FAISS's index_factory
import faiss
d = 128 # vector dimension
index = faiss.index_factory(d, "IVF4096,PQ16")
# IVF: Divides the vector space into 4096 clusters for approximate search.
# PQ:  Compresses each vector into 16 subvectors (16 bytes if 8 bits per code).
This combination is key to achieving millisecond search times on billion-scale datasets:
IVF efficiently narrows down the search space to a few relevant clusters.
PQ then allows for fast, memory-efficient comparisons within those selected clusters, by working with compressed vector representations.
This is the practical answer to how ANN algorithms are leveraged within FAISS for high-performance similarity search.
Navigating Index Types: A Selection Guide
Choosing the right FAISS index type depends heavily on your dataset size and performance requirements.
Data Scale
Recommended Index
Index Factory String
Typical Recall
Latency
< 10K
Flat
"Flat"
100%
< 1ms
10K - 100K
IVFFlat
"IVF256,Flat"
~95%
< 5ms
100K - 1M
HNSW or IVFFlat
"HNSW32"
~97%
< 1ms
1M - 10M
IVF+PQ
"IVF4096,PQ16"
~85%
< 5ms
10M - 100M
IVF+PQ (tuned)
"OPQ16,IVF16384,PQ16"
~90%
< 10ms
100M+
IVF+PQ + Sharding
(Distributed)
~85%
< 20ms
Distance Metrics in FAISS
Selecting the correct distance metric is crucial for meaningful similarity search.
L2 (Euclidean Distance): The default and most common metric, measuring the straight-line distance between two points.
index = faiss.IndexFlatL2(d)
Inner Product: Widely used in recommendation systems, where higher inner product signifies higher similarity.
index = faiss.IndexFlatIP(d)
Cosine Similarity: Measures the cosine of the angle between two vectors. FAISS does not have a native cosine similarity metric. To achieve it, you must first L2-normalize your vectors, then use Inner Product. After normalization, maximizing inner product is equivalent to maximizing cosine similarity.
faiss.normalize_L2(vectors) # Normalize all vectors before adding to index
index = faiss.IndexFlatIP(d)
FAISS: An Engine, Not a Database
It's essential to distinguish FAISS from full-fledged vector databases like Milvus or Pinecone.
Feature
FAISS
Vector Databases (Milvus, Pinecone)
Type
Library (in-process)
Distributed DB / Managed Service
Persistence
None (in-memory)
Built-in (disk / cloud storage)
Filtering
Post-search only
Pre- and post-search metadata filtering
Replication/HA
Manual
Built-in / Managed
Latency
Lowest (zero overhead)
10-100ms (network, DB overhead)
Use Case
Direct embedding control, highest performance, specific application needs
Many vector databases, including Milvus, leverage FAISS as their underlying search engine. FAISS provides the core ANN capabilities, while vector databases add persistence, distributed architecture, metadata filtering, and operational tooling on top. Your choice depends on whether you need a raw, high-performance engine or a feature-rich, managed database solution.
Practical Considerations for Production
When deploying FAISS, several practical challenges and solutions arise:
1) Handling Updates and Deletions
FAISS indexes are largely append-only. For updates or deletions, common strategies include:
Two-Index Strategy: Maintain a main, periodically rebuilt index and a smaller "staging" index for recent additions. Merge them on a schedule.
ID Exclusion List: For deletions, query the FAISS index and then filter out excluded IDs from the results in application logic.
These approaches highlight one area where vector databases offer a clear advantage with built-in update/delete functionalities.
2) The Accuracy-Speed Trade-off
This is a critical balance to strike. In IVF, the nprobe parameter is the primary knob:
Higher nprobe searches more clusters, increasing recall (accuracy) but linearly increasing latency.
Similarly, for PQ, a larger number of subvectors (M) gives better distance approximation but uses more memory.
In production, it's crucial to profile recall@k against latency at different parameter values (e.g., nprobe) and select the configuration that meets both accuracy and performance targets.
3) Scaling FAISS to Billion Vectors
While demanding, scaling FAISS to a billion vectors is achievable: IVF+PQ for Compression: Using highly compressed IVF+PQ indexes can reduce each vector to ~16 bytes, allowing 1 billion vectors to fit into ~16GB of RAM (or more depending on M).
Sharding: Distribute the dataset across multiple machines, with each machine holding a partition of the index. Queries are sent to all shards, and results are aggregated.
Memory-Mapped Indexes: For datasets exceeding available RAM on a single machine, FAISS supports memory-mapped indexes to utilize disk storage efficiently.
GPU Acceleration: For index training (e.g., k-means clustering for IVF), GPU-accelerated FAISS can drastically reduce training times.
At this scale, the operational overhead can be significant, which might lead one to consider distributed systems like Milvus for reduced management burden.
Core Code Example
Let's illustrate the creation and use of an IVF+PQ index in FAISS.
import faiss
import numpy as np

d = 128          # embedding dimension
n = 1_000_000   # dataset size (1 million vectors)
nlist = 4096     # Number of IVF clusters
m = 16           # Number of PQ subvectors (e.g., 16 means each vector becomes 16 bytes if 8 bits per code)

# 1. Generate example vectors (in a real scenario, these would be embedding model outputs)
xb = np.random.random((n, d)).astype('float32') # Database vectors
xq = np.random.random((10, d)).astype('float32') # Query vectors

# 2. Create the Index (IVF + PQ)
# Option A: Manual creation
quantizer = faiss.IndexFlatL2(d) # The quantizer (e.g., for clustering centroids)
index = faiss.IndexIVFPQ(quantizer, d, nlist, m, 8) # 8 bits per code for each subvector

# Option B: Using index_factory (recommended for simplicity)
# index = faiss.index_factory(d, "IVF4096,PQ16")

# 3. Training the index (learns nlist centroids and PQ codebooks)
# This step is crucial for IVF and PQ. It should be done on a representative subset of data.
print("Training index...")
index.train(xb)
print("Index trained.")

# 4. Add vectors to the index
print("Adding vectors...")
index.add(xb)
print(f"Total vectors in index: {index.ntotal}")

# 5. Search for nearest neighbors
index.nprobe = 32 # Set the number of clusters to search (adjust for recall/latency)
k = 10            # Number of nearest neighbors to retrieve
print(f"Searching with nprobe={index.nprobe}...")
D, I = index.search(xq, k) # D: distances, I: indices of nearest neighbors
print("Search complete. Example results:")
print("Distances:\n", D[:2]) # Display distances for first two queries
print("Indices:\n", I[:2])   # Display indices for first two queries

# 6. (Optional) Measure Recall against an exact search for evaluation
print("\nMeasuring recall...")
index_flat = faiss.IndexFlatL2(d) # An exact, brute-force index
index_flat.add(xb)
D_exact, I_exact = index_flat.search(xq, k)

# Calculate recall@k
recall_at_k = np.mean([len(set(I[i]) & set(I_exact[i])) / k for i in range(len(xq))])
print(f"Recall@{k}: {recall_at_k:.3f}")