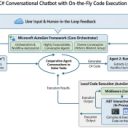
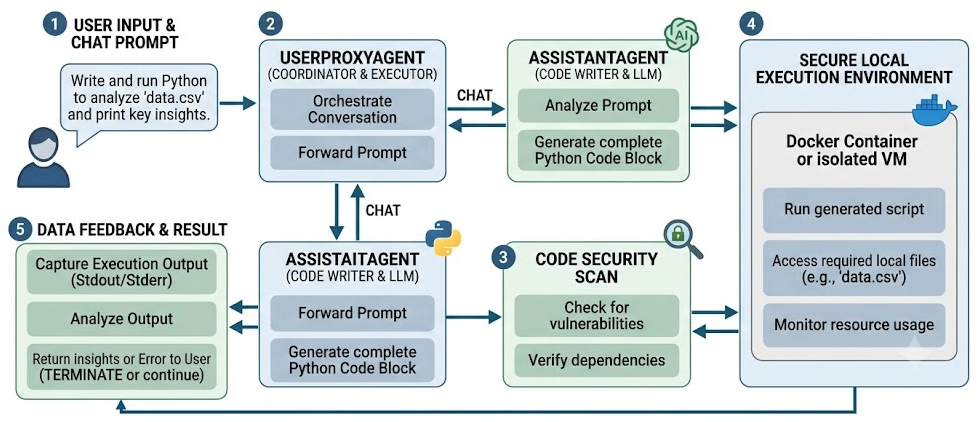
| To build a chatbot using Microsoft's AutoGen framework that can automatically write and execute Python code based on your chat prompt, you can use the autogen library. In AutoGen, the standard setup involves two main agents: - An AssistantAgent that acts as the LLM (writing the code).
- A UserProxyAgent that acts as the proxy for the user, which is also capable of automatically running the code blocks inside a secure docker container or a local execution environment.
PrerequisitesFirst, install the AutoGen package: pip install autogen
Python Code Example (using AutoGen and Llama)Since you want to use Llama as the underlying LLM, you can route it through a local server like Ollama, LM Studio, or LiteLLM that provides an OpenAI-compatible API endpoint. Here is a complete example setup using AutoGen to create a code-writing and code-executing chatbot loop: import os
from autogen import AssistantAgent, UserProxyAgent
# 1. Define the LLM configuration pointing to your local Llama model
# Assumes you have Ollama or a similar service running locally on port 11434
config_list = [
{
"model": "llama3.1", # The name of your local Llama model
"base_url": "http://localhost:11434/v1", # OpenAI-compatible endpoint
"api_key": "ollama", # Placeholder key required by the client
}
]
llm_config = {
"config_list": config_list,
"temperature": 0.1, # Lower temperature for accurate coding
}
# 2. Create the Assistant Agent (The Code Writer)
assistant = AssistantAgent(
name="coder_assistant",
llm_config=llm_config,
system_message="You are an expert Python developer. Write clean, complete Python code blocks "
"enclosed in ```python ... ``` when asked to solve a problem. Do not provide "
"partial snippets. Include print statements so the output can be clearly seen."
)
# 3. Create the User Proxy Agent (The Code Executor)
user_proxy = UserProxyAgent(
name="user_proxy",
human_input_mode="NEVER", # Automatically execute code without asking the user each time
max_consecutive_auto_reply=3, # Limit conversation rounds to avoid infinite loops
is_termination_msg=lambda x: x.get("content", "").rstrip().endswith("TERMINATE"),
code_execution_config={
"work_dir": "coding_workspace", # Directory where files will be saved and executed
"use_docker": False, # Set to True if you want to isolate code execution in Docker
}
)
def ask_chatbot(prompt: str):
print(f"🚀 User Prompt: {prompt}\n")
# Start the conversation loop
user_proxy.initiate_chat(
assistant,
message=prompt
)
if __name__ == "__main__":
# Create the workspace directory if it doesn't exist
os.makedirs("coding_workspace", exist_ok=True)
# Example task
sample_prompt = (
"Write a Python script that fetches the current price of Bitcoin using a public API "
"and prints it formatted cleanly. Once done, output TERMINATE."
)
ask_chatbot(sample_prompt)
How this works under the hood:AssistantAgent: Receives the text prompt, thinks through the solution, and generates a response containing standard markdown code blocks.UserProxyAgent: Scans the incoming message from the assistant. If it finds a ```python block, it automatically extracts the code, writes it to a file inside the coding_workspace directory, runs it locally, and sends the standard output/error back to the assistant.- Termination: The conversation naturally concludes when the agent outputs
TERMINATE, or when it reaches the max_consecutive_auto_reply limit.
Improving Intelligence by AutoGen Group ChatTo significantly improve intelligence and add structured reasoning, we can transition this setup into an AutoGen Group Chat. By doing this, we keep your two existing core agents (coder_assistant and user_proxy) but inject a third specialized agent—a code_reviewer (or critic)—into the loop. This introduces a "Review and Refine" architecture where the code isn't just blindly executed: it gets verified, optimized, or fixed before or after the execution phase. Here is the updated code implementing this multi-agent logic: import os
from autogen import AssistantAgent, UserProxyAgent, GroupChat, GroupChatManager
# 1. Define the LLM configuration pointing to your local Llama model
config_list = [
{
"model": "llama3.1",
"base_url": "http://localhost:11434/v1",
"api_key": "ollama",
}
]
llm_config = {
"config_list": config_list,
"temperature": 0.1,
}
# 2. Existing Agent 1: The Code Writer
assistant = AssistantAgent(
name="coder_assistant",
llm_config=llm_config,
system_message="You are an expert Python developer. Write clean, complete Python code blocks "
"enclosed in ```python ... ``` when asked to solve a problem or when fixing bugs "
"pointed out by the code_reviewer. Do not provide partial snippets."
)
# 3. New Agent: The Code Reviewer / Critic (Improves Intelligence)
# This agent analyzes the written code or execution output for logic gaps, security issues, or bugs.
reviewer = AssistantAgent(
name="code_reviewer",
llm_config=llm_config,
system_message="You are a Senior Quality Assurance Engineer and Code Reviewer. Analyze code written by "
"the coder_assistant or execution results from the user_proxy. "
"Verify if requirements are fully met, look for edge cases, and ensure clean coding standards. "
"If the code looks perfect and execution output matches expectations, reply ONLY with 'TERMINATE'. "
"Otherwise, state exactly what needs to be fixed or improved so the coder_assistant can adjust it."
)
# 4. Existing Agent 2: The User Proxy & Code Executor
user_proxy = UserProxyAgent(
name="user_proxy",
human_input_mode="NEVER",
max_consecutive_auto_reply=6, # Higher limit to accommodate multi-turn planning
is_termination_msg=lambda x: "TERMINATE" in x.get("content", ""),
code_execution_config={
"work_dir": "coding_workspace",
"use_docker": False,
}
)
def ask_intelligent_chatbot(prompt: str):
print(f"🚀 User Prompt: {prompt}\n")
# 5. Define the Group Chat orchestration
# We bring together all agents into a unified conversation ecosystem
groupchat = GroupChat(
agents=[user_proxy, assistant, reviewer],
messages=[],
max_round=12
)
manager = GroupChatManager(
groupchat=groupchat,
llm_config=llm_config
)
# Start the group conversation loop via the manager proxy
user_proxy.initiate_chat(
manager,
message=prompt
)
if __name__ == "__main__":
os.makedirs("coding_workspace", exist_ok=True)
sample_prompt = (
"Write a Python script that fetches the current price of Bitcoin using a public API, "
"calculates what $500 USD is worth in BTC based on that price, and prints it cleanly."
)
ask_intelligent_chatbot(sample_prompt)
Why this increases intelligence:- Iterative Optimization: Instead of a linear write-then-execute flow,
coder_assistant writes the code $\rightarrow$ user_proxy runs it $\rightarrow$ code_reviewer validates the code output. If the code throws an error or fails an edge case, code_reviewer explains the bug, and the orchestrator dynamically routes it back to coder_assistant to refactor. - Deterministic Termination: Instead of the coder declaring it's done prematurely, the
code_reviewer holds the responsibility to issue the final TERMINATE flag only when the script successfully proves its runtime objective.
|