| When building modern AI models or high-throughput media pipelines, you’ll quickly hear the phrase "GPU Cluster." But a true GPU cluster is much more than just a random collection of virtual machines with GPUs attached to them. To make workload scaling work—whether for LLM pre-training or massive batch processing—four primary infrastructure pillars must align seamlessly: - Compute: High-end GPU SKUs (e.g., NVIDIA H100, H200, B200, or AMD MI300X) sized appropriately so single jobs can span multiple nodes simultaneously.
- Interconnect: Ultra-fast, low-latency fabrics (such as InfiniBand, GPUDirect-RDMA, or AWS EFA) ensuring data synchronization operations like
all-reduce do not bottleneck performance. - Storage: High-throughput parallel file systems (like Managed Lustre or AWS FSx for Lustre) feeding datasets to thousands of GPU cores without stalling execution pipelines.
- Orchestration: Management engines like Slurm for batch/HPC workloads, or Kubernetes (GKE/AKS/EKS) for containerized environments.
The Core Concept: Sharding and MergingAt its core, working with a GPU cluster follows a straightforward mental model: Sharding (dividing) the workload across multiple nodes/GPUs, executing the computations in parallel, and merging (synchronizing) the results. 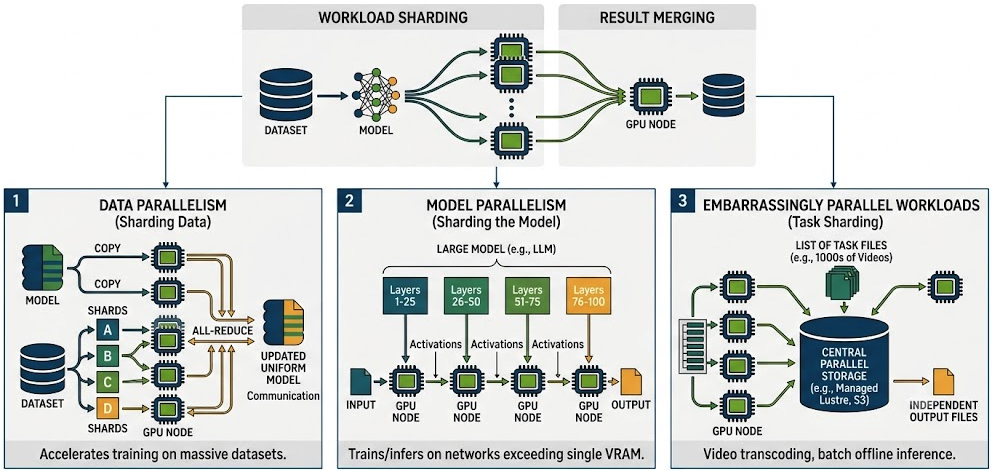
Depending on your task, this sharding pattern takes one of three main forms: 1. Data Parallelism (Sharding Data)- How it works: The model is replicated across every GPU, but the dataset (batch) is split into smaller chunks (shards) and distributed to each worker.
- How it merges: After each GPU completes its forward and backward passes, all GPUs exchange gradients using high-speed collective communication (
All-Reduce) to update weights uniformly. - Use case: Accelerating training speed when you have a massive dataset.
2. Model Parallelism (Sharding the Model)- How it works: When a model (like an LLM with hundreds of billions of parameters) exceeds the VRAM limit of a single GPU, the model layers or tensor matrices are split across multiple GPUs.
- How it merges: GPUs pass intermediate activations step-by-step through the network layers during computation.
- Use case: Training or running inference on massive neural networks.
3. Embarrassingly Parallel Workloads (Task Sharding)- How it works: Tasks are completely independent (e.g., video transcoding using FFmpeg fleets or batch offline inference). A list of thousands of independent files is sharded across worker nodes.
- How it merges: GPUs do not need inter-node communication. Each worker simply saves its output directly to central parallel storage (e.g., Managed Lustre or S3).
What Does This Look Like in Code?Writing code for a GPU cluster differs significantly from single-GPU scripting. You have to account for distributed process groups, distributed data samplers, and parallel checkpointing. Here is a simplified Python example using PyTorch Distributed Data Parallel (DDP): import os
import torch
import torch.distributed as dist
from torch.nn.parallel import DistributedDataParallel as DDP
from torch.utils.data import DataLoader
from torch.utils.data.distributed import DistributedSampler
def init_cluster_env():
# Read cluster environment variables (passed by Slurm or Kubernetes JobSet)
dist.init_process_group(backend="nccl")
local_rank = int(os.environ["LOCAL_RANK"])
torch.cuda.set_device(local_rank)
return local_rank
def train():
local_rank = init_cluster_env()
# 1. Load Model onto assigned GPU and wrap with DDP
model = MyLargeModel().to(local_rank)
model = DDP(model, device_ids=[local_rank])
# 2. Shard dataset across all GPUs in the cluster using DistributedSampler
# Reading directly from high-performance shared storage (e.g., /fsx or /lustre)
dataset = MyDataset(data_path="/lustre/data/train_shard_*.bin")
sampler = DistributedSampler(dataset)
dataloader = DataLoader(dataset, batch_size=32, sampler=sampler)
# 3. Training Loop
optimizer = torch.optim.AdamW(model.parameters(), lr=1e-4)
for epoch in range(10):
sampler.set_epoch(epoch)
for batch in dataloader:
optimizer.zero_grad()
outputs = model(batch.to(local_rank))
loss = outputs.loss
loss.backward() # All-Reduce automatically triggers across GPUs via NCCL/InfiniBand
optimizer.step()
if __name__ == "__main__":
train()
How to Launch Jobs on a ClusterOnce your code is ready, you submit execution scripts to the orchestrator rather than running python train.py directly. Slurm Job Script (sbatch)#!/bin/bash
#SBATCH --job-name=cluster-training
#SBATCH --nodes=4 # Request 4 nodes
#SBATCH --gpus-per-node=8 # Request 8 GPUs per node (32 total GPUs)
#SBATCH --output=/lustre/logs/%j.out
# Run training across all nodes using torchrun
srun torchrun \
--nnodes=4 \
--nproc_per_node=8 \
--rdzv_id=$SLURM_JOB_ID \
--rdzv_backend=c10d \
--rdzv_endpoint=$MASTER_ADDR:$MASTER_PORT \
train.py
SummaryScaling compute with a GPU cluster isn't just about throwing more GPUs at a problem. It’s about structuring your architecture so that Compute, Interconnect, Storage, and Orchestration work together seamlessly. On the coding side, understanding how to shard data/models and synchronize results efficiently is the key to unlocking true cluster scalability. |