Beyond Prompt Engineering: Why Loop Engineering is the Future of Autonomous AI
CK 3788 Created at
31100
If you’ve been building with Large Language Models (LLMs), you’re likely familiar with Prompt Engineering. You type a prompt, evaluate the response, tweak your wording, and send it back. It’s effective, but it has a glaring bottleneck: You.
As AI system architectures evolve, manual human-in-the-loop prompting is giving way to Loop Engineering—a paradigm shift from driving an LLM turn-by-turn to designing self-directed, autonomous feedback environments.
What is Loop Engineering?
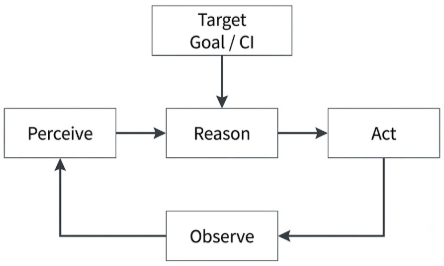
Loop Engineering is an AI engineering discipline focused on building closed-loop execution environments for autonomous agents. Instead of waiting for human input after every turn, an agent continuously cycles through a execution loop:
The agent runs tools, evaluates outputs (like compiler errors or unit test runs), self-corrects, and loops automatically until pre-defined criteria are met.
Key Conceptual Differences
Dimension
Prompt Engineering
Loop Engineering
Primary Focus
Crafting precise inputs to optimize a single response.
Designing systemic environments (tools, state, guardrails) for autonomy.
Human Role
Driver: Evaluates outputs and manually initiates every step.
Architect: Sets objectives, safety boundaries, and validation rules.
Execution Flow
Linear / Single-turn.
Circular & Self-correcting.
Error Handling
Manual prompt adjustments.
Automated via error-catching, tests, and linters.
The Core Challenge: Token Costs & Context Bloat
When an agent iterates in a continuous loop, the raw prompt trace grows exponentially. This causes two major issues:
Cost Inflation: Repeatedly sending thousands of context tokens on every cycle drains API budgets instantly.
Context Saturation: Long transcripts degrade the LLM's reasoning quality.
To build production-grade loops, you need Circuit Breakers and Structured State Management.
Pattern 1: Guardrails & Circuit Breakers
A robust agent loop must prevent runaway spending and infinite retry logic. Key circuit breakers include:
Token & Budget Caps: Stop execution automatically if USD or token thresholds are breached.
Action Deduplication: Hash tool commands. If the agent executes the exact same action multiple times, break the loop to handle stagnation.
Log Truncation: Limit tool output (stdout/stderr) to only critical stack traces before passing it to context.
Pattern 2: Structured Scratchpad Memory
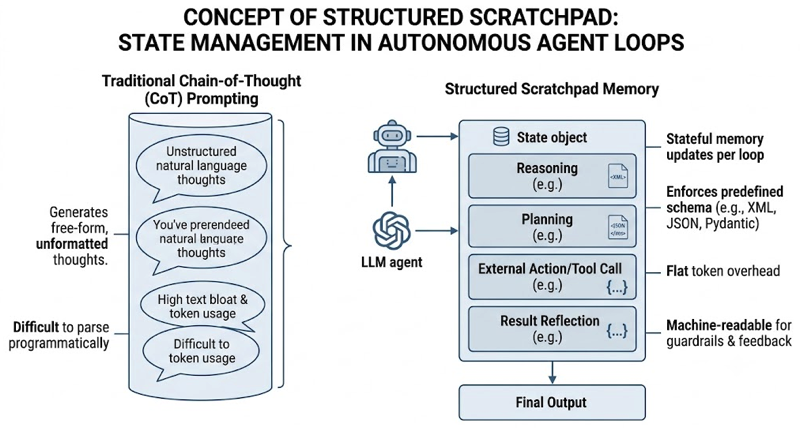
Instead of appending full conversation histories, use a rolling Structured Scratchpad. The agent updates a single state object on every loop, keeping token overhead flat regardless of how many iterations run.
By pairing Pydantic with an LLM's structured output engine, you enforce strict schema validation for the agent's internal memory:
from typing import List, Literal
from pydantic import BaseModel, Field

class ScratchpadState(BaseModel):
    summary_of_last_action: str = Field(
        description="Brief summary of what was attempted in the last turn."
    )
    key_findings: List[str] = Field(
        description="Cumulative list of facts learned so far."
    )
    current_hypothesis: str = Field(
        description="Current working theory regarding the root cause or solution."
    )
    next_planned_action: str = Field(
        description="The specific tool call or action to take next."
    )
    status: Literal["IN_PROGRESS", "NEEDS_HUMAN", "GOAL_ACHIEVED"] = Field(
        description="Operational state of the loop."
    )
Putting It Together: A Self-Correcting Python Loop
Here is an architectural template combining Pydantic state management, token tracking, and stagnation guardrails:
import dataclasses
import hashlib
from openai import OpenAI

class AutonomousAgentLoop:
    def __init__(self, goal: str, max_iterations: int = 5):
        self.goal = goal
        self.max_iterations = max_iterations
        self.scratchpad: ScratchpadState | None = None
        self.history_hashes = set()
        self.client = OpenAI()

    def step_agent(self, last_output: str) -> ScratchpadState:
        """Call LLM with structured outputs to update scratchpad state."""
        system_prompt = "You are an autonomous coding agent. Update your state based on tool outputs."
        user_content = f"GOAL: {self.goal}\n"

        if self.scratchpad:
            user_content += f"PREVIOUS STATE:\n{self.scratchpad.model_dump_json()}\n"
        user_content += f"LATEST TOOL OUTPUT:\n{last_output}"

        response = self.client.beta.chat.completions.parse(
            model="gpt-4o-mini",
            messages=[
                {"role": "system", "content": system_prompt},
                {"role": "user", "content": user_content}
            ],
            response_format=ScratchpadState,
            temperature=0.1
        )
        return response.choices[0].message.parsed

    def run(self):
        last_tool_output = "Initial loop execution started."

        for step in range(1, self.max_iterations + 1):
            print(f"\n--- Iteration {step}/{self.max_iterations} ---")

            # 1. Update Scratchpad
            self.scratchpad = self.step_agent(last_tool_output)
            print(f"Hypothesis: {self.scratchpad.current_hypothesis}")
            print(f"Next Action: {self.scratchpad.next_planned_action}")

            # 2. Check Goal Completion
            if self.scratchpad.status == "GOAL_ACHIEVED":
                print("✅ Goal achieved successfully!")
                return "SUCCESS"

            # 3. Circuit Breaker: Action Stagnation Guard
            action_hash = hashlib.md5(self.scratchpad.next_planned_action.encode()).hexdigest()
            if action_hash in self.history_hashes:
                print("🛑 CIRCUIT BREAKER: Stagnation detected! Same action repeated.")
                return "STAGNATION_DETECTED"
            self.history_hashes.add(action_hash)

            # 4. Simulate Tool Execution
            last_tool_output = f"Executed '{self.scratchpad.next_planned_action}'. Output: Success."

        print("🛑 CIRCUIT BREAKER: Max iterations reached.")
        return "MAX_ITERATIONS"
Concept of Structured Scratchpad
A Structured Scratchpad is a design pattern and prompt engineering technique used in Large Language Model (LLM) architectures to facilitate step-by-step reasoning, planning, and state management.
Unlike traditional "Chain-of-Thought" (CoT) prompting—which generates free-form, unformatted natural language thoughts—a Structured Scratchpad enforces a predefined schema (such as XML tags, JSON, YAML, or specific Markdown headers). This structure allows the model to separate its internal working memory, action planning, tool interactions, and final answers into distinct, machine-readable blocks before rendering a final output.
1) Key Structural Components
A Structured Scratchpad typically divides the LLM's thought process into distinct operational fields:
/ : Dedicated space for the model to decompose the task, analyze constraints, and plan the execution steps.
/ : Standardized syntax indicating an external function call, API request, or search query.
/ : Reserved block to feed external feedback, tool execution results, or context back into the scratchpad.
/ : Self-evaluation section where the model checks if previous steps were successful or if errors occurred.
: The polished, user-facing output isolated from the internal reasoning tags.
2) Comparison: Unstructured vs. Structured Scratchpad
Feature
Free-form Chain-of-Thought (Unstructured)
Structured Scratchpad
Format
Narrative prose / bullet points
JSON, XML, YAML, or Key-Value pairs
Parsing
Difficult to reliably parse with software
Deterministic and easily parsed via regex or schema validation
Control
High risk of prompt drift or topic deviation
Strict boundaries guide specific cognitive steps
Agentic Integration
Hard to trigger programmatic workflows
Seamless integration with external code, APIs, and tools
Interpretability
Human-readable, but messy for developers
Clean separation of internal logs vs. user responses
3) How It Works in an Agentic Loop
Instruction & Schema Injection: The system prompt provides the model with specific markup/JSON templates to follow for its working memory.
Generation of Intermediate Steps: The LLM writes to its internal scratchpad tags (, ), committing its logical steps to context.
Tool Execution: When an block is generated, the execution framework pauses the LLM, runs the corresponding API or script, and injects the output into the block.
Reflection & Iteration: The LLM evaluates the block within a tag to decide whether to run another loop or complete the process.
Final Output Extraction: The framework parses and hides the scratchpad elements, delivering only the block to the user.
4) Primary Benefits
Increased Determinism & Reliability: Constraining intermediate thinking to specific formats significantly decreases hallucinations and logical shortcuts.
Programmatic Interceptability: External backend systems can easily parse the structured scratchpad in real time to monitor progress, enforce safety guardrails, or trigger specific UI elements (e.g., showing a "Searching database..." status).
Enhanced Debugging & Auditability: Developers can trace exact failure points (e.g., identifying whether a failure occurred during planning, action specification, or result reflection).
Stateful Memory Management: Serves as a clear short-term memory dynamic for long-running autonomous tasks across multiple turns.
5) Practical Example (XML Schema)
<scratchpad>
  <plan>
    1. Extract user intent: Calculate total revenue.
    2. Retrieve Q3 revenue data from database tool.
    3. Retrieve Q4 revenue data from database tool.
    4. Compute the sum and formulate the answer.
  </plan>

  <action name="query_db">
    {"query": "SELECT revenue FROM sales WHERE quarter = 'Q3'"}
  </action>

  <observation>
    {"revenue": 150000}
  </observation>

  <action name="query_db">
    {"query": "SELECT revenue FROM sales WHERE quarter = 'Q4'"}
  </action>

  <observation>
    {"revenue": 200000}
  </observation>

  <reflection>
    Both values retrieved successfully. 150,000 + 200,000 = 350,000. Ready for final output.
  </reflection>
</scratchpad>

<final_answer>
  The total revenue for Q3 and Q4 is $350,000.
</final_answer>
Final Thoughts
The shift from Prompt Engineering to Loop Engineering represents a transition from treating LLMs as text-in/text-out interfaces to treating them as reasoning engines inside software pipelines. By giving agents strict operational limits, explicit tool access, and compressed memory state, you can build reliable, self-healing systems that operate long after you log off.