| RedisVL (Redis Vector Library) is an official Python client library designed to simplify using Redis as a vector database. It provides an intuitive, high-level interface for AI/ML developers to manage vector schemas, create indexes, store embeddings, and perform real-time semantic searches (Vector Search) and Retrieval-Augmented Generation (RAG) workflows. 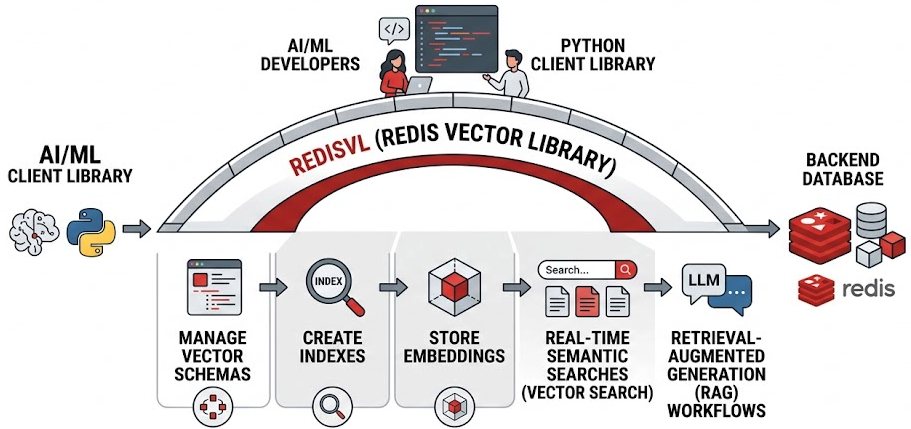
Key Features- Schema Management: Simple YAML or dictionary-based schema definitions for document attributes and vector fields.
- Integrated Vectorizers: Native integrations with popular embedding providers (OpenAI, HuggingFace, Cohere, VertexAI) to automatically generate vectors.
- Efficient Search: Built-in support for K-Nearest Neighbors (KNN), range queries, and hybrid search (combining metadata filtering with vector similarity).
- Async & Sync Support: Supports both synchronous and asynchronous operations for high-throughput applications.
Prerequisites & EnvironmentTo use RedisVL, you need both a Python environment and a running instance of Redis equipped with vector search capabilities. 1. Python Environment- Python Version: 3.8 or higher.
2. Redis Database RequirementStandard Redis OSS does not include vector search capabilities. You must run Redis Stack or Redis Enterprise, which includes the required search (RediSearch) and JSON modules. Local Setup via Docker (Recommended)The fastest way to set up a compatible Redis instance is using Docker: docker run -d --name redis-stack -p 6379:6379 -p 8001:8001 redis/redis-stack:latest
- Port
6379: Redis Database server. - Port
8001: Redis Insight (GUI web interface accessible via browser).
InstallationInstall RedisVL via pip: # Basic installation
pip install redisvl
# Optional: Install with specific vectorizer support (e.g., OpenAI or Sentence-Transformers)
pip install redisvl[openai]
pip install sentence-transformers
How Embeddings Are GeneratedRedisVL provides built-in Vectorizer classes within the redisvl.utils.vectorize module. You do not need to write custom pipeline code to convert text into embeddings; RedisVL handles the transformation directly. Supported Vectorizers:OpenAIVectorizer: Uses OpenAI's API (text-embedding-3-small, text-embedding-ada-002, etc.).HFTextVectorizer: Runs HuggingFace models locally via sentence-transformers.CohereVectorizer: Uses Cohere's embedding API.VertexAIVectorizer: Uses Google Cloud Vertex AI.
Vectorizer Usage Example:from redisvl.utils.vectorize import HFTextVectorizer, OpenAIVectorizer
# Option 1: Local HuggingFace Model (No API key required)
hf_vectorizer = HFTextVectorizer(model="sentence-transformers/all-MiniLM-L6-v2")
vector = hf_vectorizer.embed("RedisVL makes vector search easy.")
# Option 2: OpenAI API (Requires OPENAI_API_KEY environment variable)
# openai_vectorizer = OpenAIVectorizer(model="text-embedding-3-small")
# vector = openai_vectorizer.embed("RedisVL makes vector search easy.")
print(f"Vector dimension: {len(vector)}")
print(f"Sample vector data: {vector[:3]}...")
Usage Sample CodeHere is a complete end-to-end example demonstrating how to define a schema, initialize an index, generate embeddings, store documents, and perform vector similarity queries. import os
from redisvl.index import SearchIndex
from redisvl.query import VectorQuery
from redisvl.utils.vectorize import HFTextVectorizer
# ------------------------------------------------------------------
# 1. Initialize the Vectorizer
# ------------------------------------------------------------------
# We will use a lightweight HuggingFace model running locally
vectorizer = HFTextVectorizer(model="sentence-transformers/all-MiniLM-L6-v2")
# ------------------------------------------------------------------
# 2. Define Index Schema
# ------------------------------------------------------------------
schema = {
"index": {
"name": "tech_docs",
"prefix": "doc",
},
"fields": [
{"name": "doc_id", "type": "tag"},
{"name": "category", "type": "tag"},
{"name": "content", "type": "text"},
{
"name": "content_vector",
"type": "vector",
"attrs": {
"dims": 384, # Matches all-MiniLM-L6-v2 dimension output
"algorithm": "hnsw",
"distance_metric": "cosine"
}
}
]
}
# ------------------------------------------------------------------
# 3. Create Index and Connect to Redis
# ------------------------------------------------------------------
index = SearchIndex.from_dict(schema)
index.connect("redis://localhost:6379")
# Create the index in Redis (overwrites if it already exists)
index.create(overwrite=True)
# ------------------------------------------------------------------
# 4. Prepare and Insert Data (with Embeddings)
# ------------------------------------------------------------------
data = [
{"doc_id": "1", "category": "database", "content": "Redis is an in-memory data structure store used as a database, cache, and message broker."},
{"doc_id": "2", "category": "database", "content": "PostgreSQL is a powerful, open-source object-relational database system."},
{"doc_id": "3", "category": "ai", "content": "Large language models require fast vector databases for context retrieval in RAG systems."}
]
# Generate vectors for each document
for item in data:
item["content_vector"] = vectorizer.embed(item["content"])
# Load data into Redis
keys = index.load(data, id_field="doc_id")
print(f"Successfully loaded {len(keys)} documents into Redis.")
# ------------------------------------------------------------------
# 5. Perform Vector Search (KNN Query)
# ------------------------------------------------------------------
user_query = "What database is best for fast caching?"
# Embed the query text
query_vector = vectorizer.embed(user_query)
# Build a Vector Query to find the top 2 most similar documents
query = VectorQuery(
vector=query_vector,
vector_field_name="content_vector",
return_fields=["doc_id", "category", "content"],
num_results=2
)
# Execute search
results = index.query(query)
# Print results
print("\n--- Search Results ---")
for doc in results:
print(f"ID: {doc['doc_id']} | Category: {doc['category']}")
print(f"Content: {doc['content']}")
print(f"Score (Distance): {doc['vector_distance']}\n")
# ------------------------------------------------------------------
# 6. Cleanup (Optional)
# ------------------------------------------------------------------
# index.delete(drop_attributes=True)
Does the embedding value created using RedisVL always produce the same result for the same input, and can it be searched using Similarity Search?The embeddings generated using RedisVL are deterministic and will always yield the exact same vector for identical inputs, provided the underlying embedding model and configurations remain unchanged. Furthermore, RedisVL fully supports vector similarity searches, enabling you to store these generated embeddings in Redis and efficiently perform vector similarity queries using distance metrics such as cosine similarity or Euclidean distance to retrieve the most semantically relevant results. |