Circuit Breakers.zip

GPU & LLM Cluster Infrastructure & Task Scheduling Architecture

GPU & LLM Cluster Infrastructure & Task Scheduling Architecture

252

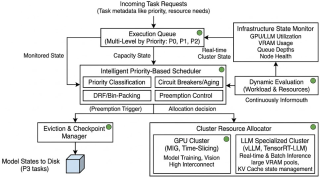
Designing a robust system infrastructure for allocating GPU and LLM clusters requires an optimized task management approach to address severe resource limitations.Because these computational clusters operate under strict hardware constraints,the infrastruc...

Invalid Auction Storms in Ad Tech

Invalid Auction Storms in Ad Tech

102

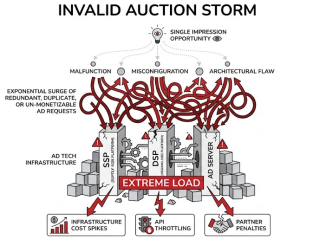
An Invalid Auction Storm occurs when a malfunction,misconfiguration,or architectural flaw causes an exponential surge of redundant,duplicate,or un-monetizable ad requests for a single impression opportunity.This places extreme load on Supply-Side Platforms...

The Two Clocks of Ad Server Architecture

The Two Clocks of Ad Server Architecture

74

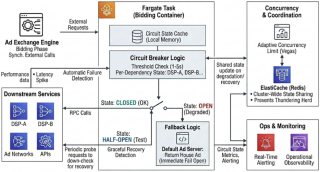
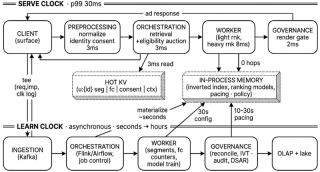
Every ad platform I have seen starts life as the same diagram.Someone opens a whiteboard and writes seven boxes in a row:Client → Preprocessing → Data Ingestion → Orchestration → Worker → Governance & Validation → Persistence.It is a good diagram.The...

TPU & GPU Cluster Management Tools

TPU & GPU Cluster Management Tools

254

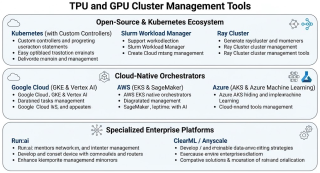
Automating machine learning pipelines while managing GPU and TPU clusters requires efficient scheduling,which is critically important because high user demand constantly competes against strictly limited hardware resources.Properly orchestrating these work...

End-to-End AI/Machine Learning Architecture: AI/ML 6 Layers

End-to-End AI/Machine Learning Architecture: AI/ML 6 Layers

250

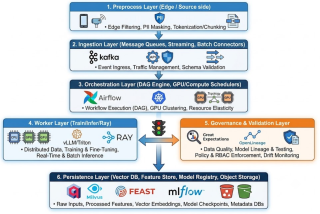
The architectural design for a modern Machine Learning and AI application adopts a cloud-native,event-driven microservices pattern structured across six core layers to satisfy functional requirements such as automated data transformation,model versioning,a...

What “GPU Clustering” Really Means (And How to Code for It)

What “GPU Clustering” Really Means (And How to Code for It)

210

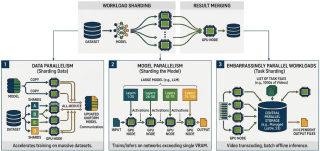
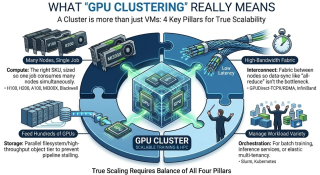
When building modern AI models or high-throughput media pipelines,you’ll quickly hear the phrase "GPU Cluster." But a true GPU cluster is much more than just a random collection of virtual machines with GPUs attached to them.To make workload scaling work—...

Milvus and LLM Integration - Very Smart Approach!

Milvus and LLM Integration - Very Smart Approach!

301

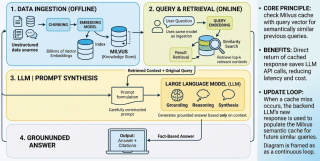
Combining Milvus,an open-source vector database,with Large Language Models (LLMs) is not only practical but has become a prevalent and highly effective strategy for building advanced AI applications.The core idea is to leverage Milvus's ability to store,in...

What is VAST? What is VMAP? How VAST/VMAP works?

What is VAST? What is VMAP? How VAST/VMAP works?

898

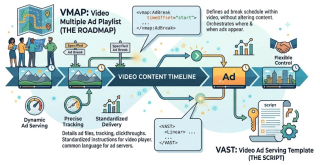
VAST (Video Ad Serving Template) is an XML schema providing standardized instructions to video players on how to play specific video ads,detailing aspects like ad file location,type,tracking URLs,and clickthrough links,essentially acting as the common lang...

Technical Hierarchy of AI Agents

Technical Hierarchy of AI Agents

822

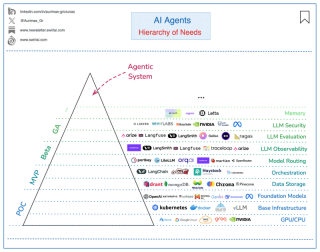
Below is from Aurimas Griciūnas showing hierarchical layers for AI Agents.Sometimes 𝗔𝗜 𝗔𝗴𝗲𝗻𝘁𝘀 might seem simple from the outside.They are not 👇There are many moving pieces that production ready Agentic Systems rely on. I like to split the 𝗛𝗶𝗲𝗿...

Vulnerabilities of MCP

Vulnerabilities of MCP

591

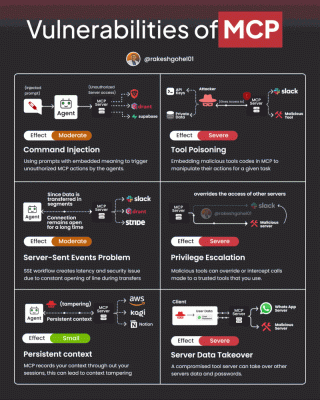
Model Context Protocol (MCP) is a framework that enables LLMs (Large Language Models) to seamlessly interact with external tools and data sources,effectively extending their capabilities beyond their pre-trained knowledge.It defines a standardized way for ...

Ad marker: SCTE-35 enhanced

577

SCTE-35 enhanced refers to improvements and additions to the original SCTE-35 standard for signaling commercial breaks in digital cable and IP video streams.These enhancements primarily focus on providing more precise and detailed information about ad inse...

Rust-GPU-tools for interacting with various GPU APIs

Rust-GPU-tools for interacting with various GPU APIs

755

Rust-GPU-tools is a collection of crates providing Rust bindings and utilities for interacting with various GPU APIs,including CUDA,Vulkan,and OpenCL.While it offers support for OpenCL through the ocl crate,it's not a strict dependency; you can use other p...

Difference between CPU and GPU - Why GPU is faster than CPU?

Difference between CPU and GPU - Why GPU is faster than CPU?

808

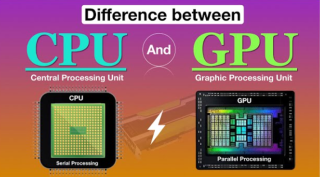
CPUs (Central Processing Units) are designed for general-purpose tasks,prioritizing sequential processing and complex instructions,while GPUs (Graphics Processing Units) are specialized for parallel processing of many simpler instructions simultaneously.GP...

xAI aims its goal to achieve AGI - Artificial General Intelligence

xAI aims its goal to achieve AGI - Artificial General Intelligence

792

xAI,Elon Musk's artificial intelligence company,was founded in March 2023.Its stated goal is to understand the true nature of the universe,a significant departure from the more commercially focused aims of many other AI companies.While its history is short...

Attribution's New Blueprint: Balancing Performance and Privacy

Attribution's New Blueprint: Balancing Performance and Privacy

505

Attribution answers a fundamental question: which marketing touchpoint deserves credit for a conversion? A user might click a display ad on Monday,click again on Friday,and finally purchase after an email on Saturday.How much credit goes to each channel? A...

Ad Auction Architectures: A Publisher's Guide to Optimal Monetization

Ad Auction Architectures: A Publisher's Guide to Optimal Monetization

684

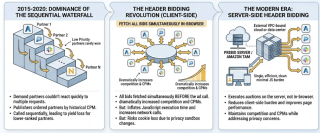
Publisher monetization hinges on filling inventory at the highest possible CPM.Unsold inventory (direct campaigns,remnant) must be routed through programmatic partners—ad networks,SSPs,demand-side platforms—to generate revenue.The core challenge is choos...

Ad Tech Idempotency: Engineering for Reliability and Scale

Ad Tech Idempotency: Engineering for Reliability and Scale

365

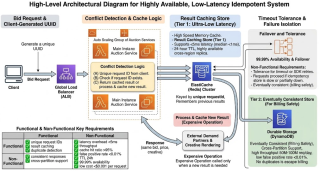
Idempotency is the property that applying the same operation multiple times produces the same result as applying it once.In ad tech,this is critical for handling duplicate bid requests,billing signals,and API calls without side effects.A network timeout or...

Real-Time Geo-Targeting: Balancing Precision, Latency, and Cost

Real-Time Geo-Targeting: Balancing Precision, Latency, and Cost

289

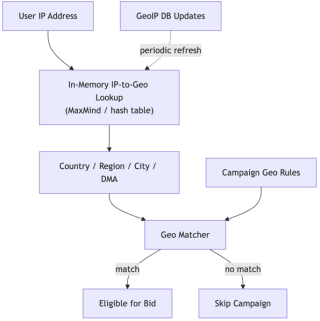
Geo-targeting enables advertisers to show ads only to users in specific geographic regions.A pizza chain wants ads shown only to users within 5 miles of its locations; a luxury car brand targets major metropolitan areas; a regional bank limits ad spend to ...

Getting Started with FAISS: A CentOS 7 Installation Guide

Getting Started with FAISS: A CentOS 7 Installation Guide

284

What is FAISS?FAISS (Facebook AI Similarity Search) is a library developed by Facebook AI Research for efficient similarity search and clustering of dense vectors.It provides algorithms that search for points in a set of vectors that are closest to a given...

Frequency Cap Architecture Overview

Frequency Cap Architecture Overview

519

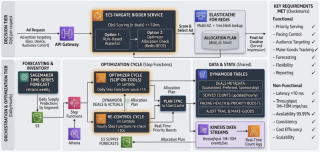
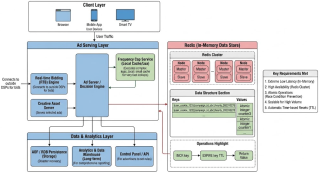
Frequency capping is a critical setting in advertising that restricts the number of times a specific advertisement,creative,or campaign is displayed to an individual user within a defined period.Its primary goal is to optimize advertising effectiveness by ...