Machine Learning Infrastructure.zip

Designing a Data Curation System Around a Vector Database

Designing a Data Curation System Around a Vector Database

228

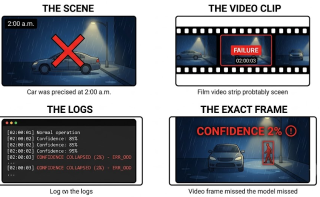
Your model fails at 2 a.m.on a rainy street.You have the clip.You have the logs.You even have the exact frame where confidence collapsed.Now what?.For most teams,the answer is a week of Slack threads,a half-remembered S3 prefix,and someone scrubbing throug...
Bridging the Gap: How Machine Learning Integrates with Infrastructure

Bridging the Gap: How Machine Learning Integrates with Infrastructure

285

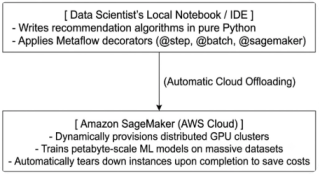
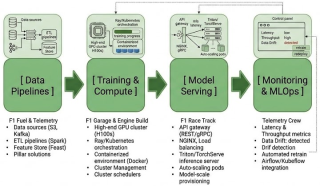
Bridging the gap between Machine Learning (ML) theory and infrastructure often comes down to shift in perspective: ML is the intelligence (the brain),and Infrastructure is the system that keeps it alive,fed,and useful to the world (the body and environment...

The Continuous Learning Machine: Designing a Loop That Actually Turns

The Continuous Learning Machine: Designing a Loop That Actually Turns

226

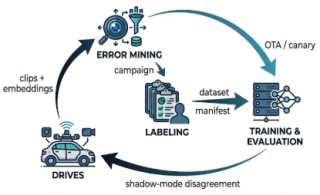
A fleet of a million vehicles drives a million hours today.Tomorrow it does it again.Somewhere in there are the forty seconds that would fix your model.The hard part was never the training job.It's that 99.999% of what the fleet sees is a car following a c...

GPU & LLM Cluster Infrastructure & Task Scheduling Architecture

GPU & LLM Cluster Infrastructure & Task Scheduling Architecture

252

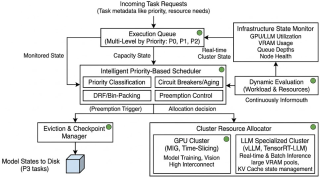
Designing a robust system infrastructure for allocating GPU and LLM clusters requires an optimized task management approach to address severe resource limitations.Because these computational clusters operate under strict hardware constraints,the infrastruc...

What ML Labeling Actually Is - And How to Design a Pipeline for It

What ML Labeling Actually Is - And How to Design a Pipeline for It

341

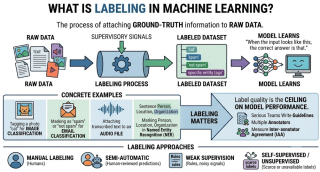
From fundamentals to autonomous vehicle architectureIf there's one thing that affects ML model performance more than architecture choices,most practitioners will tell you it's data quality — specifically,the quality of your labels.Yet clear,structured res...

End-to-End Autonomous Vehicle ML Training Pipeline

End-to-End Autonomous Vehicle ML Training Pipeline

336

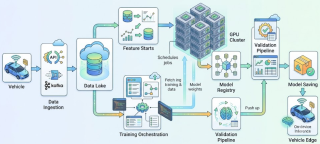
The end-to-end architectural design for the machine learning training pipeline begins at the Vehicle,where telemetry and sensor data are collected and routed into the Data Ingestion system.This ingested data is stored centrally in a Data Lake and subsequen...

What “GPU Clustering” Really Means (And How to Code for It)

What “GPU Clustering” Really Means (And How to Code for It)

210

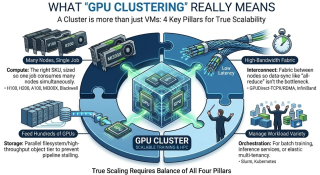
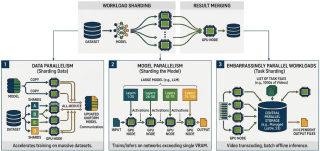
When building modern AI models or high-throughput media pipelines,you’ll quickly hear the phrase "GPU Cluster." But a true GPU cluster is much more than just a random collection of virtual machines with GPUs attached to them.To make workload scaling work—...

The Core of Vector Databases: Embeddings and LLM Dependency

The Core of Vector Databases: Embeddings and LLM Dependency

264

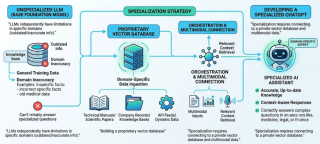
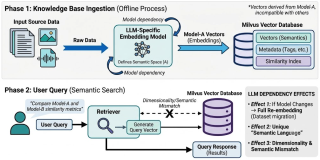
The fundamental principle of a vector database revolves around embeddings.An embedding is a numerical representation (a vector) of text,images,audio,or other data,capturing its semantic meaning in a high-dimensional space.LLMs (Large Language Models) are o...

The Immense Scale and Management of Exabyte Data with AWS

The Immense Scale and Management of Exabyte Data with AWS

513

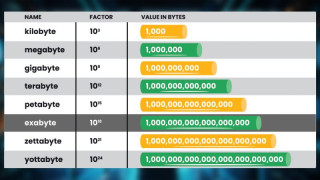
Visualizing an ExabyteAn exabyte (EB) is a staggering unit of data,equal to one quintillion bytes or one billion gigabytes.Visualizing its scale can be challenging,but here are a few attempts to put it into perspective::Books: Imagine digitizing all the bo...

Integrating VectorDB stored in S3 with Amazon Bedrock

Integrating VectorDB stored in S3 with Amazon Bedrock

427

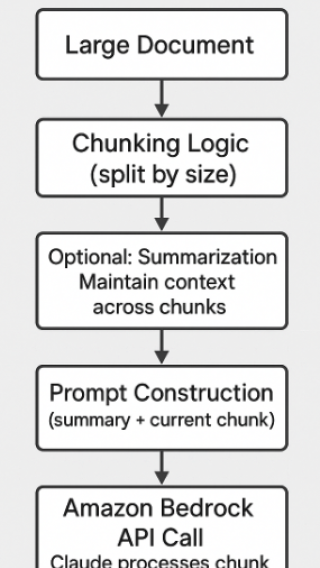
One of the rising area regarding smart search is to use Vector Database stored in S3 with Amazon Bedrock so you can use it for retrieval-augmented generation (RAG) or semantic search.Amazon Bedrock is a fully managed service that allows developers to acces...

Milvus and LLM Integration - Very Smart Approach!

Milvus and LLM Integration - Very Smart Approach!

301

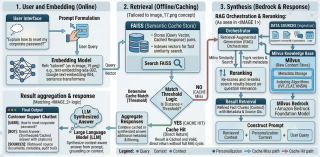
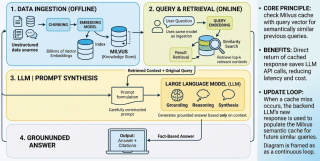
Combining Milvus,an open-source vector database,with Large Language Models (LLMs) is not only practical but has become a prevalent and highly effective strategy for building advanced AI applications.The core idea is to leverage Milvus's ability to store,in...

Technical Hierarchy of AI Agents

Technical Hierarchy of AI Agents

822

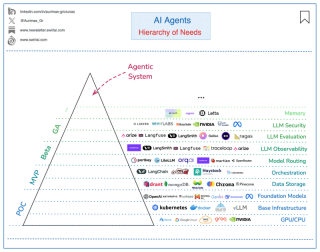
Below is from Aurimas Griciūnas showing hierarchical layers for AI Agents.Sometimes 𝗔𝗜 𝗔𝗴𝗲𝗻𝘁𝘀 might seem simple from the outside.They are not 👇There are many moving pieces that production ready Agentic Systems rely on. I like to split the 𝗛𝗶𝗲𝗿...

Rust-GPU-tools for interacting with various GPU APIs

Rust-GPU-tools for interacting with various GPU APIs

755

Rust-GPU-tools is a collection of crates providing Rust bindings and utilities for interacting with various GPU APIs,including CUDA,Vulkan,and OpenCL.While it offers support for OpenCL through the ocl crate,it's not a strict dependency; you can use other p...

Difference between CPU and GPU - Why GPU is faster than CPU?

Difference between CPU and GPU - Why GPU is faster than CPU?

808

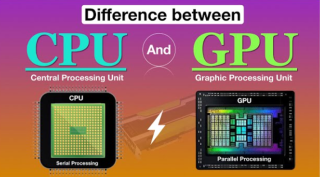
CPUs (Central Processing Units) are designed for general-purpose tasks,prioritizing sequential processing and complex instructions,while GPUs (Graphics Processing Units) are specialized for parallel processing of many simpler instructions simultaneously.GP...

Python code using GPU on CentOS with AWS

1,255

To use a GPU on CentOS with AWS,you'll need to select an EC2 instance type with a GPU.After launching the instance,install the necessary drivers for the GPU.This usually involves downloading and running a package specific to your GPU model.Then,you'll need...

MLOps Explained: Spark, Flink, and Reference Architecture Deep Dive

MLOps Explained: Spark, Flink, and Reference Architecture Deep Dive

245

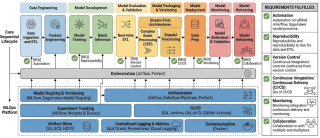
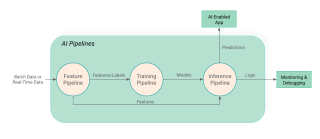
MLOps (Machine Learning Operations)MLOps is a set of practices that aims to deploy and maintain machine learning models in production reliably and efficiently.It bridges the gap between machine learning development (ML Dev) and operations (Ops),similar to ...

How to Set Up and Deploy Containerized Applications with AWS ECS

10,682

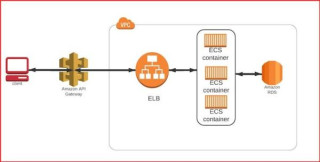
Setting up an Amazon Web Services (AWS) Elastic Container Service (ECS) involves several steps to deploy containerized applications in a scalable and managed environment.AWS ECS supports Docker containers and allows you to run applications on a managed clu...

Power of Containerized Deployment with AWS ECS

Power of Containerized Deployment with AWS ECS

10,598

Have you ever wanted to streamline how you develop and deploy applications? Amazon Elastic Container Service (ECS) could be the game-changer you're looking for.This service allows developers to manage Docker containers on a highly scalable and secure platf...

Getting Started with FAISS: A CentOS 7 Installation Guide

Getting Started with FAISS: A CentOS 7 Installation Guide

284

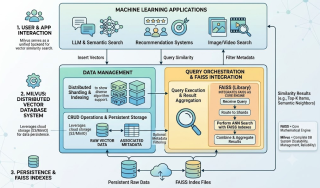
What is FAISS?FAISS (Facebook AI Similarity Search) is a library developed by Facebook AI Research for efficient similarity search and clustering of dense vectors.It provides algorithms that search for points in a set of vectors that are closest to a given...

Milvus & FAISS: Decoding Their ML Synergy

Milvus & FAISS: Decoding Their ML Synergy

282

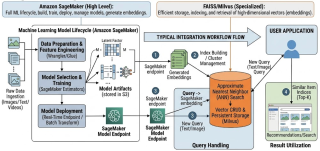
What is Milvus?Milvus is an open-source vector database designed for storing,indexing,and managing billions of embedding vectors.It specializes in high-performance similarity search over these vectors.Milvus is built to handle the unique challenges of vect...

TikTok's Recommendation System - Monolith

TikTok's Recommendation System - Monolith

297

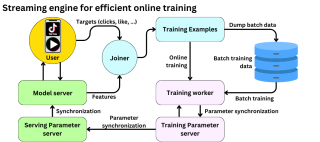
Monolith is ByteDance’s deep-learning recommendation system (described in a 2022 paper) that powers TikTok’s “For You” feed.It is a large-scale,two-stage (retrieval → ranking) deep-learning engine,purpose-built for the dynamic,sparse,and constantly sh...

NVIDIA CUDA library which can be integrated with C/C++

376

The NVIDIA CUDA library is a parallel computing platform and programming model that allows software developers to use NVIDIA GPUs for general-purpose processing – an approach known as GPGPU.It provides a C / C++ API,including header files and libraries,en...

Common Recommendation Service Architecture

Common Recommendation Service Architecture

537

Almost every large-scale recommendation service — TikTok,YouTube,Amazon,Netflix,Spotify — is built on the same architectural skeleton,regardless of which specific model it uses.Understanding this skeleton is more valuable than memorizing any single algor...

How to Design Redis Caching in Infrastructure Architecture

How to Design Redis Caching in Infrastructure Architecture

160

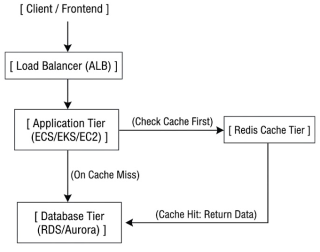
Core Architectural PlacementWhen drawing a Redis caching infrastructure,you must place Redis strategically between your application tier and your persistent database tier.The architecture is typically represented in a three-tier model::Application Tier: Ac...