TensorRT.zip

GPU & LLM Cluster Infrastructure & Task Scheduling Architecture

GPU & LLM Cluster Infrastructure & Task Scheduling Architecture

252

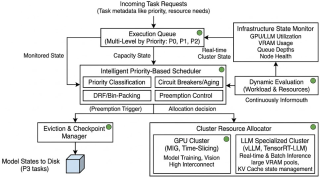
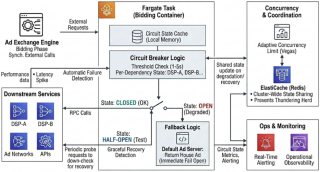
Designing a robust system infrastructure for allocating GPU and LLM clusters requires an optimized task management approach to address severe resource limitations.Because these computational clusters operate under strict hardware constraints,the infrastruc...

TPU & GPU Cluster Management Tools

TPU & GPU Cluster Management Tools

254

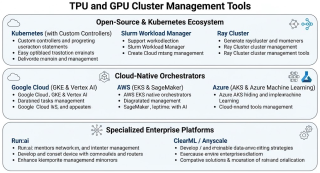
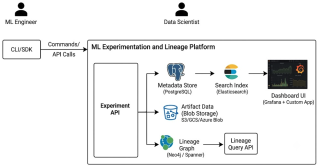
Automating machine learning pipelines while managing GPU and TPU clusters requires efficient scheduling,which is critically important because high user demand constantly competes against strictly limited hardware resources.Properly orchestrating these work...

End-to-End AI/Machine Learning Architecture: AI/ML 6 Layers

End-to-End AI/Machine Learning Architecture: AI/ML 6 Layers

250

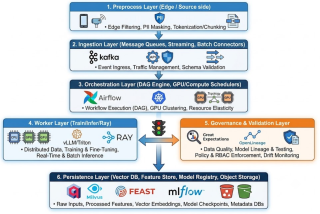
The architectural design for a modern Machine Learning and AI application adopts a cloud-native,event-driven microservices pattern structured across six core layers to satisfy functional requirements such as automated data transformation,model versioning,a...

What “GPU Clustering” Really Means (And How to Code for It)

What “GPU Clustering” Really Means (And How to Code for It)

210

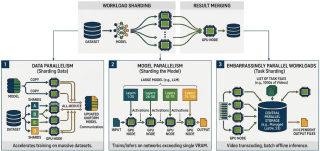
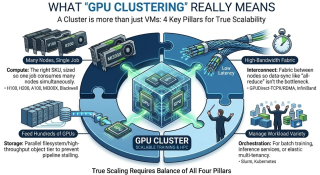
When building modern AI models or high-throughput media pipelines,you’ll quickly hear the phrase "GPU Cluster." But a true GPU cluster is much more than just a random collection of virtual machines with GPUs attached to them.To make workload scaling work—...

Microsoft AutoGen: Next-Generation Multi-Agent Framework

Microsoft AutoGen: Next-Generation Multi-Agent Framework

313

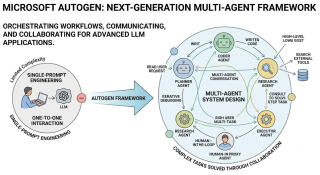
Microsoft AutoGen is an open-source framework designed to simplify the development of advanced Large Language Model (LLM) applications.Its core paradigm relies on multi-agent conversation,where multiple specialized agents communicate,collaborate,and orches...

Is a Used M1 or M2 MacBook Pro a Smart Buy Over M4?

Is a Used M1 or M2 MacBook Pro a Smart Buy Over M4?

295

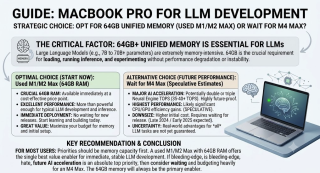
You are contemplating purchasing a MacBook Pro primarily for LLM development.Your core consideration is whether to opt for a cost-effective,used M1 or M2 MacBook Pro with 64GB of unified memory,rather than waiting for or investing in a new M4 model.Your ra...

Milvus and LLM Integration - Very Smart Approach!

Milvus and LLM Integration - Very Smart Approach!

301

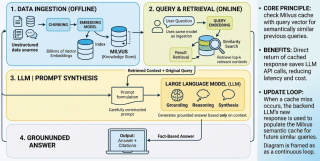
Combining Milvus,an open-source vector database,with Large Language Models (LLMs) is not only practical but has become a prevalent and highly effective strategy for building advanced AI applications.The core idea is to leverage Milvus's ability to store,in...

Learn SLM if you have interent in the next after LLM

Learn SLM if you have interent in the next after LLM

4911

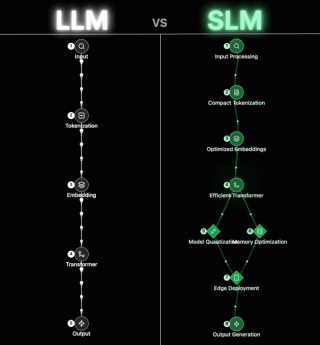
Both SLMs (Small Language Models) and LLMs (Large Language Models) are types of language models,but they differ primarily in size (number of parameters) and consequently,in their capabilities and scope.LLMs,with their massive parameter counts,possess a wid...

Technical Hierarchy of AI Agents

Technical Hierarchy of AI Agents

822

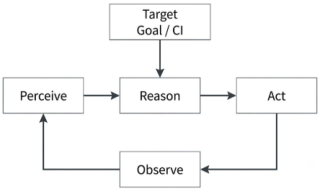
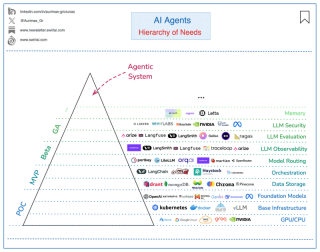
Below is from Aurimas Griciūnas showing hierarchical layers for AI Agents.Sometimes 𝗔𝗜 𝗔𝗴𝗲𝗻𝘁𝘀 might seem simple from the outside.They are not 👇There are many moving pieces that production ready Agentic Systems rely on. I like to split the 𝗛𝗶𝗲𝗿...

Vulnerabilities of MCP

Vulnerabilities of MCP

591

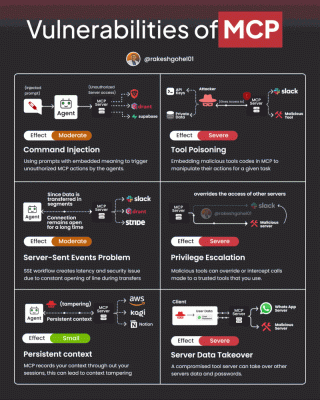
Model Context Protocol (MCP) is a framework that enables LLMs (Large Language Models) to seamlessly interact with external tools and data sources,effectively extending their capabilities beyond their pre-trained knowledge.It defines a standardized way for ...

Rust-GPU-tools for interacting with various GPU APIs

Rust-GPU-tools for interacting with various GPU APIs

755

Rust-GPU-tools is a collection of crates providing Rust bindings and utilities for interacting with various GPU APIs,including CUDA,Vulkan,and OpenCL.While it offers support for OpenCL through the ocl crate,it's not a strict dependency; you can use other p...

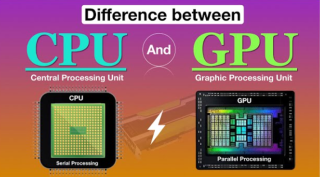
Difference between CPU and GPU - Why GPU is faster than CPU?

Difference between CPU and GPU - Why GPU is faster than CPU?

808

CPUs (Central Processing Units) are designed for general-purpose tasks,prioritizing sequential processing and complex instructions,while GPUs (Graphics Processing Units) are specialized for parallel processing of many simpler instructions simultaneously.GP...

xAI aims its goal to achieve AGI - Artificial General Intelligence

xAI aims its goal to achieve AGI - Artificial General Intelligence

792

xAI,Elon Musk's artificial intelligence company,was founded in March 2023.Its stated goal is to understand the true nature of the universe,a significant departure from the more commercially focused aims of many other AI companies.While its history is short...

Getting Started with FAISS: A CentOS 7 Installation Guide

Getting Started with FAISS: A CentOS 7 Installation Guide

284

What is FAISS?FAISS (Facebook AI Similarity Search) is a library developed by Facebook AI Research for efficient similarity search and clustering of dense vectors.It provides algorithms that search for points in a set of vectors that are closest to a given...

NVIDIA CUDA library which can be integrated with C/C++

376

The NVIDIA CUDA library is a parallel computing platform and programming model that allows software developers to use NVIDIA GPUs for general-purpose processing – an approach known as GPGPU.It provides a C / C++ API,including header files and libraries,en...

Java Maps: HashMap vs. LinkedHashMap vs. TreeMap Explained

Java Maps: HashMap vs. LinkedHashMap vs. TreeMap Explained

231

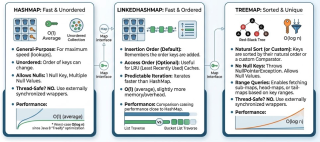
In Java,the Map interface is part of the java.util package and represents a collection that stores key-value pairs.Each key in a Map must be unique,and it maps to a single value.Maps are crucial for various programming scenarios where you need to associate...