| To build GPU-as-a-Service (GaaS), you need a robust infrastructure encompassing high-performance GPUs (e.g., NVIDIA, AMD), high-bandwidth networking (e.g., InfiniBand, 100GbE), a scalable and reliable cloud platform (e.g., Kubernetes, OpenStack), virtualization technology (e.g., Docker, VMs), a secure remote access mechanism (e.g., SSH, VPN), resource management and scheduling software (e.g., Slurm, Kubernetes), monitoring and logging tools, and a billing system to manage user access and charges. Finally, you'll need robust security measures to protect the GPUs and user data.
Dockerized GaaS provides sufficient performance for low-resolution encoding.While Docker itself doesn't inherently impact encoding performance, its overhead and reliance on the host system's resources can affect real-time encoding depending on the complexity of the encoding task and the host system's capabilities. For simple, low-resolution encoding, Docker might suffice. However, for demanding real-time encoding of high-resolution video streams with complex codecs, the overhead of virtualization and potential contention for resources could lead to dropped frames or increased latency, making Docker unsuitable for guaranteed real-time performance. Optimizing the Docker image, host hardware, and utilizing appropriate resource allocation are crucial considerations.
NVIDIA Container ToolkitYes, Dockerized GPU-as-a-Service (GaaS) can provide sufficient performance for real-time encoding, provided that the system is well-optimized. NVIDIA GPUs and Docker integration through the NVIDIA Container Toolkit allow containerized applications to access GPU resources with minimal overhead, making it feasible for performance-critical tasks such as real-time encoding. However, achieving optimal performance depends on several factors:
Factors Affecting Real-Time Encoding Performance in Dockerized GaaS1. GPU Hardware Capability- Use GPUs designed for encoding, such as NVIDIA's NVENC-enabled GPUs (e.g., Turing, Ampere, or Ada Lovelace series).
- Ensure the GPU supports the desired codec (e.g., H.264, HEVC) and bitrate for real-time processing.
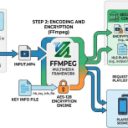
2. Encoding Library- Utilize NVIDIA's NVENC API or libraries like FFmpeg with NVIDIA GPU support (
--enable-nvenc). - NVENC is highly efficient and designed for real-time encoding workloads.
3. Docker Configuration- Use the NVIDIA Container Toolkit to expose GPU devices to containers:
- Ensure no bottlenecks in the container network (e.g., proper bandwidth allocation, low-latency network setup).
4. Real-Time Constraints- Real-time encoding requires low latency, which depends on:
- Input and Output Latency: Minimize delays in fetching video frames and streaming the output.
- Concurrent Workloads: If multiple clients share the GPU, use NVIDIA Multi-Instance GPU (MIG) or allocate GPUs to containers dynamically.
- Resource Isolation: Limit CPU and memory usage by other processes using Docker's resource constraints.
5. Encoding Configuration- Optimize encoder settings for real-time performance:
6. Networking Overhead- Real-time applications often require low-latency data transmission:
- Use high-speed interconnects (e.g., 10GbE, InfiniBand).
- Reduce network serialization overhead by using efficient protocols like gRPC or WebSocket for data streaming.
- Consider edge deployment to reduce round-trip time.
7. Workload Balancing- Balance encoding workloads across GPUs using orchestration tools:
- Kubernetes with NVIDIA GPU operators for scaling containers.
- Use resource allocation strategies to prevent GPU overload.
8. Disk and I/O Speed- Ensure fast I/O for loading video streams or writing encoded data:
- Use NVMe SSDs for temporary storage or caching.
- Optimize Docker volume mounts for high-speed data access.
Benefits of Dockerized GaaS for Real-Time Encoding- Scalability: Containers can be scaled horizontally to meet demand.
- Isolation: Each client or encoding task runs in its own container, ensuring isolation and security.
- Portability: The same container can run on any GPU-enabled server.
- Resource Efficiency: Dynamically allocate GPUs based on workload requirements.
- Flexibility: Support for multiple codecs and configurations in different containers.
Potential Challenges- Container Overhead:
- While minimal, Docker containers do introduce slight performance overhead. Proper configuration of
runtime=nvidia ensures near-native GPU performance.
- Latency:
- Real-time encoding requires end-to-end latency to be less than frame intervals (e.g., <33ms for 30fps). Optimize both GPU and network performance to meet this.
- Concurrent Users:
- High concurrency might saturate GPU resources, affecting performance. Implement resource management via Kubernetes or other orchestration tools.
Practical Example: Dockerized Real-Time EncodingDockerfile for FFmpeg with NVIDIA NVENC:FROM nvidia/cuda:11.8.0-runtime-ubuntu22.04
RUN apt-get update && \
apt-get install -y ffmpeg libavcodec-extra && \
rm -rf /var/lib/apt/lists/*
CMD ["ffmpeg"]
Run the Container:docker run --gpus all -v /path/to/videos:/videos -it my-encoder-container \
ffmpeg -i /videos/input.mp4 -c:v h264_nvenc -preset fast -b:v 5M /videos/output.mp4
ConclusionA Dockerized GaaS setup can handle real-time encoding effectively if: - High-performance GPUs are used (e.g., with NVENC support).
- Network latency and I/O bottlenecks are minimized.
- Encoding settings and resource allocation are optimized.
For large-scale deployments, consider using Kubernetes with GPU scheduling to handle workloads dynamically. Let me know if you need help setting up a specific environment! |